OLake Go
Replicate your databases fast, into Apache Iceberg & Parquet on S3.
12.5X
Faster than traditional tools
90%
Cost Savings with OSS
Trusted by Engineers at
Benchmarks
Time to move 4.01 Billion rows,
Postgres to Apache Iceberg, full load
| Metrics | OLake GoOpen Source | Airbyte | Fivetran | Debezium | Estuary |
|---|---|---|---|---|---|
| Rows synced | 4.01 Billion | 12.7 Million | 4.01 Billion | 1.28 Billion | 0.34 Billion |
| Elapsed time | 1.91 hours | 7.5 hours (failed sync) | 24 hours | 24 hours | 24 hours |
| Speed (Rows/Sec) | 5,80,113 RPS | 457 RPS | 46,395 RPS | 14,839 RPS | 3,982 RPS |
| Comparison | – | 1270x slower | 12.5x slower | 39.1x slower | 146x slower |
| CostOLake is OSS and self-hosted — only pay for your infrastructure. | < $ 6 | $ 5,560 | $ 0 (free full load) | $ 75 | $ 1,668 |
Faster & half the cost
View OLake Fusion benchmarks| OLake Fusion | Spark Compaction | |
|---|---|---|
| Total Compaction Time | 27m 02s2.06x faster | 55m 47s |
| Compaction Cost/ Job | $1.0652% less cost | $2.19 |
| Config Parameters | 110x simpler | 10+ |
Two Engines
Features
Running Ingestion
# run it
$ OLake sync
orders      1,204,553 rows   00:41  ✓
customers     318,090 rows   00:12  ✓
Fast
Sync MySQL, Postgres, MongoDB, Oracle, and more to Apache Iceberg with parallelised chunking, incremental sync, and change data capture, so your lakehouse tables stay fresh with minimal overhead.
s3://lake/warehouse
Open
Write directly to Apache Iceberg or Parquet with support for multiple catalogs including AWS Glue, Apache Hive Metastore, and REST catalogs like Nessie, Polaris, and Unity Catalog — your data stays queryable by any engine you choose.
res
container
Controlled
Deploy OLake entirely within your own cloud or on-prem environment, keeping full control over where your data lives — critical for regulated industries like financial services that can't compromise on data residency.
P95 Query Time
0.9s
Table Size
12.4 TB
Maintained
Automate Iceberg table maintenance through compaction, clearing delete files, and trimming metadata so query performance and storage costs don't degrade as your lakehouse scales.
Running Ingestion
# run it
$ OLake sync
orders      1,204,553 rows   00:41  ✓
customers     318,090 rows   00:12  ✓
Fast
Sync MySQL, Postgres, MongoDB, Oracle, and more to Apache Iceberg with parallelised chunking, incremental sync, and change data capture, so your lakehouse tables stay fresh with minimal overhead.
s3://lake/warehouse
Open
Write directly to Apache Iceberg or Parquet with support for multiple catalogs including AWS Glue, Apache Hive Metastore, and REST catalogs like Nessie, Polaris, and Unity Catalog — your data stays queryable by any engine you choose.
res
container
Controlled
Deploy OLake entirely within your own cloud or on-prem environment, keeping full control over where your data lives — critical for regulated industries like financial services that can't compromise on data residency.
P95 Query Time
0.9s
Table Size
12.4 TB
Maintained
Automate Iceberg table maintenance through compaction, clearing delete files, and trimming metadata so query performance and storage costs don't degrade as your lakehouse scales.
Running Ingestion
# run it
$ OLake sync
orders      1,204,553 rows   00:41  ✓
customers     318,090 rows   00:12  ✓
Fast
Sync MySQL, Postgres, MongoDB, Oracle, and more to Apache Iceberg with parallelised chunking, incremental sync, and change data capture, so your lakehouse tables stay fresh with minimal overhead.
s3://lake/warehouse
Open
Write directly to Apache Iceberg or Parquet with support for multiple catalogs including AWS Glue, Apache Hive Metastore, and REST catalogs like Nessie, Polaris, and Unity Catalog — your data stays queryable by any engine you choose.
res
container
Controlled
Deploy OLake entirely within your own cloud or on-prem environment, keeping full control over where your data lives — critical for regulated industries like financial services that can't compromise on data residency.
P95 Query Time
0.9s
Table Size
12.4 TB
Maintained
Automate Iceberg table maintenance through compaction, clearing delete files, and trimming metadata so query performance and storage costs don't degrade as your lakehouse scales.
Running Ingestion
# run it
$ OLake sync
orders      1,204,553 rows   00:41  ✓
customers     318,090 rows   00:12  ✓
Fast
Sync MySQL, Postgres, MongoDB, Oracle, and more to Apache Iceberg with parallelised chunking, incremental sync, and change data capture, so your lakehouse tables stay fresh with minimal overhead.
s3://lake/warehouse
Open
Write directly to Apache Iceberg or Parquet with support for multiple catalogs including AWS Glue, Apache Hive Metastore, and REST catalogs like Nessie, Polaris, and Unity Catalog — your data stays queryable by any engine you choose.
res
container
Controlled
Deploy OLake entirely within your own cloud or on-prem environment, keeping full control over where your data lives — critical for regulated industries like financial services that can't compromise on data residency.
P95 Query Time
0.9s
Table Size
12.4 TB
Maintained
Automate Iceberg table maintenance through compaction, clearing delete files, and trimming metadata so query performance and storage costs don't degrade as your lakehouse scales.
Architecture
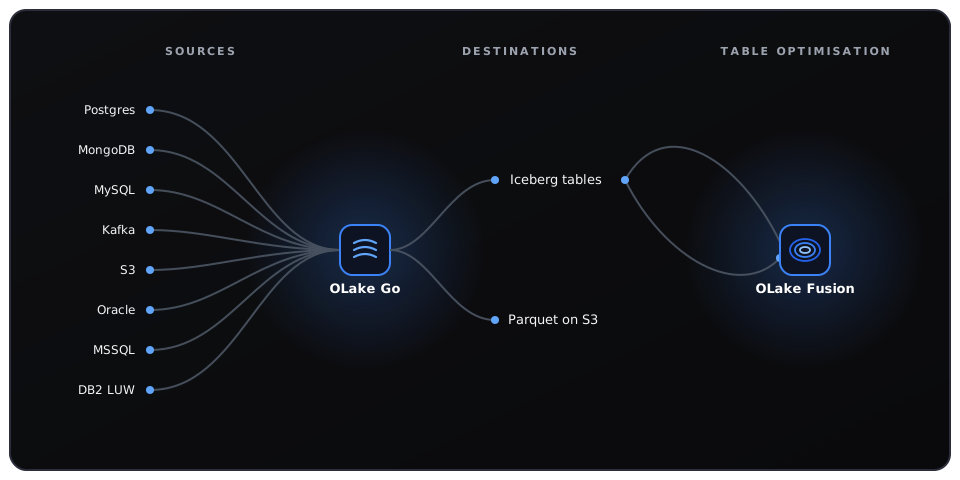
OLake Go supports ingestion from 8 different sources into Iceberg and Parquet. OLake Fusion keeps your Iceberg tables fast, through scheduled compaction and maintenance.
Get in touchSources
Catalogs
Destinations
Query Engines that read results
Latest News
For Enterprises
While we are open source, we offer custom support for enterprises based on your GRC requirements. Leave your contact information and our team will get in touch.
Request a callback