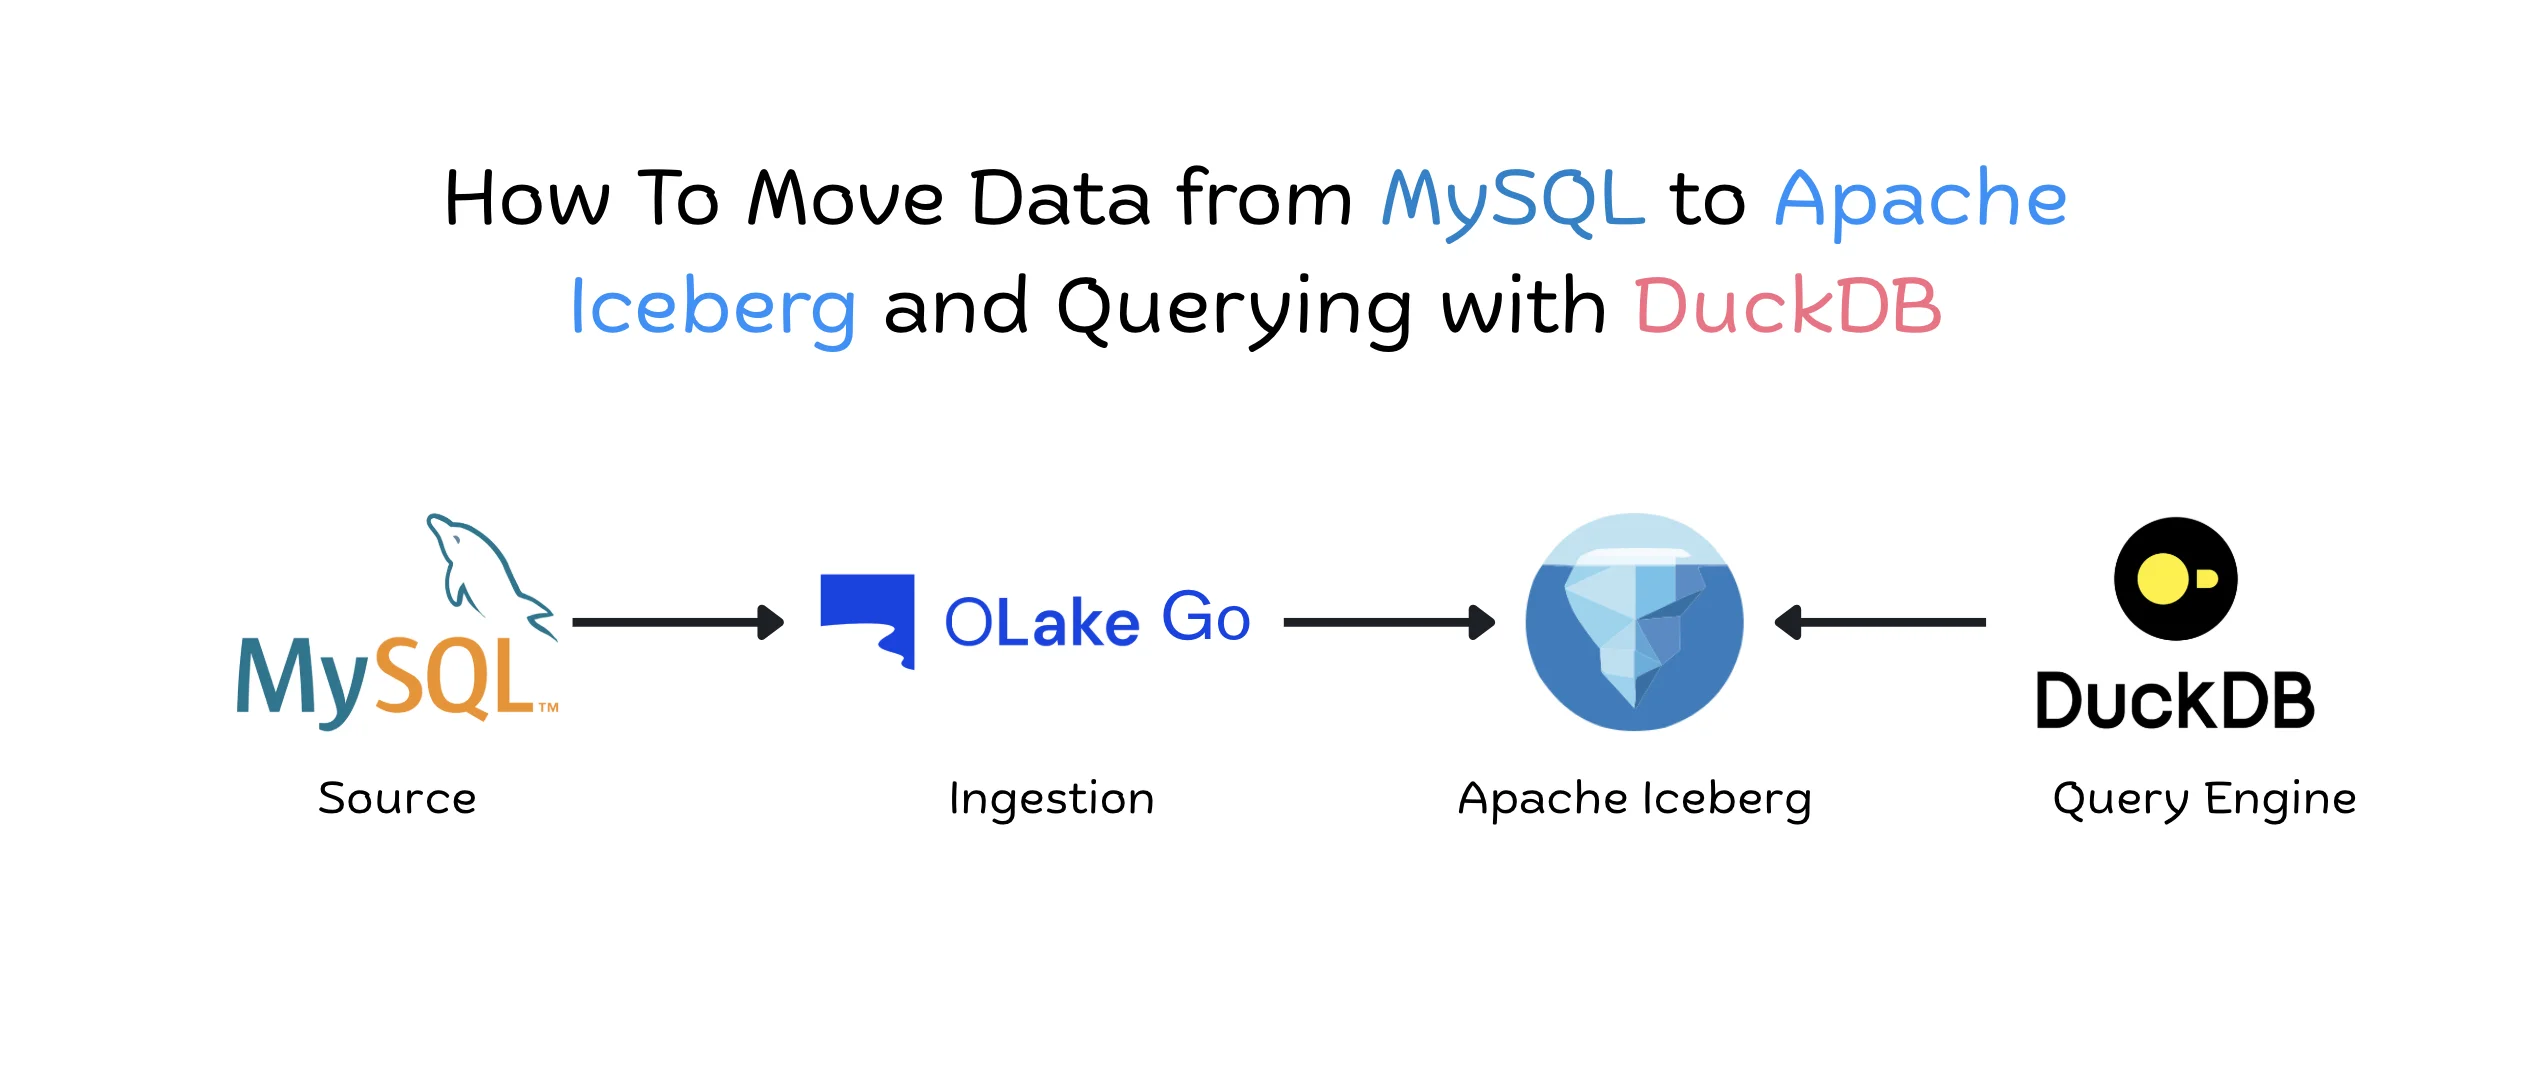
How To Move Data from MySQL to Apache Iceberg and Querying with DuckDB
Replicate MySQL tables to Apache Iceberg with OLake Go and query them in DuckDB. Step-by-step: set up the source and catalog, create a job, run CDC sync, query.
Replicate MySQL tables to Apache Iceberg with OLake Go and query them in DuckDB. Step-by-step: set up the source and catalog, create a job, run CDC sync, query.
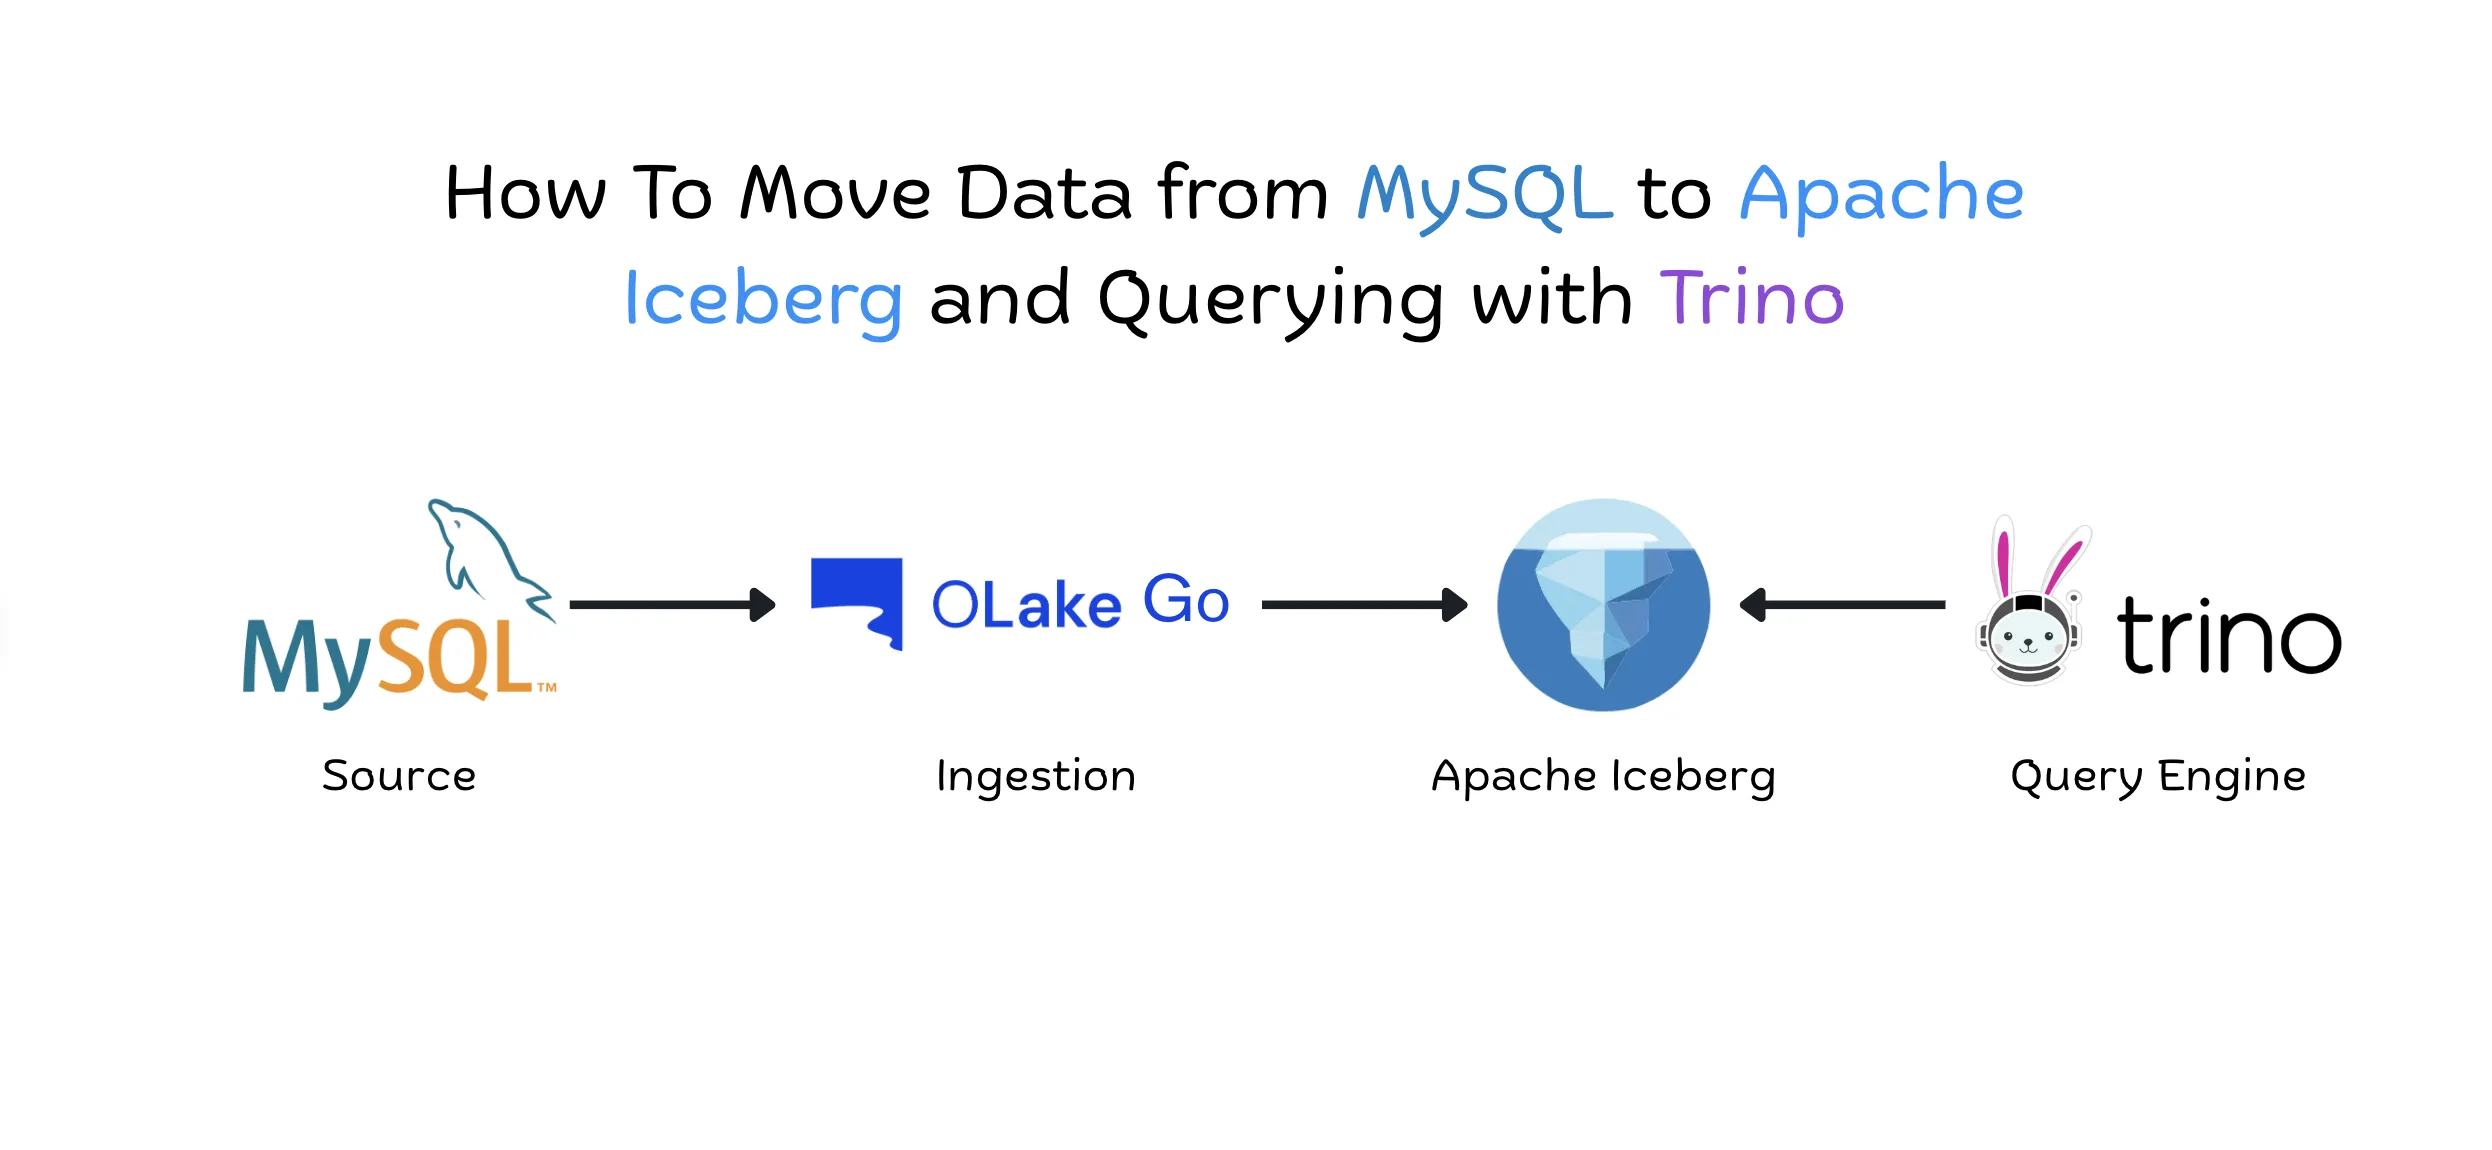
Replicate MySQL to Apache Iceberg with OLake Go and query the tables in Trino. Step-by-step: connect MySQL, pick a catalog, run CDC sync, and query with Trino SQL.
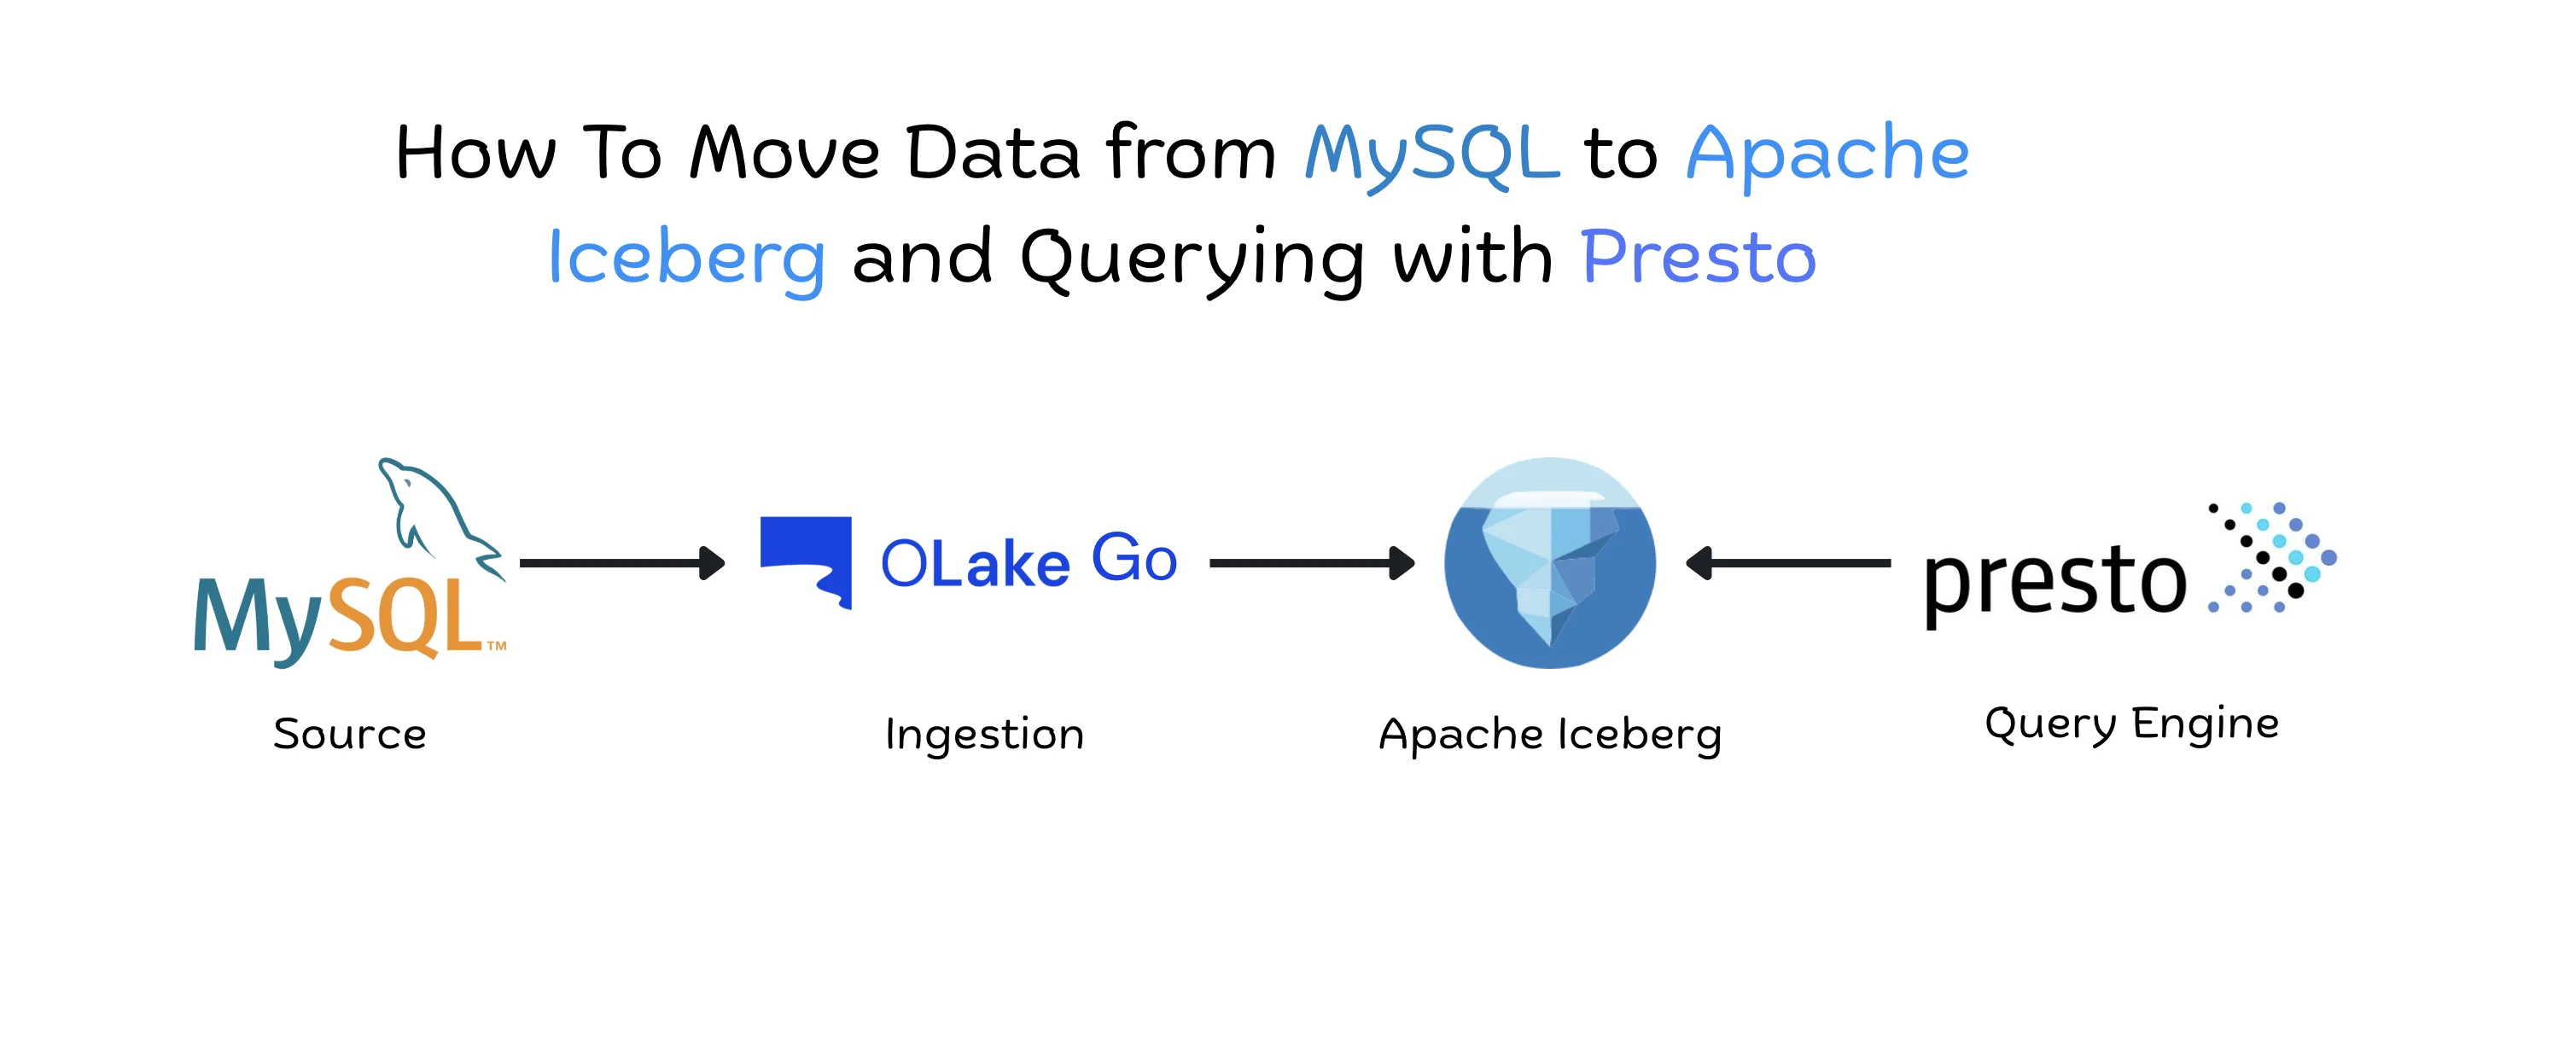
Replicate MySQL tables into Apache Iceberg with OLake Go CDC and query them in Presto. Step-by-step: connect MySQL, pick a catalog, run the sync, run SQL.
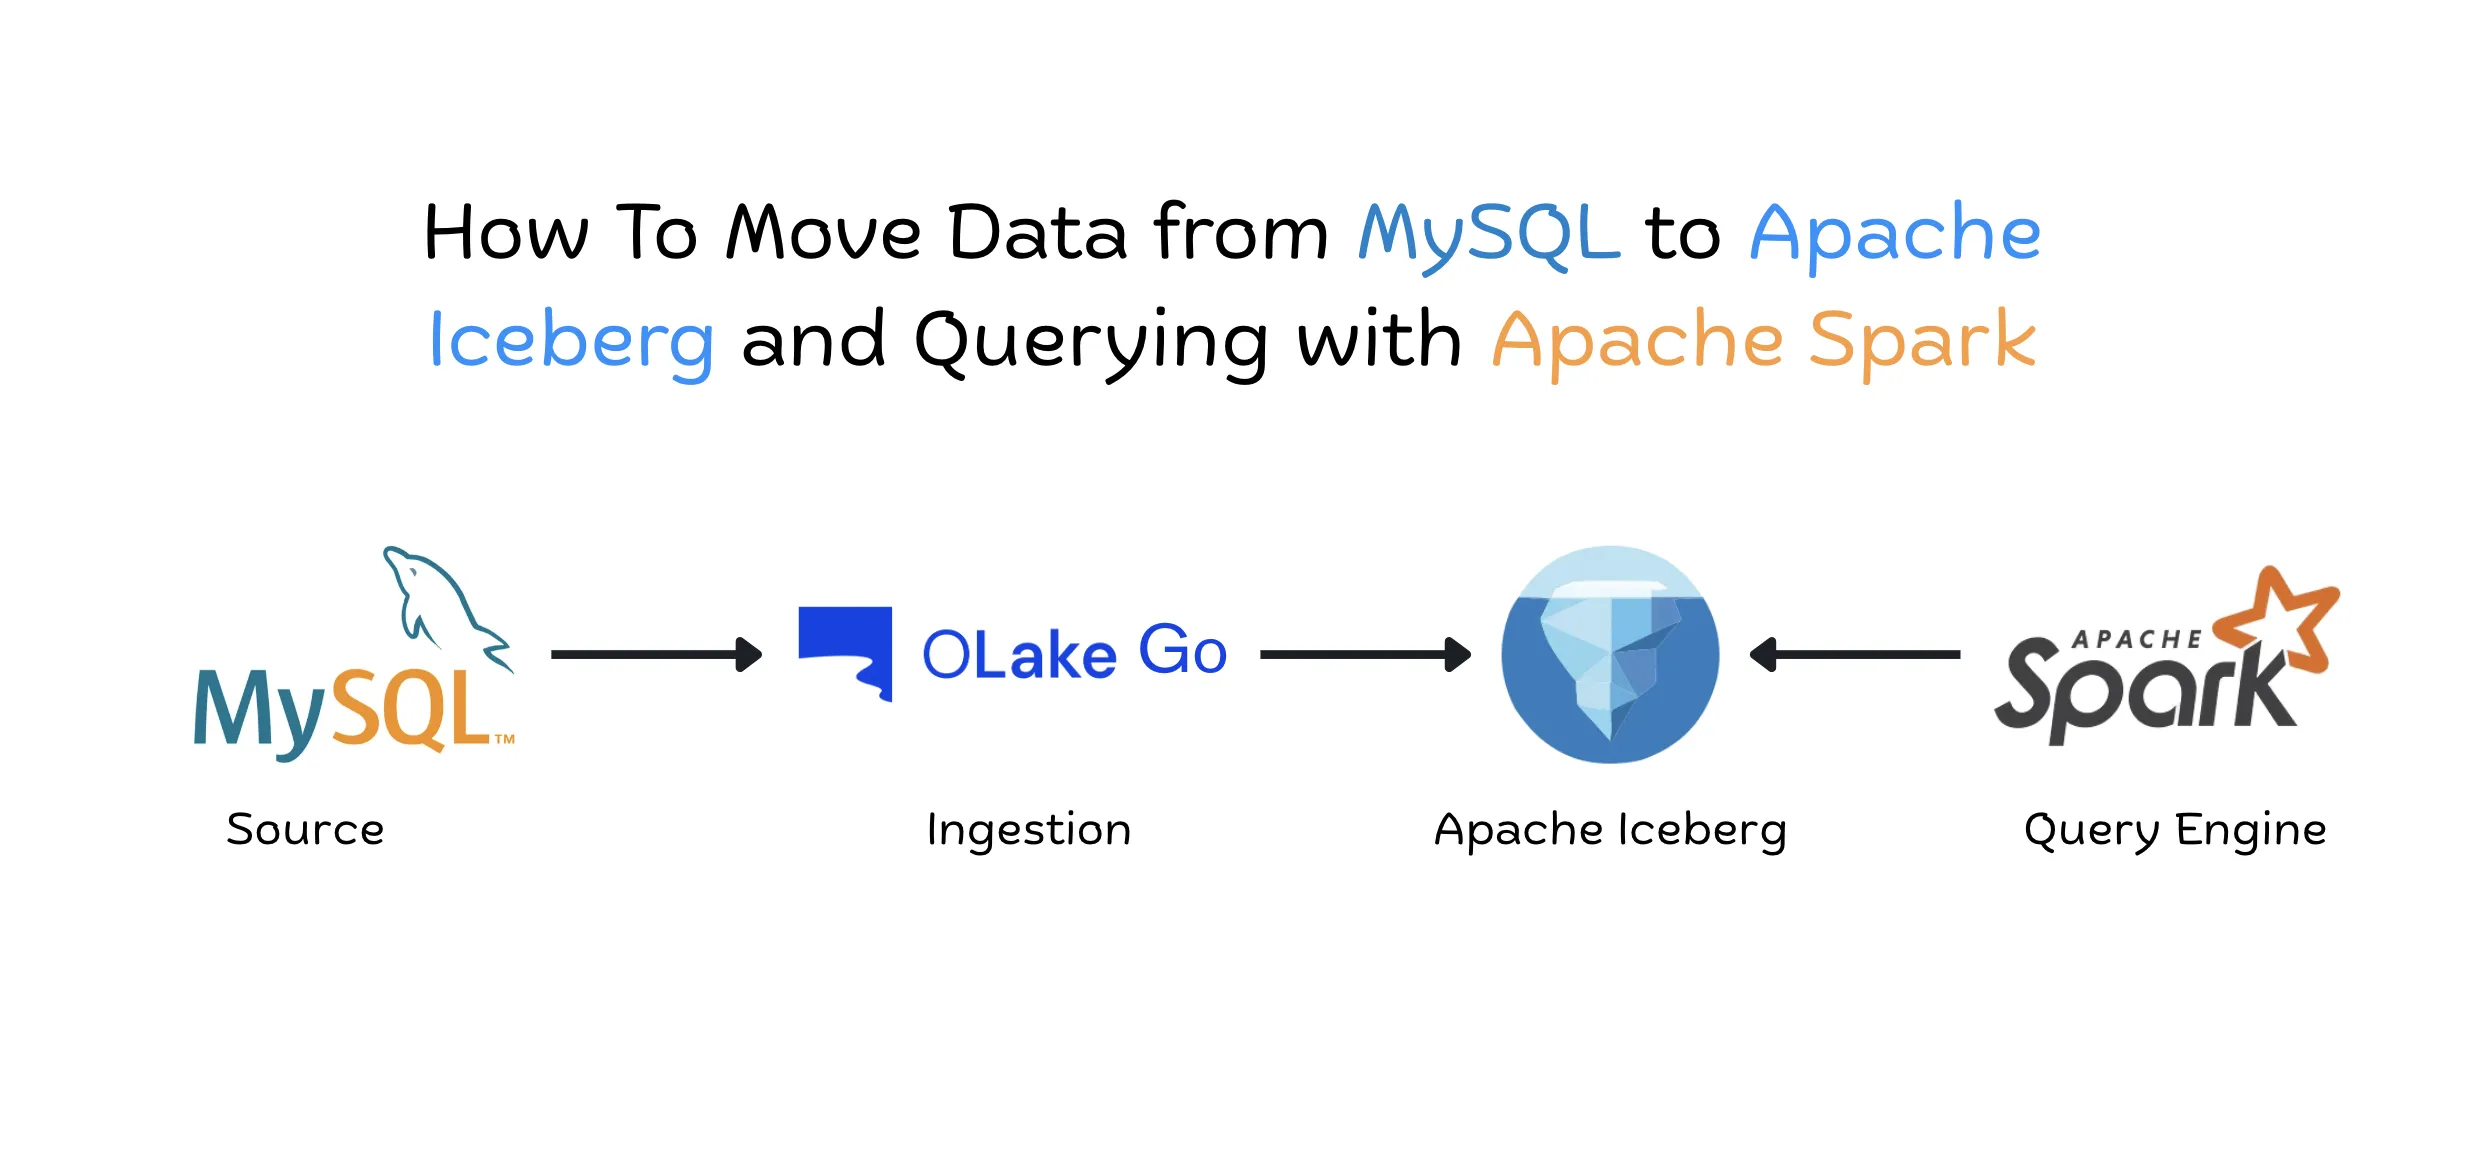
Replicate MySQL to Apache Iceberg with OLake Go and query it in Apache Spark. A step-by-step guide to setting up the source, catalog, job, sync and Spark SQL.
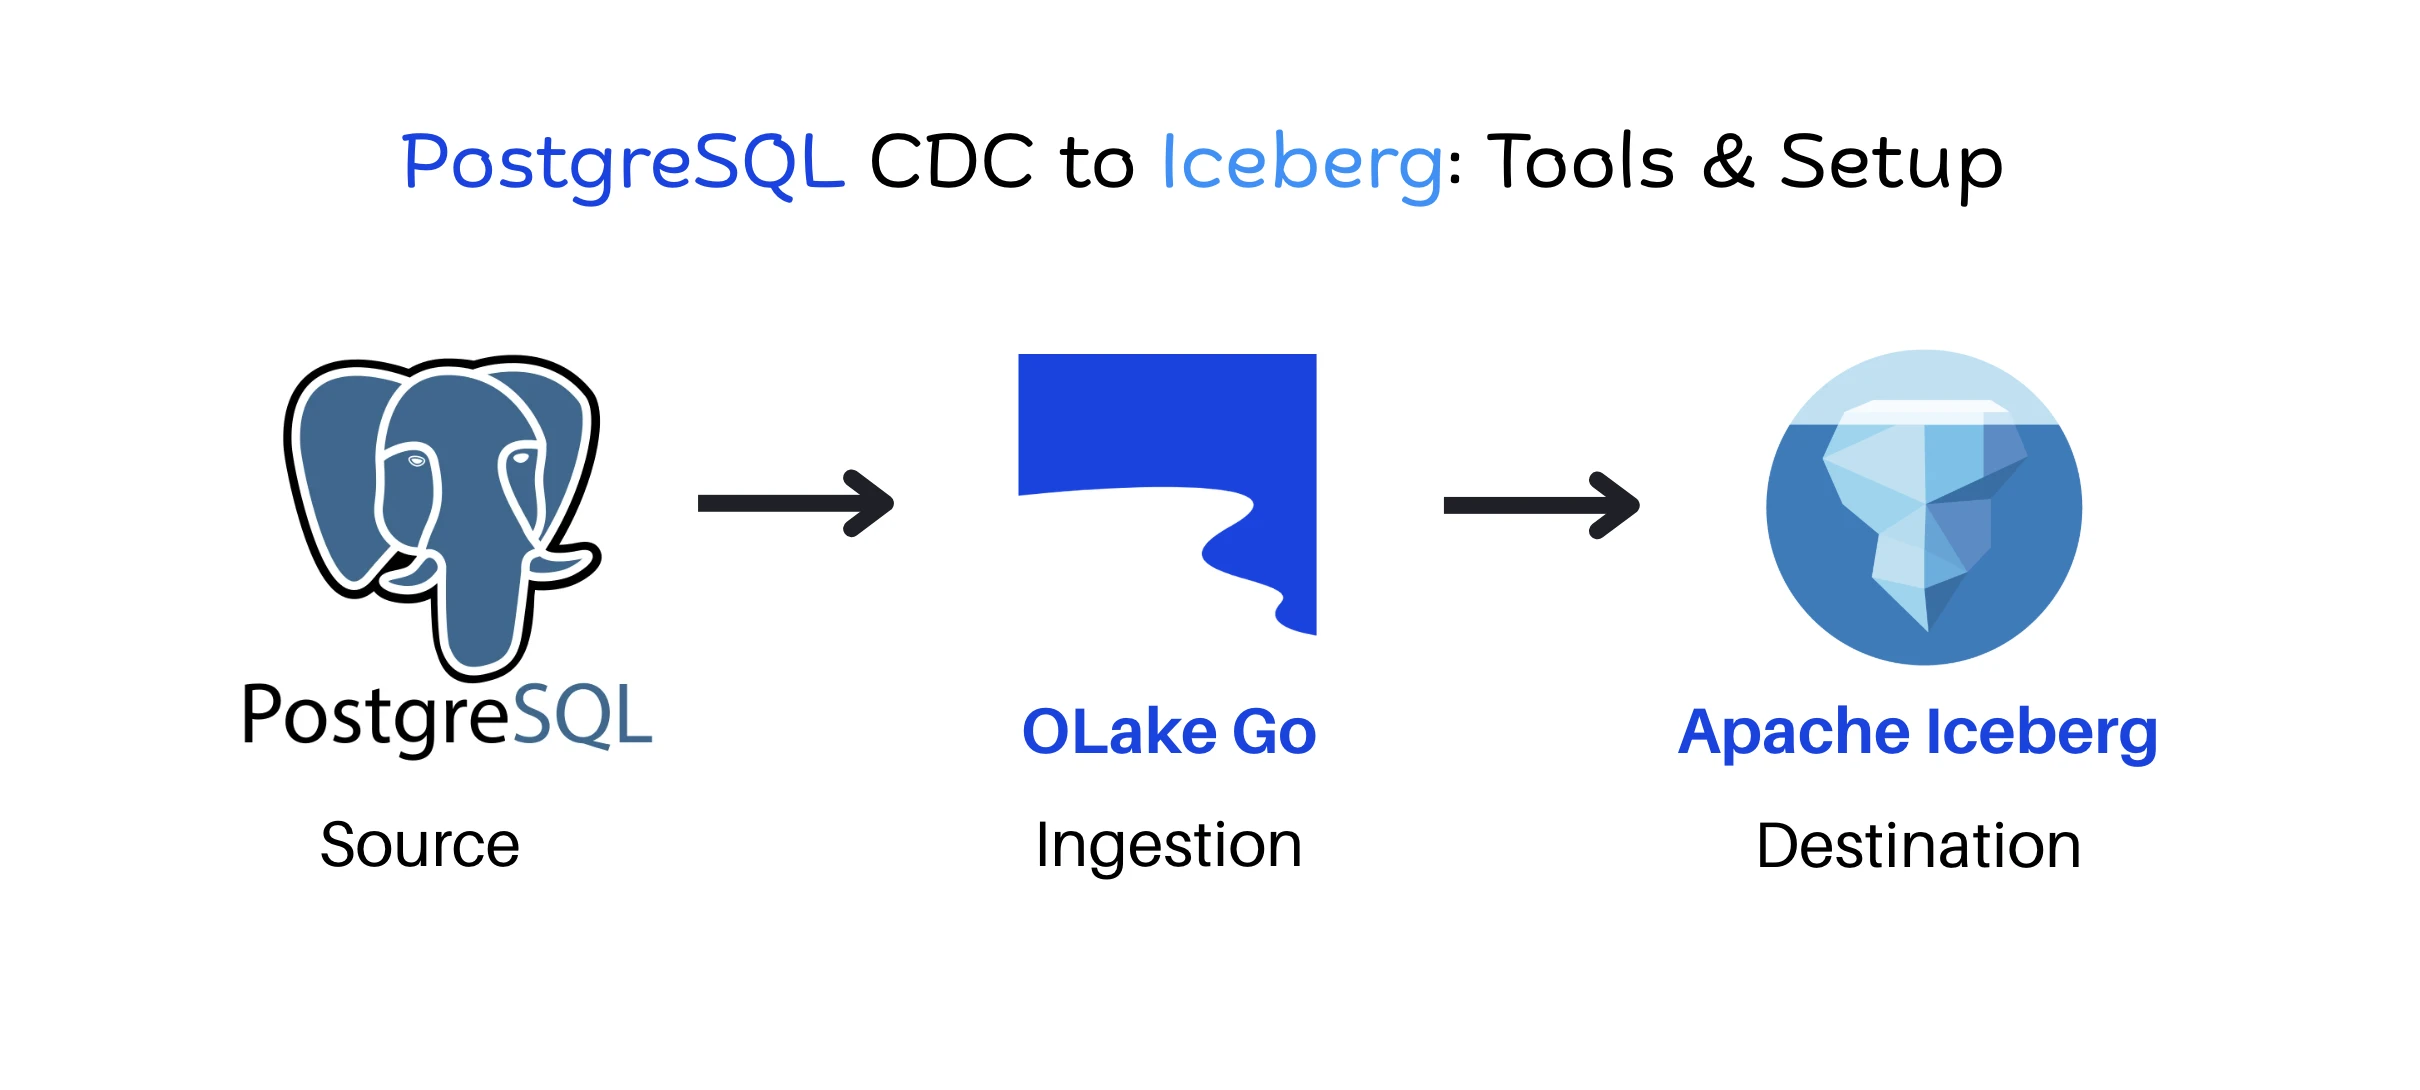
Learn how to replicate PostgreSQL CDC data to Apache Iceberg without Spark using Kafka, Flink, or OLake, including setup, architecture, and best practices.
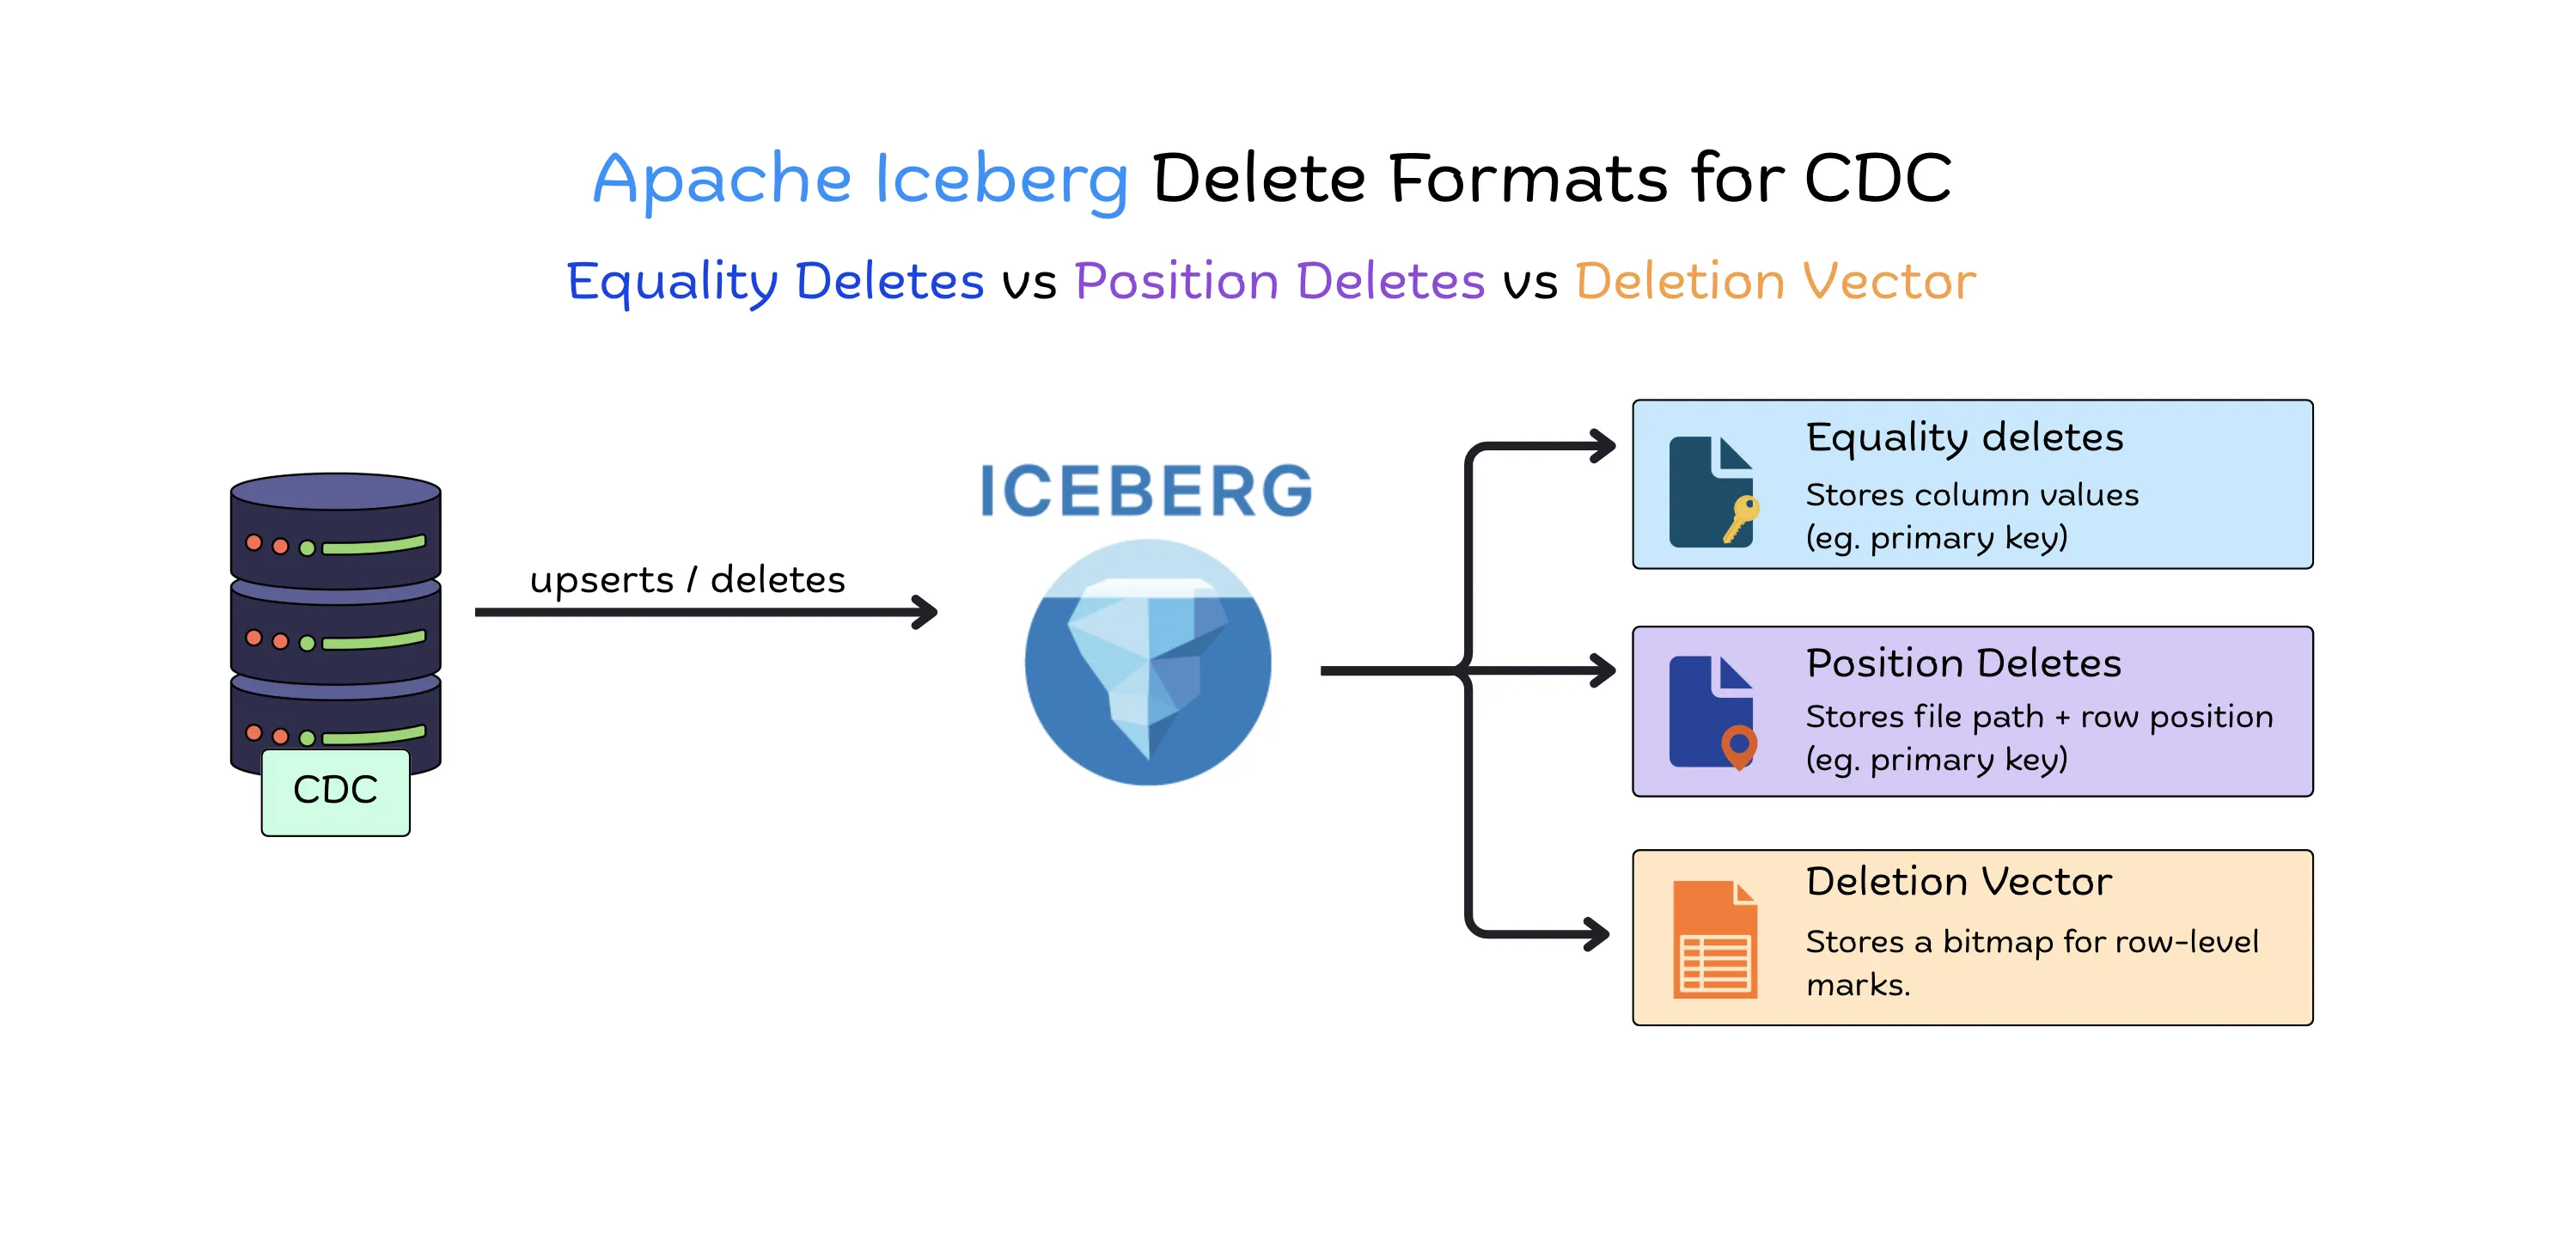
Equality deletes, position deletes, and deletion vectors compared for CDC pipelines: what each stores, which query engines can read them, what compaction fixes, and the table properties to set explicitly.