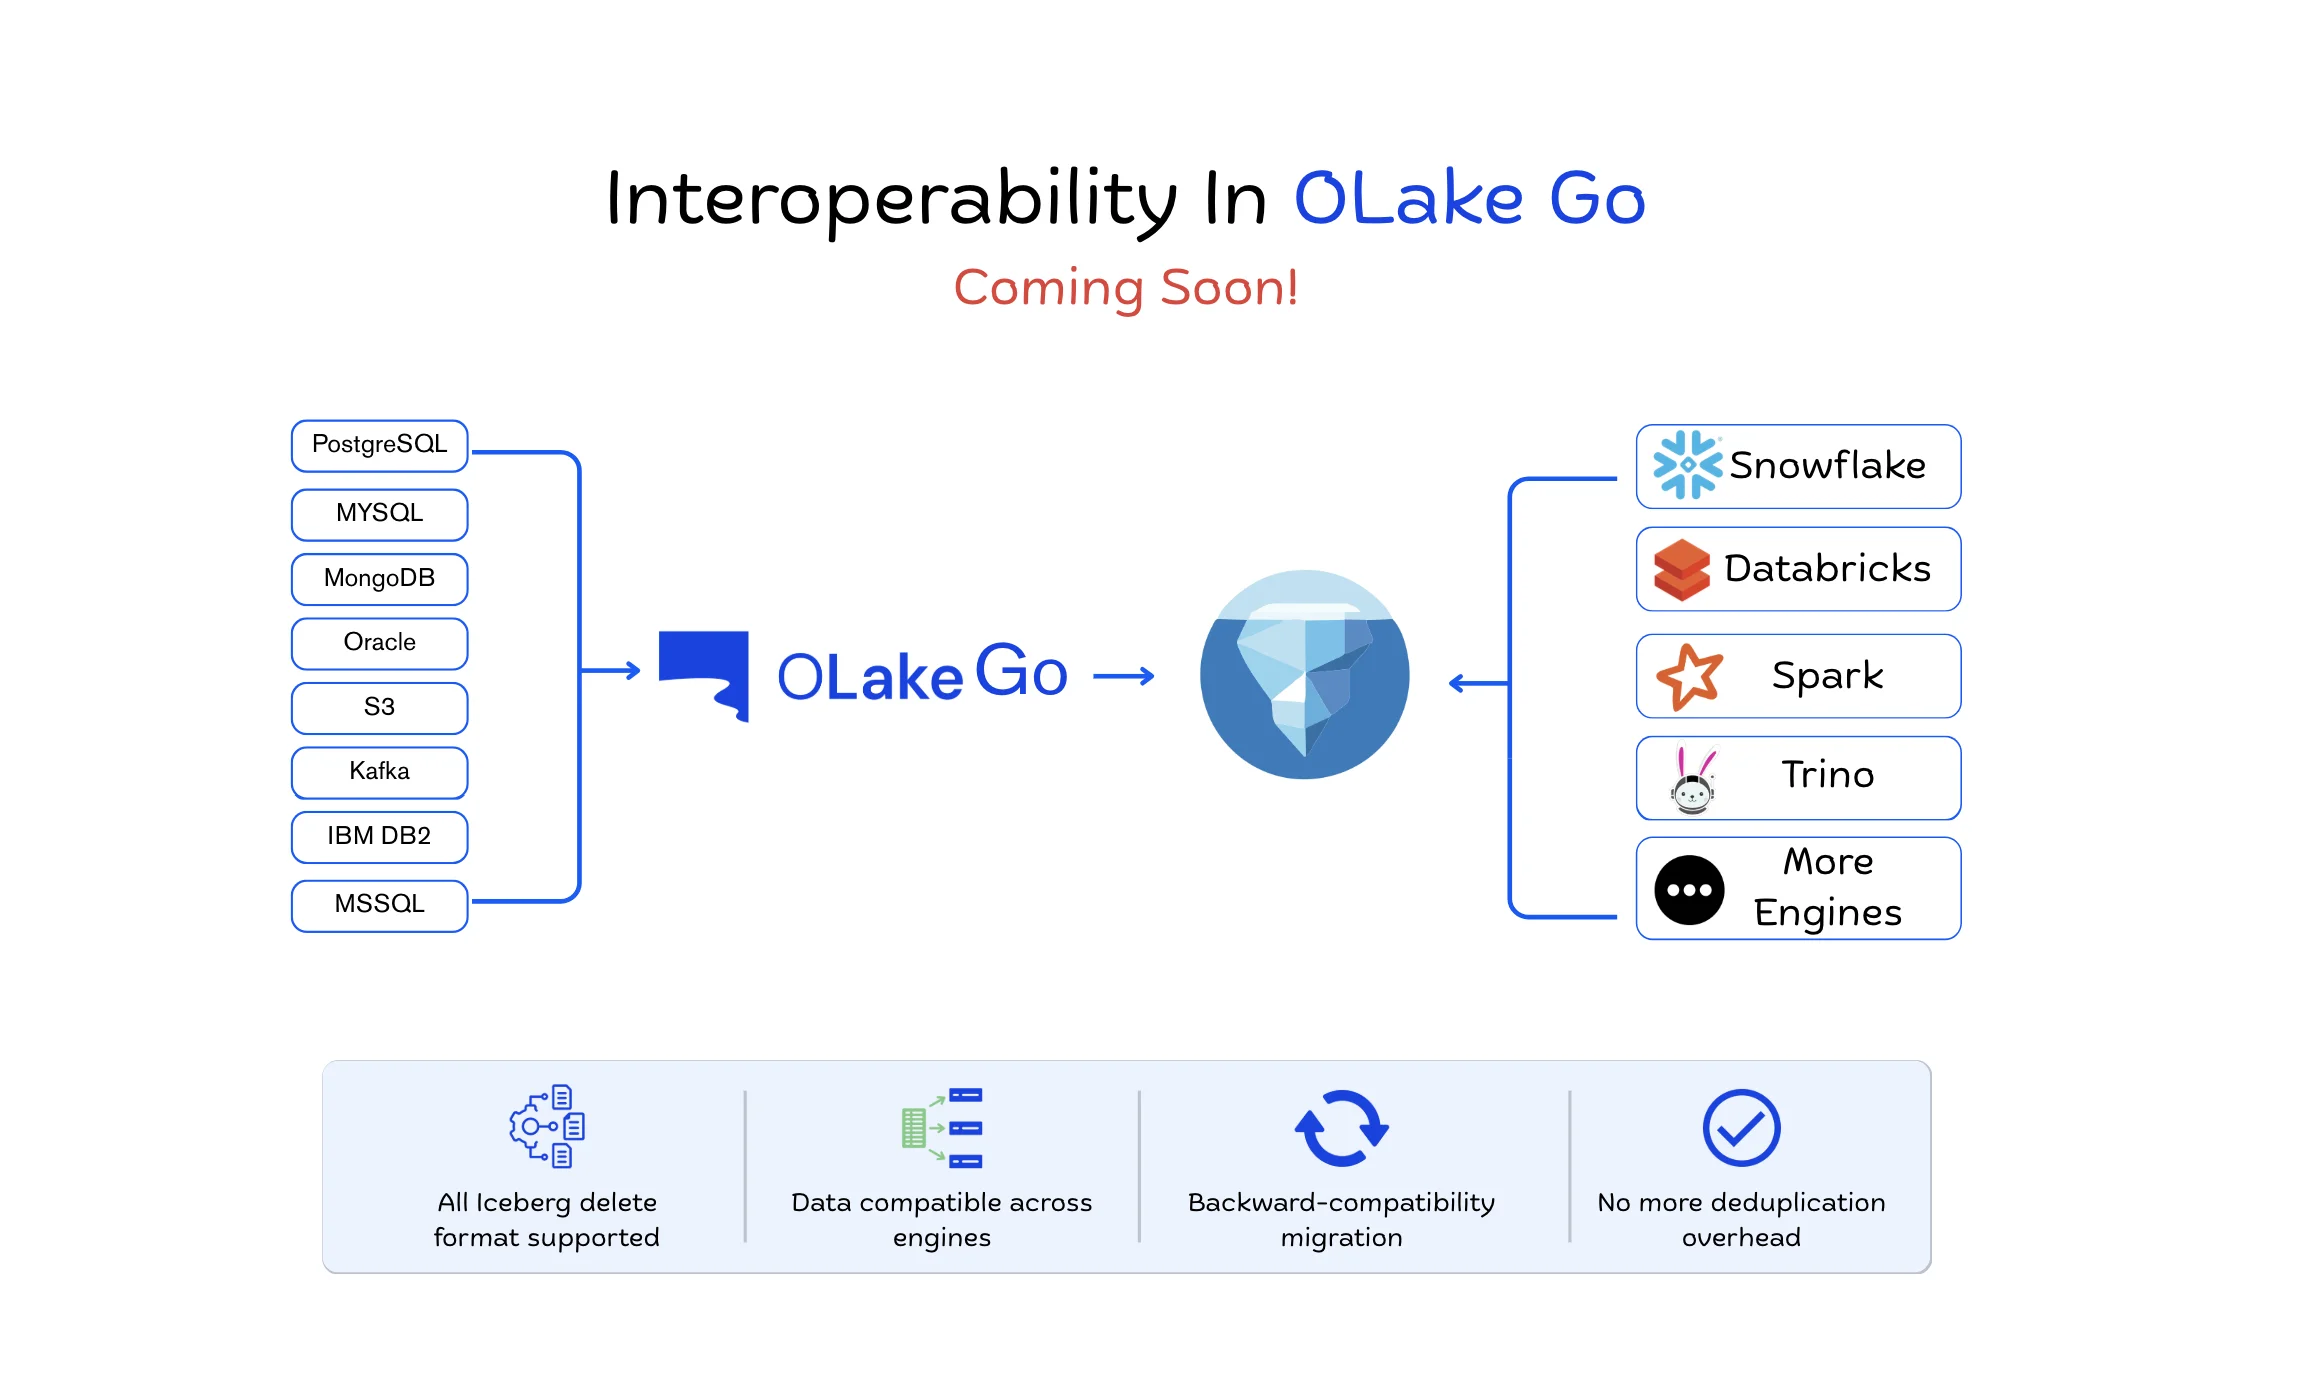
Iceberg Delete Format Interoperability in OLake Go: Equality, Position & Deletion Vectors
How OLake Go picks the right Iceberg delete format for your destination catalog and query engines, so tables are readable across Spark, Snowflake, Databricks, Athena, and Trino.
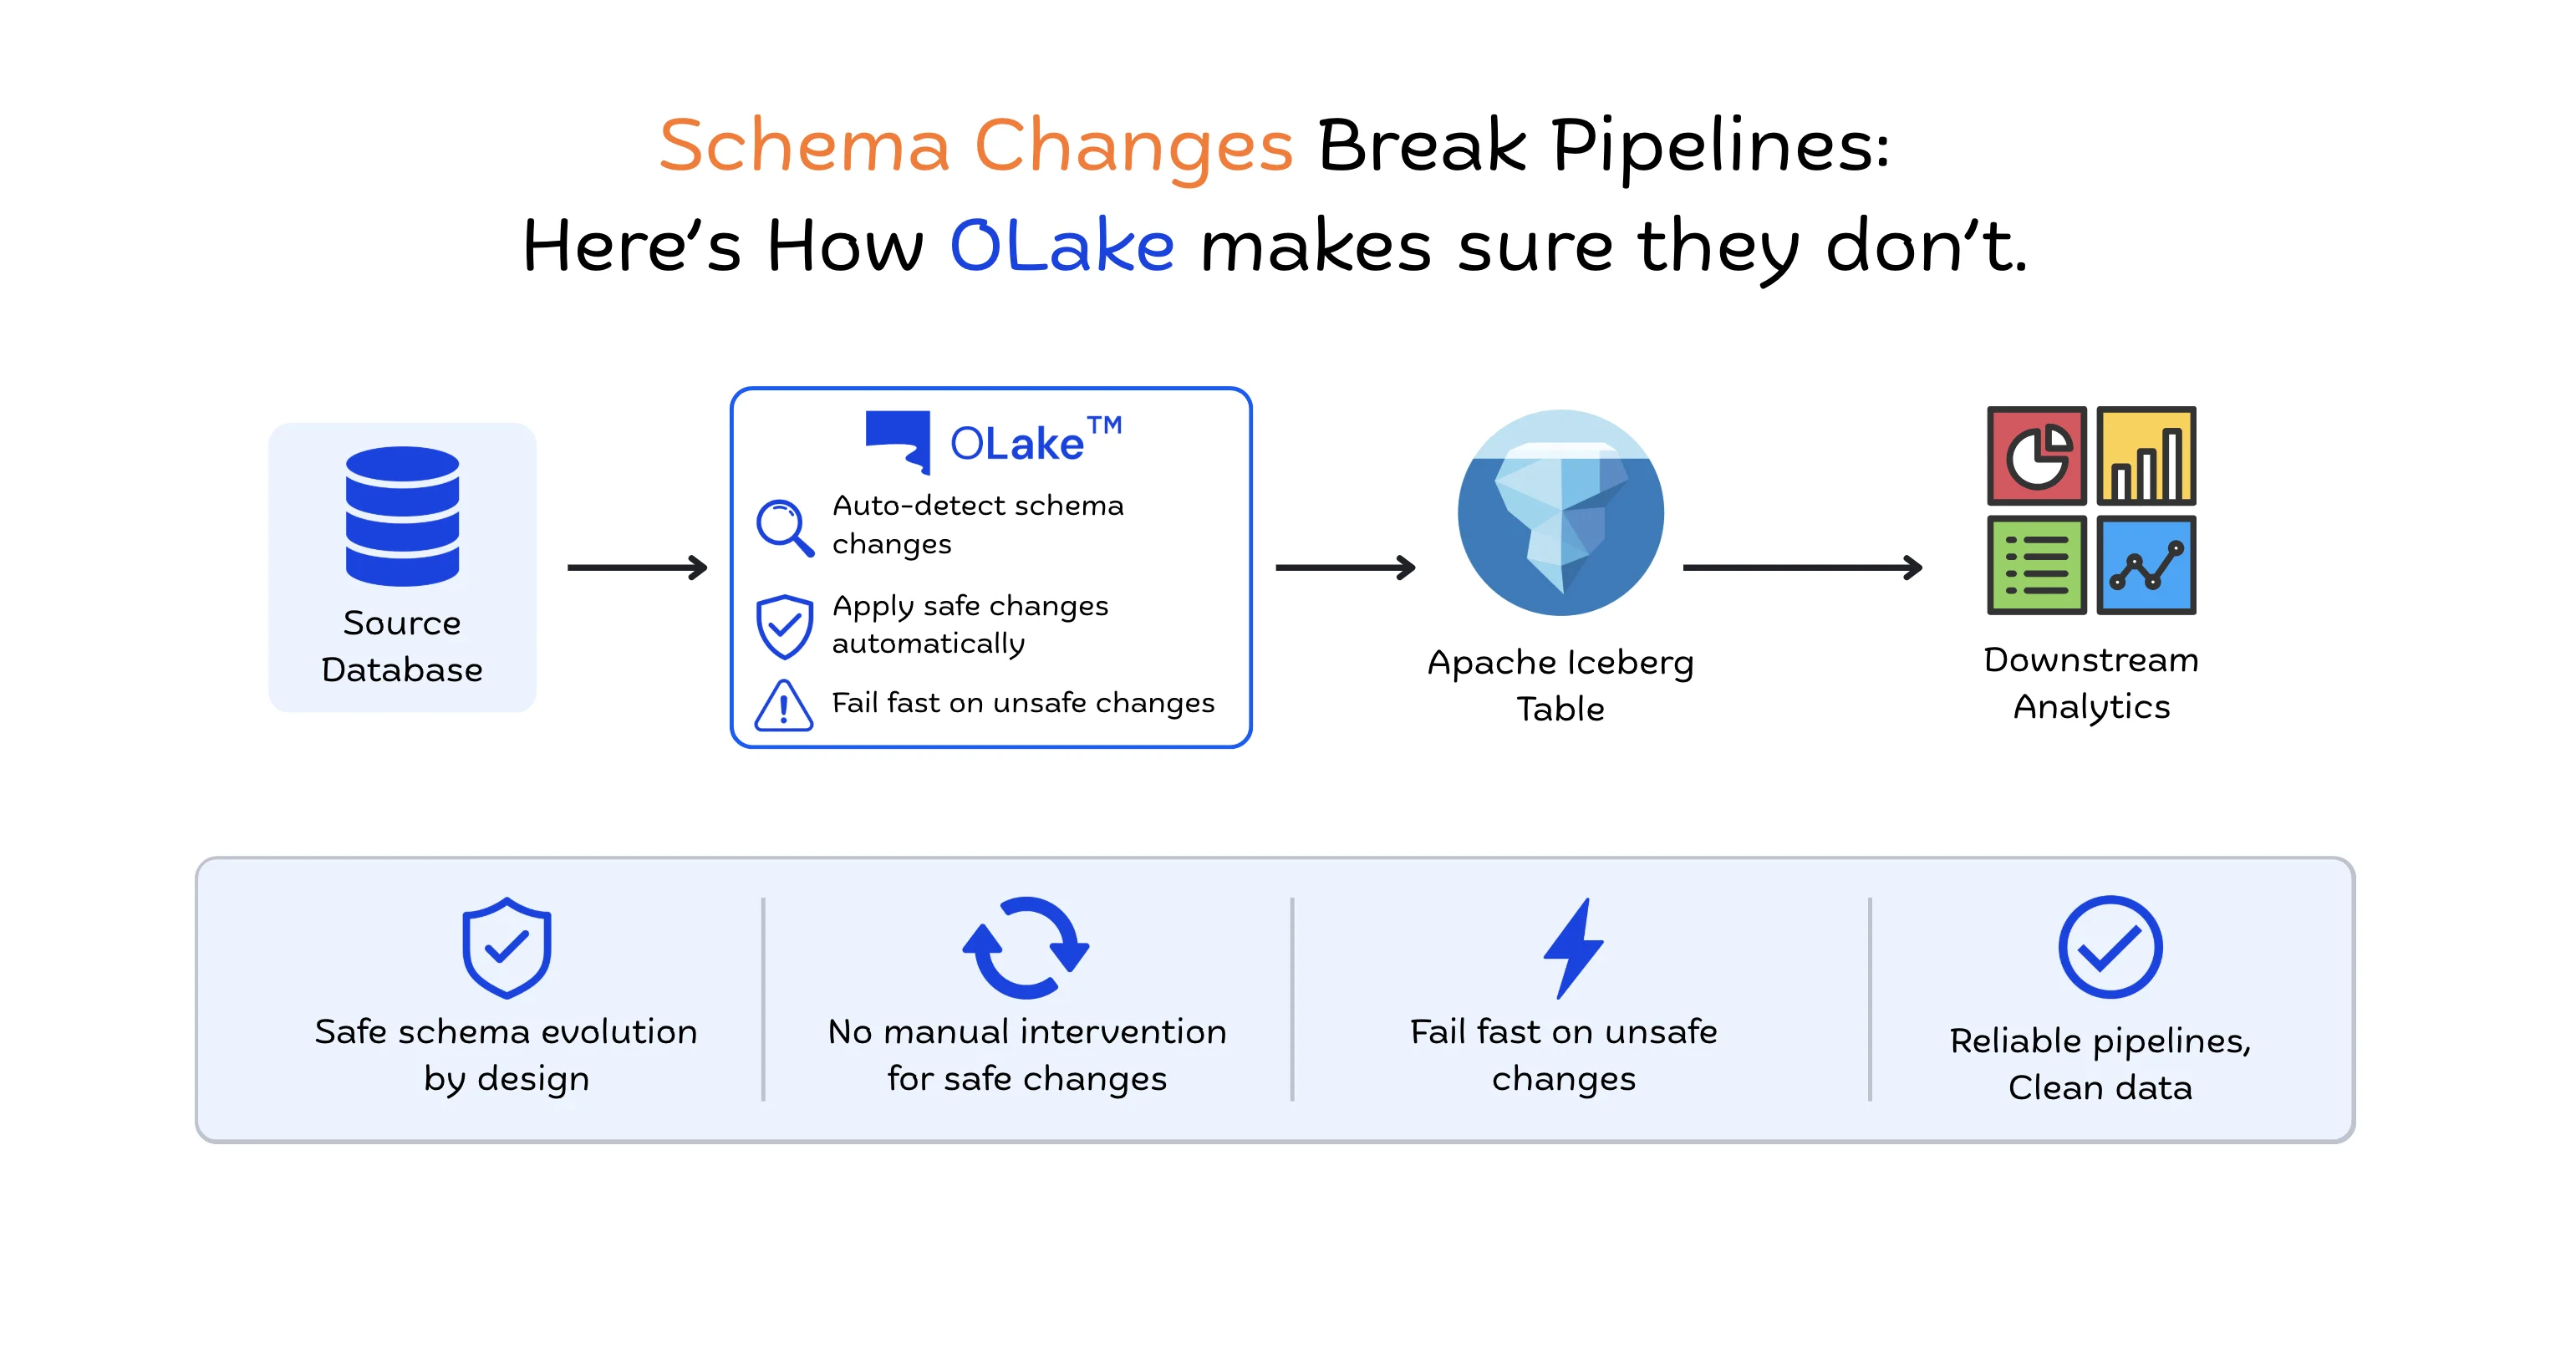
How OLake Go Handles Schema Evolution Without Breaking Your Pipeline
How OLake Go handles schema evolution into Apache Iceberg: automatic column adds, retained drops, safe type promotions, and explicit failures only where data would corrupt. Built on Iceberg's field-ID tracking, across Postgres, MySQL, MongoDB, and Kafka.
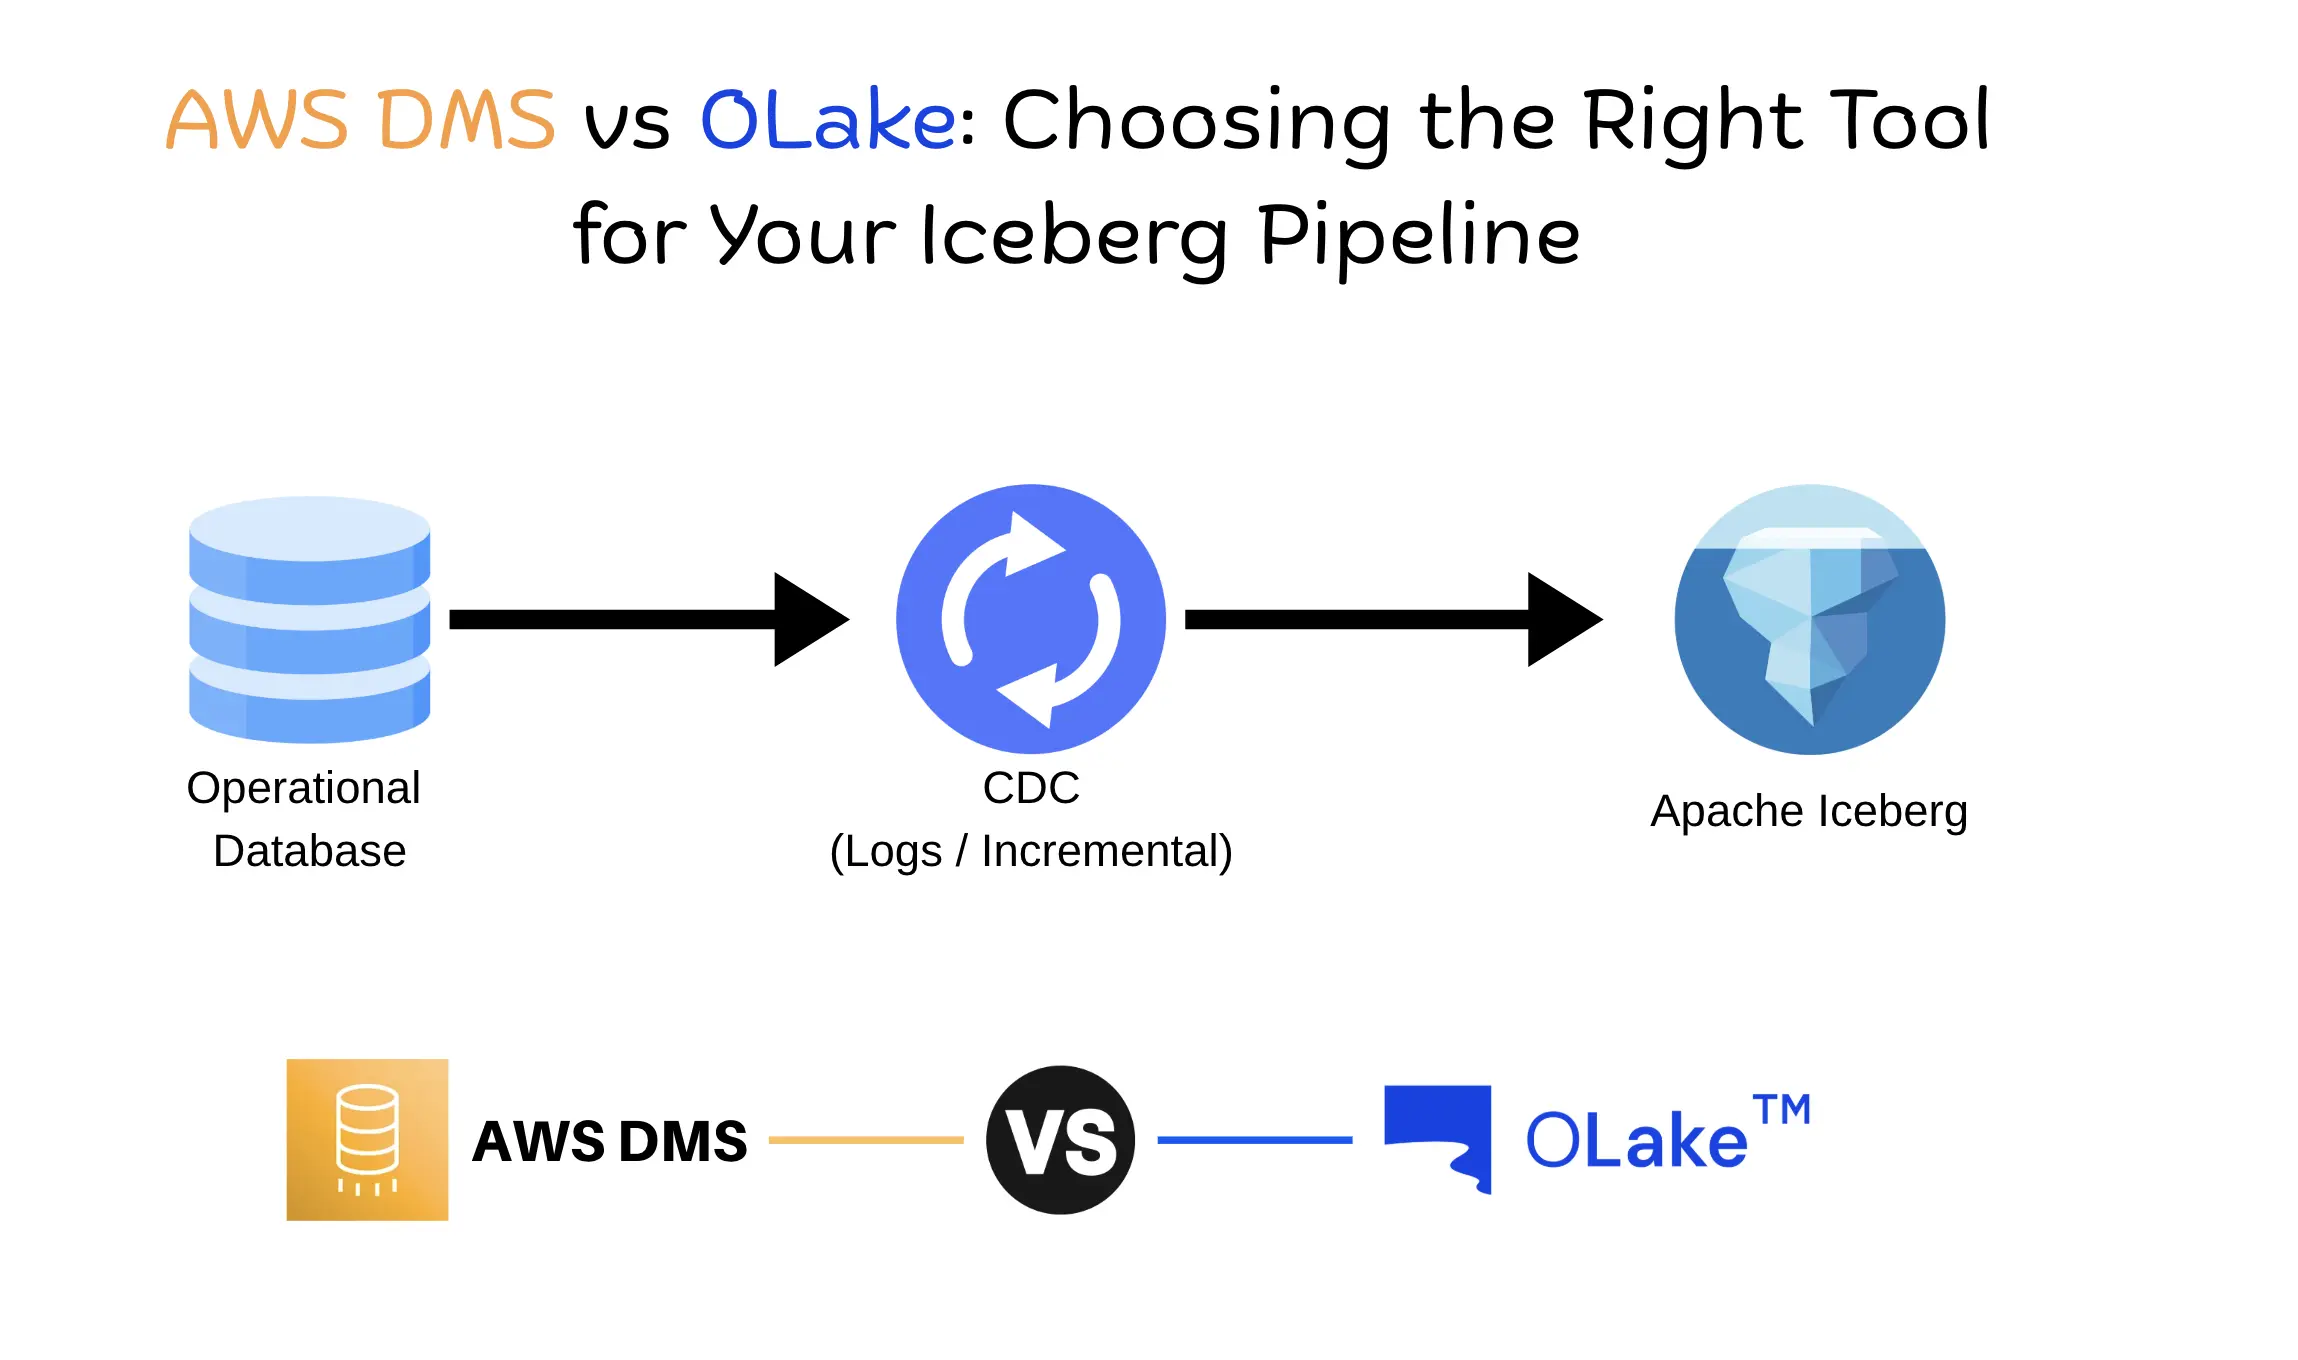
AWS DMS vs OLake Go: Choosing the Right Tool for Your Iceberg Pipeline
Compare AWS DMS and OLake Go for database-to-Iceberg pipelines: setup, CDC, schema evolution, scaling, and cost, with benchmark numbers on over 4 billion rows.
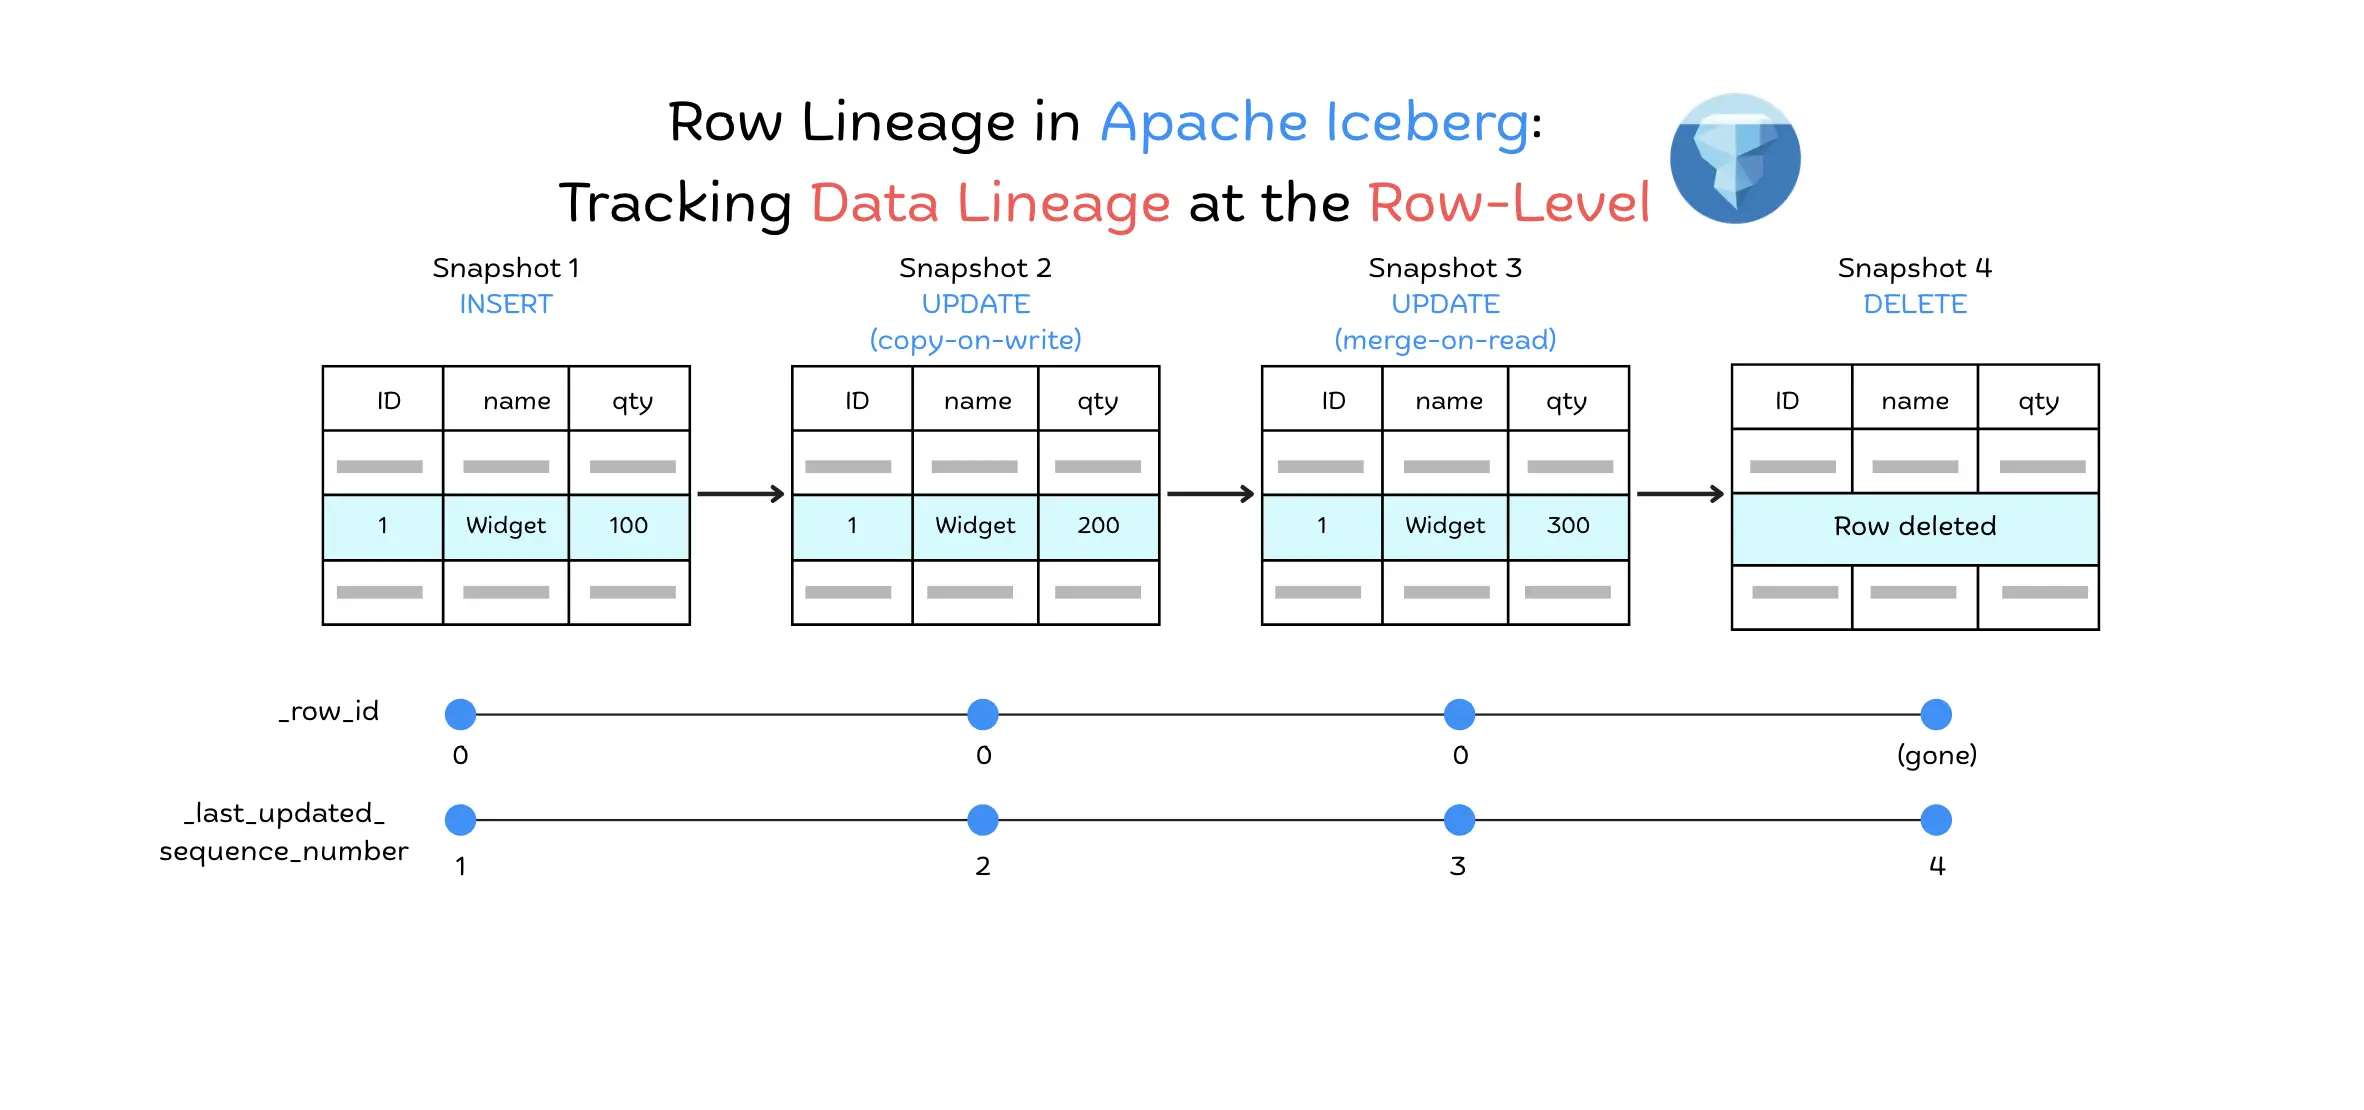
Apache Iceberg Row Lineage: Tracking Data Lineage at the Row-Level
How Apache Iceberg v3 row lineage tracks row-level changes for CDC, with a tested look at _row_id preservation across Spark 3.5 and Iceberg 1.9 vs 1.10.

Apache Iceberg Observability: Monitoring & Metrics for Data Lake Tables
How Apache Iceberg turns table metadata into a first-class observability layer, enabling proactive monitoring, anomaly detection, and automated maintenance for modern data lakes.
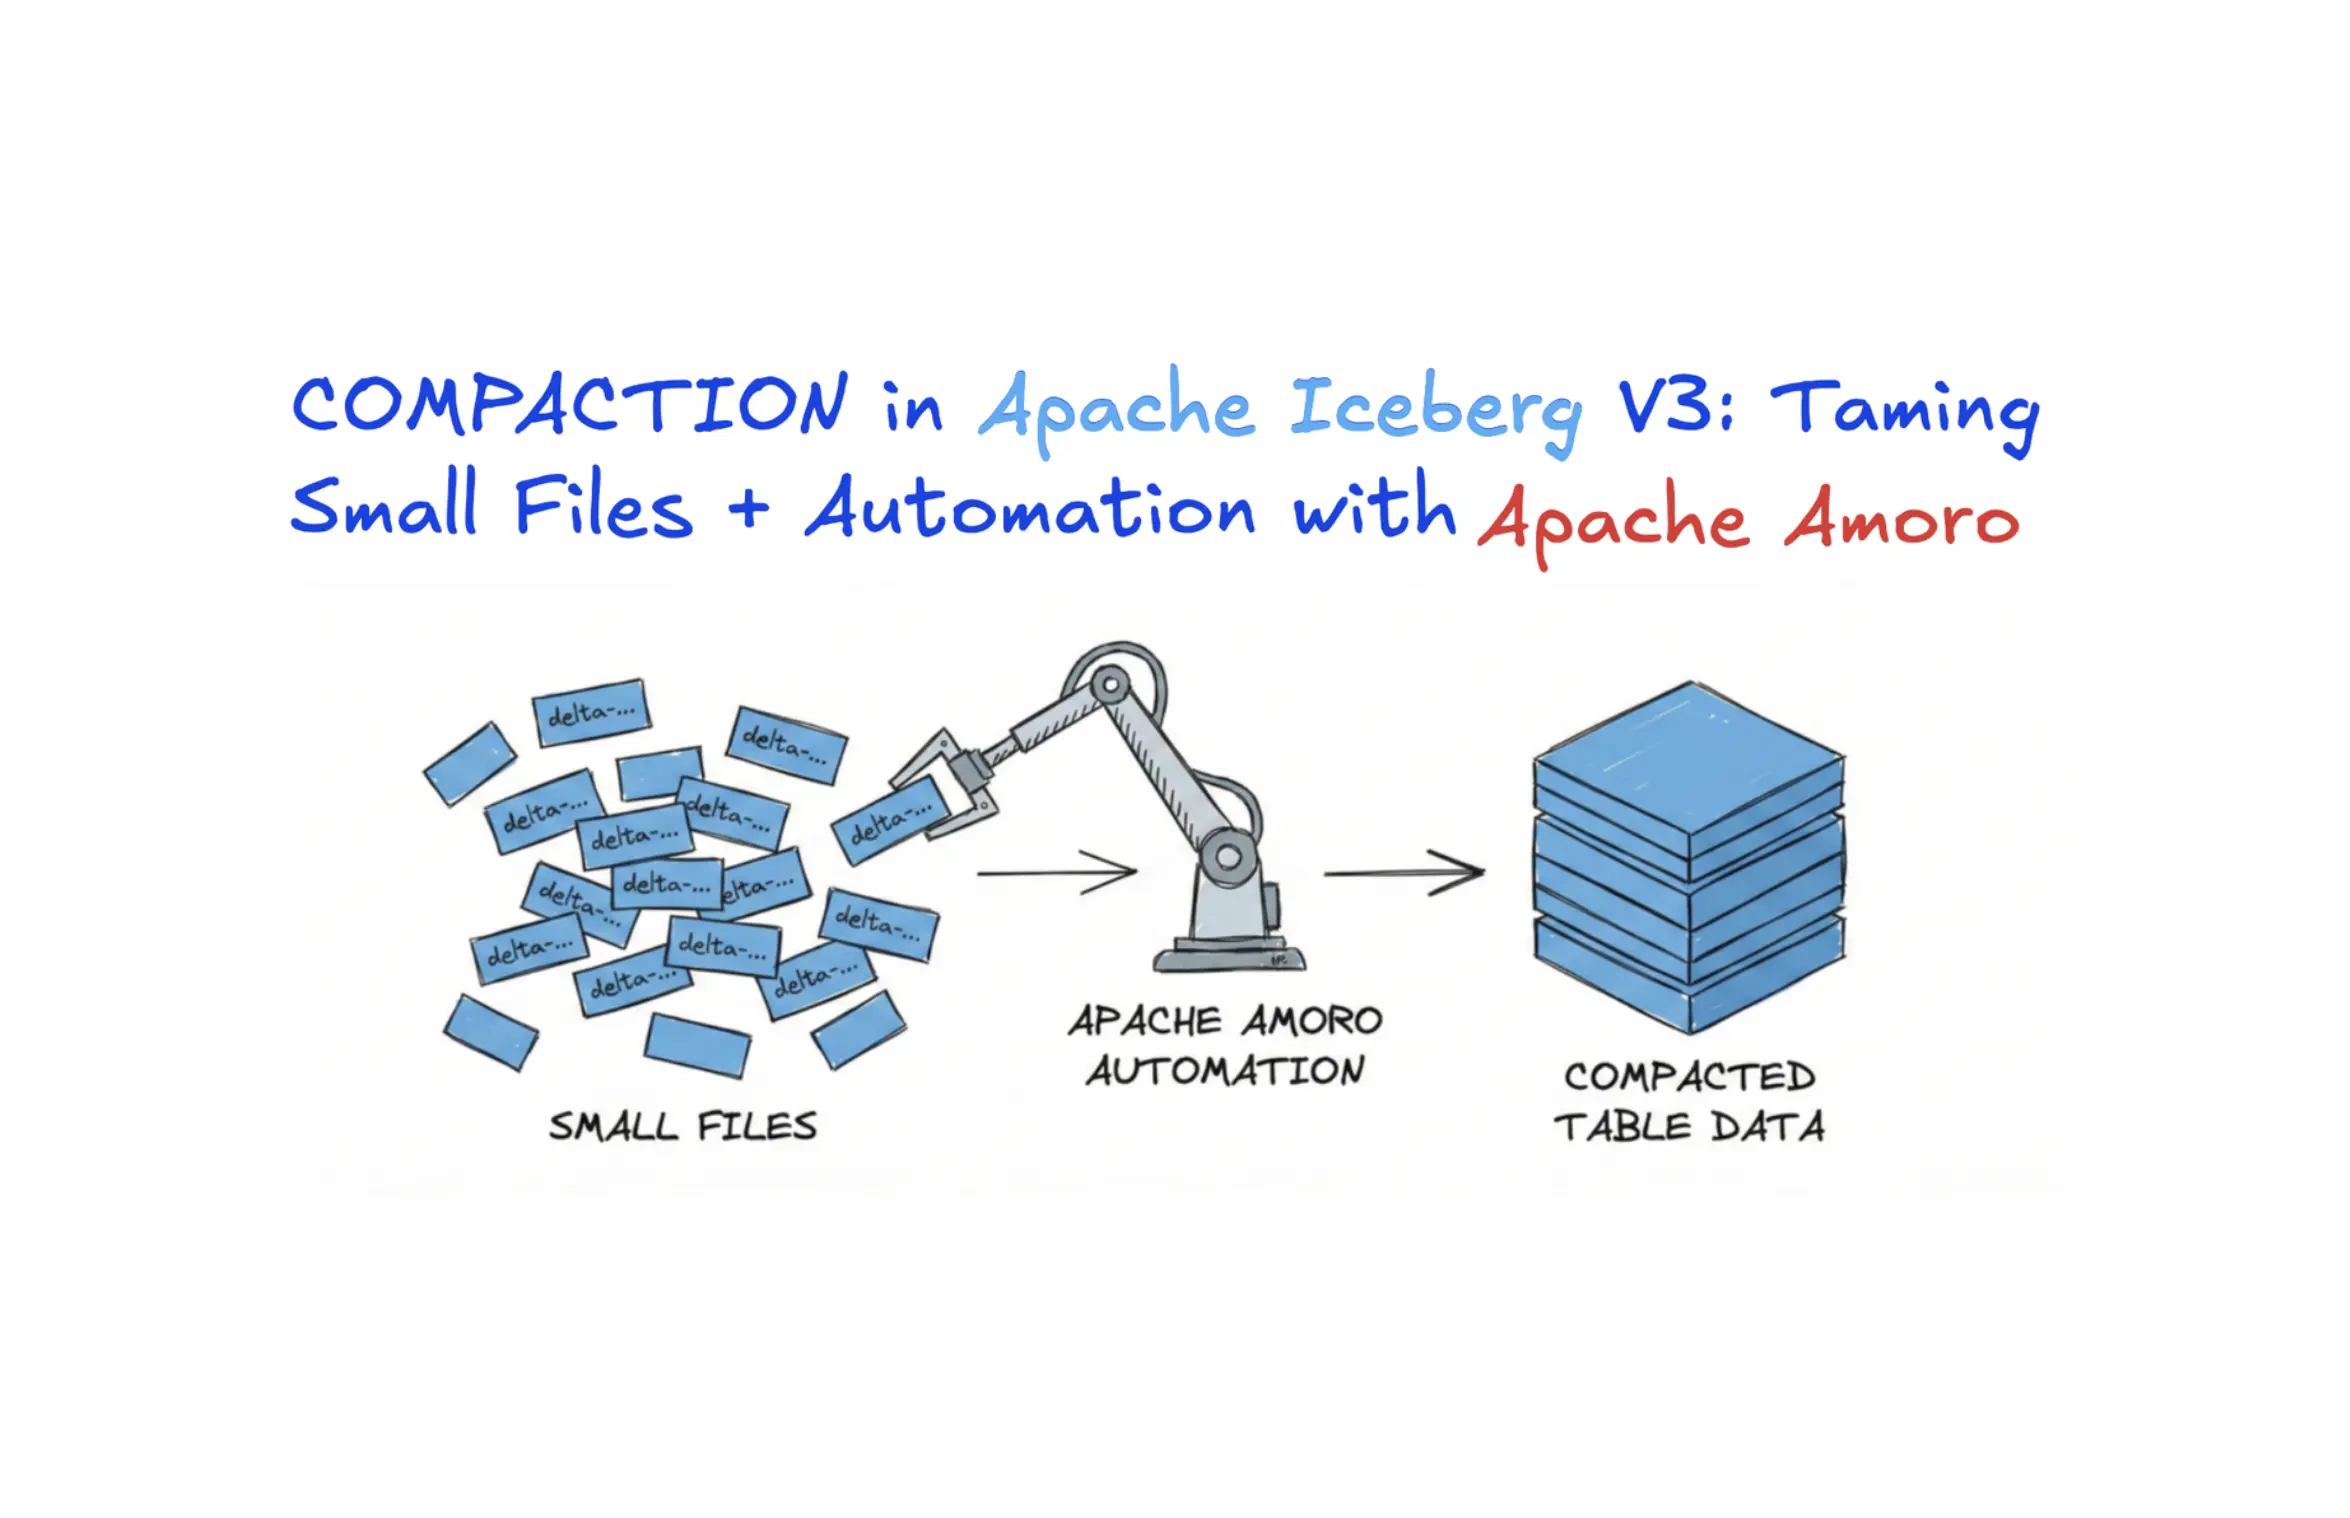
How to Compact Apache Iceberg Tables: Small Files + Automation with Apache Amoro™
A practical guide to fixing small-file bloat in Apache Iceberg, showing when and how to run compaction, the performance gains you can expect, and how Apache Amoro™ automates it to turn Iceberg tables into self-optimizing lakehouses.