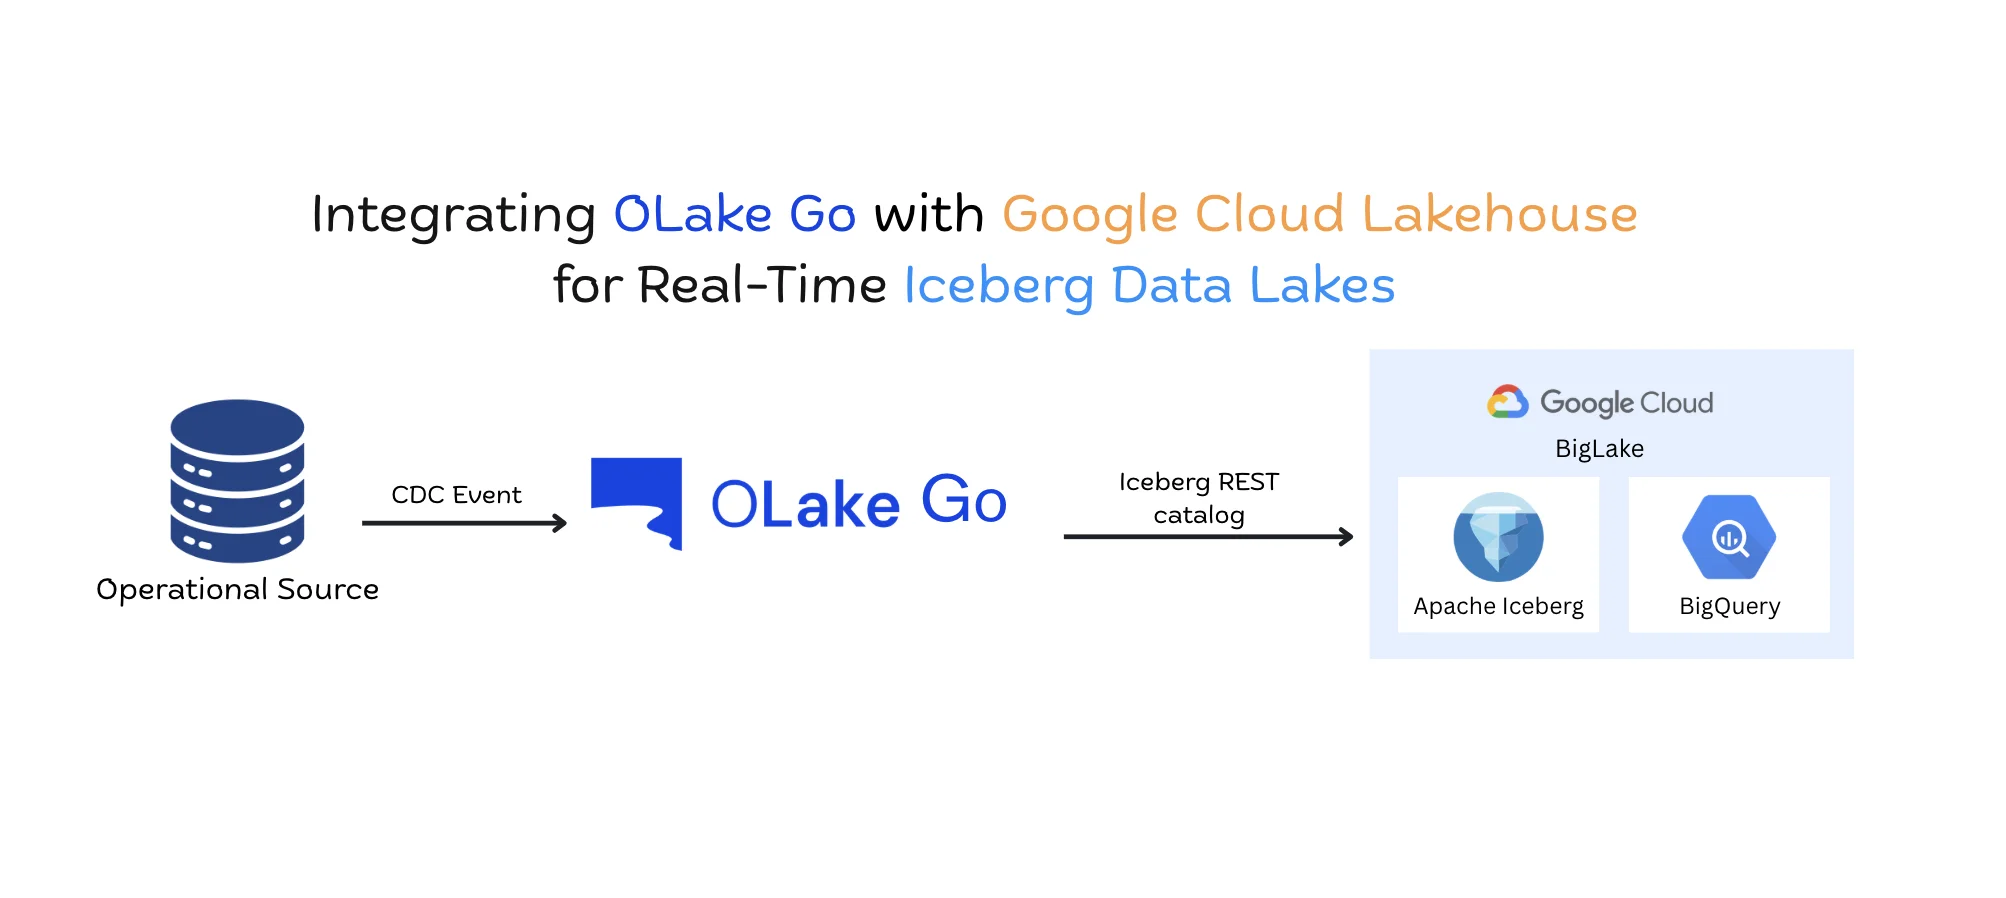
Postgres CDC to Iceberg on Google Cloud Lakehouse with OLake Go
Stream Postgres CDC into Apache Iceberg tables on Google BigLake with OLake Go and query live data in BigQuery. A step-by-step setup with no Kafka or Spark.
Stream Postgres CDC into Apache Iceberg tables on Google BigLake with OLake Go and query live data in BigQuery. A step-by-step setup with no Kafka or Spark.
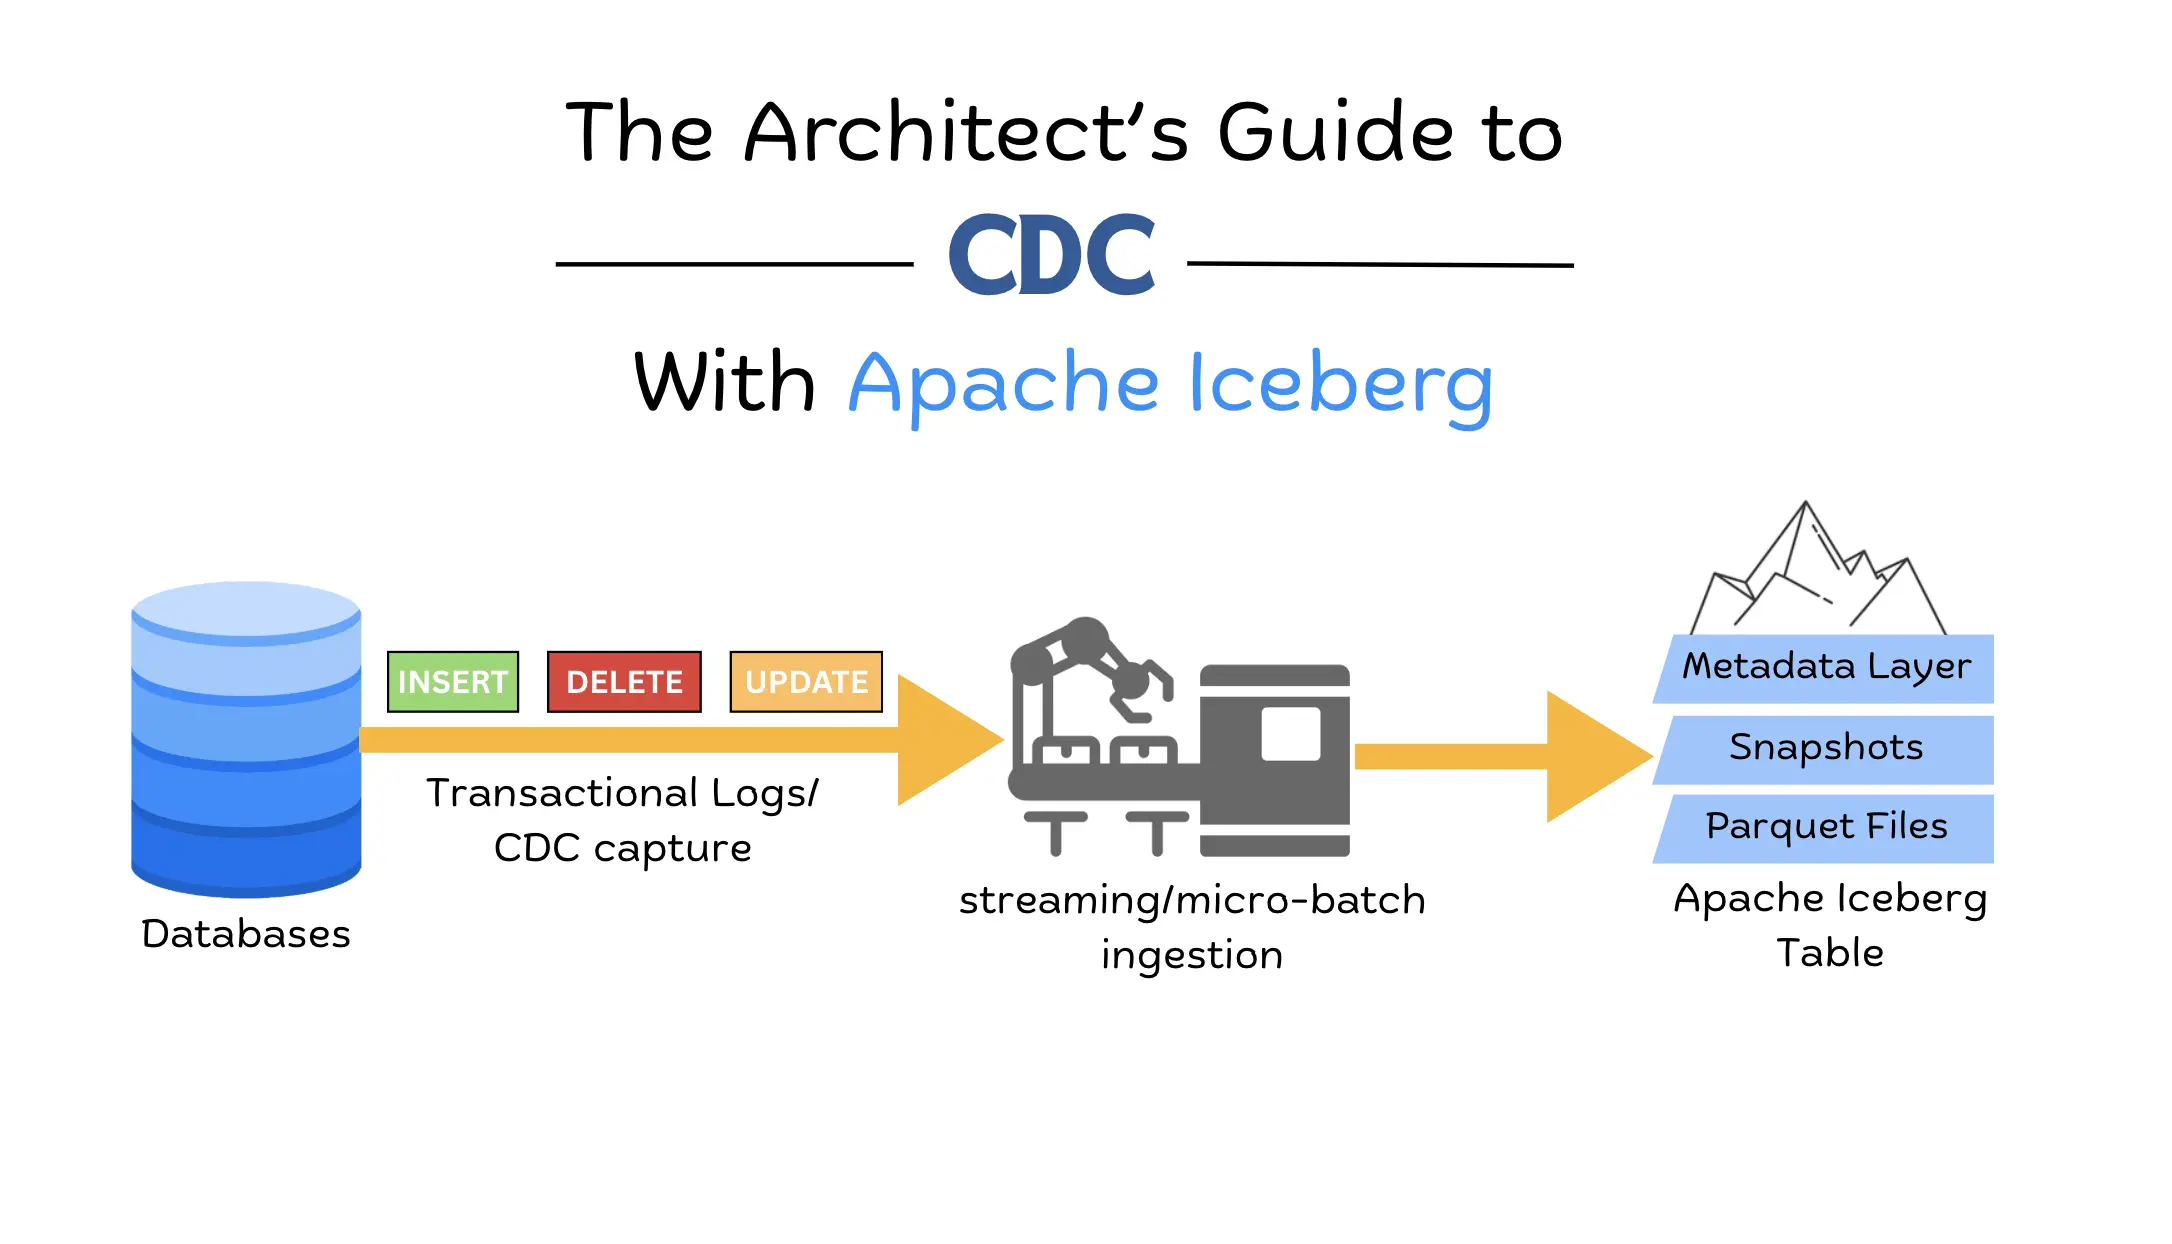
Learn how to design reliable CDC pipelines into Apache Iceberg, covering ingestion patterns, delete handling, and architecture best practices.
Data warehouse vs data lakehouse compared: core architectural differences, feature capabilities, and when to choose each approach for your data stack.
Data lake vs data lakehouse: how a lakehouse adds ACID transactions, schema enforcement and governance to object storage and ends dual-tier systems.
Parquet is a columnar file format and Iceberg is a table format built on top of it. See how they differ on schema evolution, transactions and partitioning.
How Iceberg metadata works: the catalog, metadata.json, snapshots, manifest lists and manifest files, and how they enable time travel, pruning and ACID.