How To Move Data from MySQL to Apache Iceberg and Querying with Presto
7 min read
Introduction
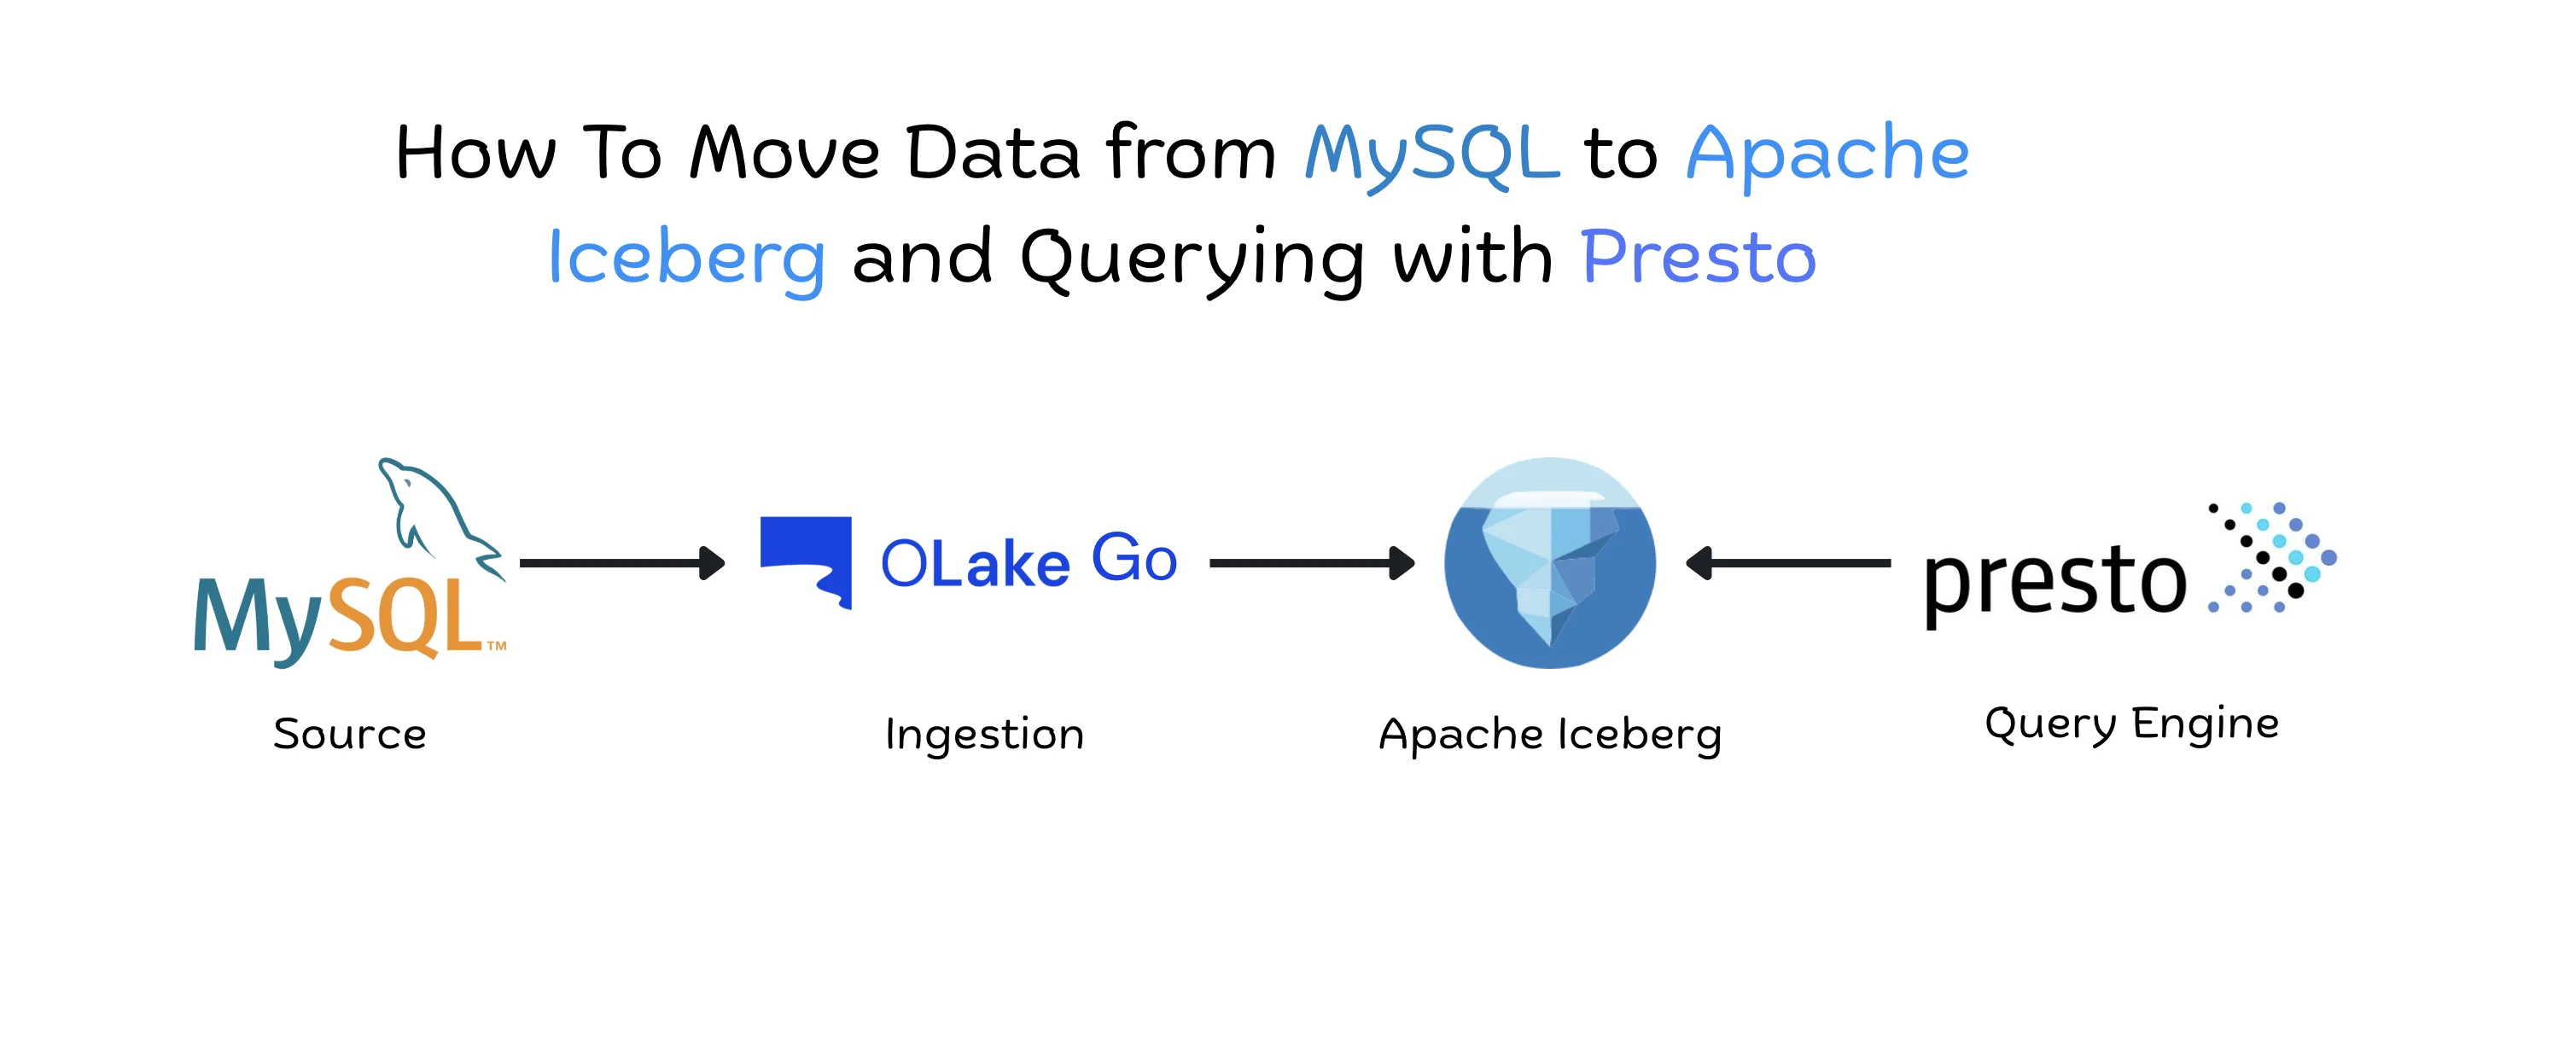
MySQL is built to serve your application: fast single-row reads, quick writes, and lots of short transactions. Ask it to scan millions of rows for a dashboard or an ad-hoc analyst question, and it starts competing with the very traffic it exists to serve. Presto was designed for the opposite job: distributed SQL that reads large datasets in parallel. The missing piece is a place for that data to live outside MySQL.
That place is Apache Iceberg. OLake Go captures changes from MySQL using CDC and writes them into Iceberg tables on object storage, registered in the catalog you already use. Presto (v0.288+) reads those tables through its Iceberg connector, so analysts get fresh MySQL data to query while the production database keeps doing its own work.
In this guide you'll connect MySQL in OLake Go, point it at an Iceberg destination, set Presto as the target query engine, choose the tables to replicate, run the sync, and query the results from the Presto CLI.
Step 1: Set Up the Source and Destination
The OLake Go docs explain how to set up MySQL and Iceberg, so follow the links below for each one. Pick the catalog you want to use and follow the link below to help you set it up. To see which engines work with which catalogs, check Compatibility with Query Engines.
When both connection tests pass, you can move on to the next step.
| Source | Setup Guide |
|---|---|
| MySQL | Link |
| Destination | Catalog | Link |
|---|---|---|
| Apache Iceberg | HIVE | Link |
| REST | Link | |
| NESSIE | Link | |
| AWS GLUE | Link | |
| JDBC | Link | |
| Polaris | Link | |
| BigLake | Link | |
| Lakekeeper | Link | |
| Unity | Link | |
| S3 tables | Link | |
| Horizon | Link |
Step 2: Create a Job and Select the Query Engine
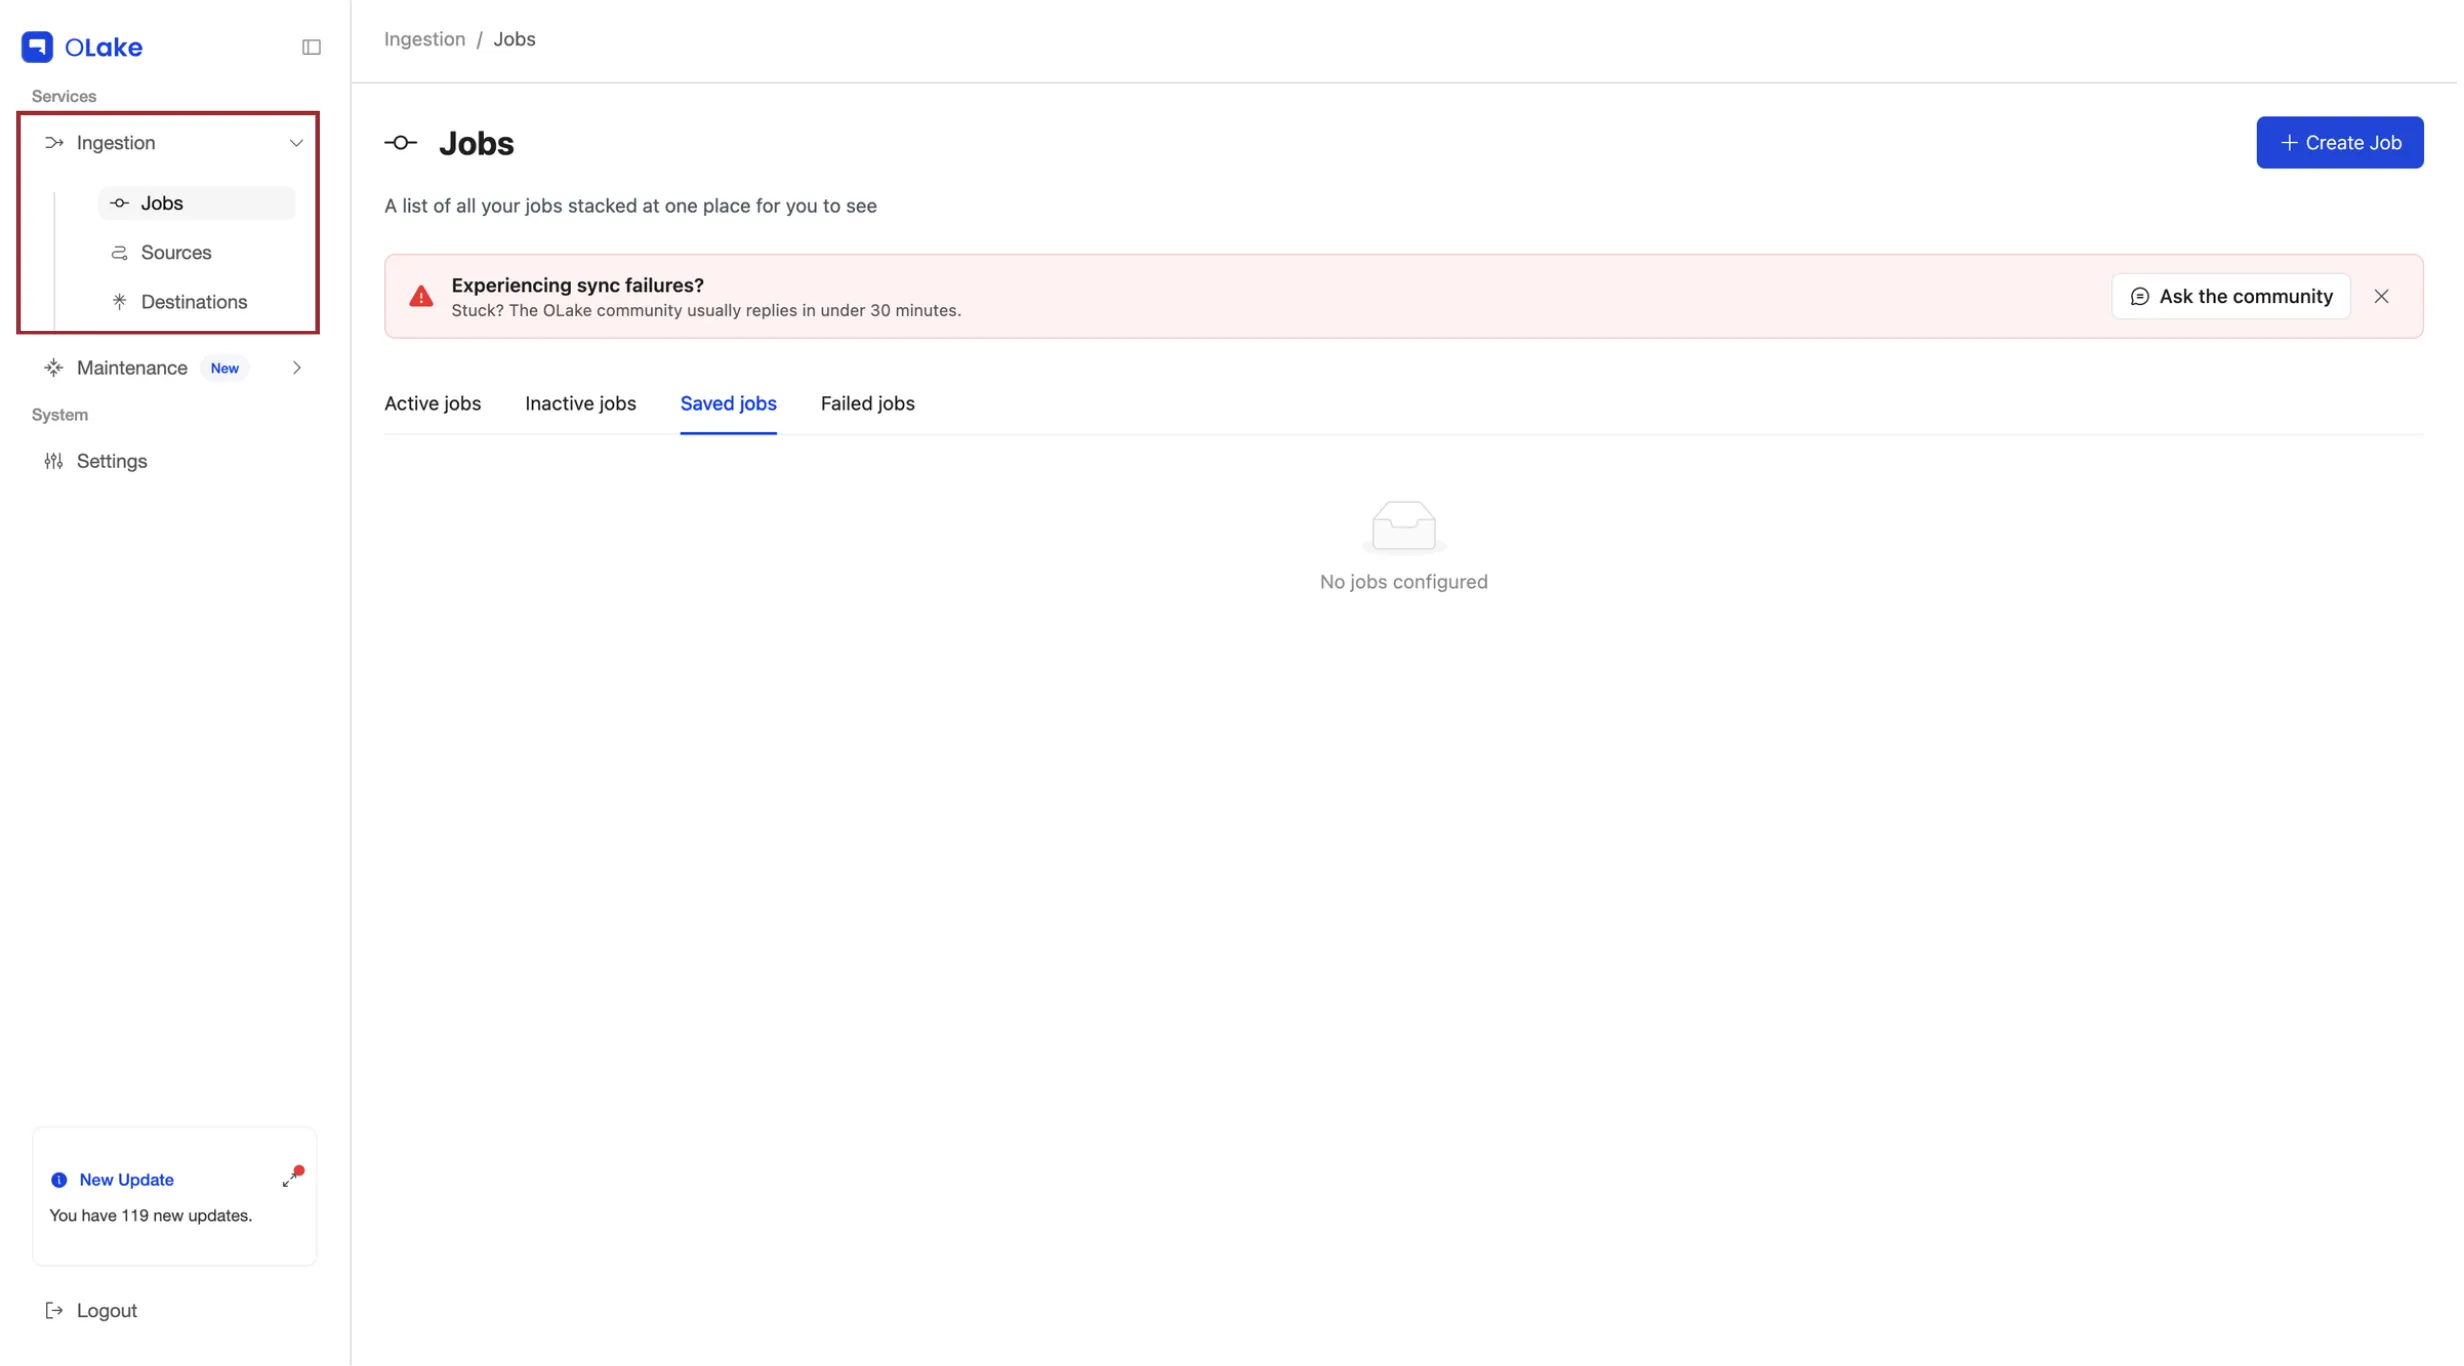
In the left menu, go to Ingestion > Jobs.
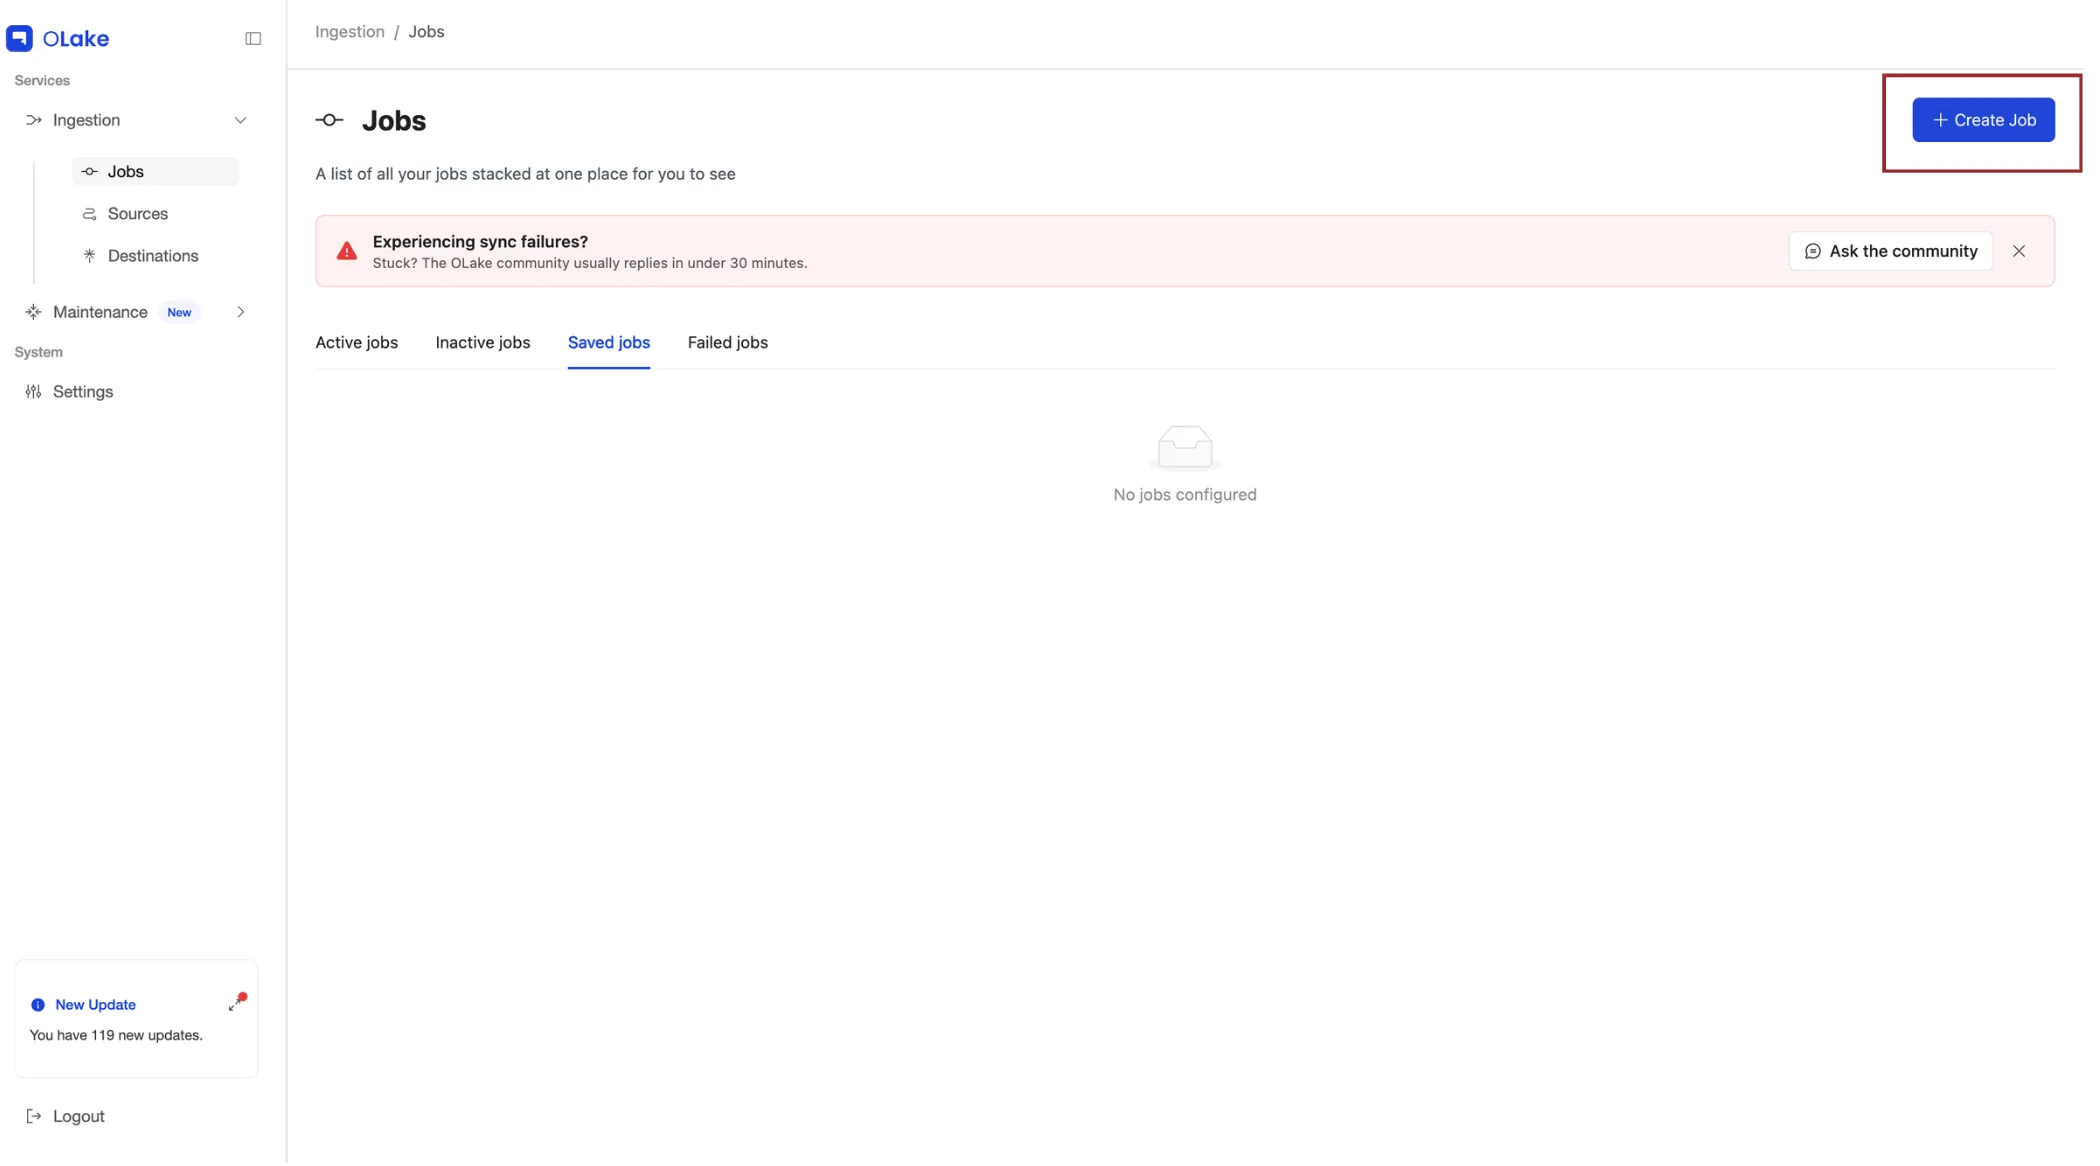
Click + Create Job at the top right.
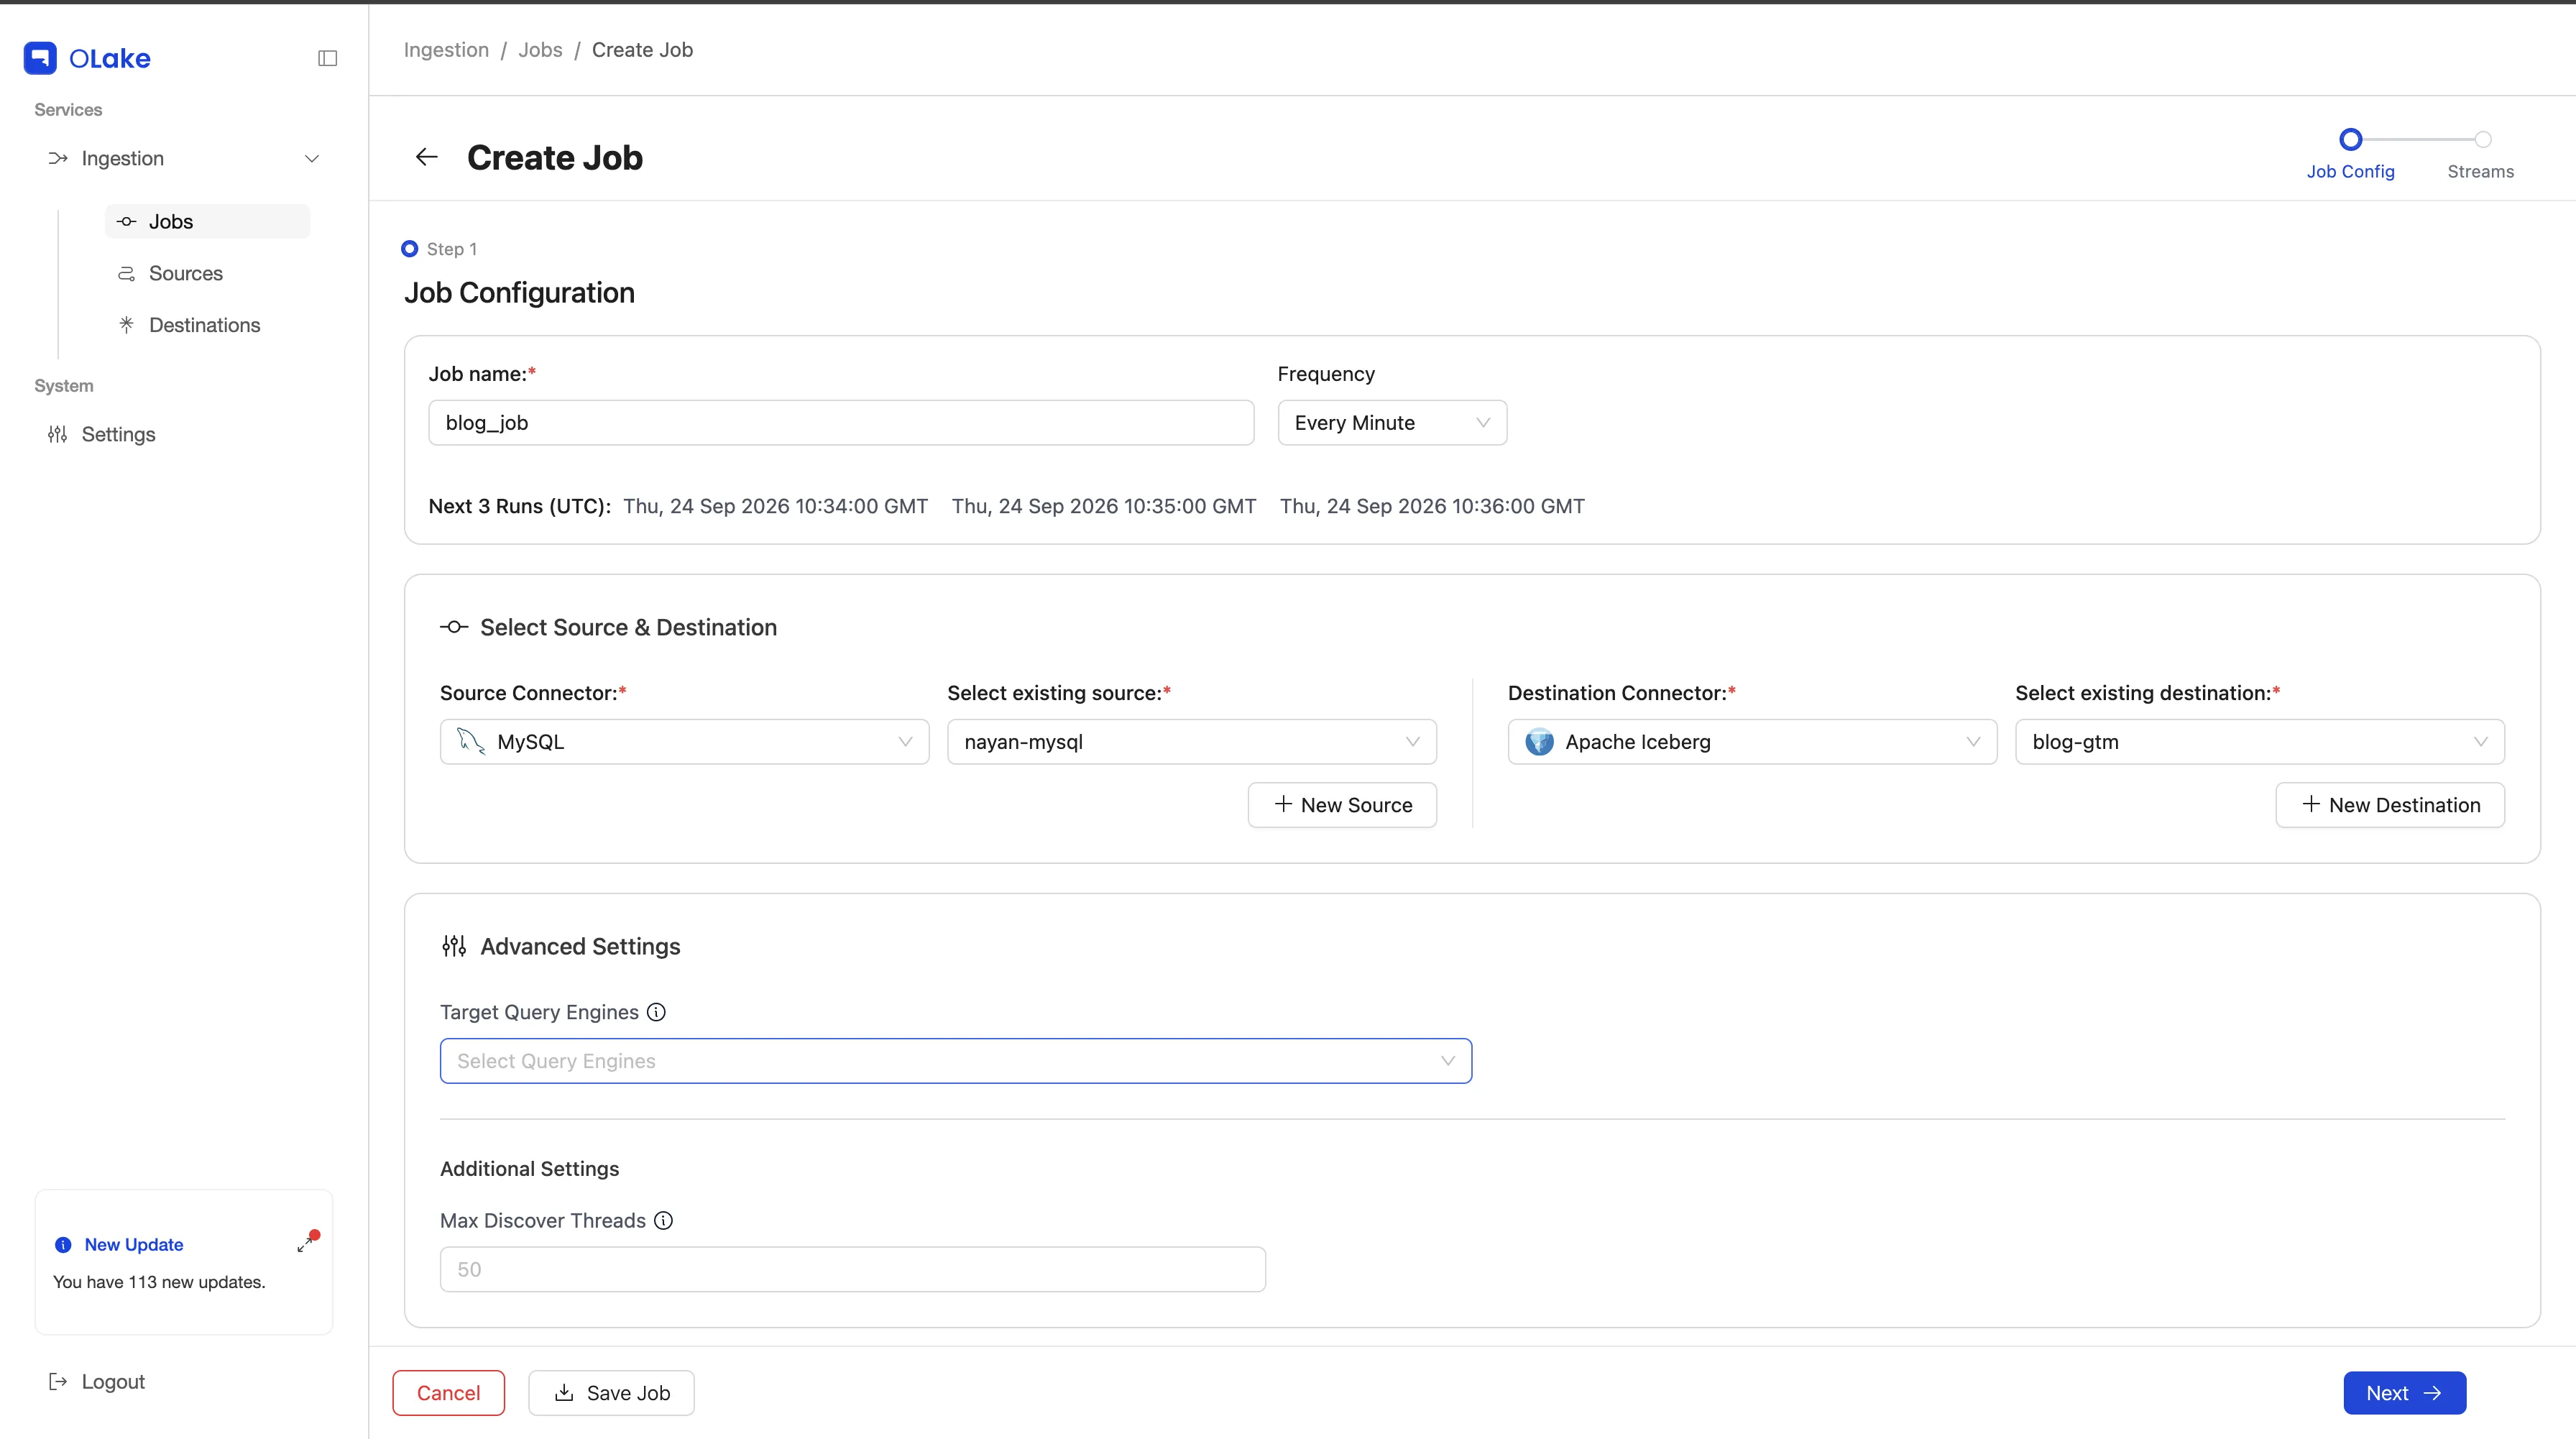
On the Job Configuration page, give your job a name (for example, blog_job) and choose how often it should run from the Frequency dropdown. Then pick MySQL as the source connector and select the source you created in Step 1, and do the same for the Iceberg destination.
Step 2a: Select Query Engine
Under Advanced Settings, open the Target Query Engines dropdown.
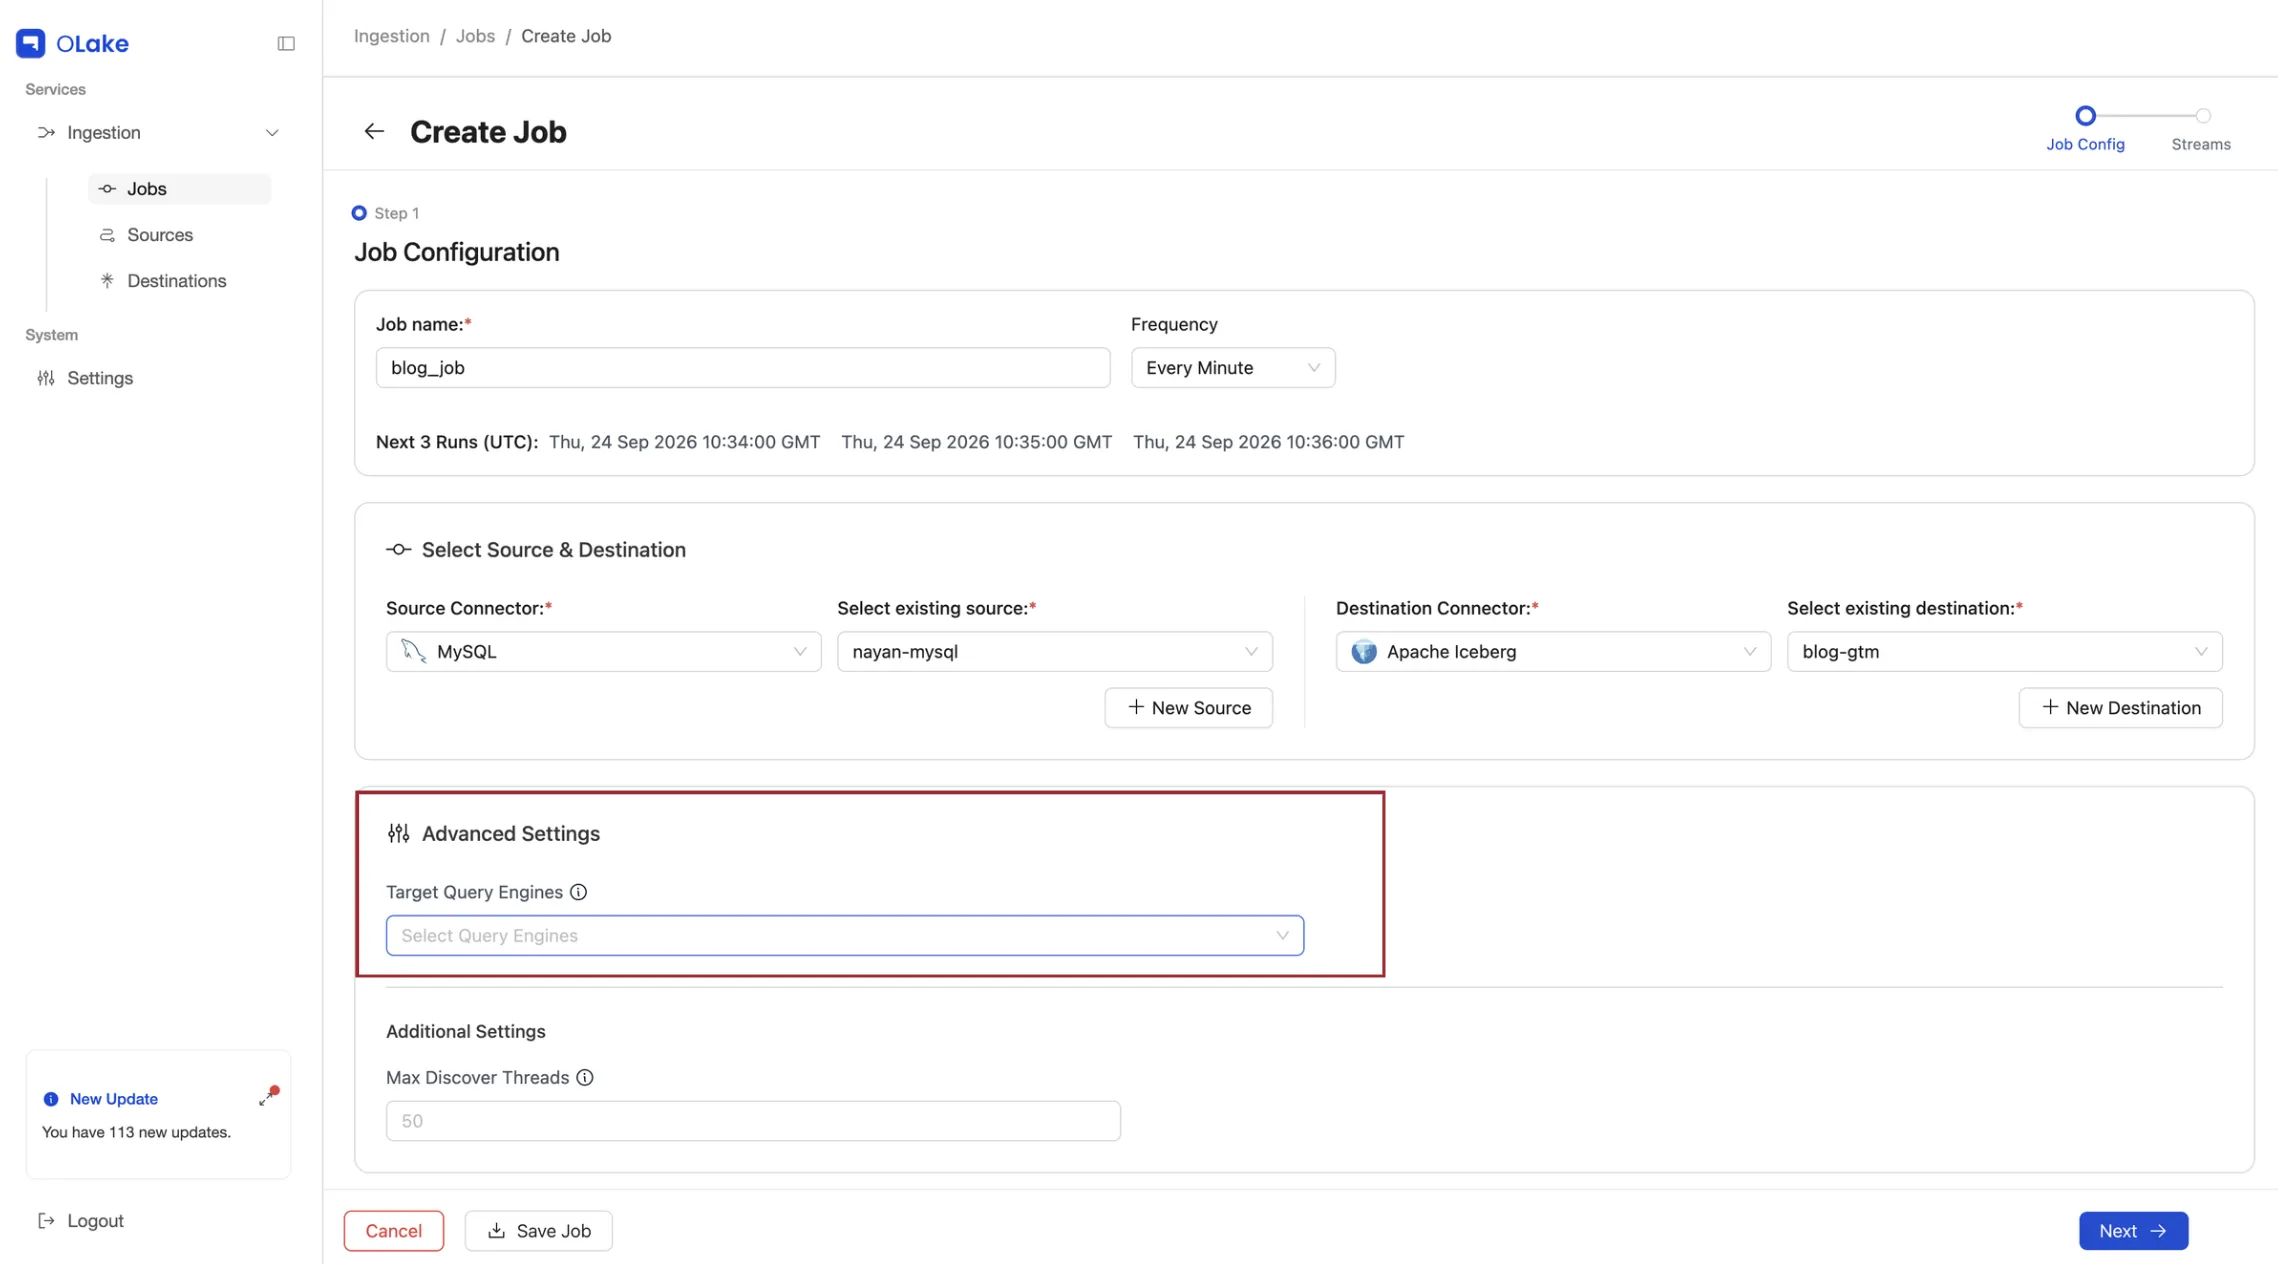
Select Presto. You can pick more than one engine, but this guide uses Presto only.
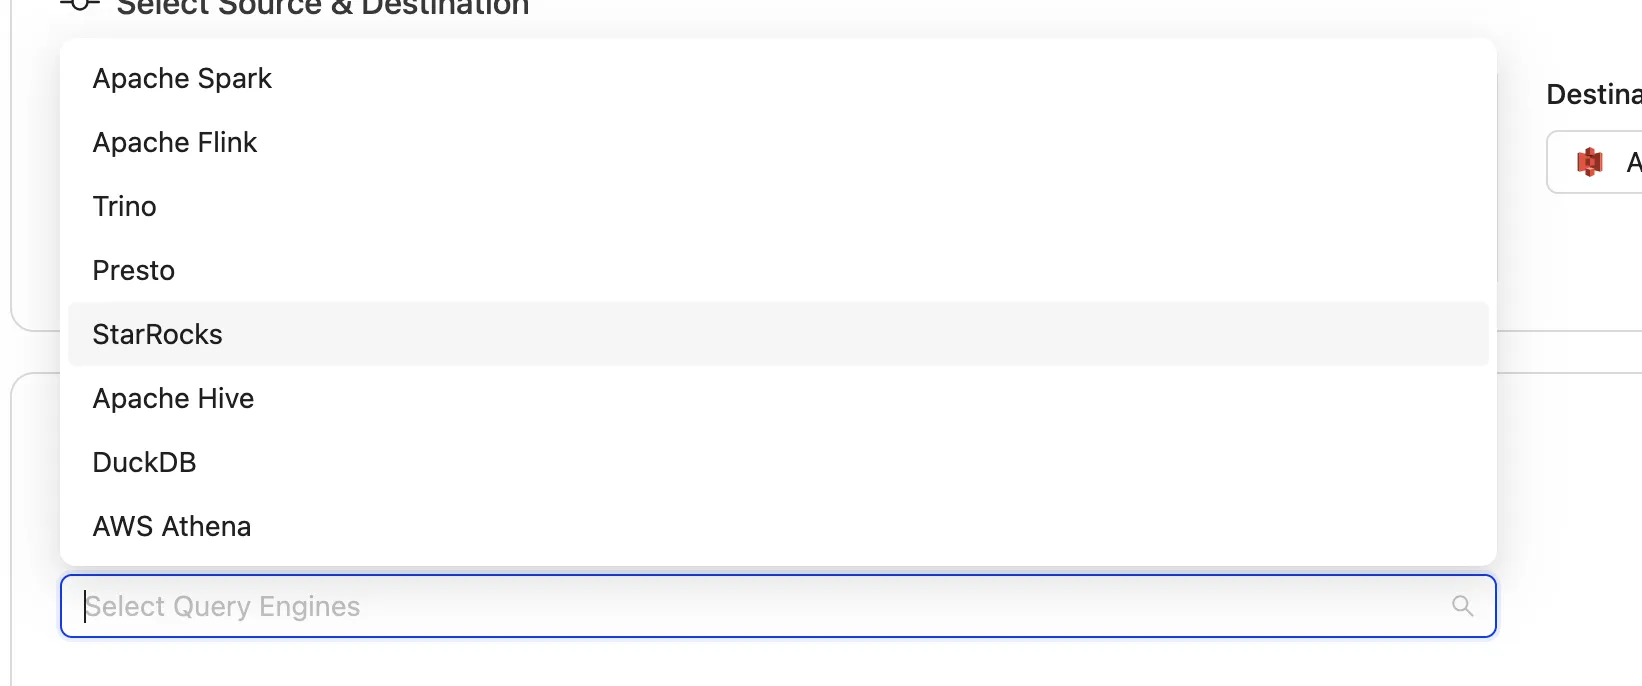
Click Next and you'll be redirected to the Stream configuration page.
Step 3: Configure Streams
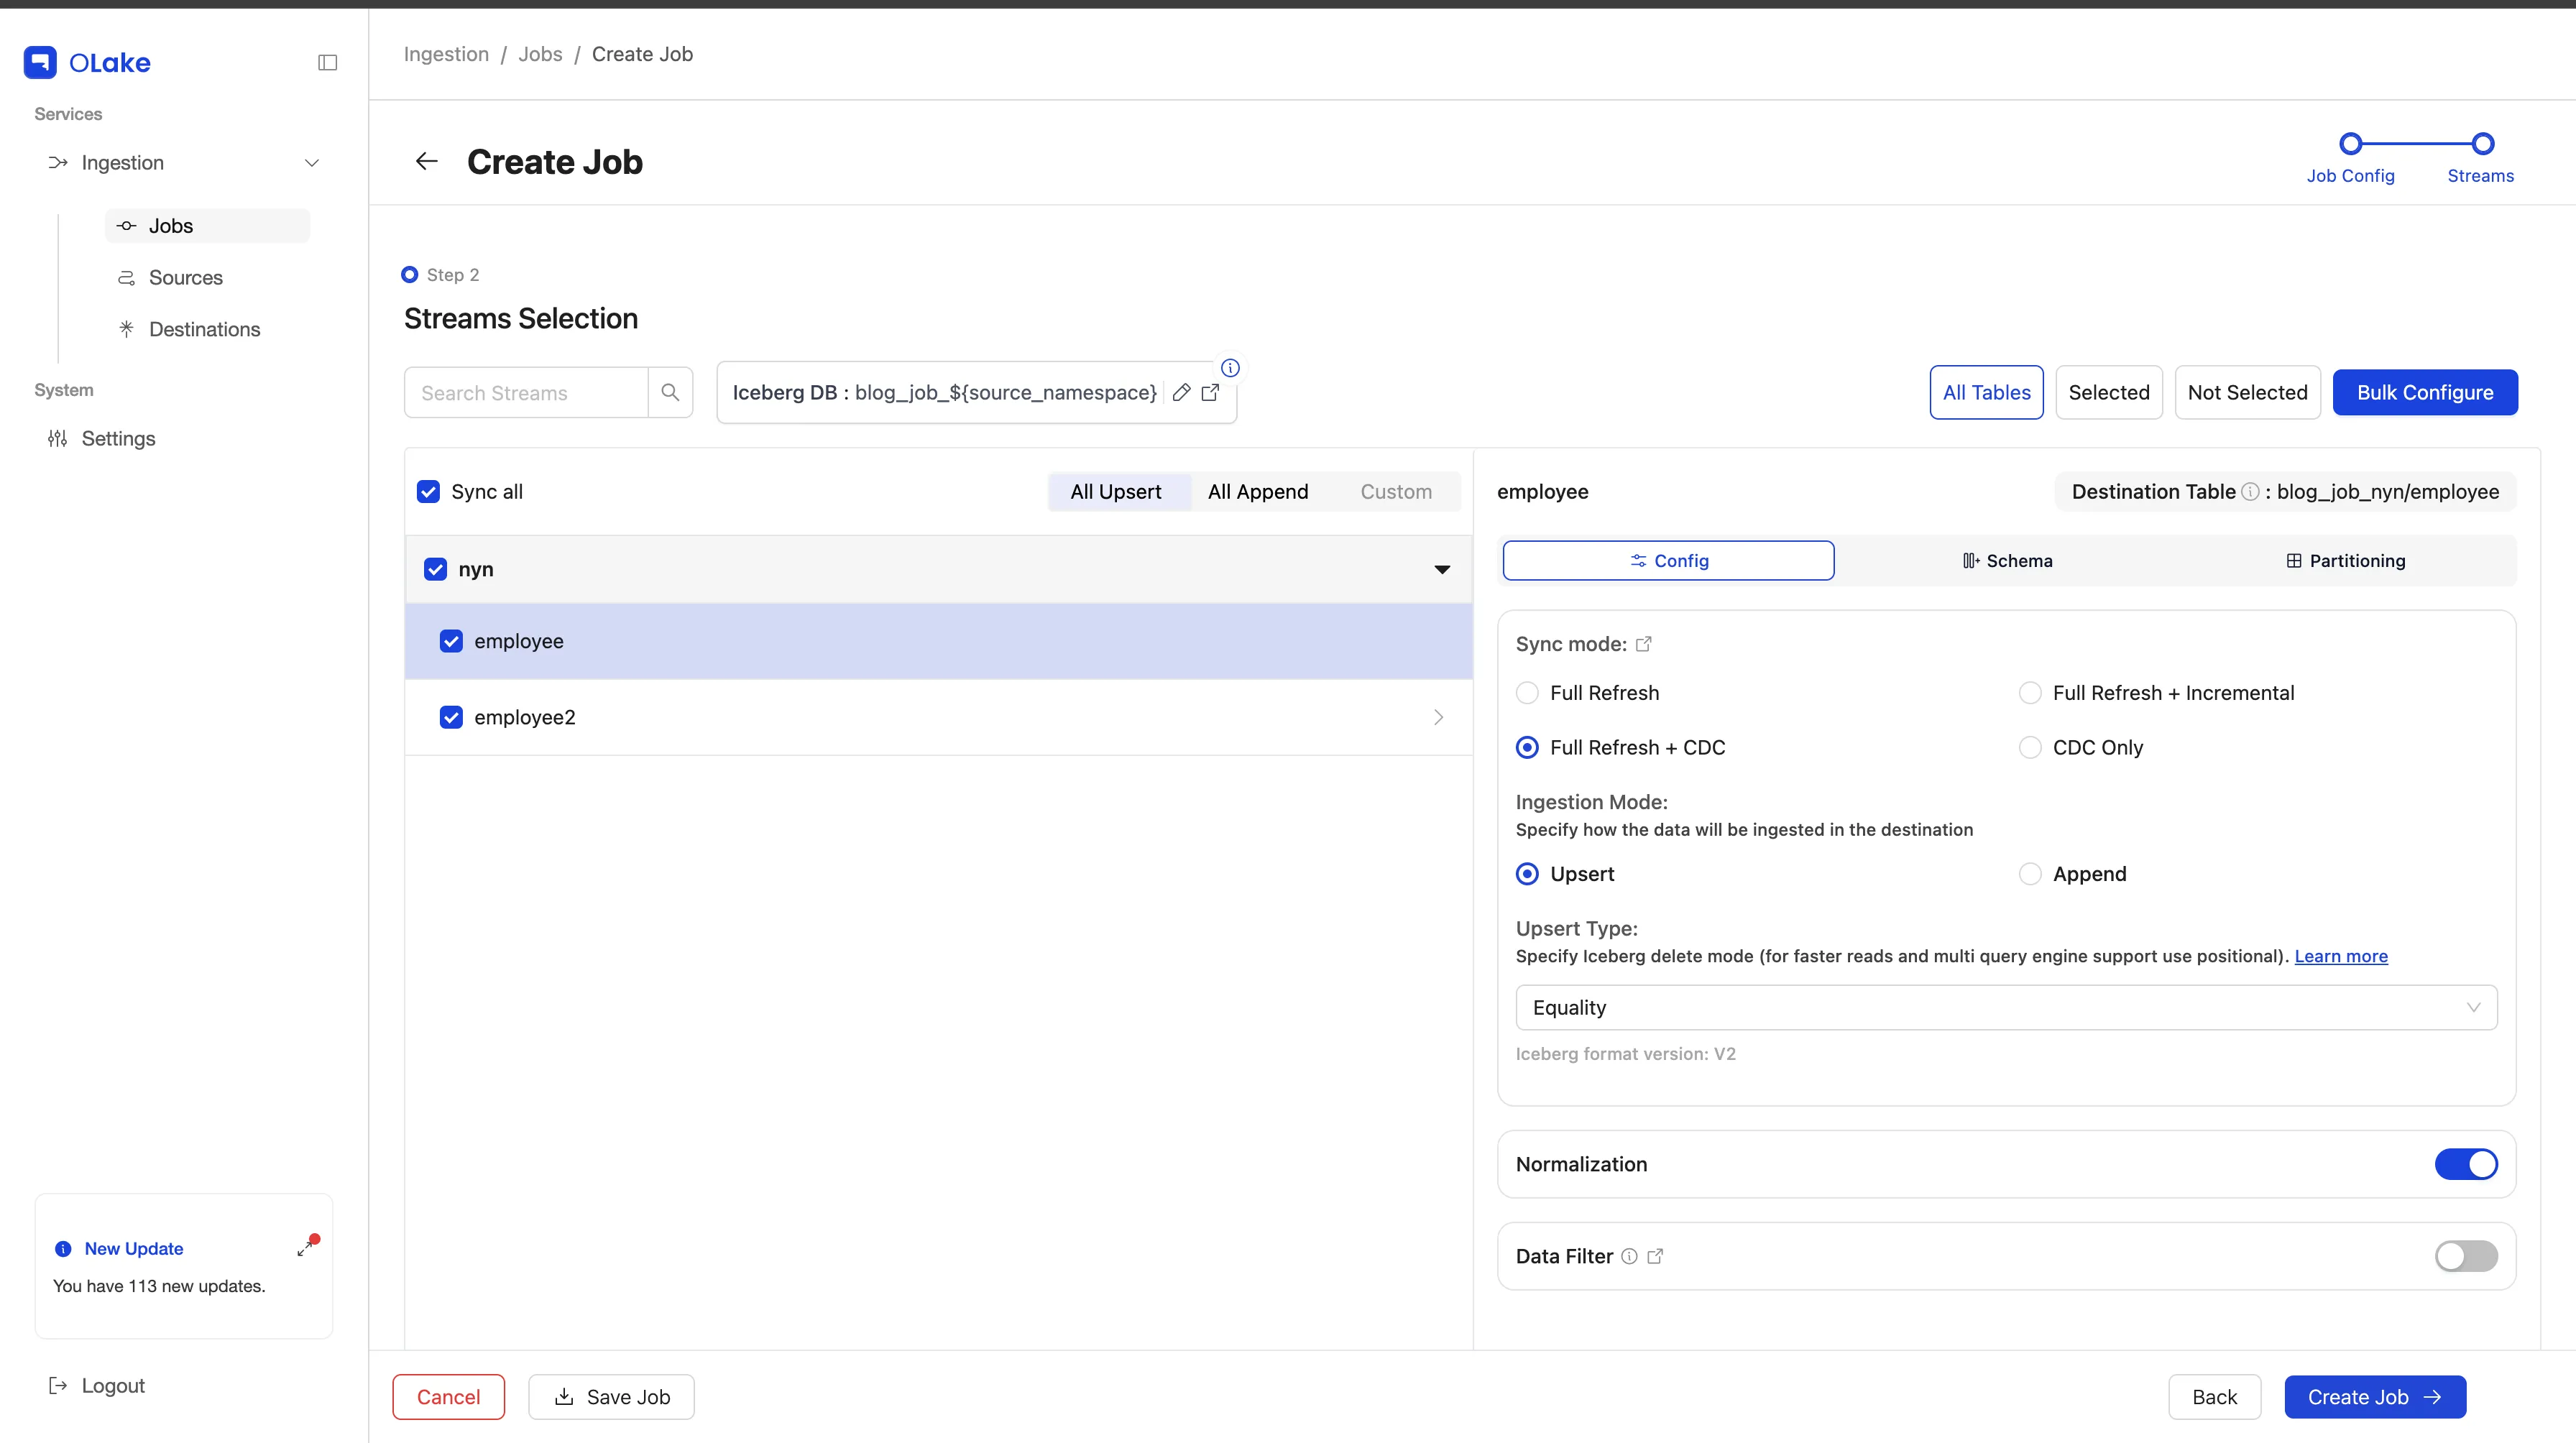
The Streams page lists every table in your MySQL database. Check the box next to each table you want to copy, or use Sync all to select everything. The Iceberg DB field at the top shows the database name your tables will land in, and you can click the edit icon to change it.
Click a table name to open its settings on the right. On the Config tab, you can:
- Pick a sync mode. Full Refresh + CDC copies all current rows first and then keeps copying new changes
- Choose an Ingestion Mode. Upsert updates existing rows when they change, while Append adds every change as a new row
- Turn on Normalization to store nested data as regular columns
The Schema tab shows the table's columns, and the Partitioning tab lets you group data by a column so queries run faster.
Step 3a: Specify Iceberg Delete Mode
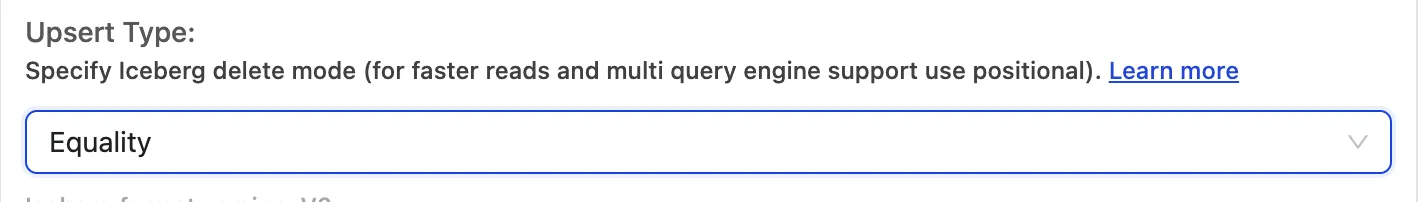
When the ingestion mode is Upsert, you can choose which type of delete file OLake Go writes to Iceberg.
Open the Upsert Type dropdown and select the delete type you want: Equality, Positional, or Deletion.
Equality is by default selected for Presto. You can change the delete mode to the one you prefer via the drop-down.
When you're done, click Create Job at the bottom right. A confirmation shows that your job was created, and clicking Jobs takes you back to the main Jobs page.
Step 4: Run the Sync
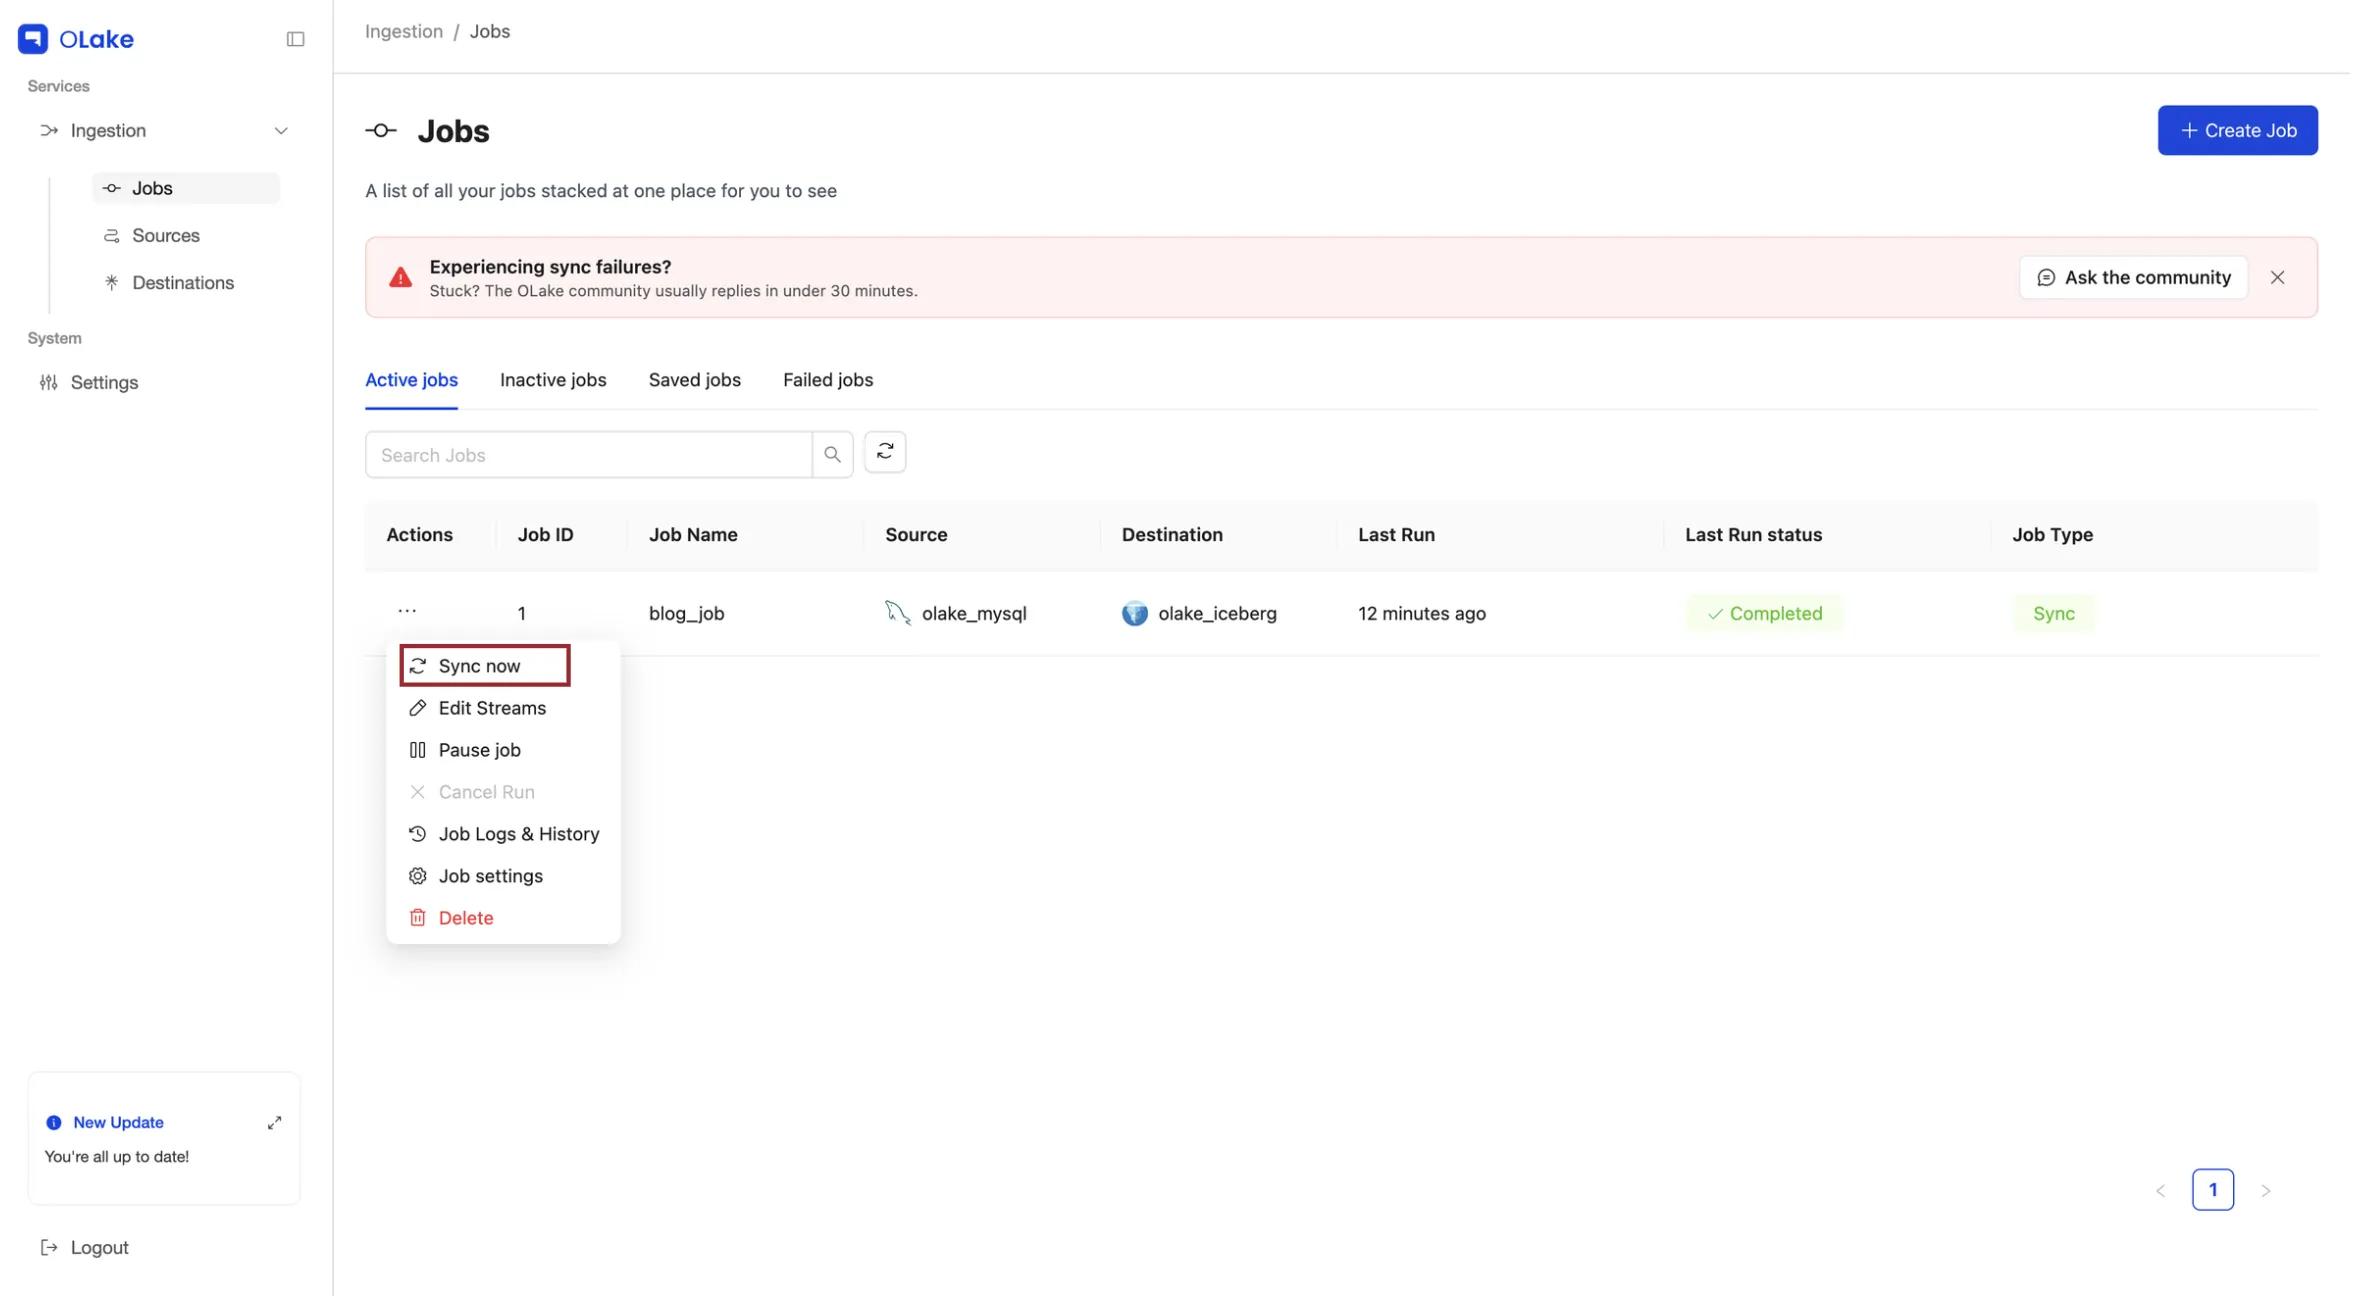
Your new job appears in the Active jobs tab. The Last Run status column shows whether each run is Running, Completed, or Failed.
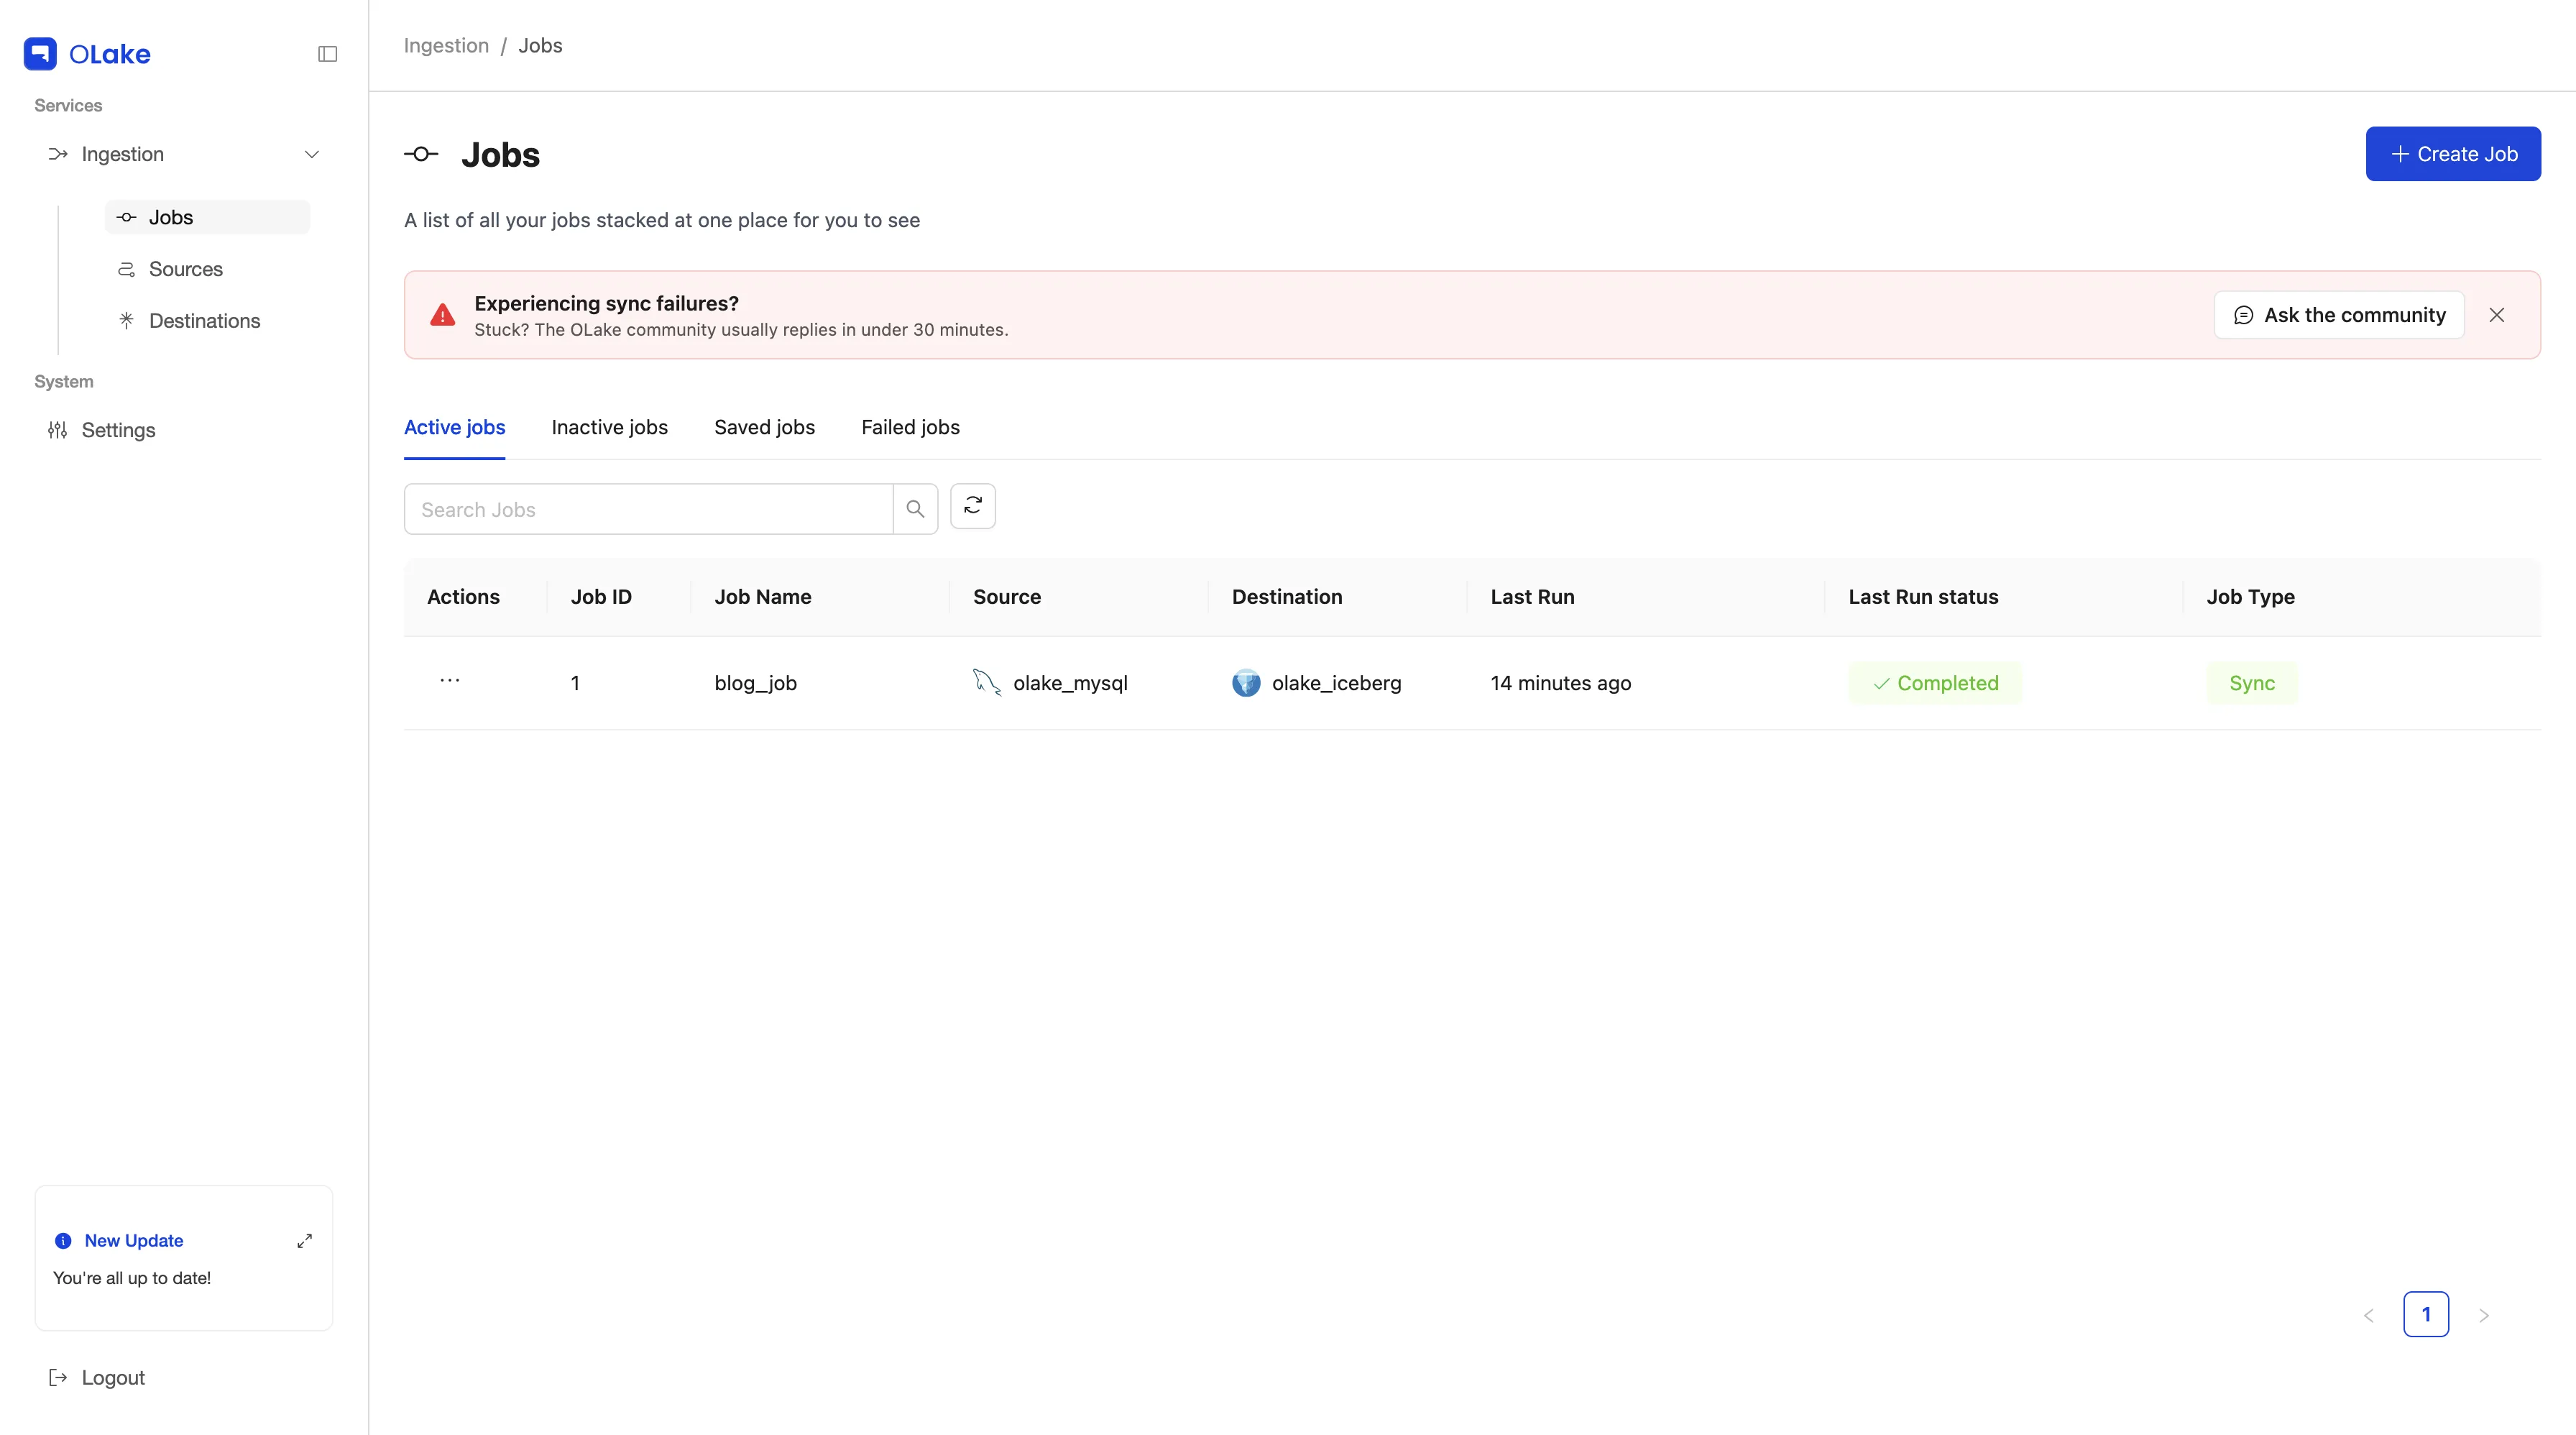
The job will run at its next scheduled time. To start it now, click the three dots in the Actions column next to your job and select Sync now.
To see how each run went, under Actions, select Job Logs & History. This page lists every run with its start time, runtime, and status.
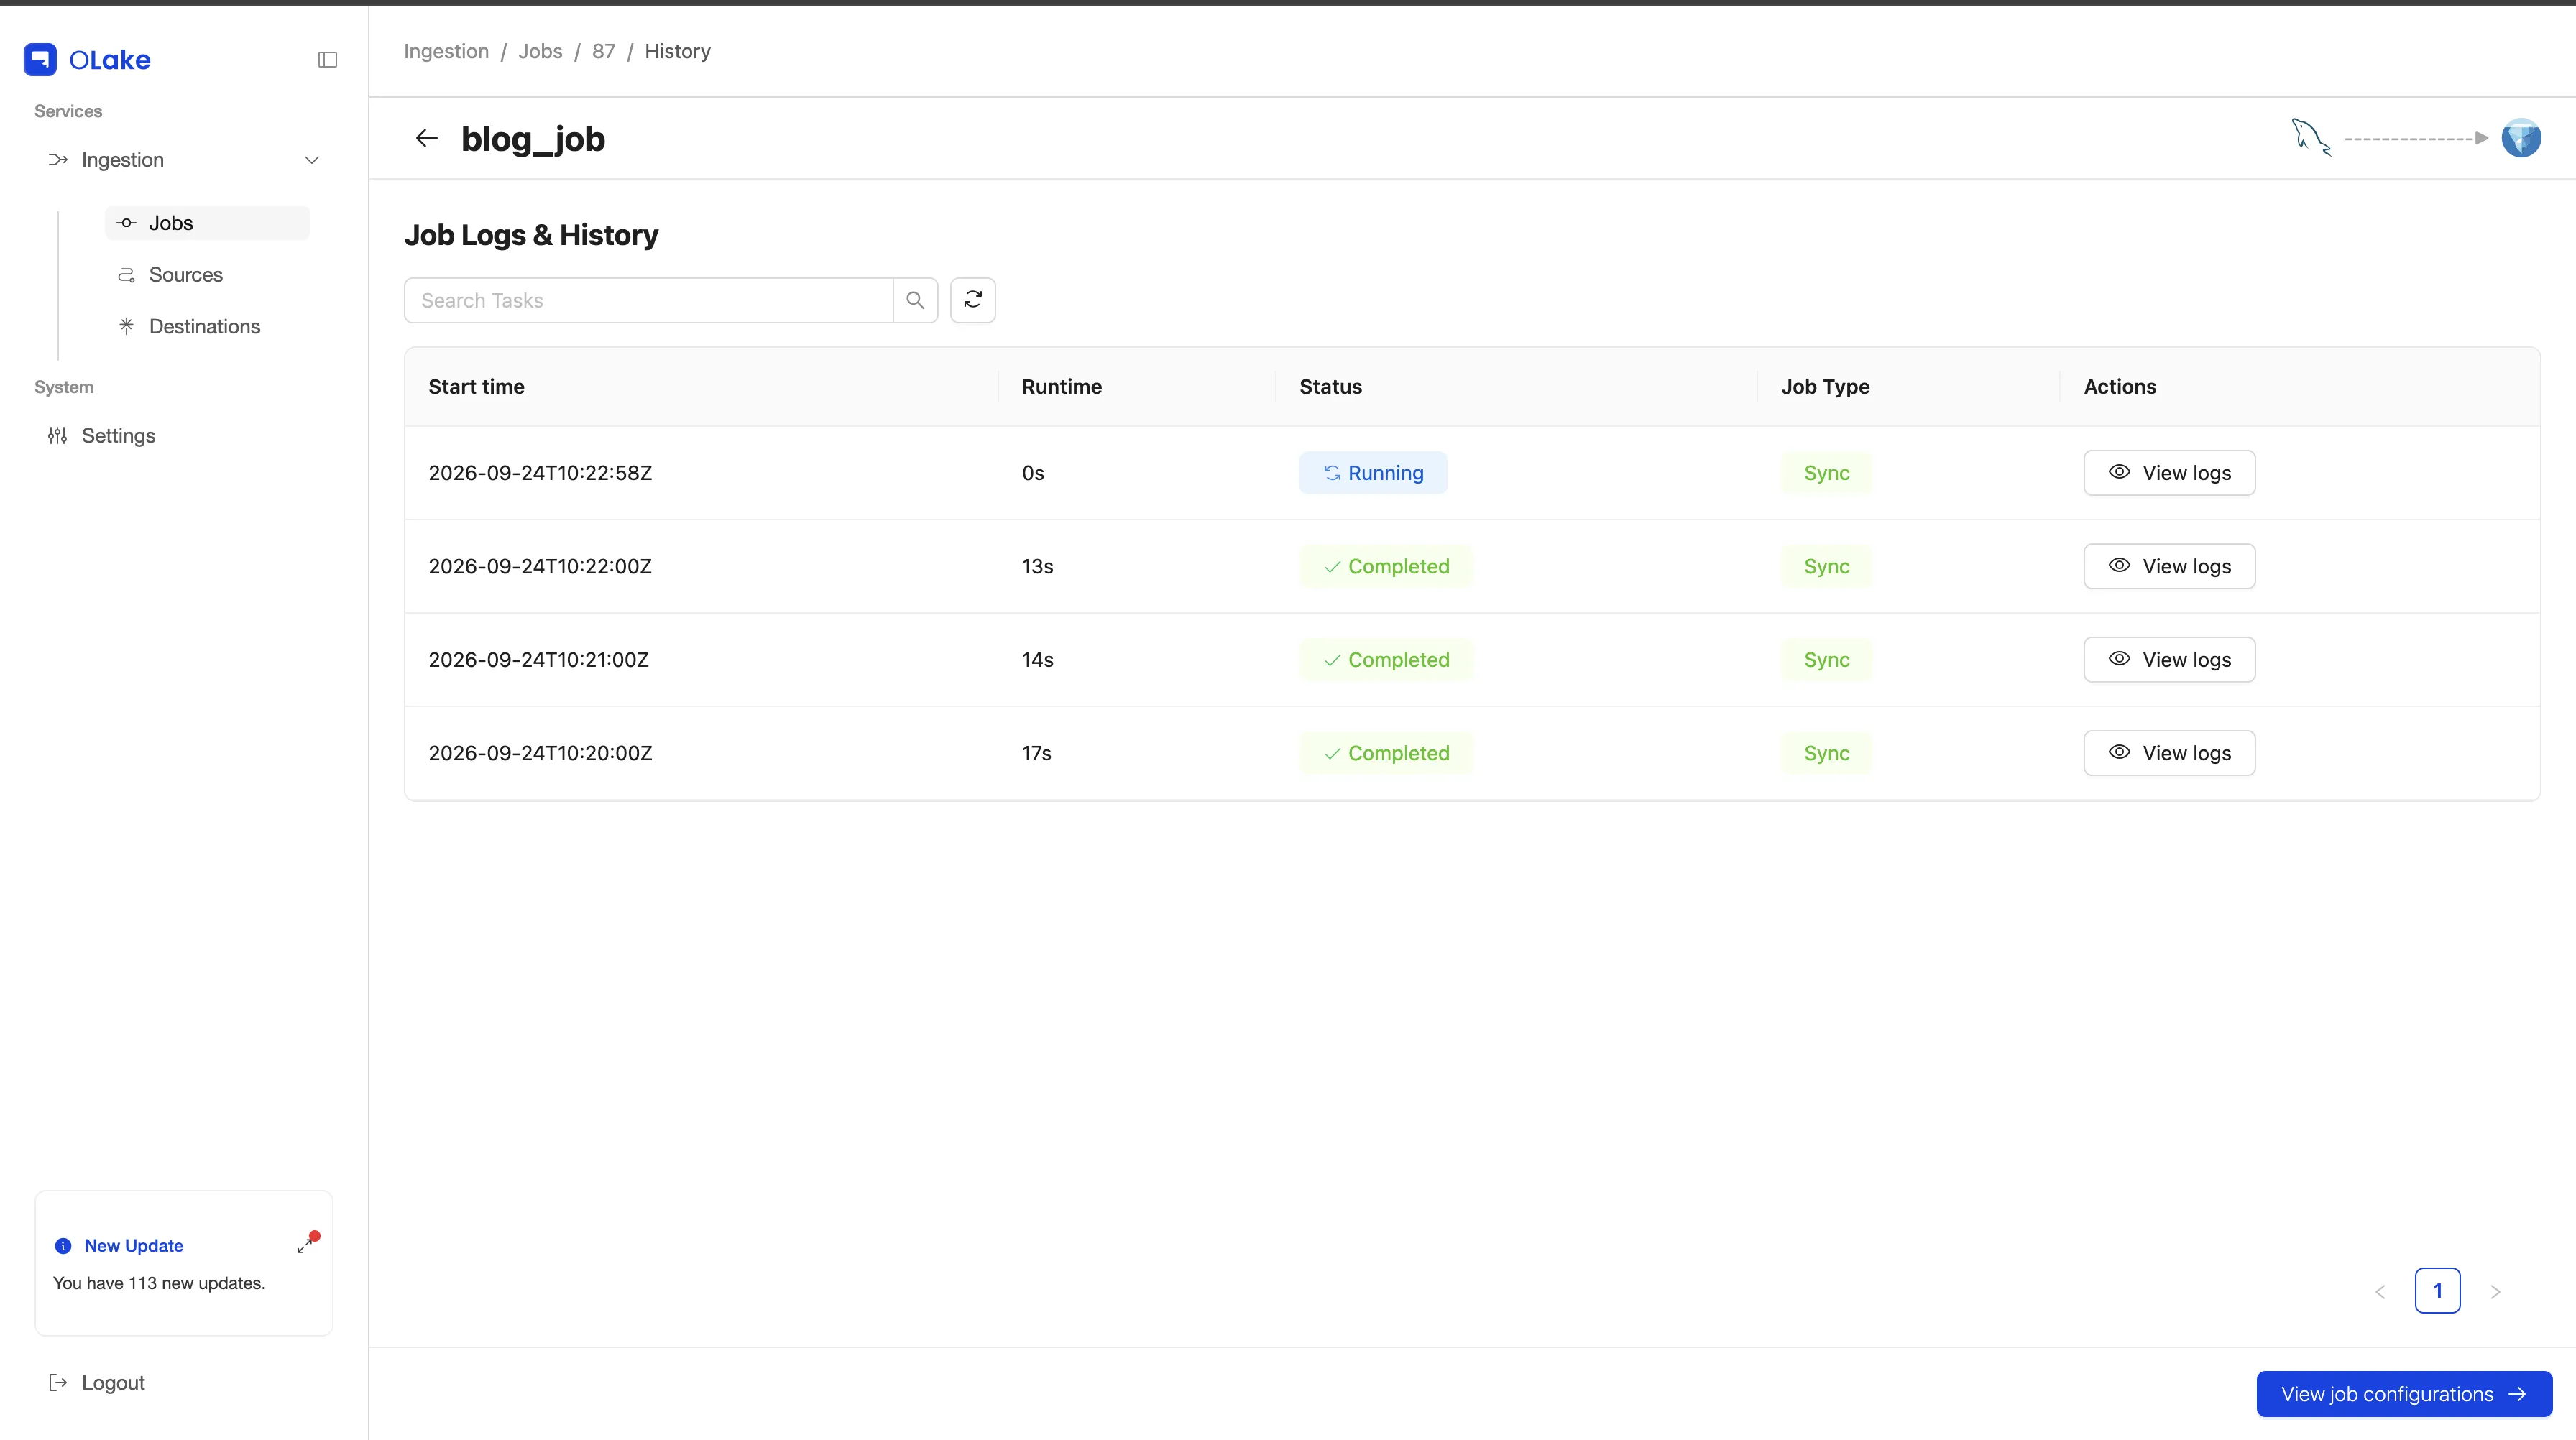
Click View logs next to any run to see its full log, including when MySQL CDC started, the total records read, and when the sync finished.
Once the sync finishes, the new Iceberg tables will be registered in your catalog and the data files will show up in your S3 bucket.
Step 5: Query with Presto
Connect Presto to your AWS Glue catalog by creating a catalog file at etc/catalog/<catalog-name>.properties:
connector.name=iceberg
iceberg.catalog.type=hive
hive.metastore=glue
hive.metastore.glue.region=<region>
hive.metastore.glue.aws-access-key=<access-key>
hive.metastore.glue.aws-secret-key=<secret-key>
hive.s3.aws-access-key=<access-key>
hive.s3.aws-secret-key=<secret-key>
Restart Presto to load the catalog, then open the Presto CLI:
presto --catalog <catalog-name> --schema <namespace>
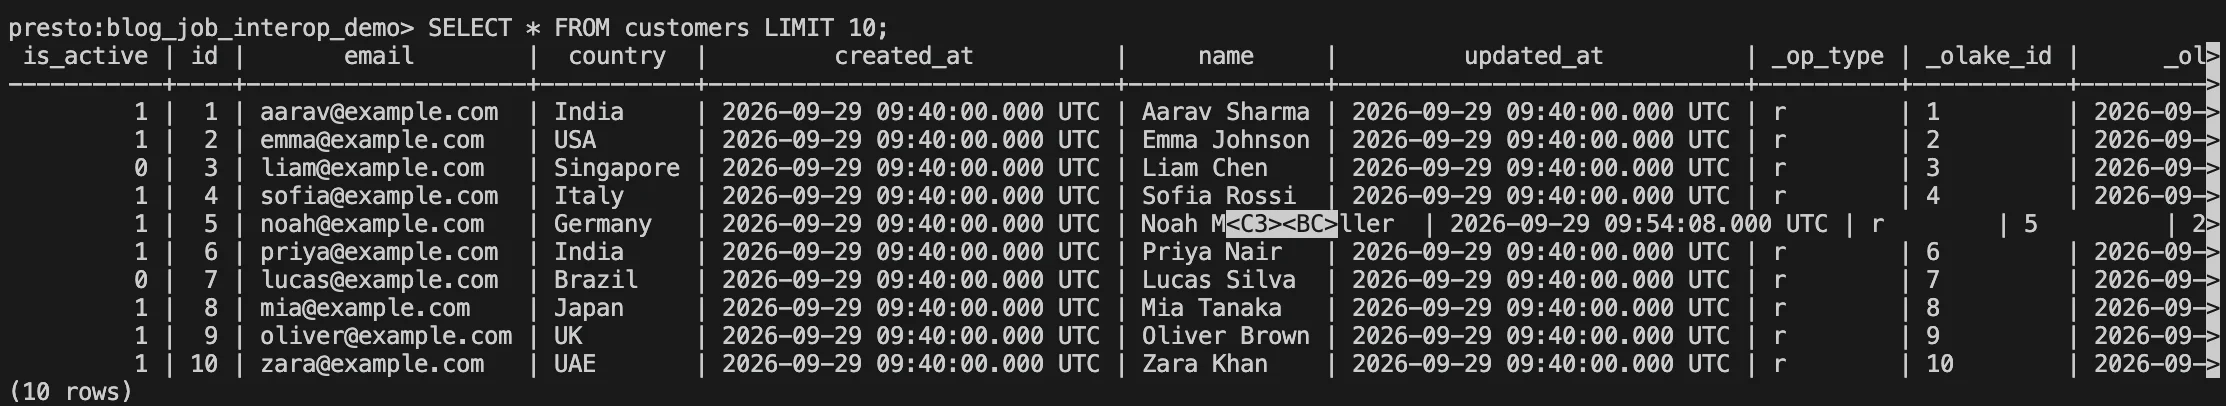
See the tables OLake Go created:
SELECT * FROM <table> LIMIT 10;
Conclusion
You now have a pipeline that keeps MySQL changes flowing into Apache Iceberg on your chosen schedule, and a Presto catalog that can run SQL over those tables without placing any analytical load on your production database. Joins, aggregations, and long-range scans that would strain MySQL now run against a separate copy in object storage.
Since the tables are standard Iceberg, Presto isn't the only engine that can read them. Spark, Trino, Flink, and DuckDB can query the same data through the same catalog, so you can add engines later without re-ingesting anything. Check the compatibility guide for supported catalog and delete-format combinations, and join the OLake Slack community if you get stuck.