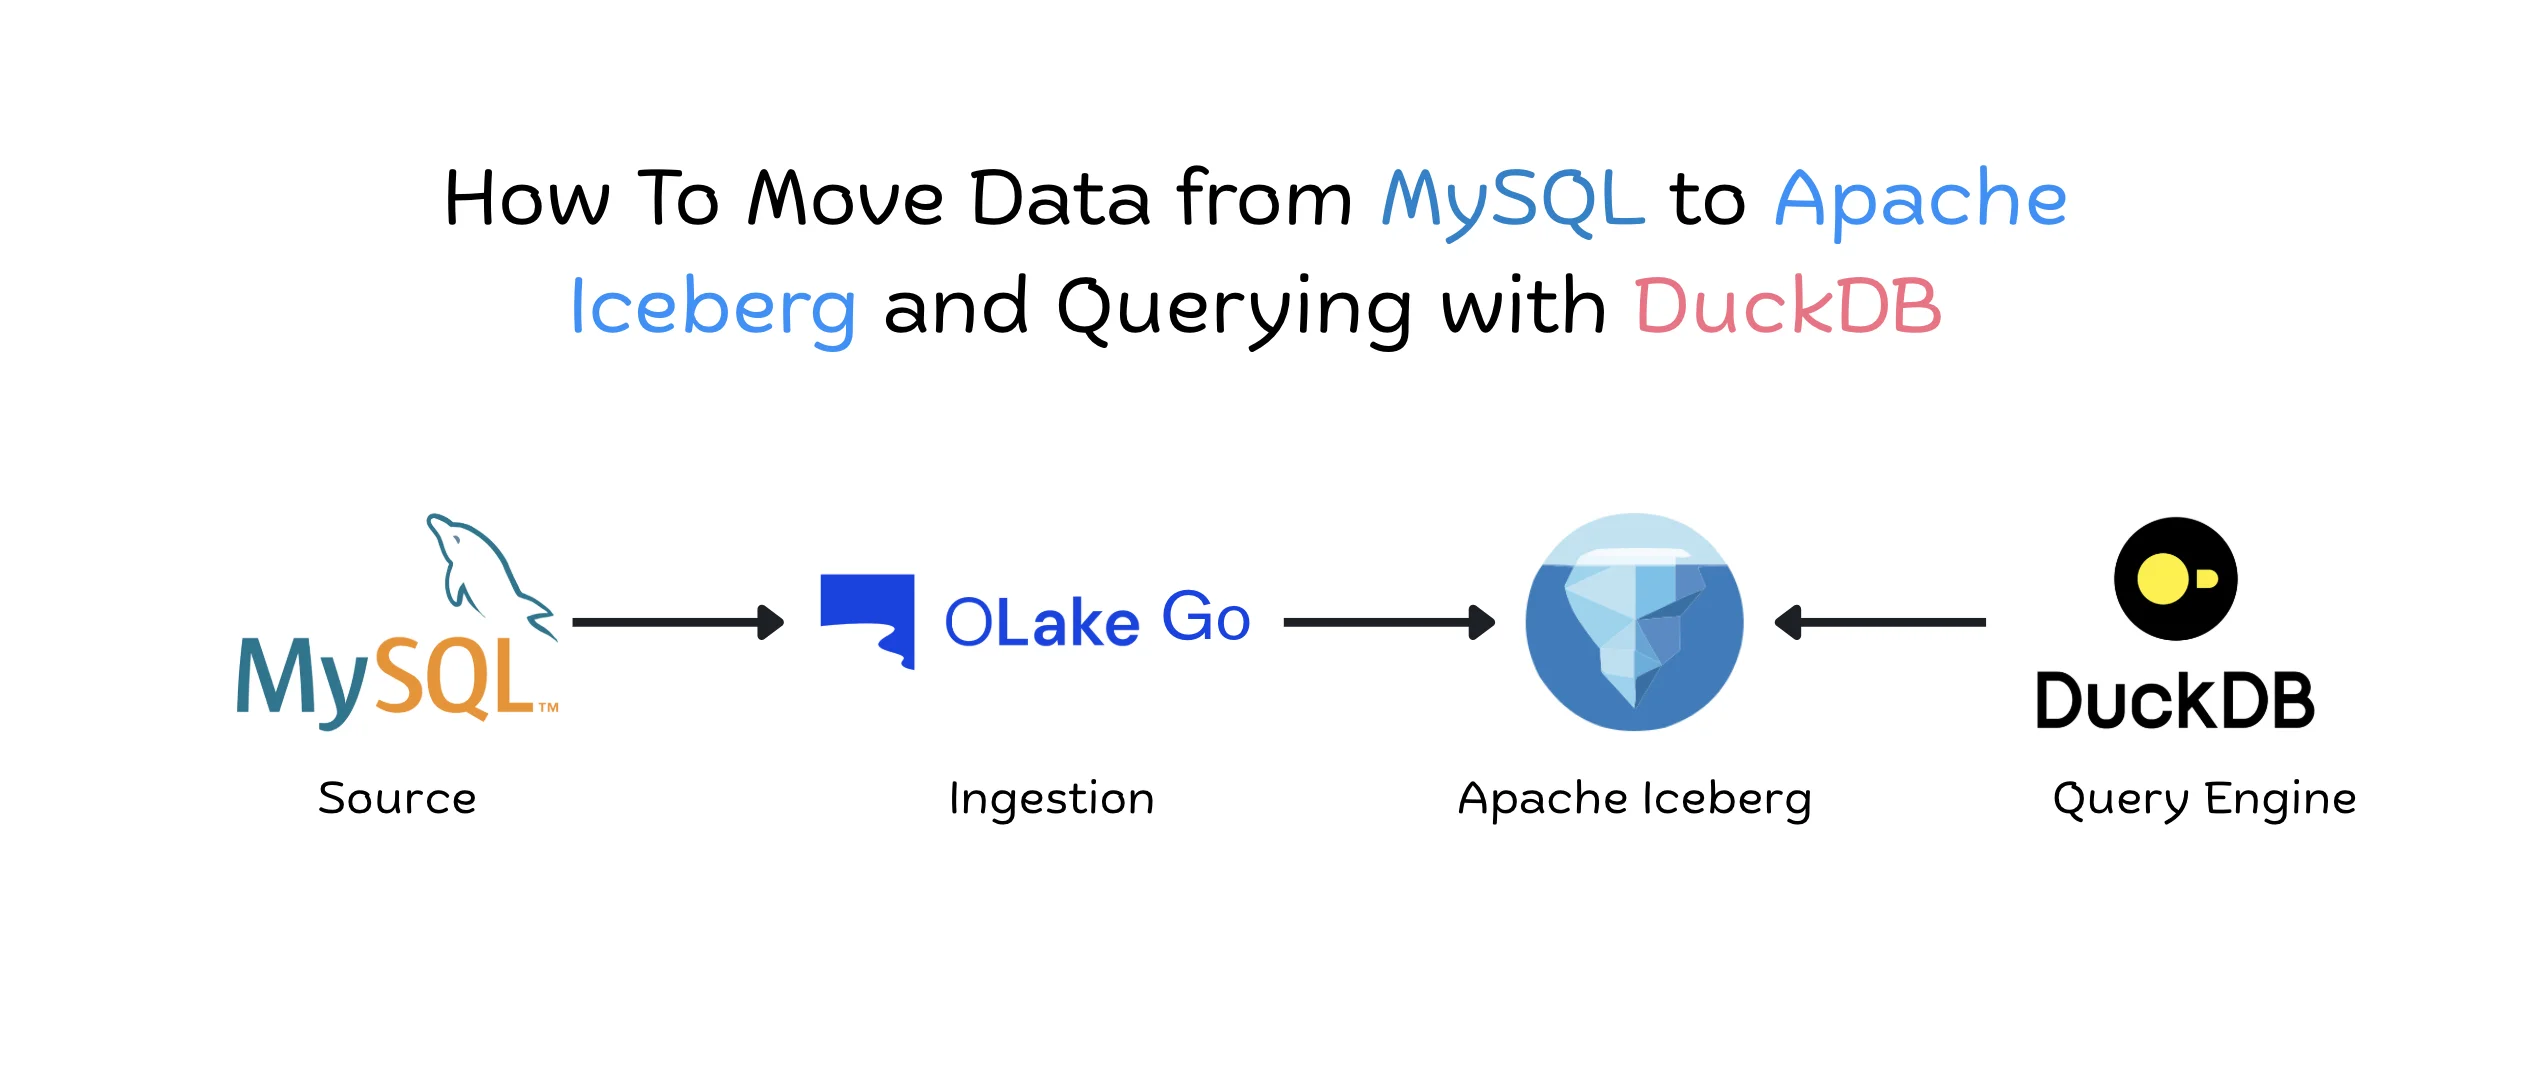
How To Move Data from MySQL to Apache Iceberg and Querying with DuckDB
7 min read
Introduction
Sooner or later, someone on the team wants to slice MySQL data in ways the application never planned for: a cohort breakdown, a year-over-year comparison, a quick check across a few million orders. Running that kind of query against the production MySQL instance competes with the transactions your users are waiting on, and spinning up a full warehouse or Spark cluster just to answer it is often overkill. Landing MySQL data in Apache Iceberg gives you an analytics-ready copy on object storage, and DuckDB can read that copy straight from your laptop or a single VM, with no cluster to manage.
OLake Go handles the replication side. It reads MySQL through CDC and writes Iceberg tables in a format that the query engines you pick can read. This guide walks through each step in OLake Go: connecting MySQL, writing to Iceberg in the catalog of your choice, selecting DuckDB as the target query engine, choosing which tables to ingest, running the sync, and finally querying the Iceberg tables in DuckDB.
Step 1: Set Up the Source and Destination
The OLake Go docs explain how to set up MySQL and Iceberg, so follow the links below for each one. Pick the catalog you want to use and follow the link below to help you set it up. To see which engines work with which catalogs, check Compatibility with Query Engines.
When both Sources and Destinations are created, you can move on to the next step.
| Source | Setup Guide |
|---|---|
| MySQL | Link |
| Destination | Catalog | Link |
|---|---|---|
| Apache Iceberg | HIVE | Link |
| REST | Link | |
| NESSIE | Link | |
| AWS GLUE | Link | |
| JDBC | Link | |
| Polaris | Link | |
| BigLake | Link | |
| Lakekeeper | Link | |
| Unity | Link | |
| S3 tables | Link | |
| Horizon | Link |
Step 2: Create a Job and Select the Query Engine
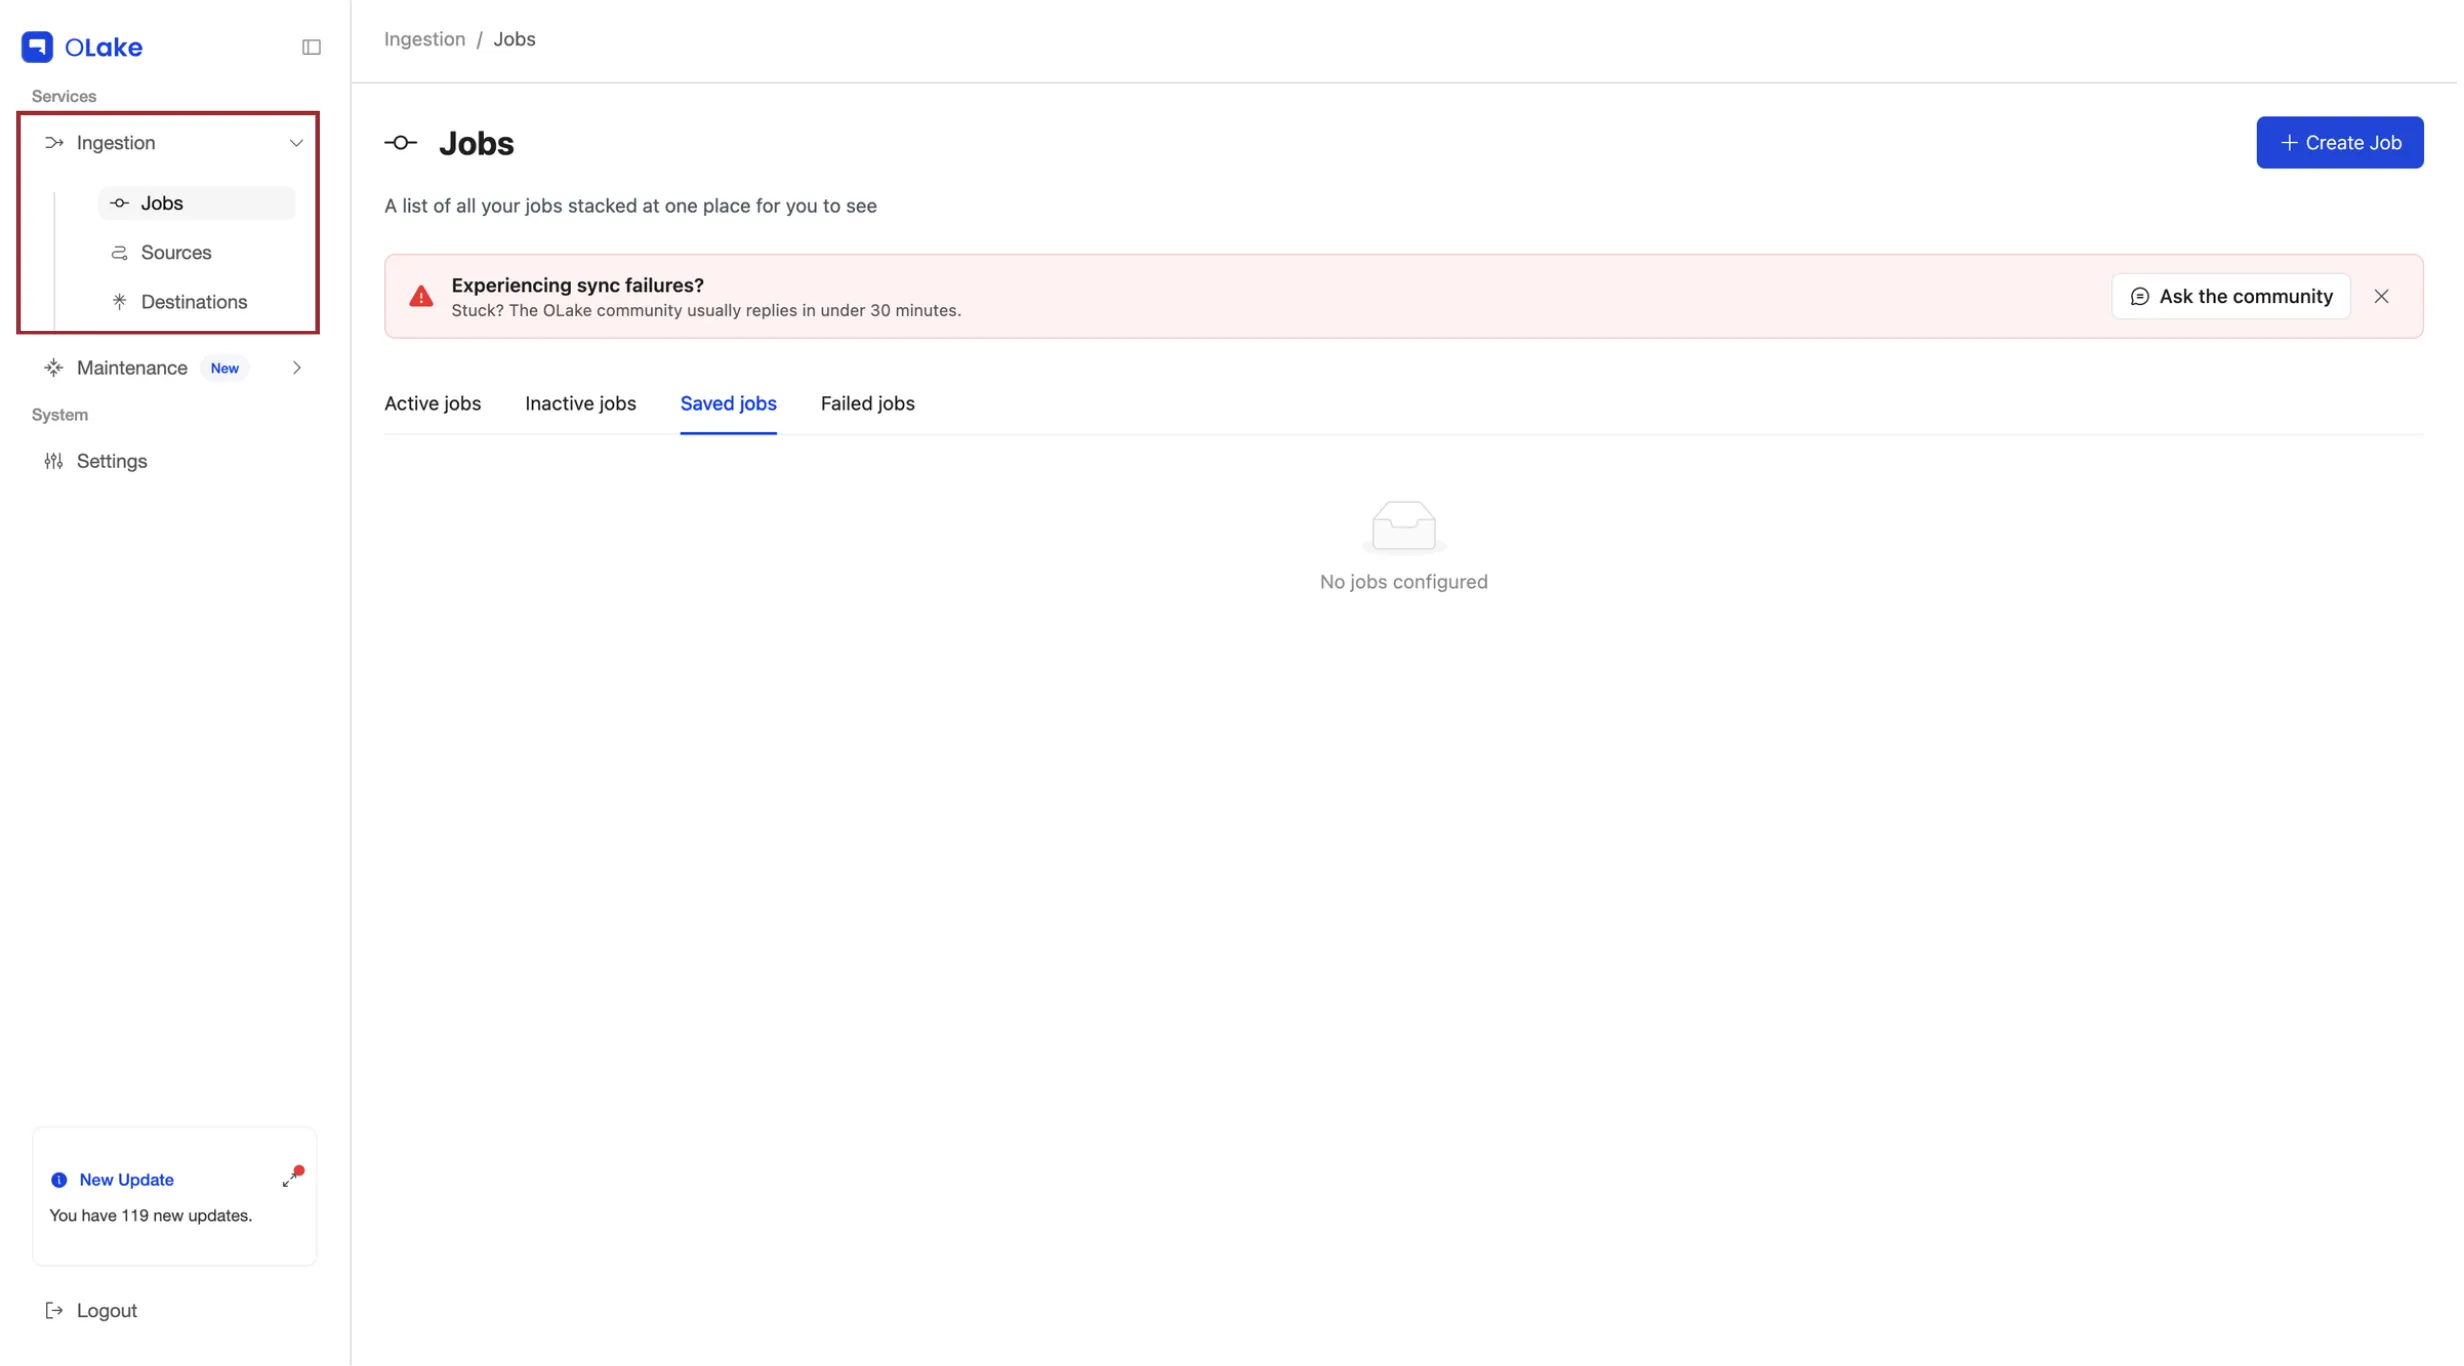
In the left menu, go to Ingestion > Jobs.
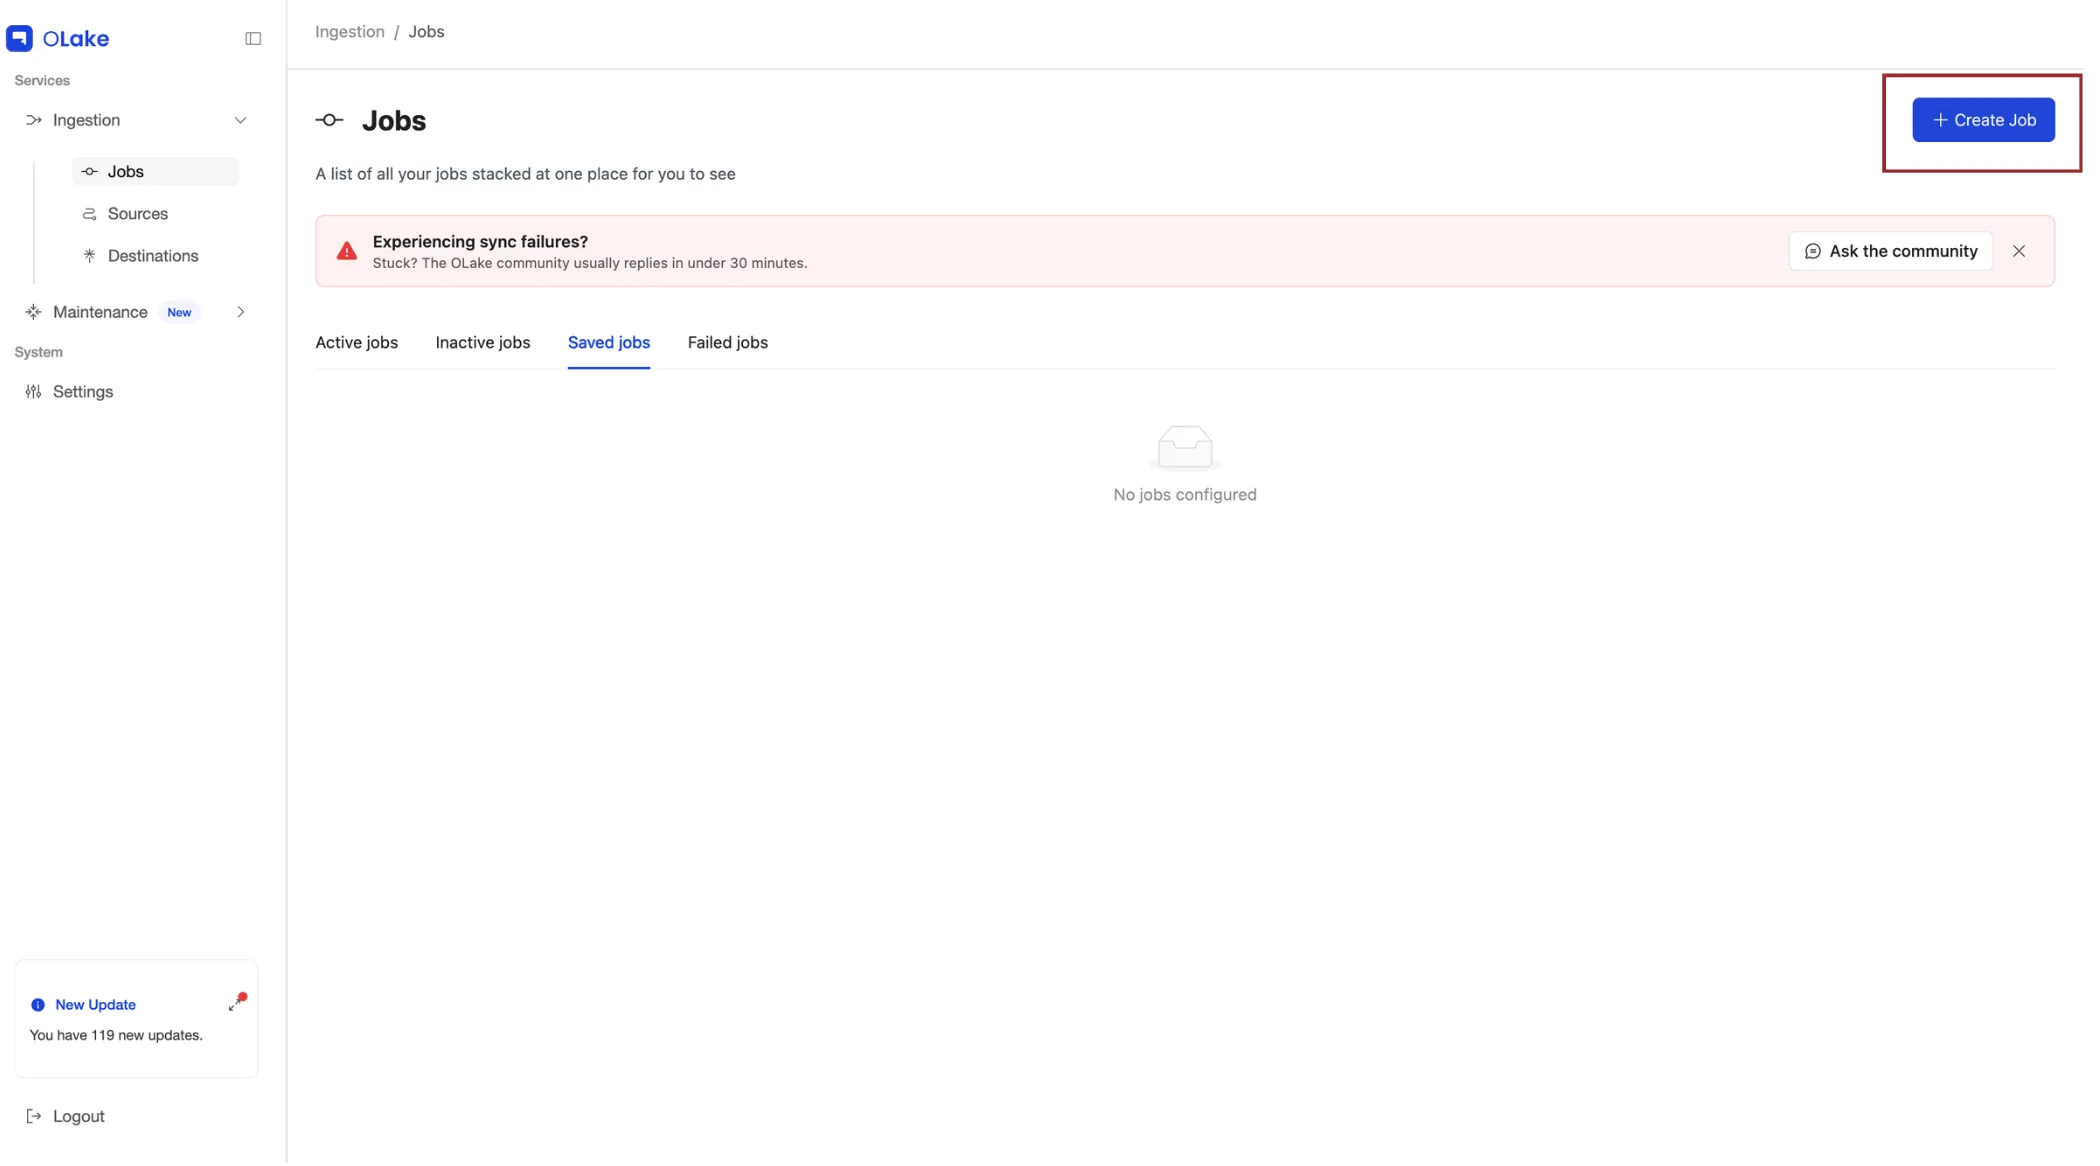
Click + Create Job at the top right.
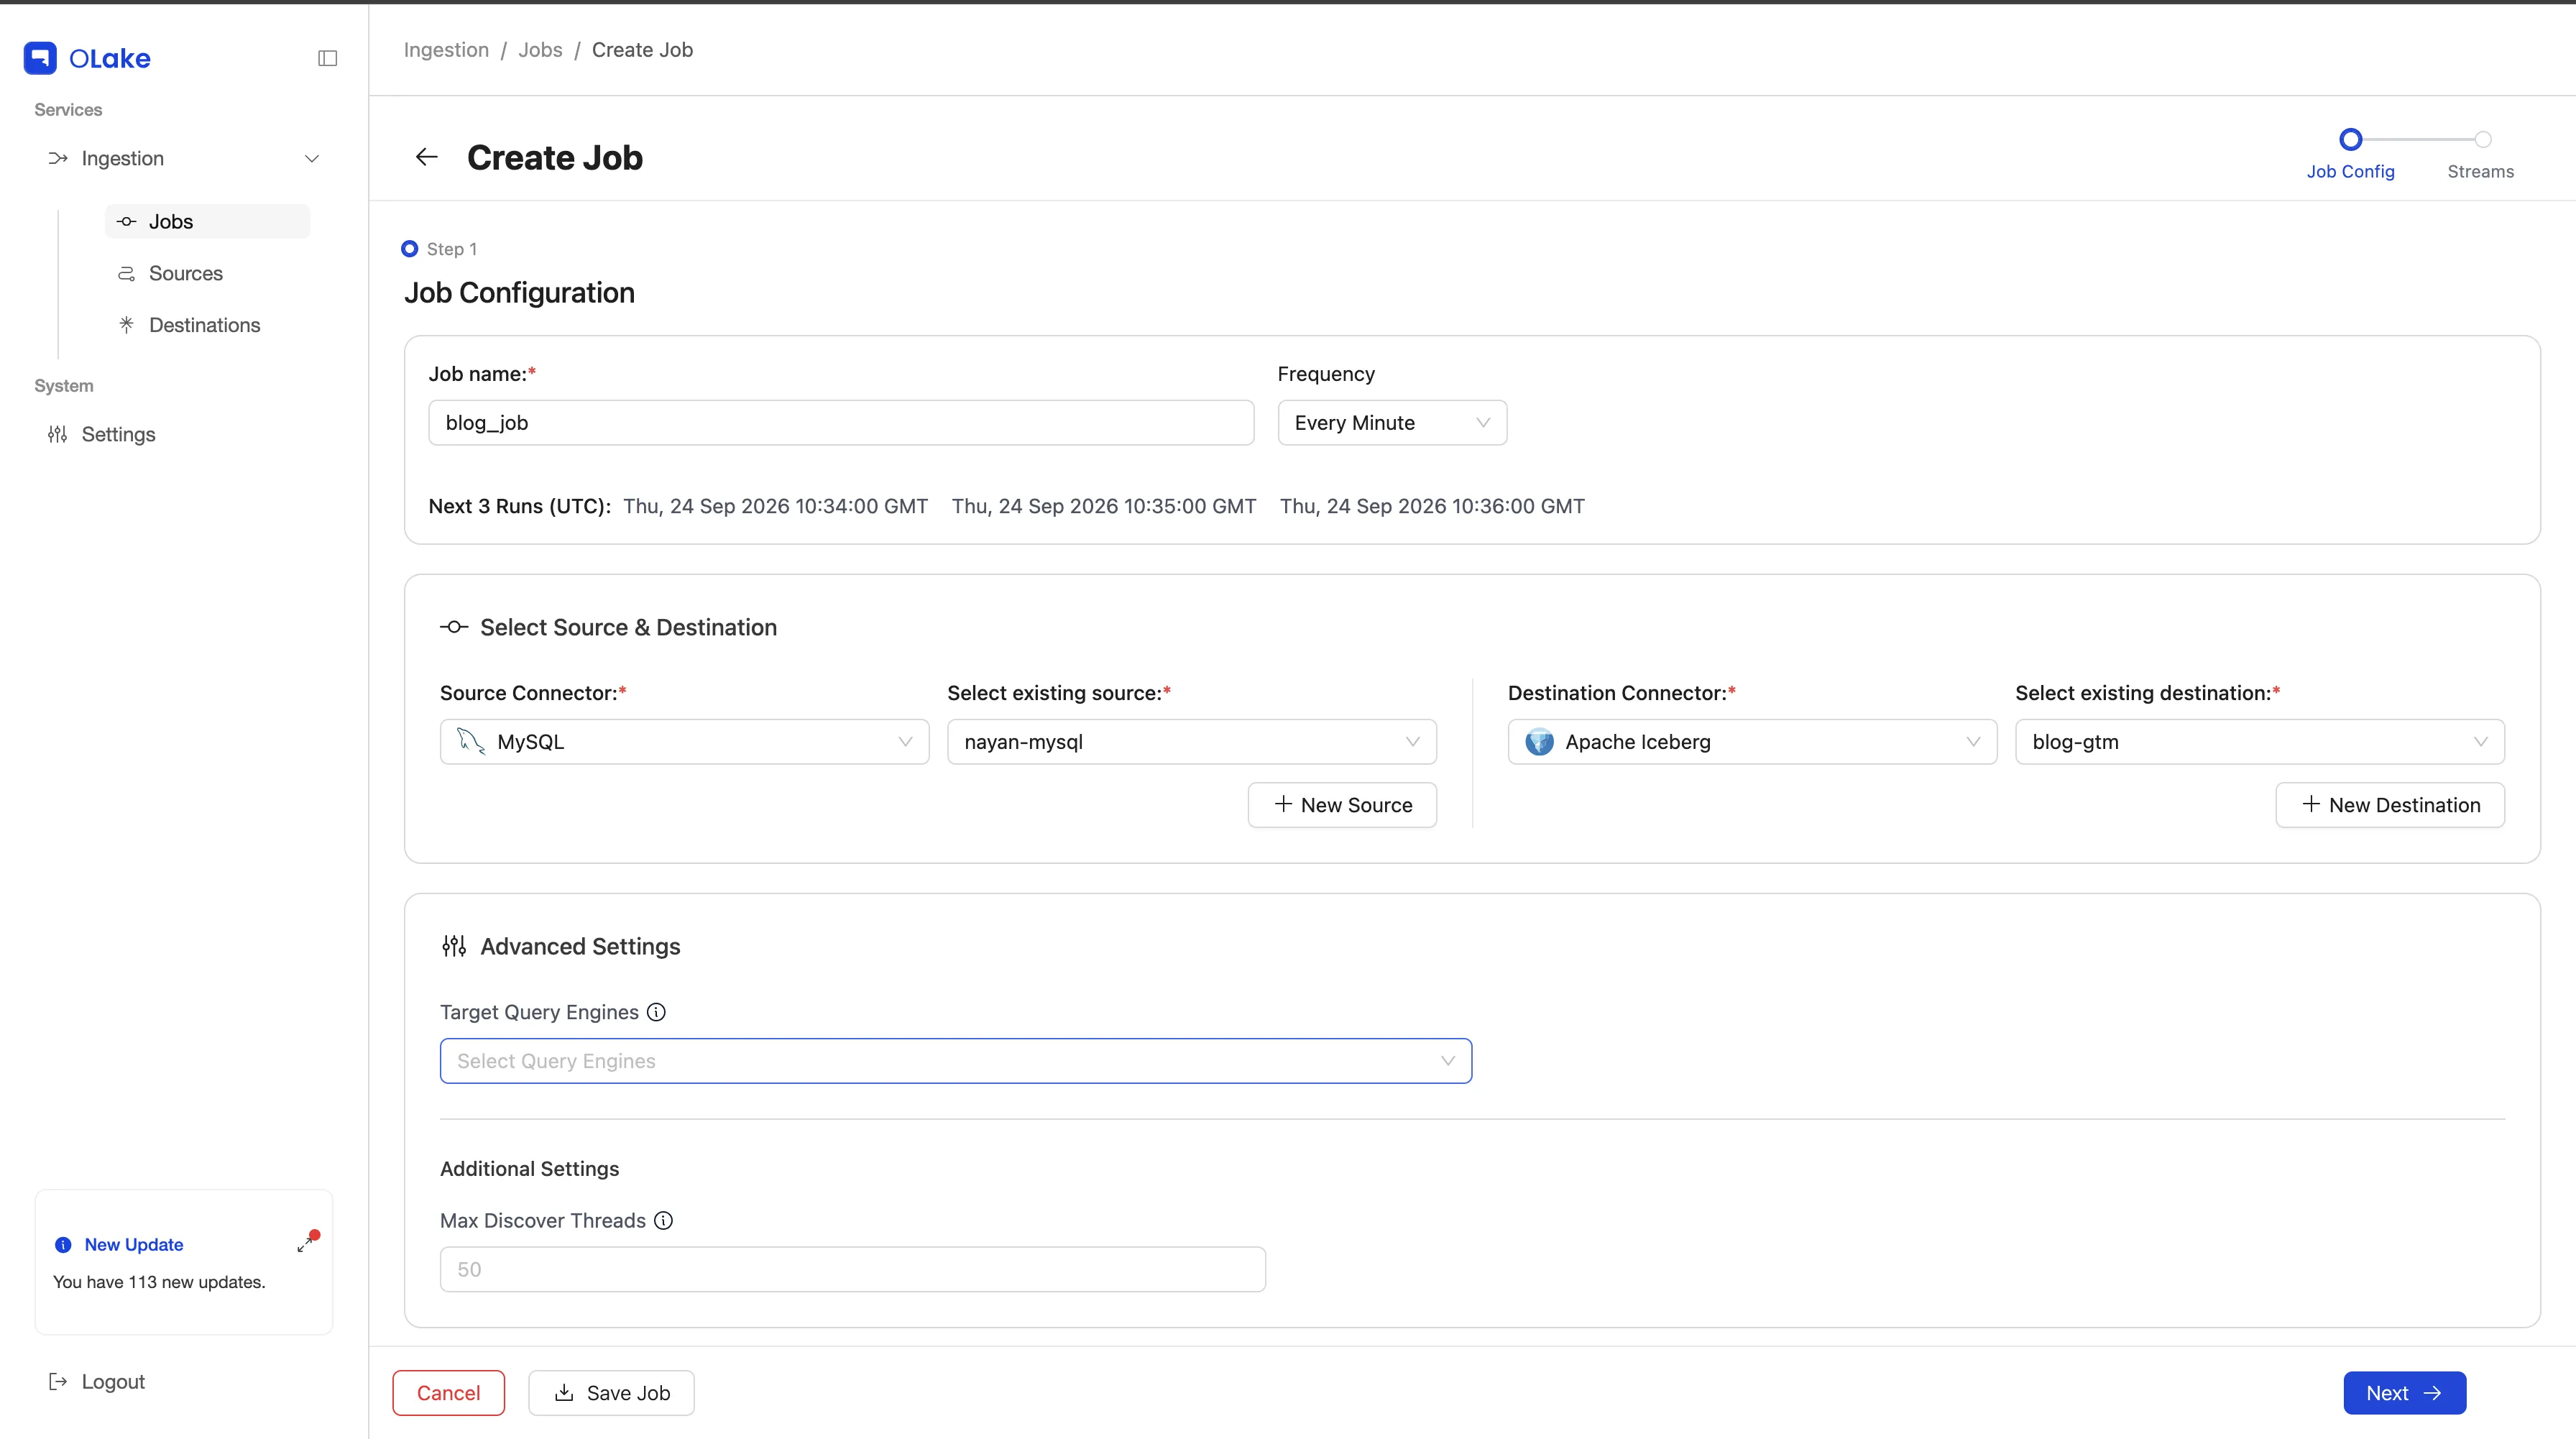
On the Job Configuration page, give your job a name (for example, blog_job) and choose how often it should run from the Frequency dropdown. Then pick MySQL as the source connector and select the source you created in Step 1, and do the same for the Iceberg destination.
Step 2a: Select Query Engine
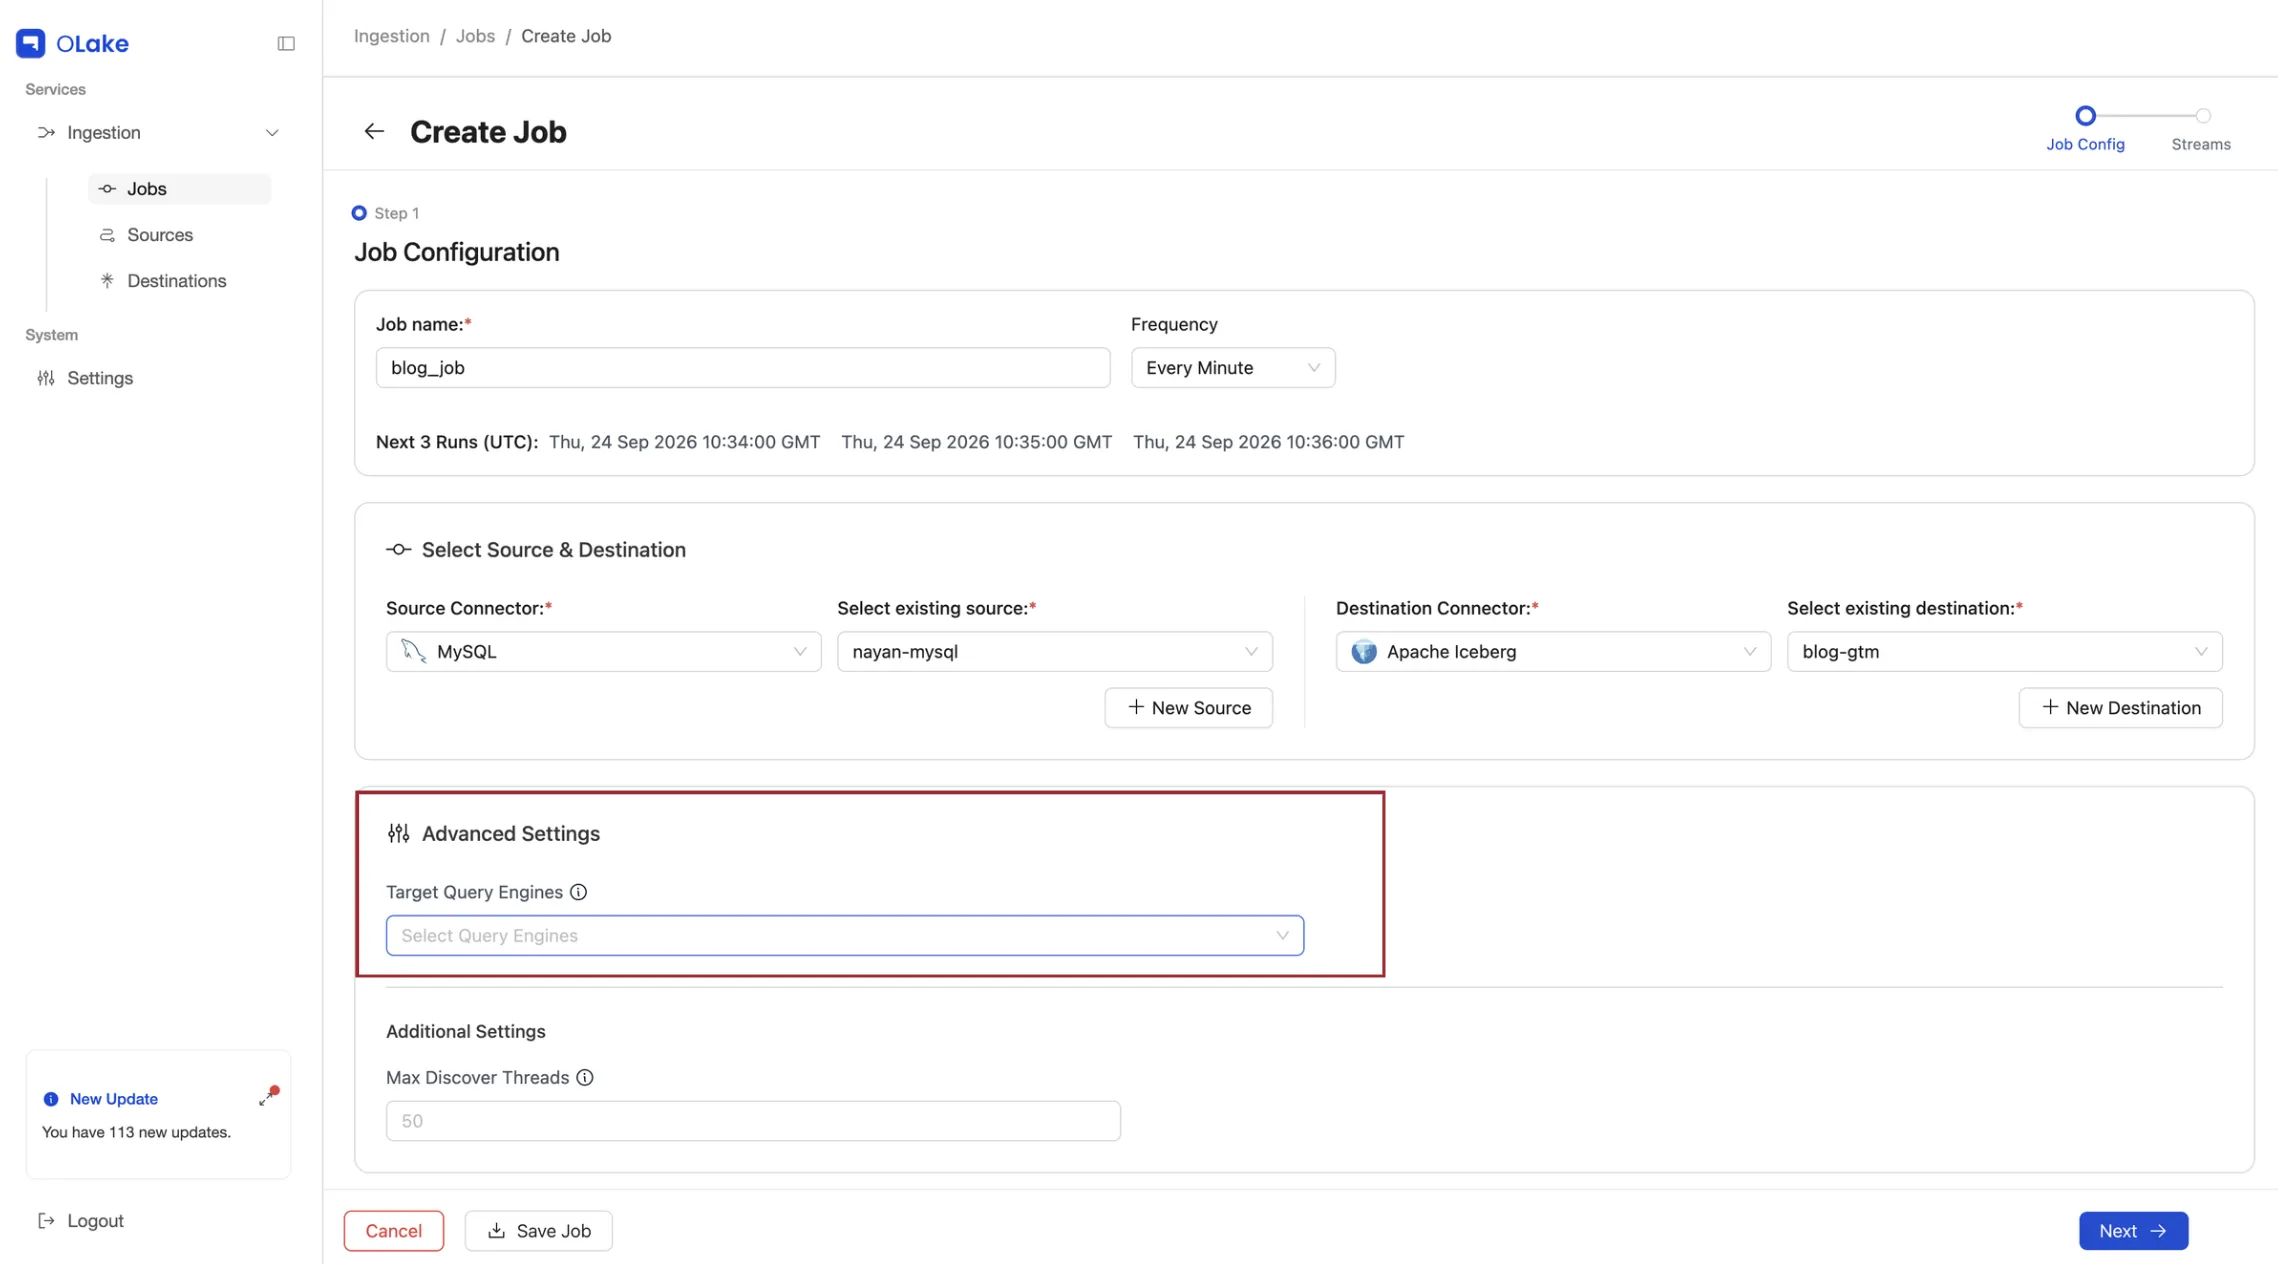
Under Advanced Settings, open the Target Query Engines dropdown and select DuckDB. You can pick more than one engine, but this guide uses DuckDB only.
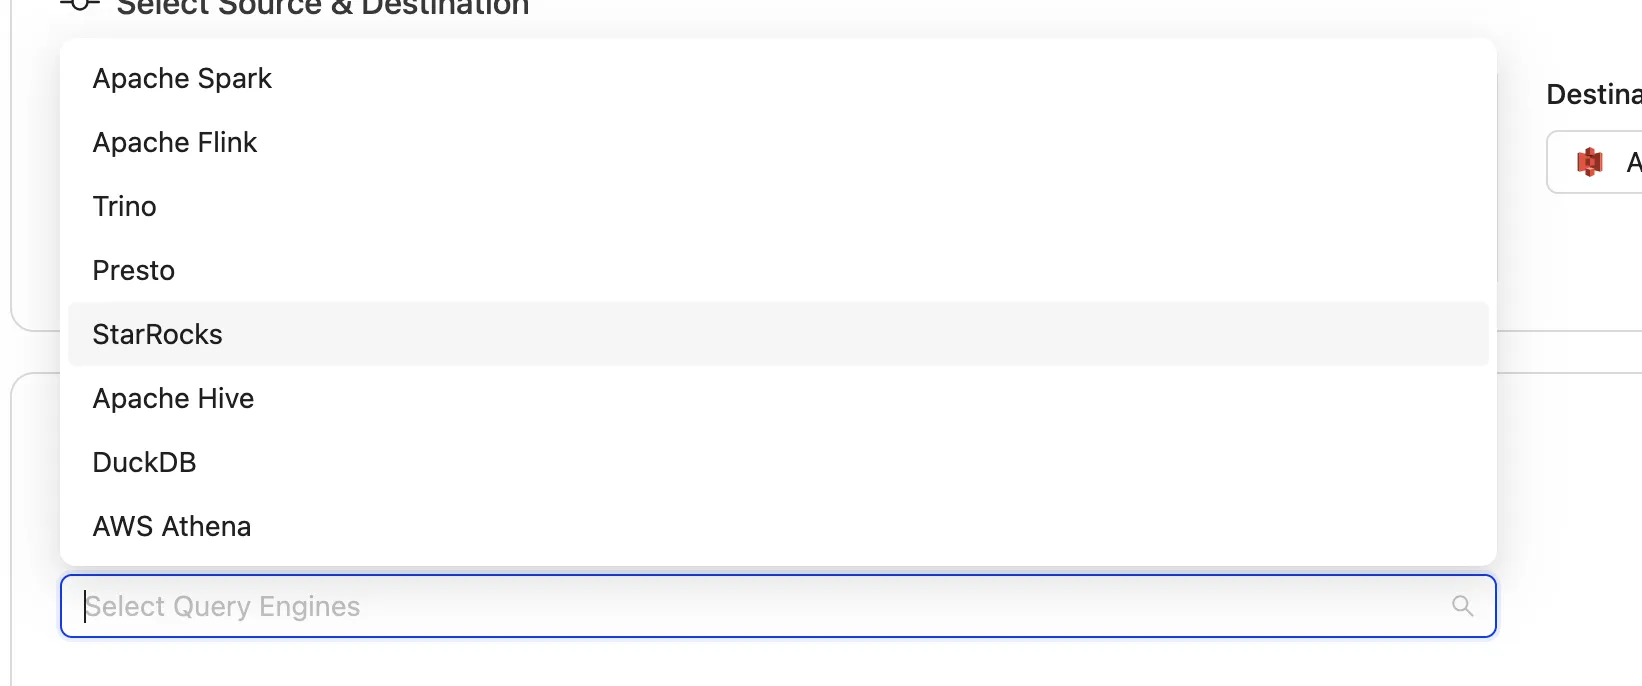
Click Next and you’ll be redirected to the Stream configuration page.
Step 3: Configure Streams
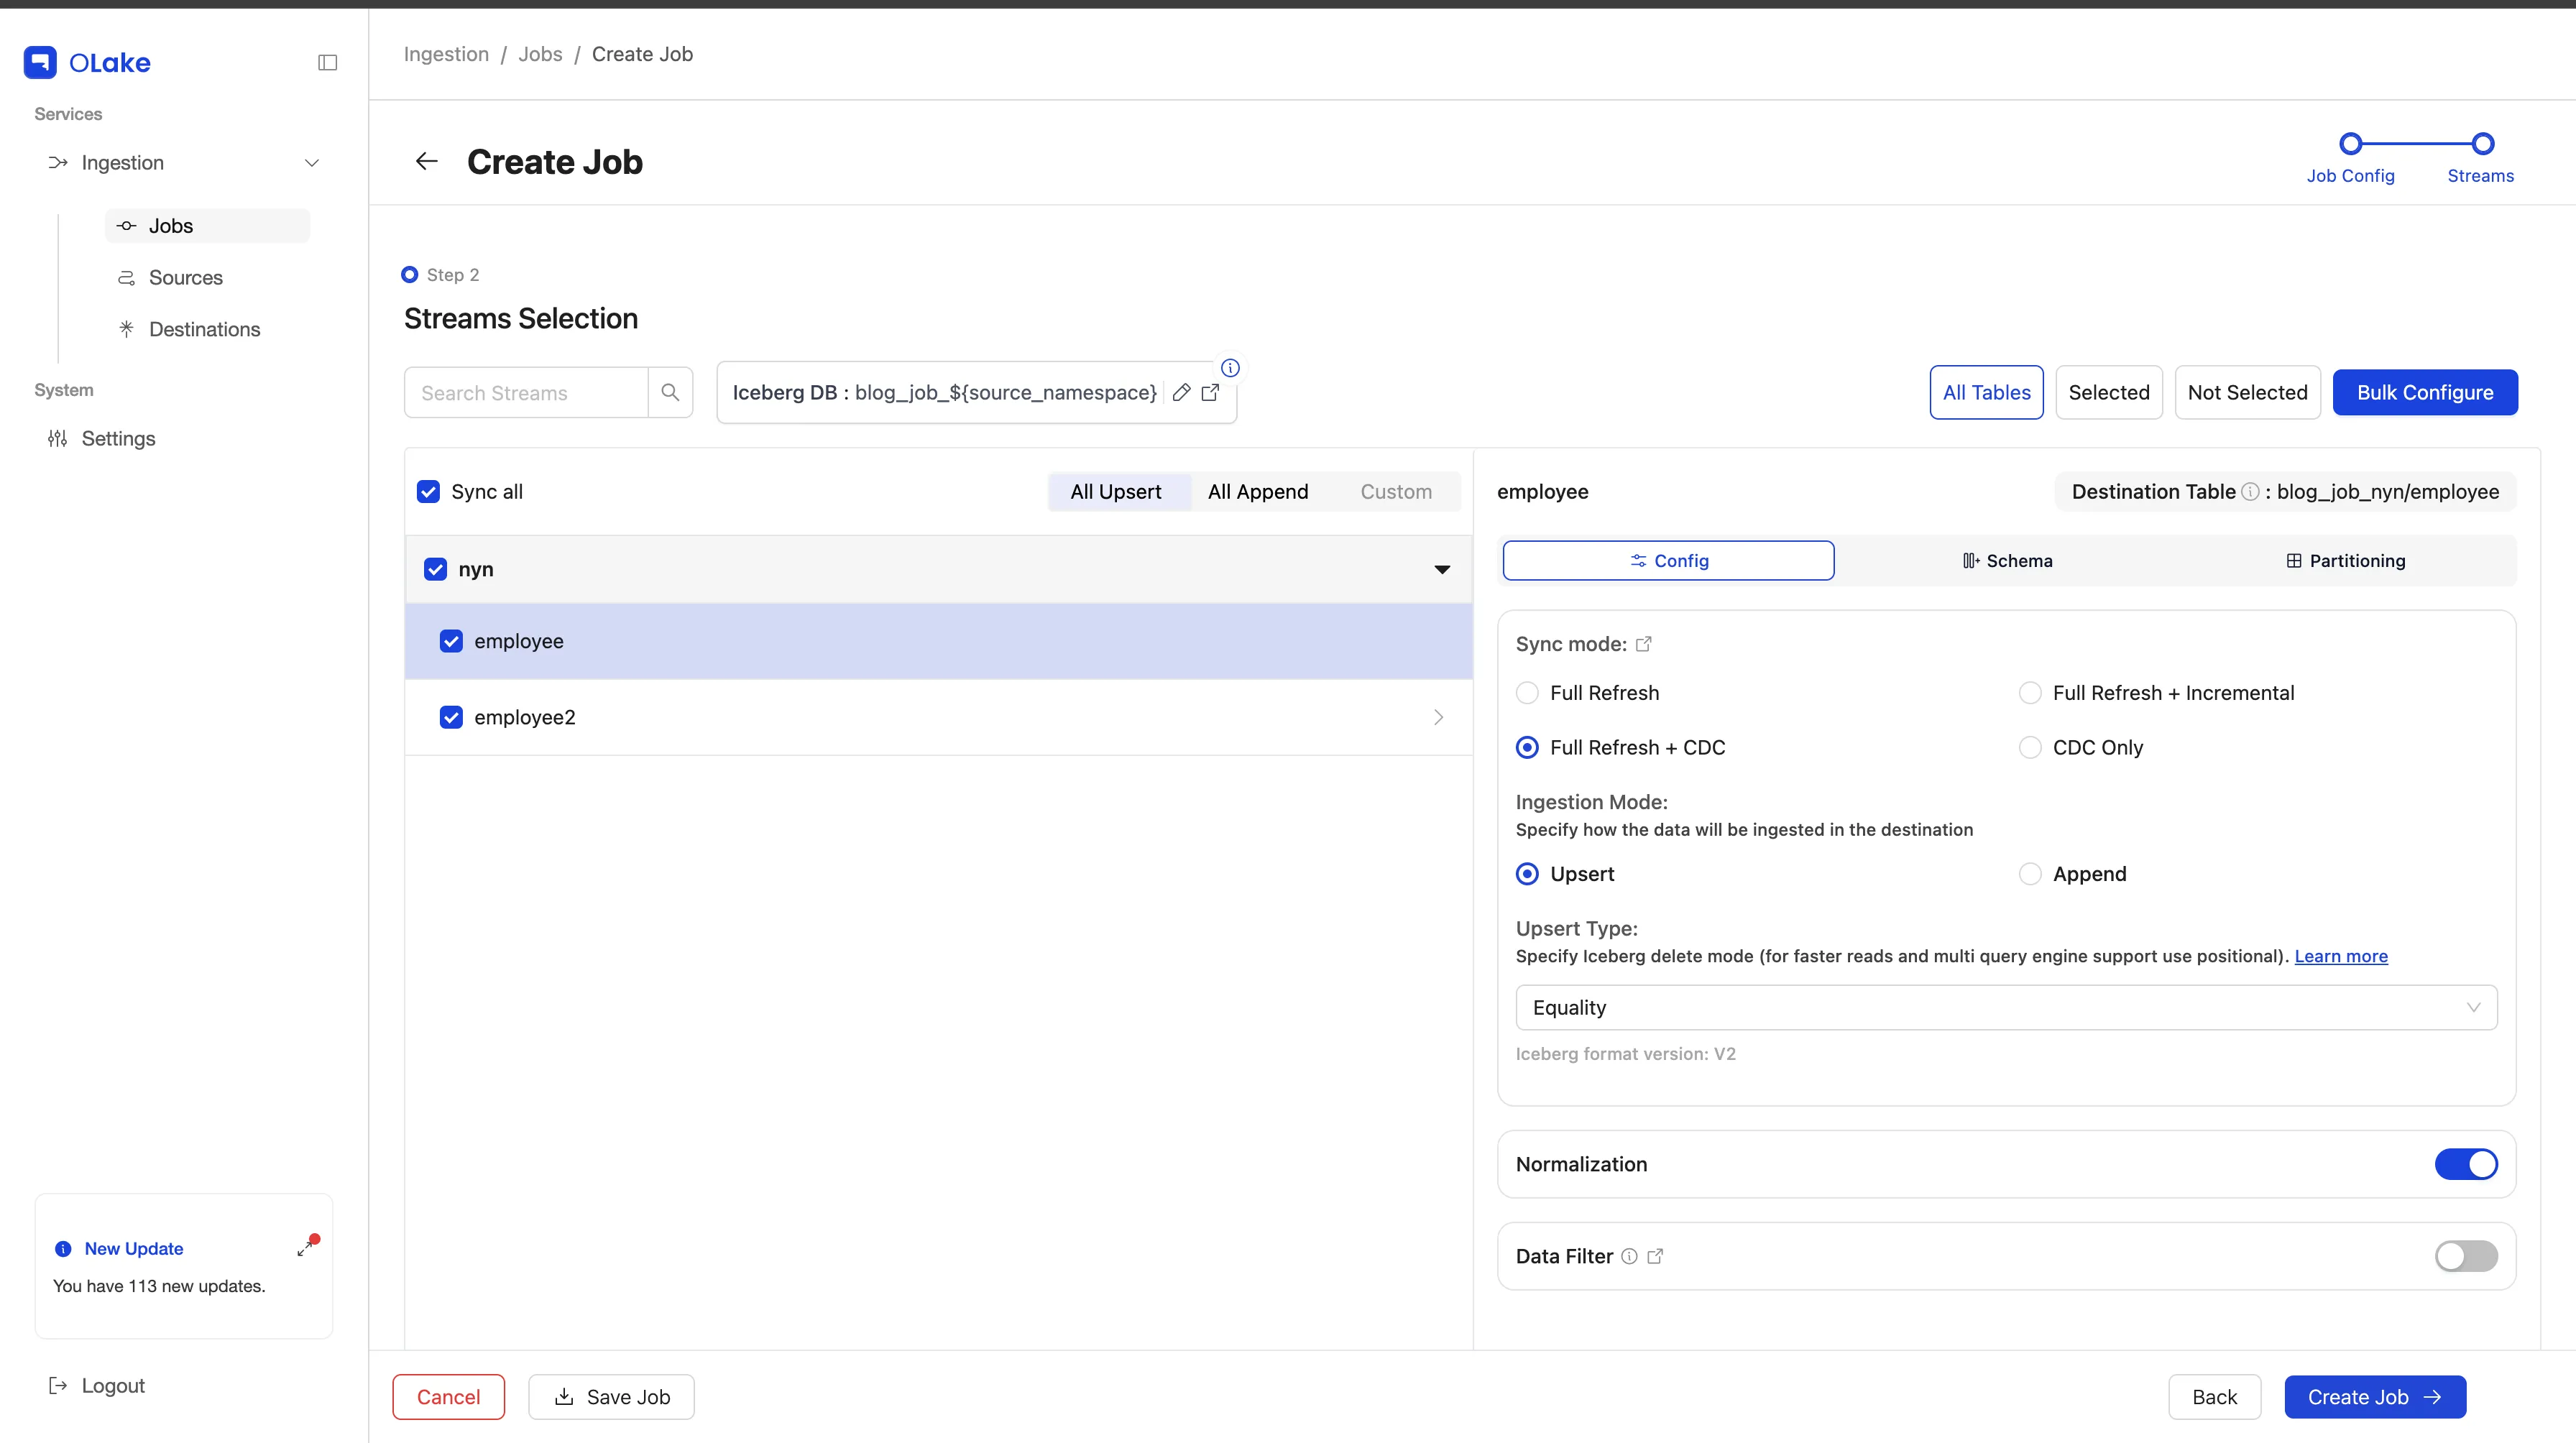
The Streams page lists every table in your MySQL database. Check the box next to each table you want to copy, or use Sync all to select everything. The Iceberg DB field at the top shows the database name your tables will land in, and you can click the edit icon to change it.
Click a table name to open its settings on the right. On the Config tab, you can:
- Pick a sync mode. Full Refresh + CDC copies all current rows first and then keeps copying new changes
- Choose an Ingestion Mode. Upsert updates existing rows when they change, while Append adds every change as a new row
- Turn on Normalization to store nested data as regular columns
The Schema tab shows the table's columns, and the Partitioning tab lets you group data by a column so queries run faster.
Step 3a: Specify Iceberg Delete Mode
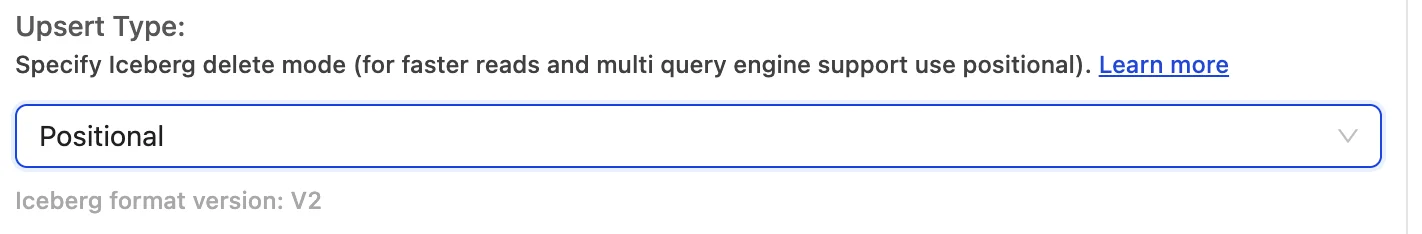
When the ingestion mode is Upsert, you can choose which type of delete file OLake Go writes to Iceberg.
Open the Upsert Type dropdown and select the delete type you want: Equality, Positional, or Deletion.
Positional is by default selected for DuckDB. You can change the delete mode to the one you prefer via the drop-down.
When you're done, click Create Job at the bottom right. A confirmation shows that your job was created, and clicking Jobs takes you back to the main Jobs page.
Step 4: Run the Sync
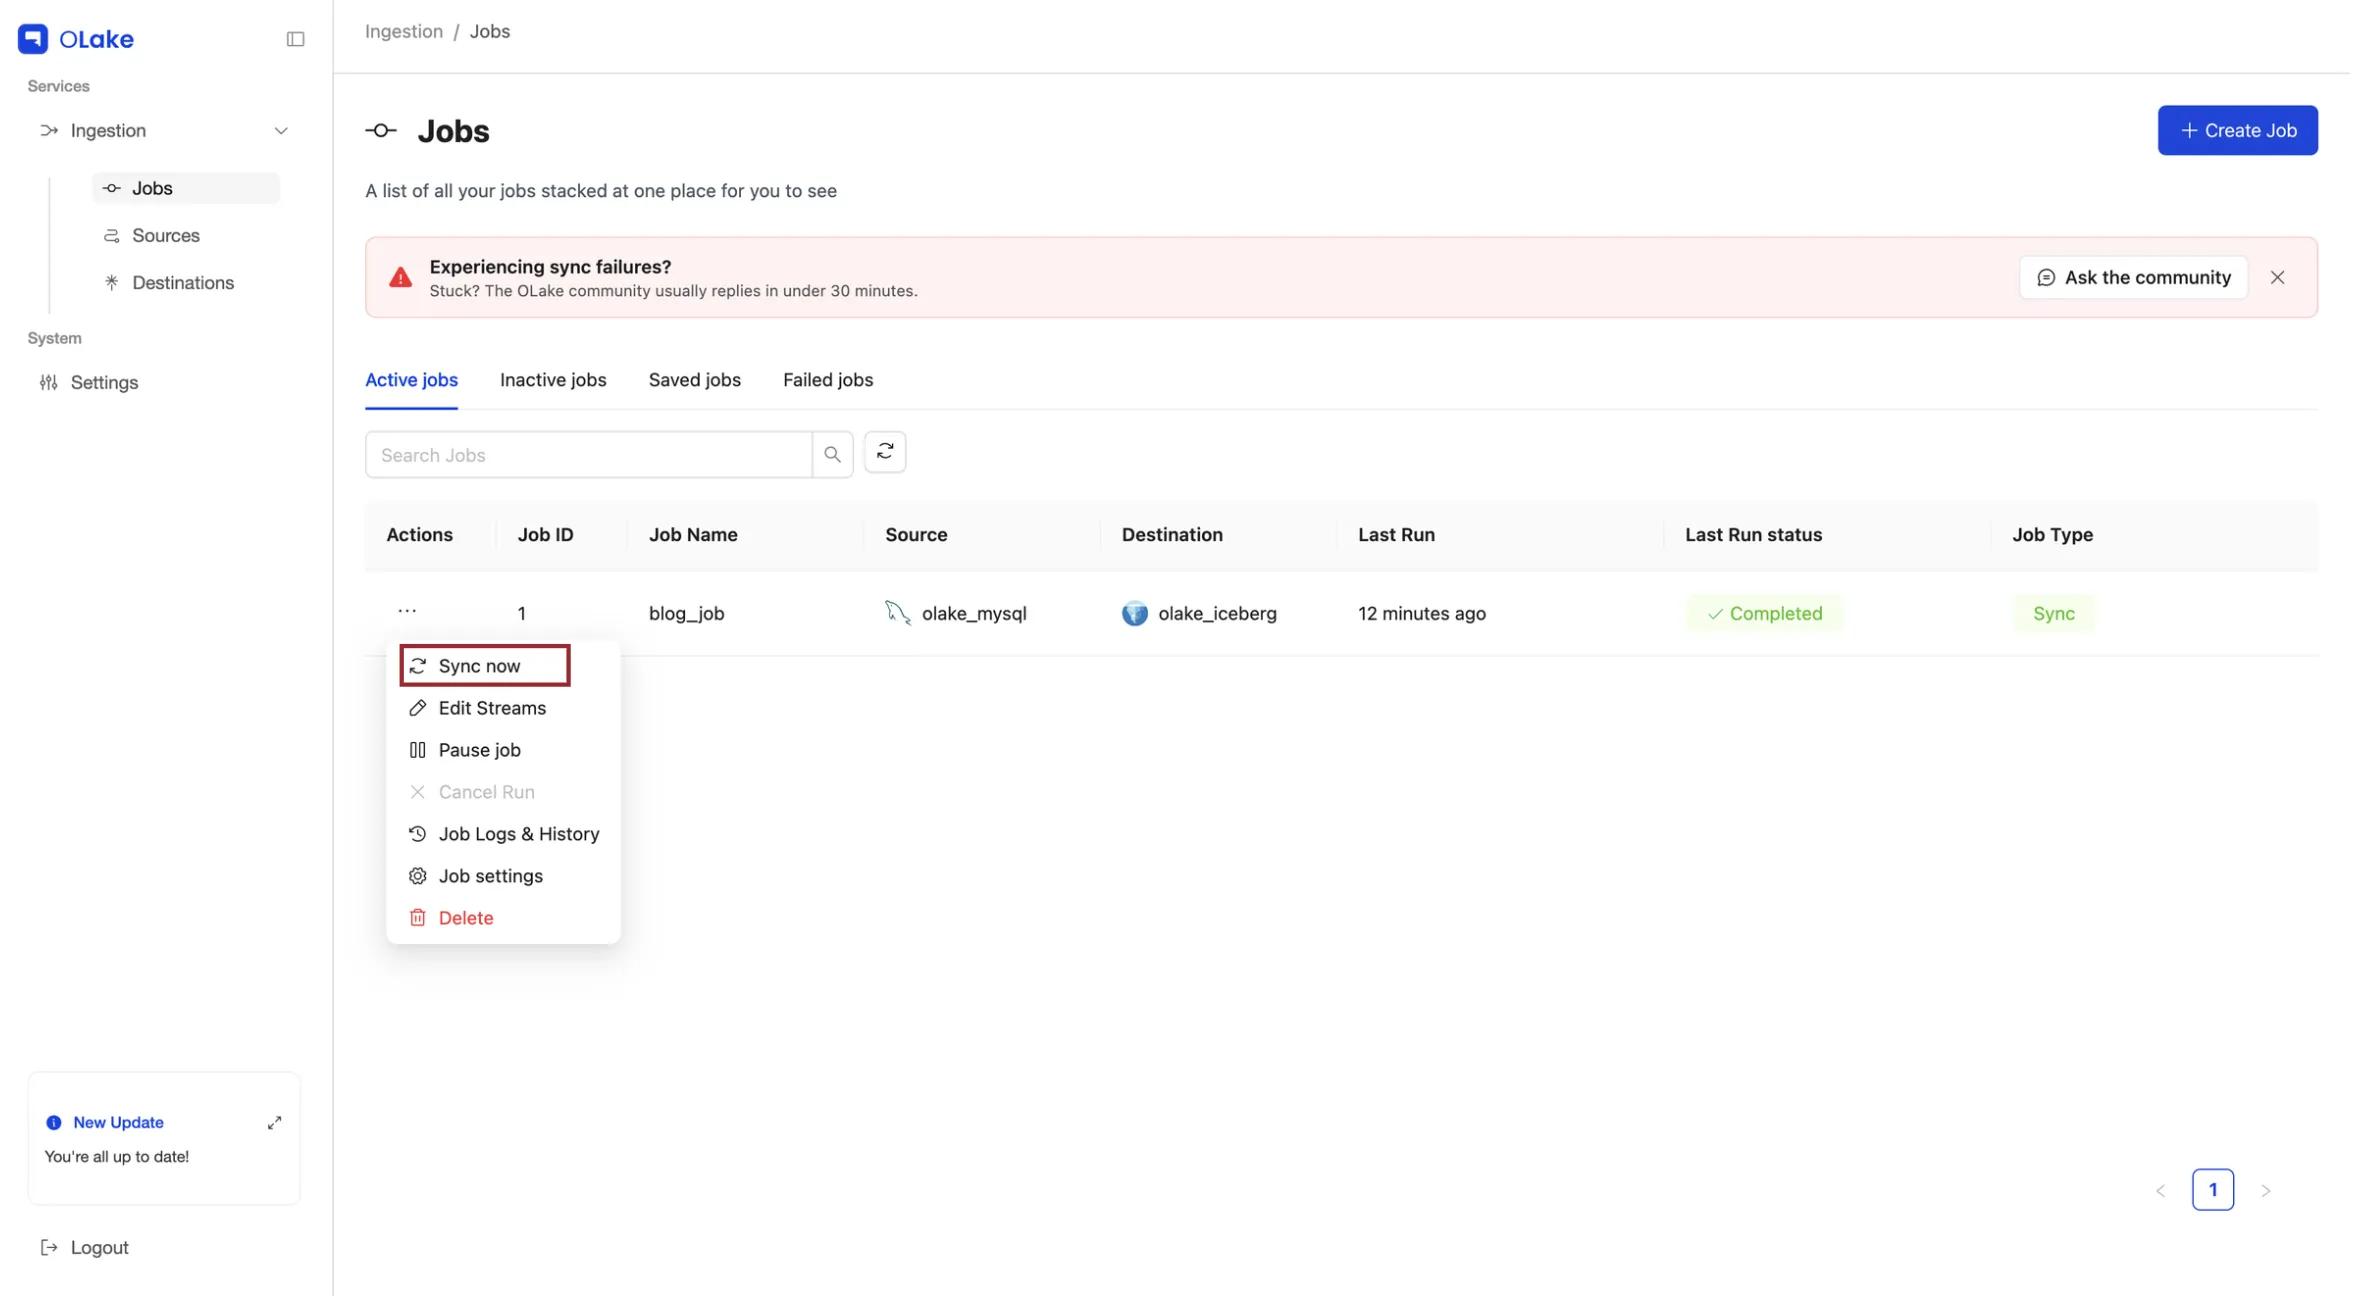
Your new job appears in the Active jobs tab. The Last Run status column shows whether each run is Running, Completed, or Failed.
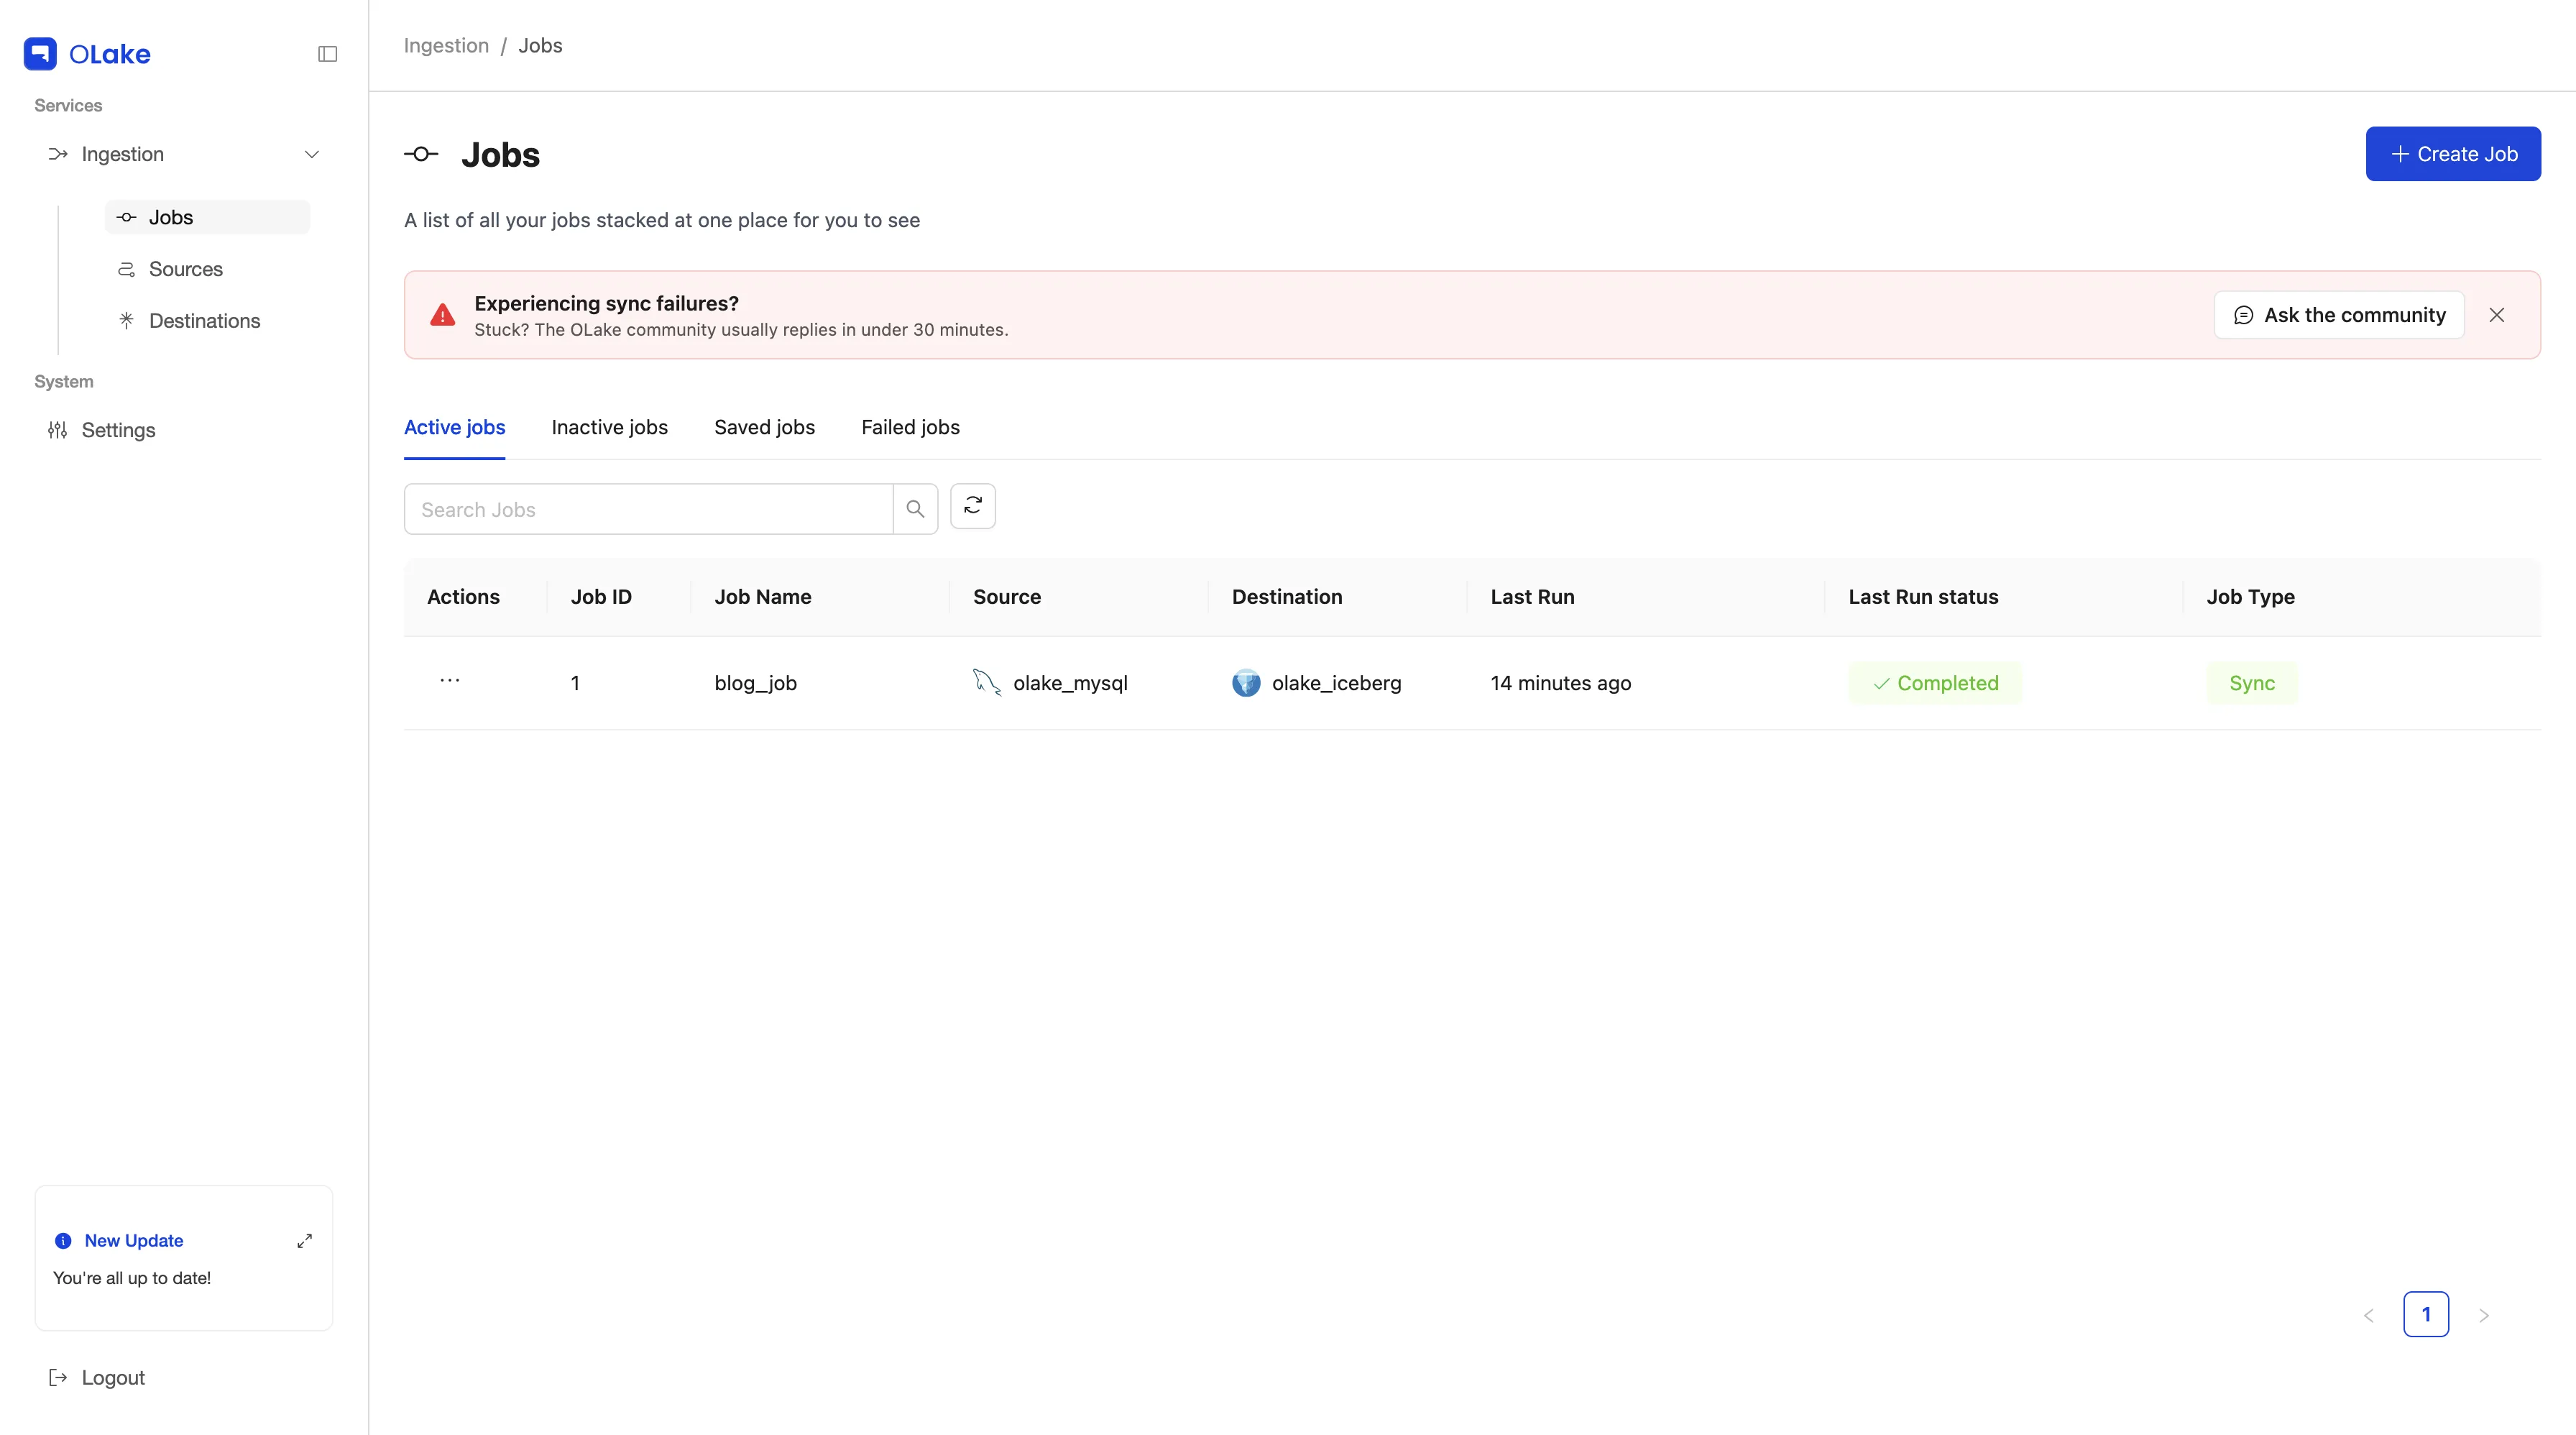
The job will run at its next scheduled time. To start it now, click the three dots in the Actions column next to your job and select Sync now.
To see how each run went, under Actions, select Job Logs & History. This page lists every run with its start time, runtime, and status.
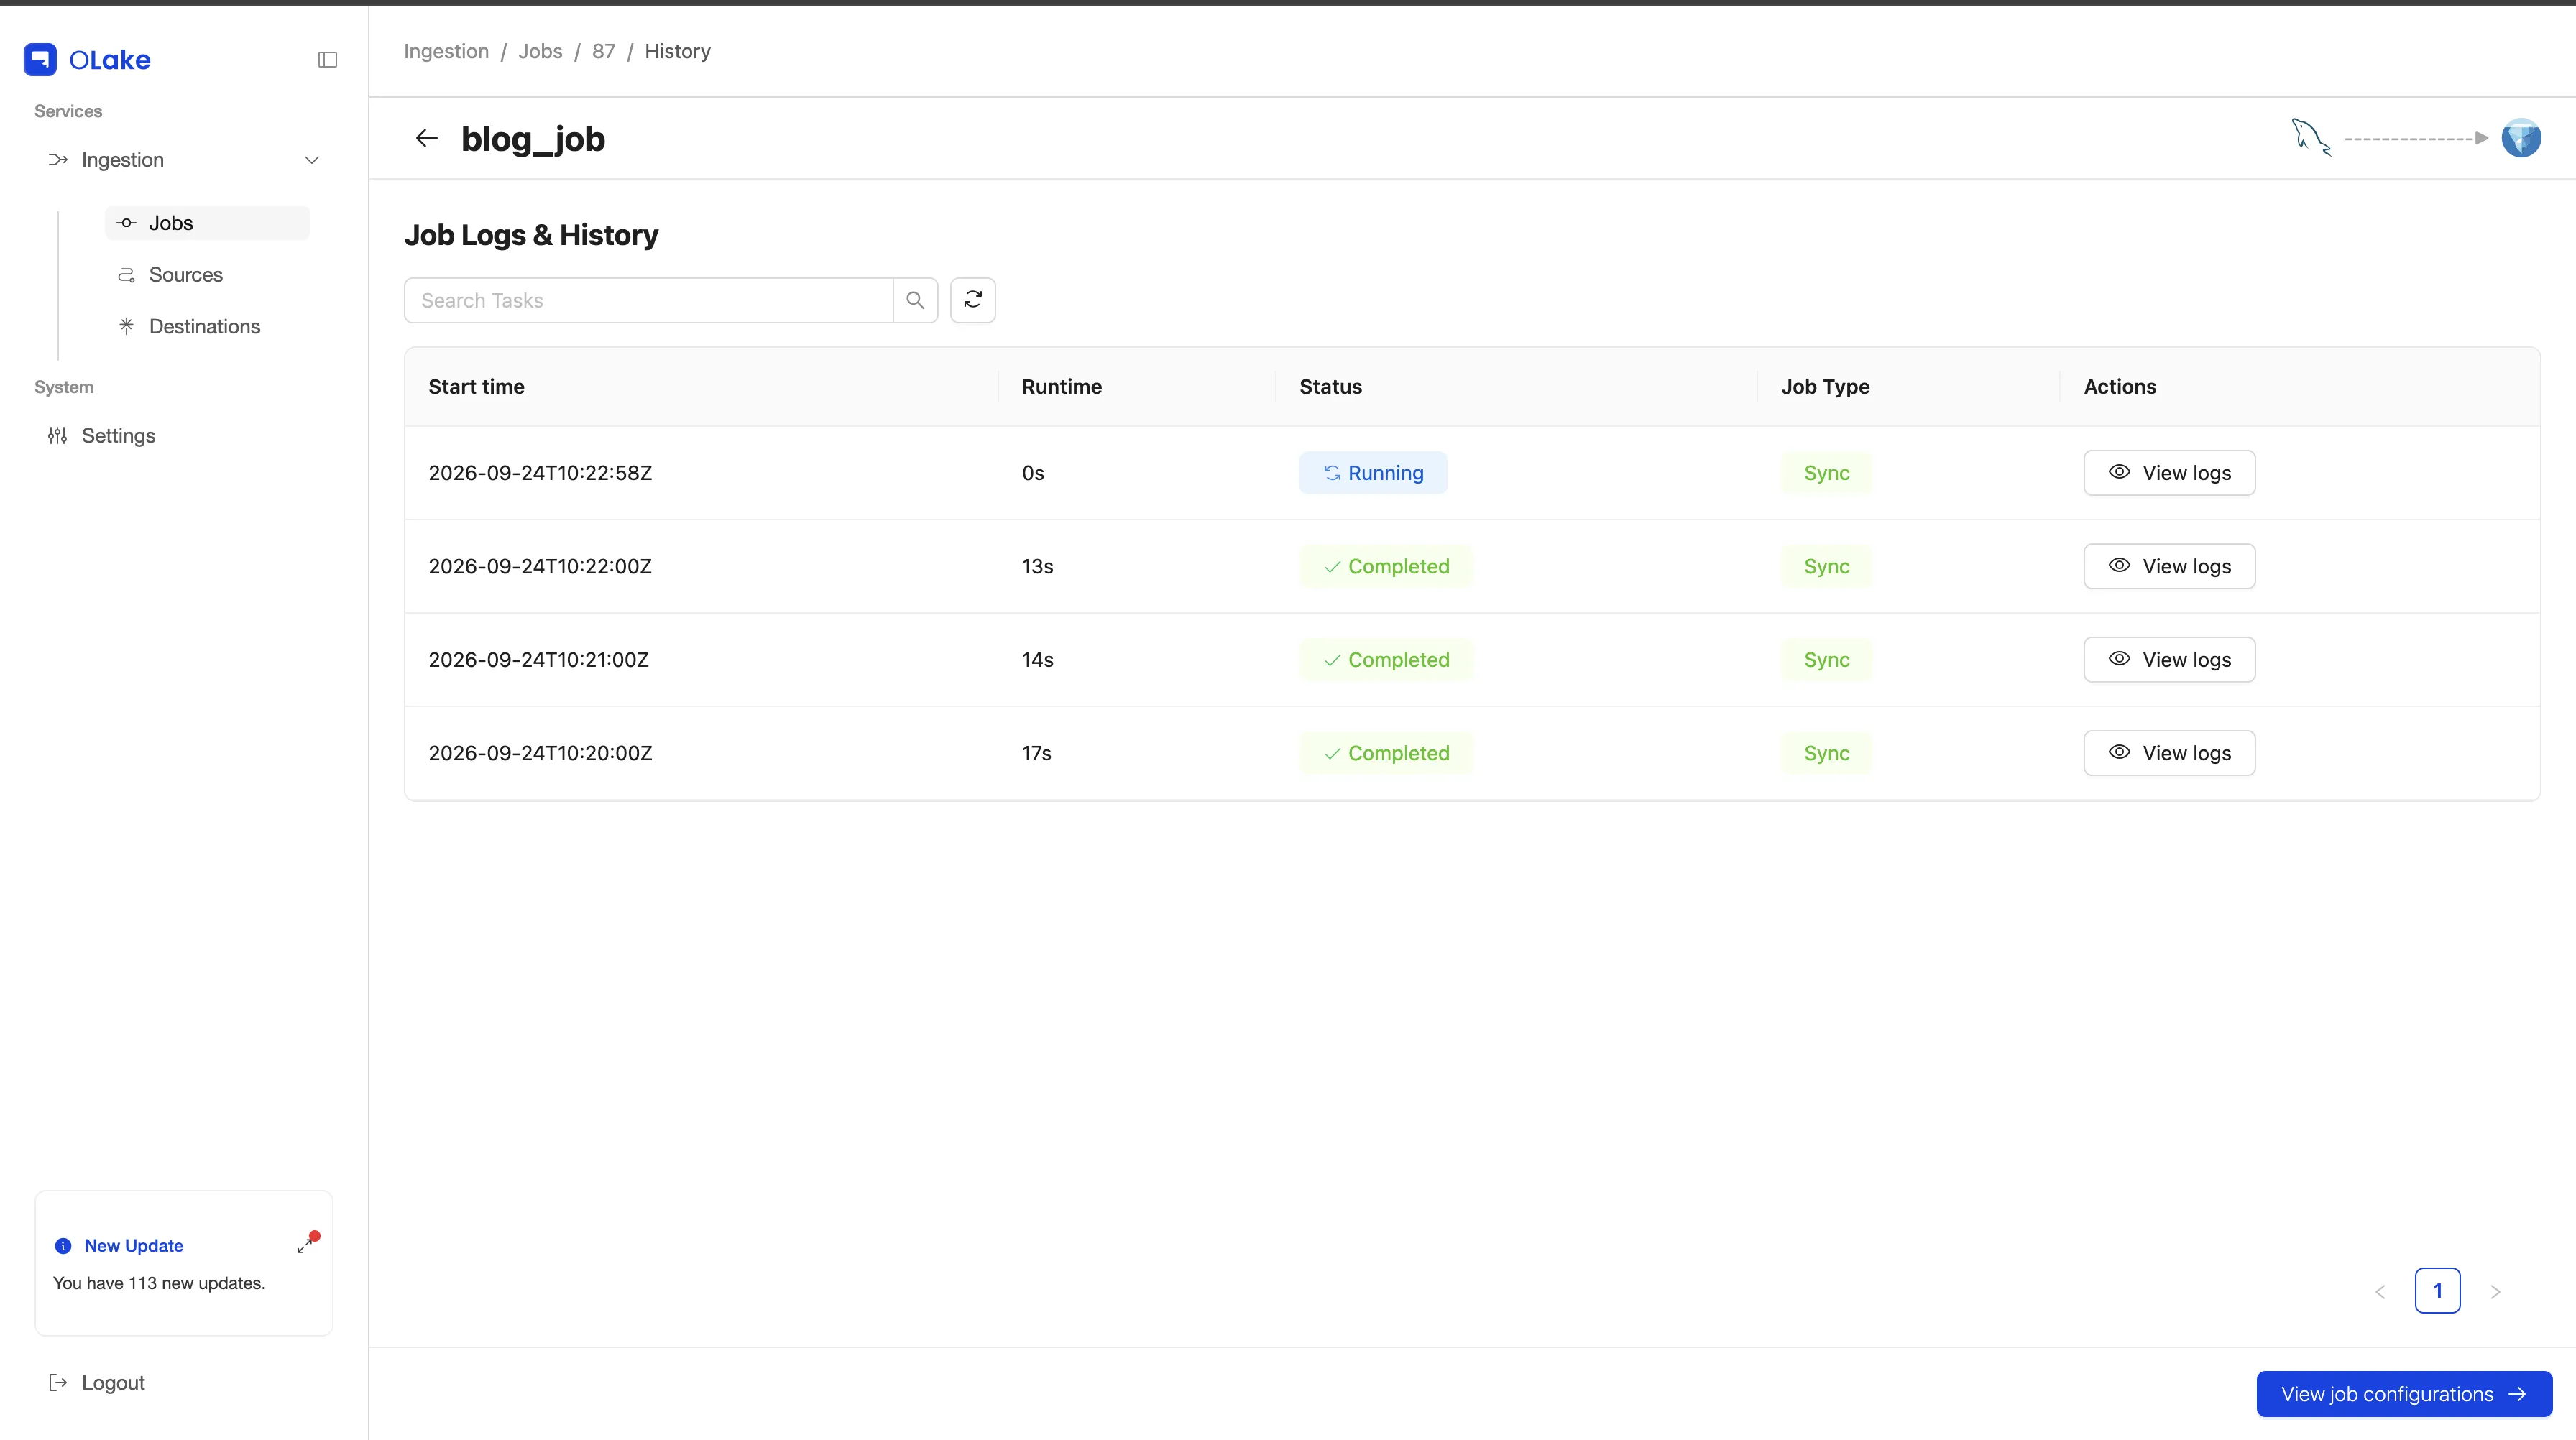
Click View logs next to any run to see its full log, including when MySQL CDC started, the total records read, and when the sync finished.
Once the sync finishes, the new Iceberg tables will be registered in your catalog and the data files will show up in your S3 bucket.
Step 5: Query with DuckDB
See the tables OLake Go created:
INSTALL httpfs;
LOAD httpfs;

CREATE SECRET (
    TYPE s3,
    KEY_ID '<ACCESS_KEY>',
    SECRET '<SECRET_KEY>',
    REGION '<REGION>',
    ENDPOINT '<ENDPOINT>',   -- remove for AWS S3
    URL_STYLE 'path',        -- required for MinIO and most S3-compatible stores
    USE_SSL false            -- set to true for AWS S3 or HTTPS endpoints
);
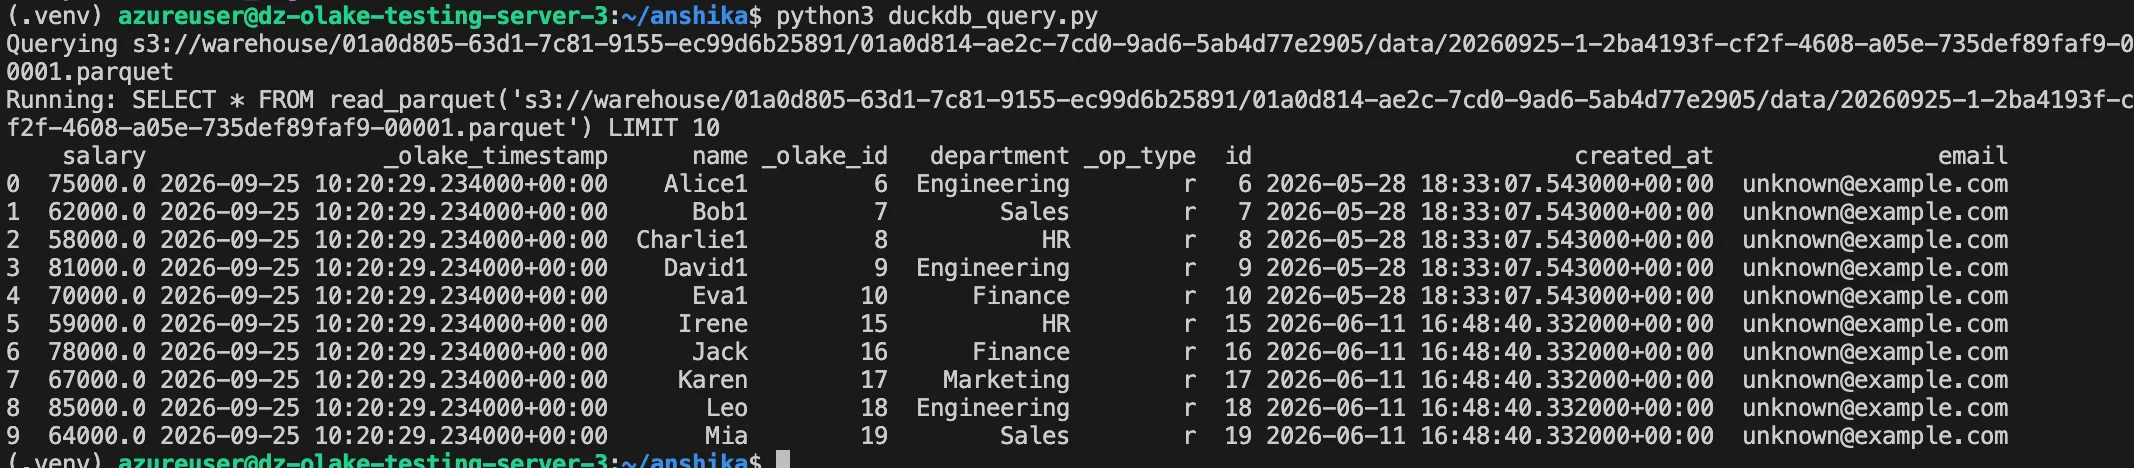
See the tables OLake Go created:
INSTALL iceberg;
LOAD iceberg;

SELECT * FROM iceberg_scan('<TABLE_LOCATION>') LIMIT 10;
Conclusion
You now have a pipeline that keeps MySQL changes flowing into Apache Iceberg on the schedule you chose, and a DuckDB session that can query those tables directly from object storage. Your production database stays focused on serving the application, while ad-hoc analysis, notebook exploration, and quick sanity checks run locally in DuckDB without a warehouse or cluster in the middle.
The tables are standard Iceberg, so DuckDB is just one way in. When a workload outgrows a single machine, the same tables can be read by Trino, Apache Spark, ClickHouse, or StarRocks, with no re-ingestion. See which engines pair with your catalog in the compatibility guide. Have questions? Join the OLake Slack community.