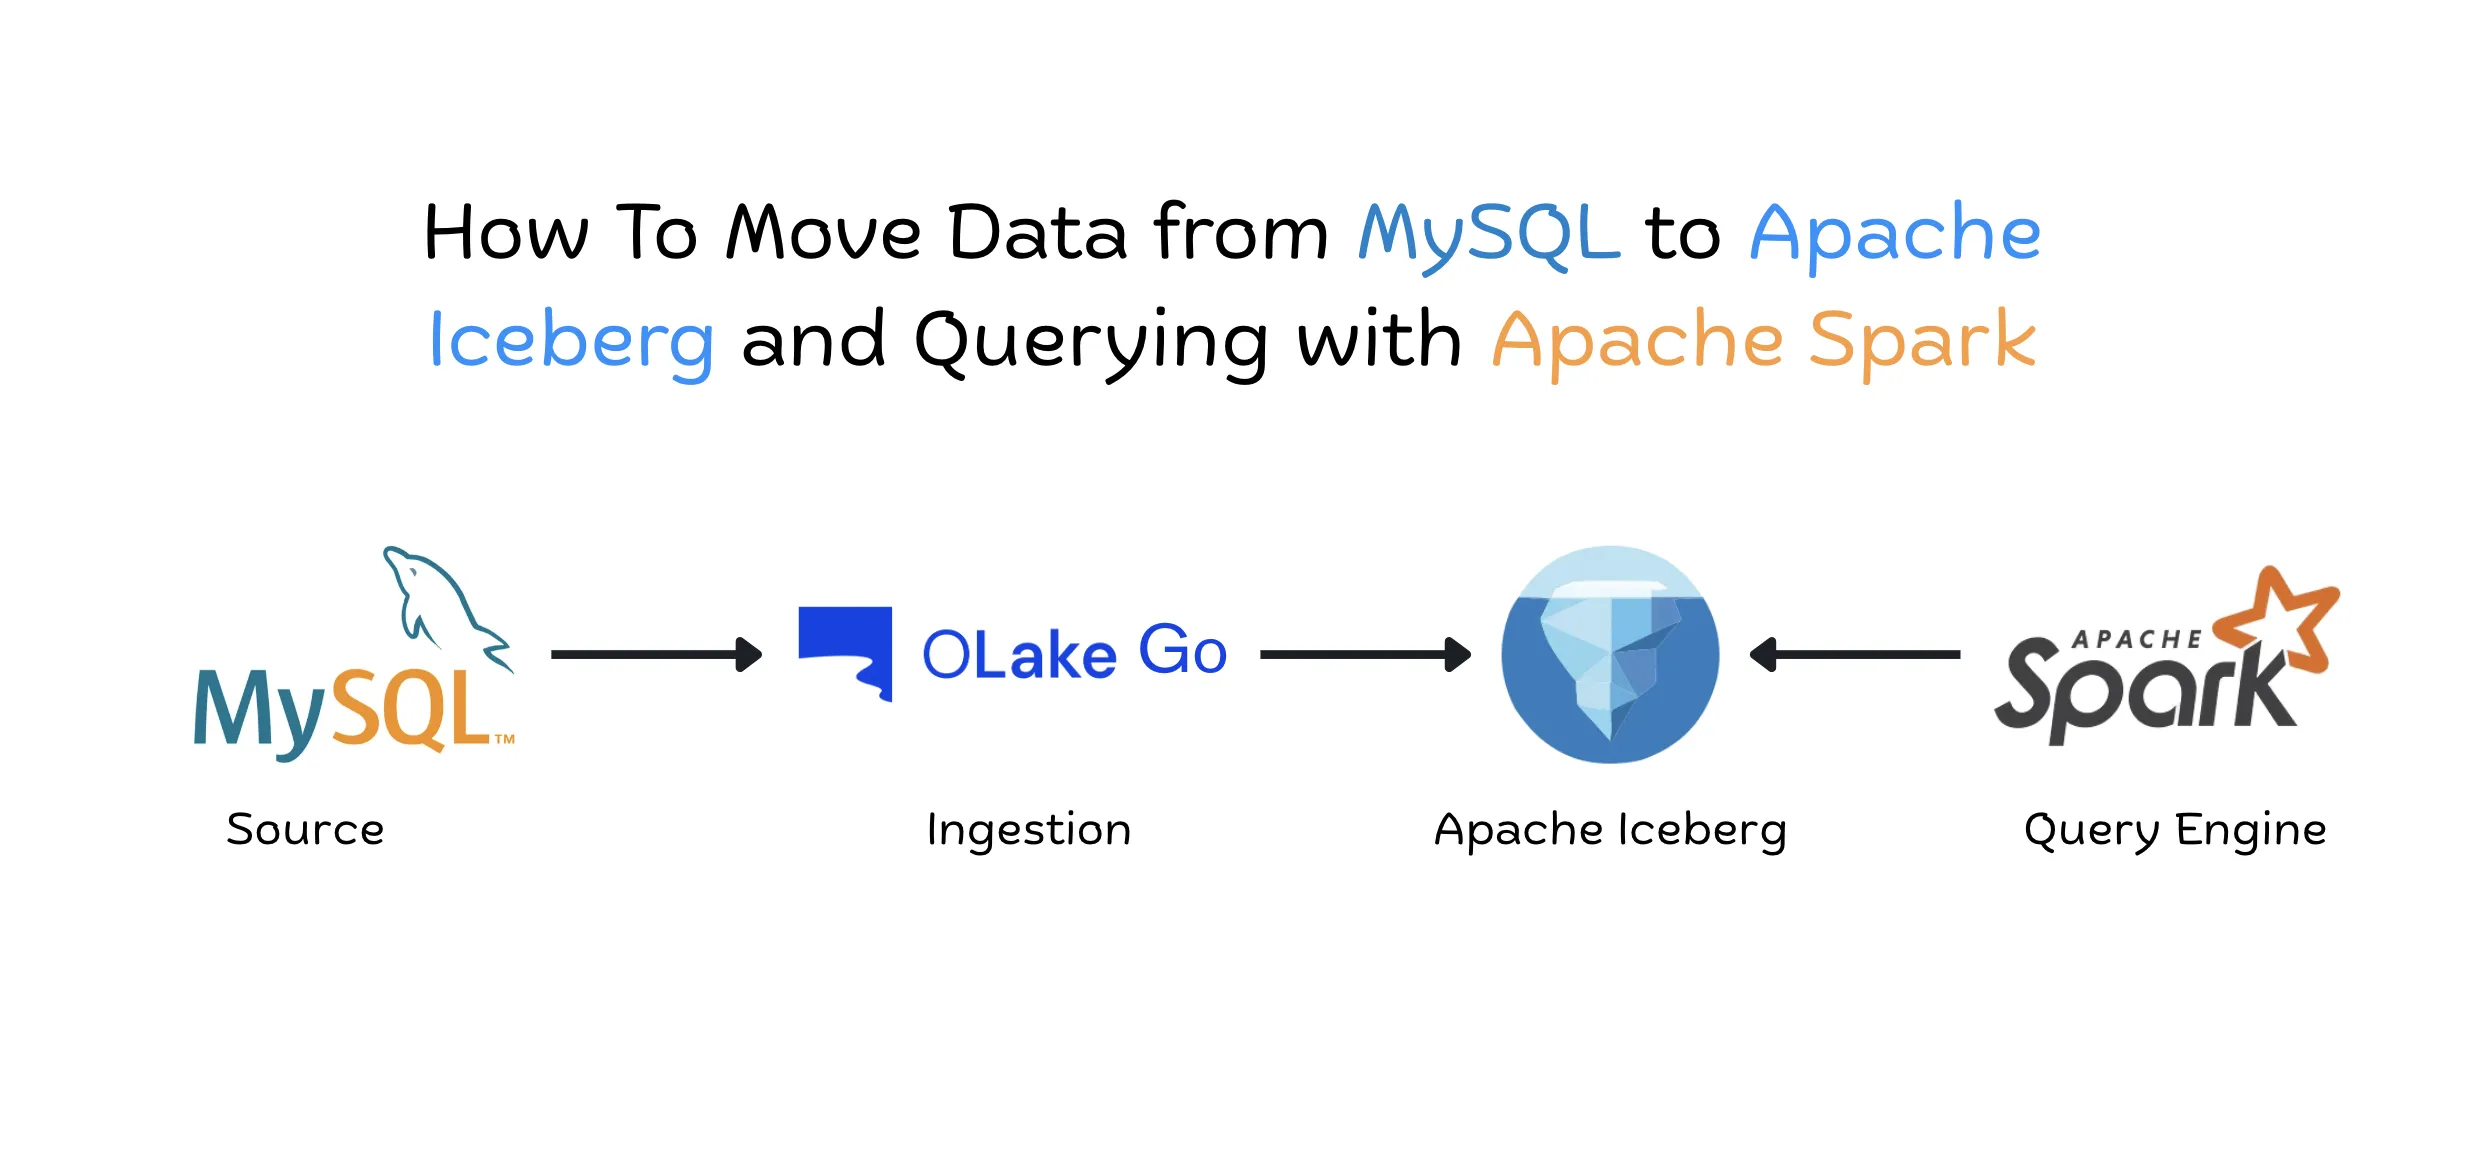
How To Move Data from MySQL to Apache Iceberg and Querying with Apache Spark
6 min read
Introduction
Many teams keep their data in MySQL, but running large reports directly on the production database adds load and slows down the queries the application depends on.Copying that data into Apache Iceberg lets you run reports on a separate copy, so MySQL stays fast. Iceberg is also an open format, which means you can query it with whichever engine you prefer.
OLake Go replicates data from databases like MySQL into Apache Iceberg tables and writes them in a format your chosen query engines can read. This guide shows each step in OLake Go. You'll connect MySQL, replicate the data to Iceberg tables in the catalog of your choice, pick Apache Spark as your query engine, choose which tables to ingest, run the sync, and then query the data in Spark.
Step 1: Set Up the Source and Destination
The OLake Go docs explain how to set up MySQL and Iceberg, so follow the links below for each one. Pick the catalog you want to use and follow the link below to help you set it up. To see which engines work with which catalogs, check Compatibility with Query Engines.
When both Soruces and Destinations are created, you can move on to the next step.
| Source | Setup Guide |
|---|---|
| MySQL | Link |
| Destination | Catalog | Link |
|---|---|---|
| Apache Iceberg | HIVE | Link |
| REST | Link | |
| NESSIE | Link | |
| AWS GLUE | Link | |
| JDBC | Link | |
| Polaris | Link | |
| BigLake | Link | |
| Lakekeeper | Link | |
| Unity | Link | |
| S3 tables | Link | |
| Horizon | Link |
Step 2: Create a Job and Select the Query Engine
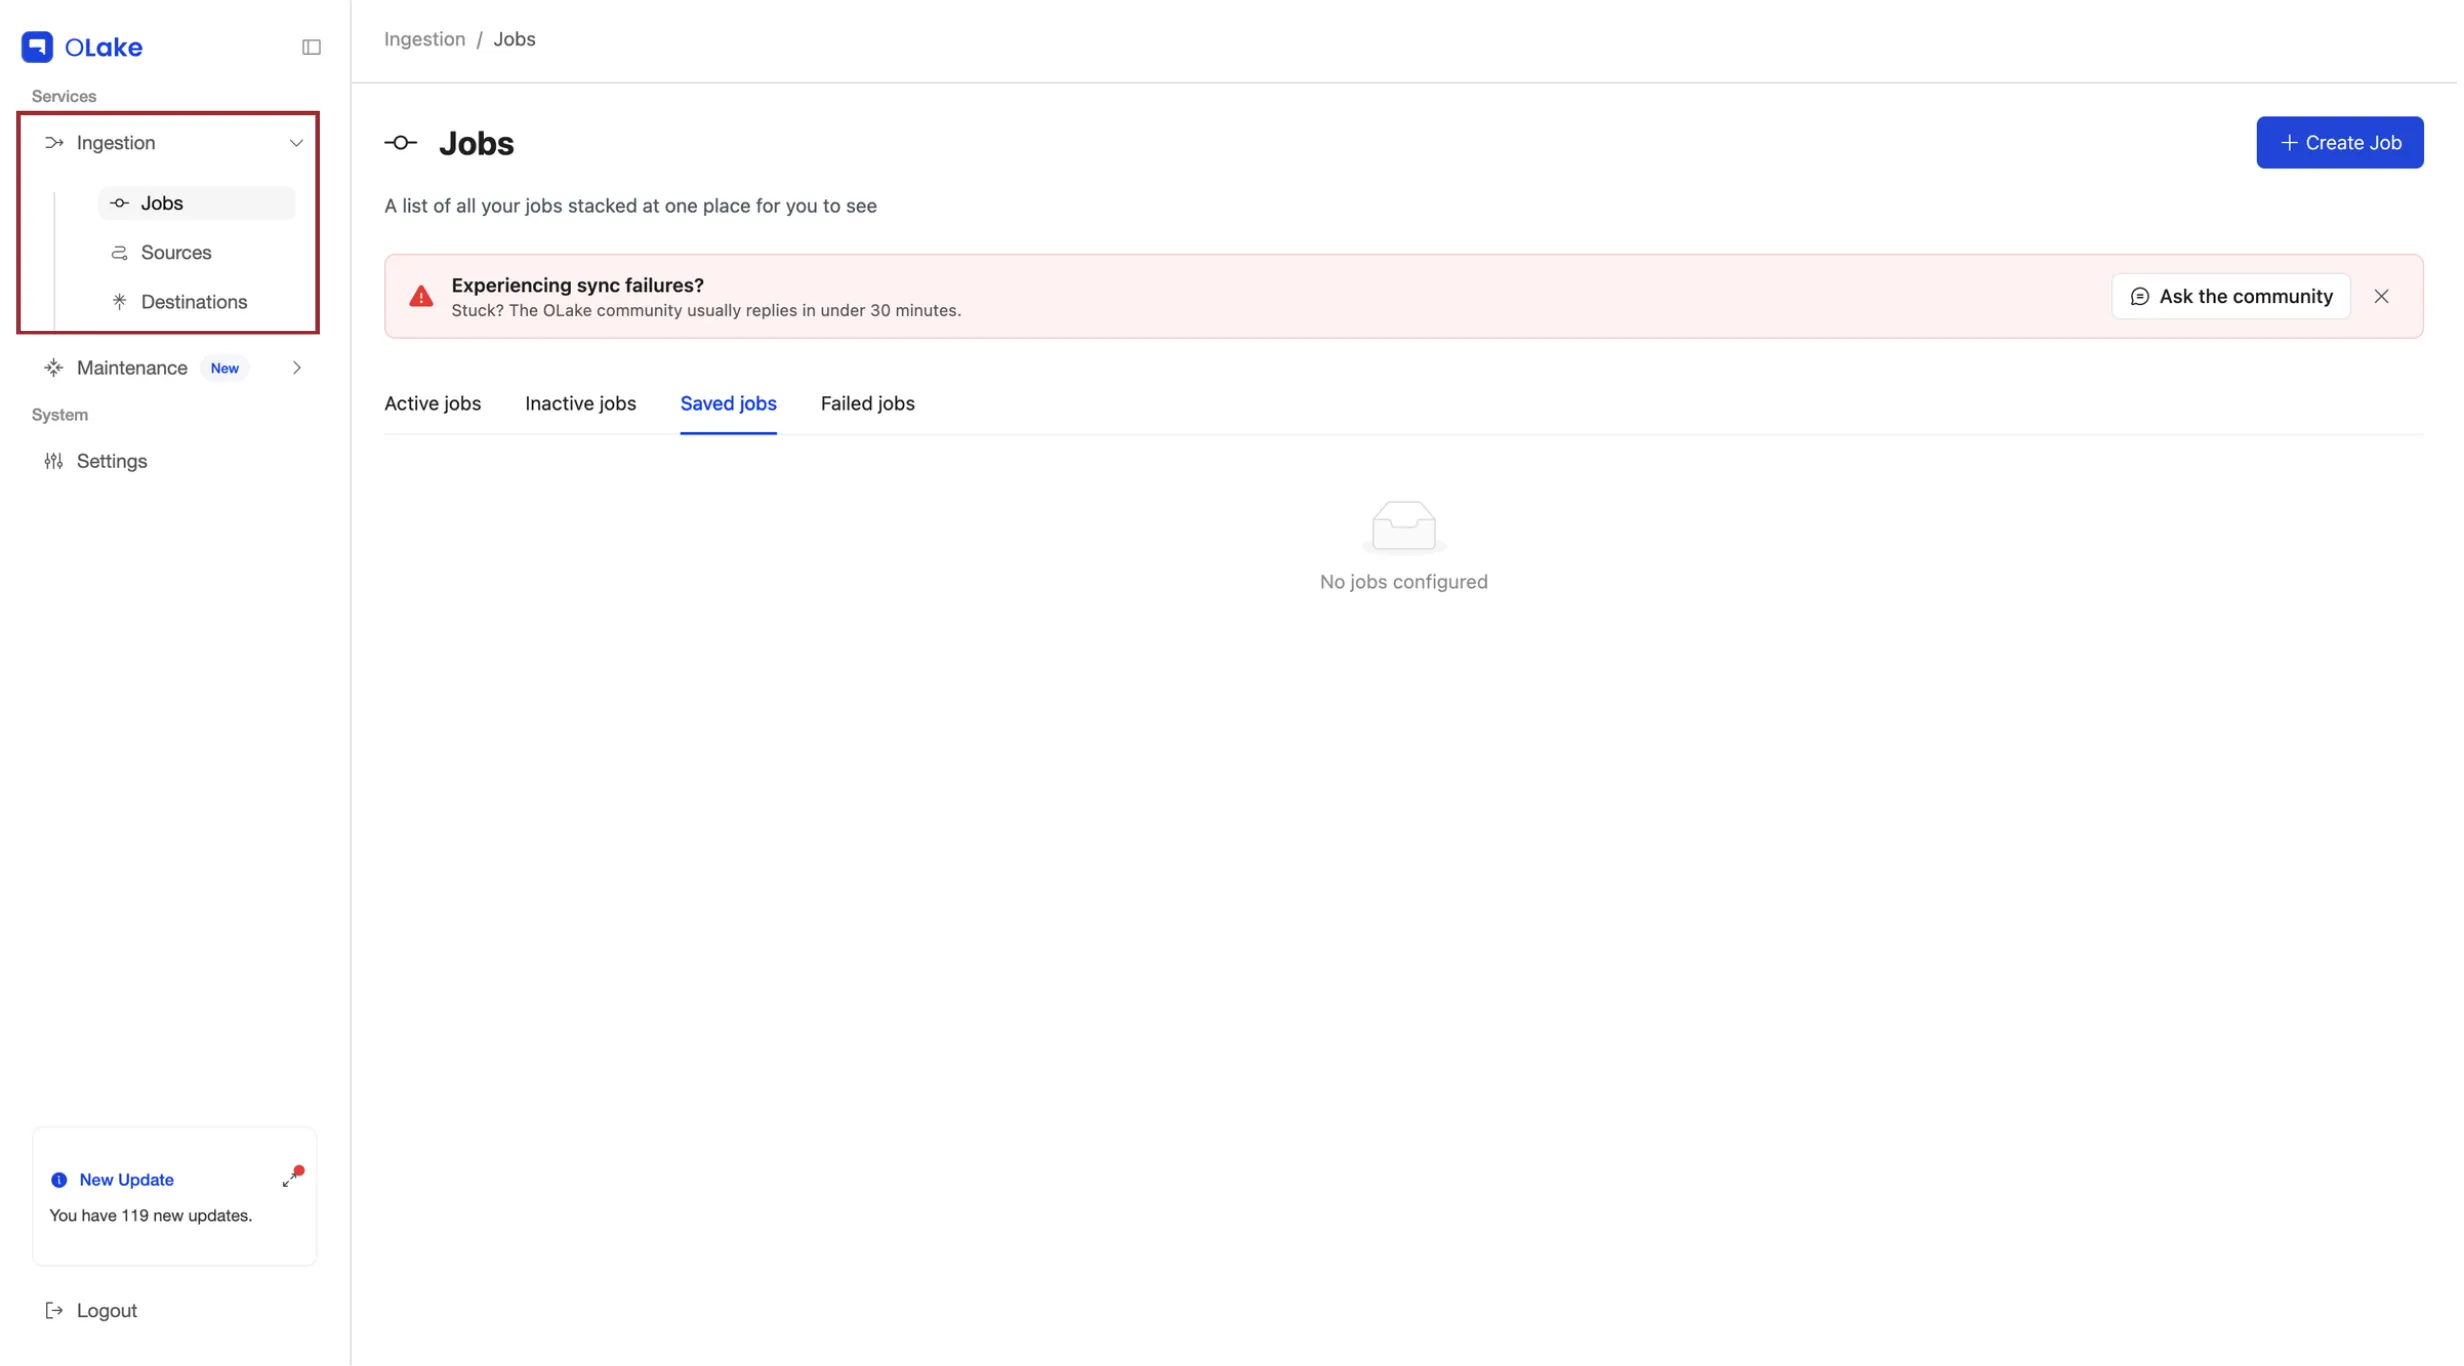
In the left menu, go to Ingestion > Jobs.
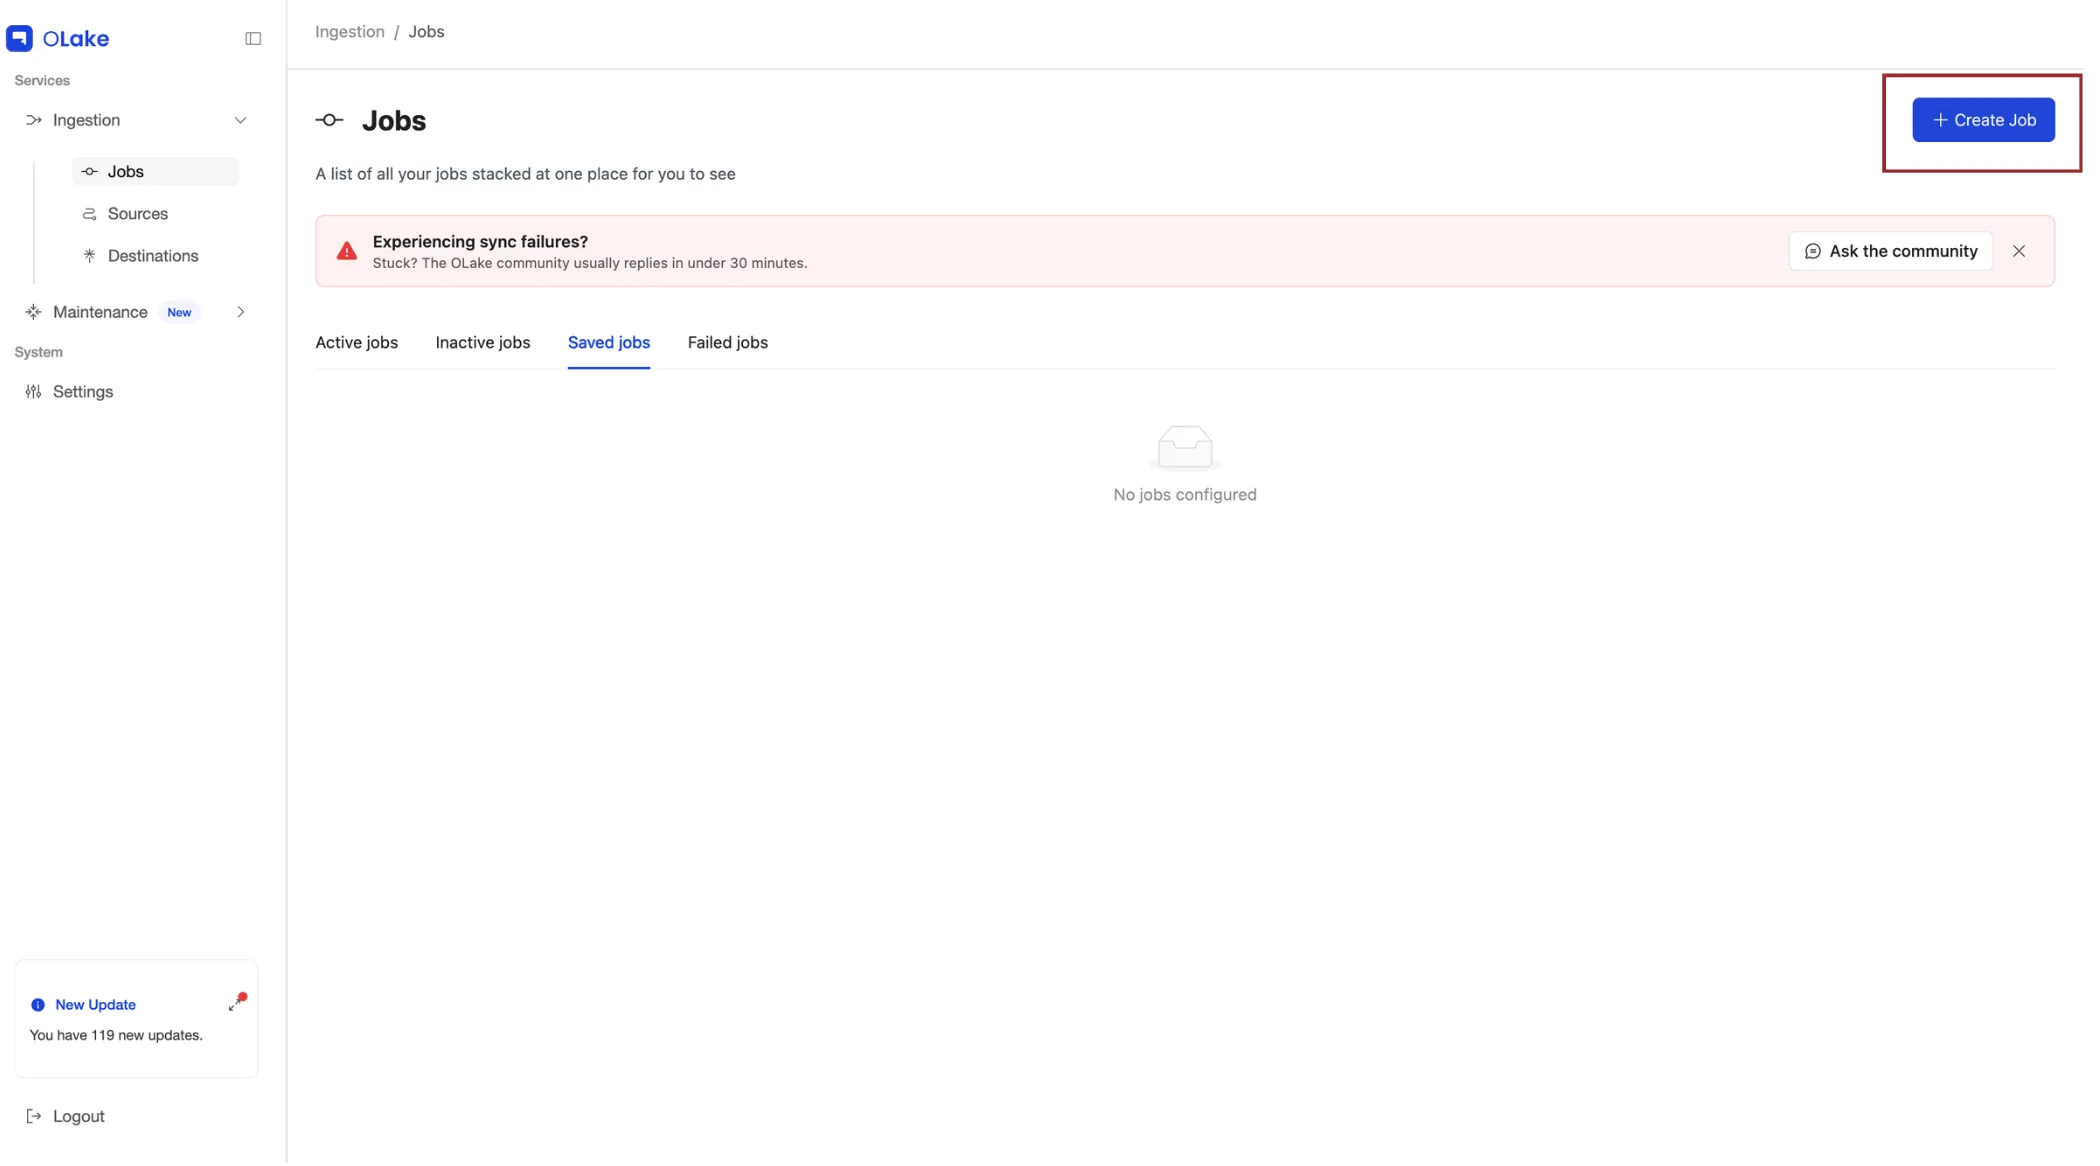
Click + Create Job at the top right.
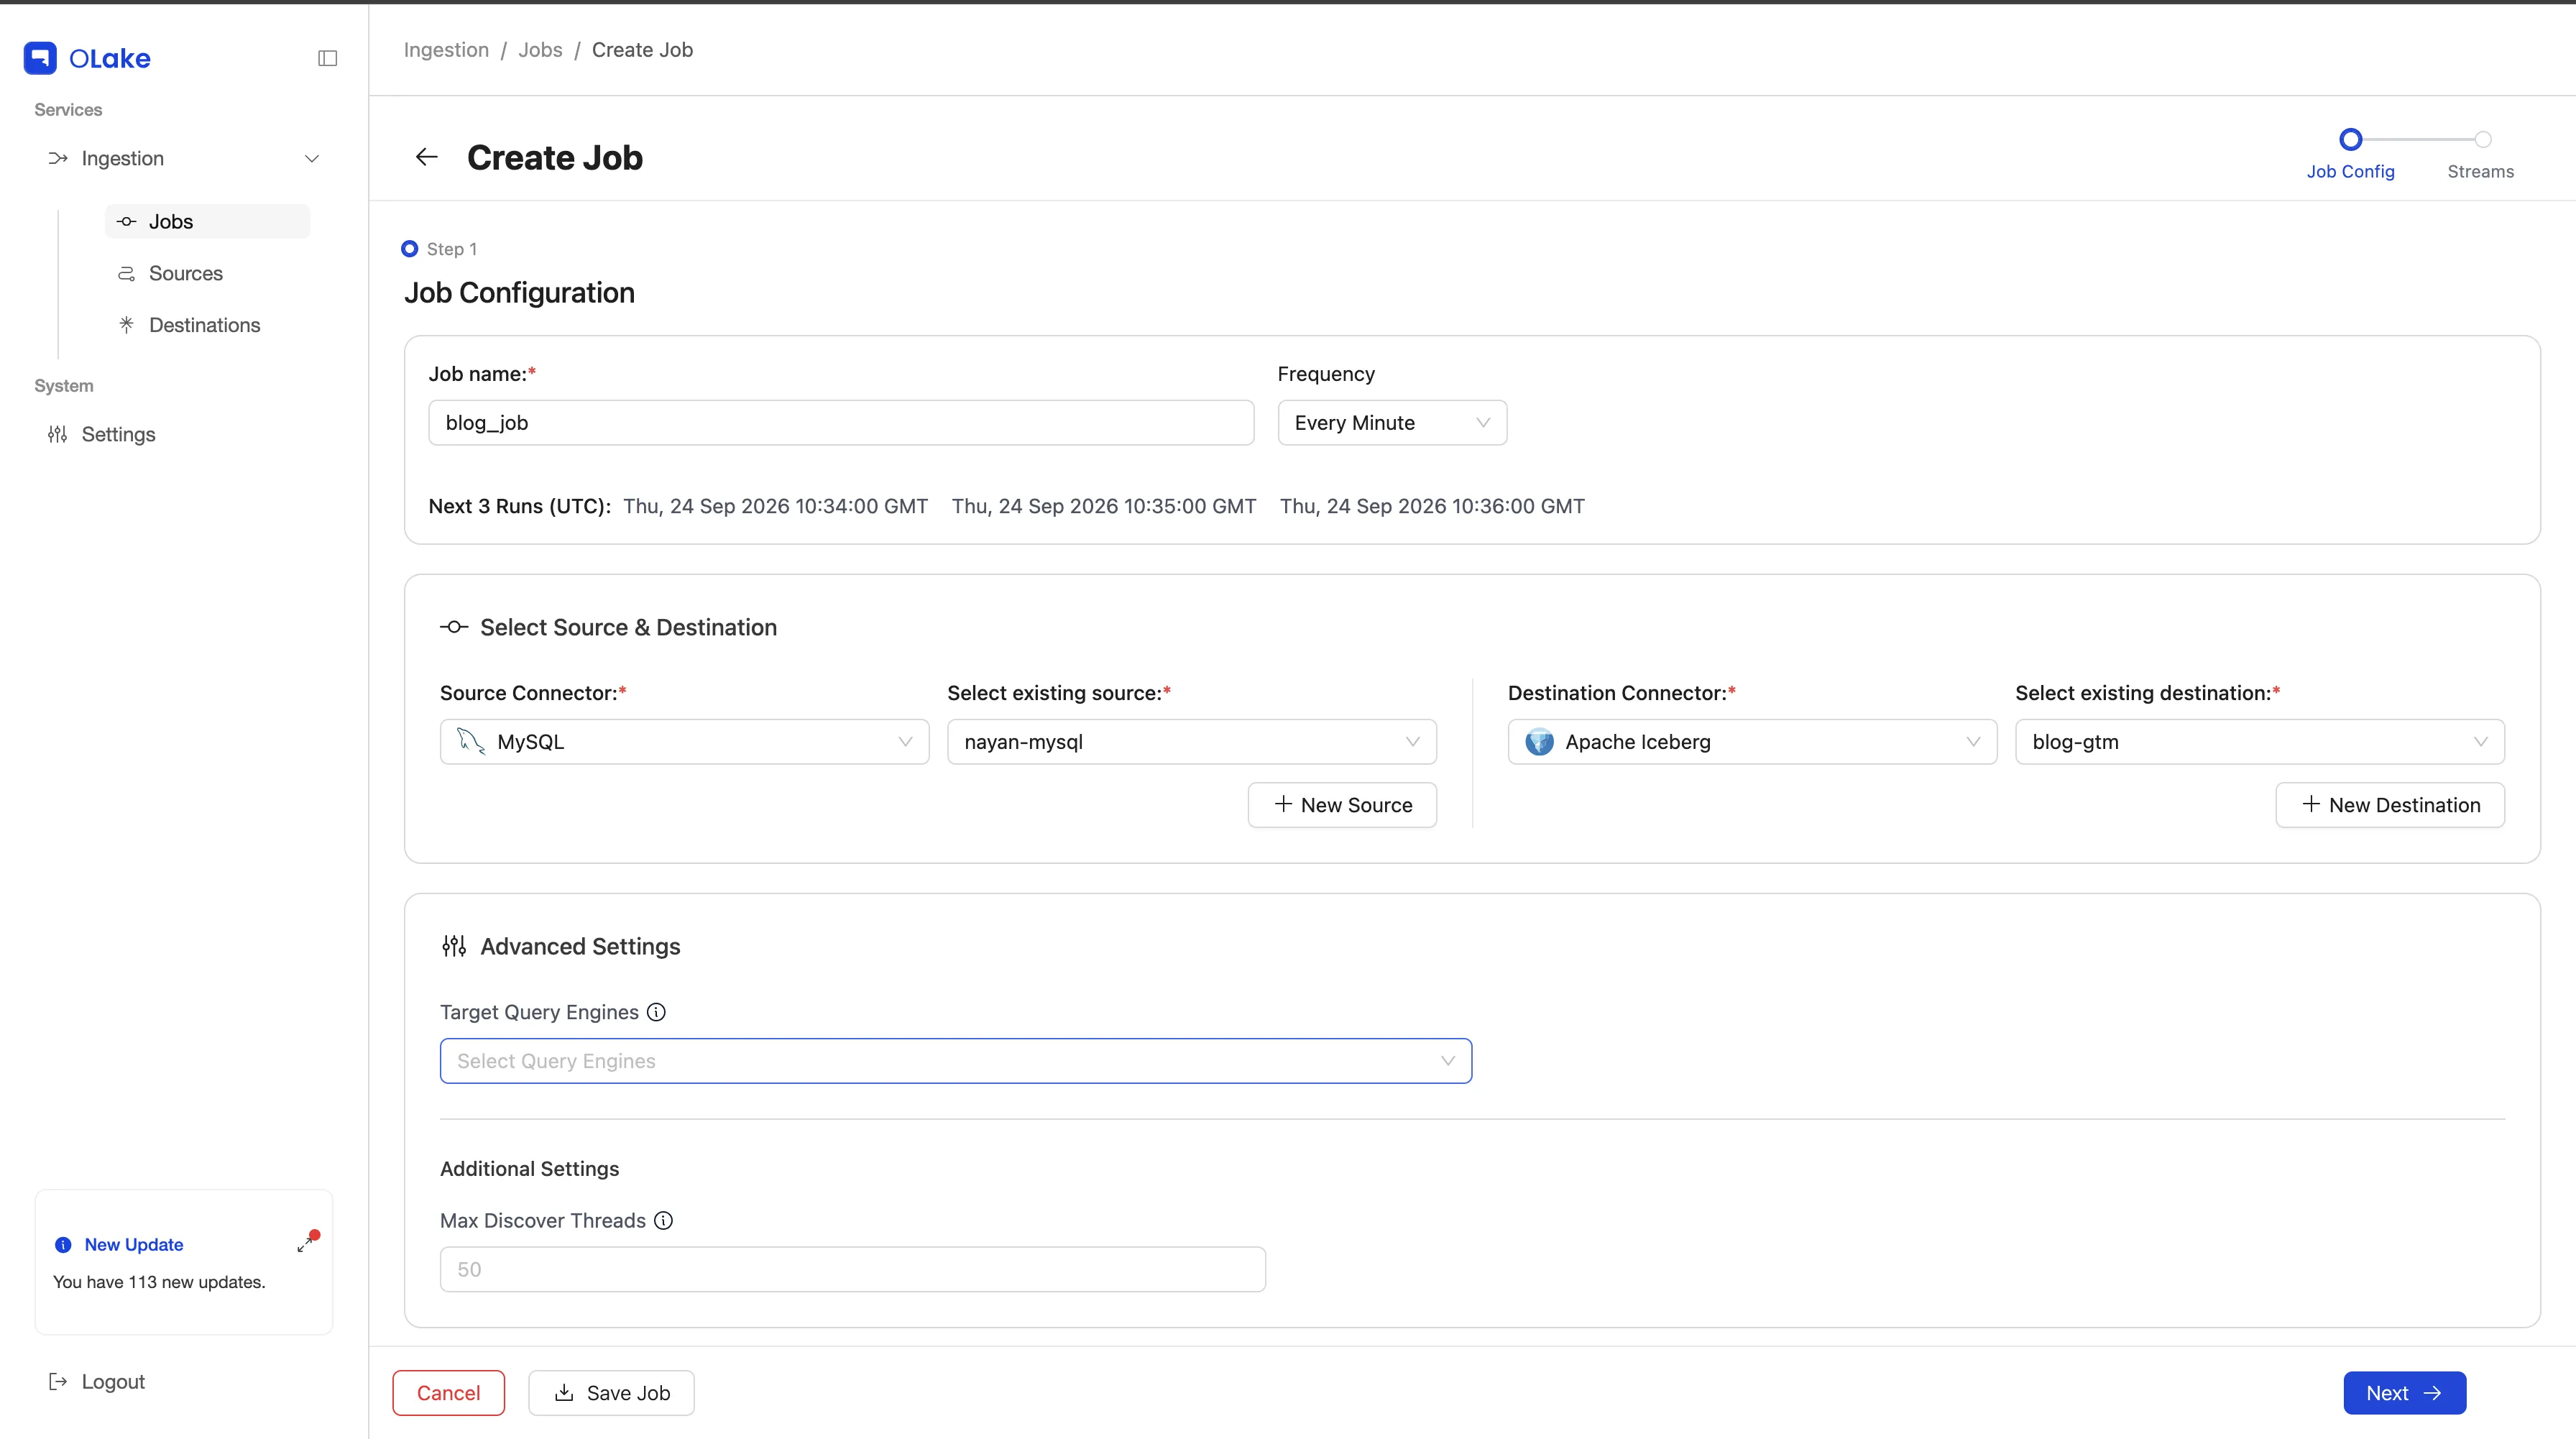
On the Job Configuration page, give your job a name (for example, blog_job) and choose how often it should run from the Frequency dropdown. Then pick MySQL as the source connector and select the source you created in Step 1, and do the same for the Iceberg destination.
Step 2a: Select Query Engine
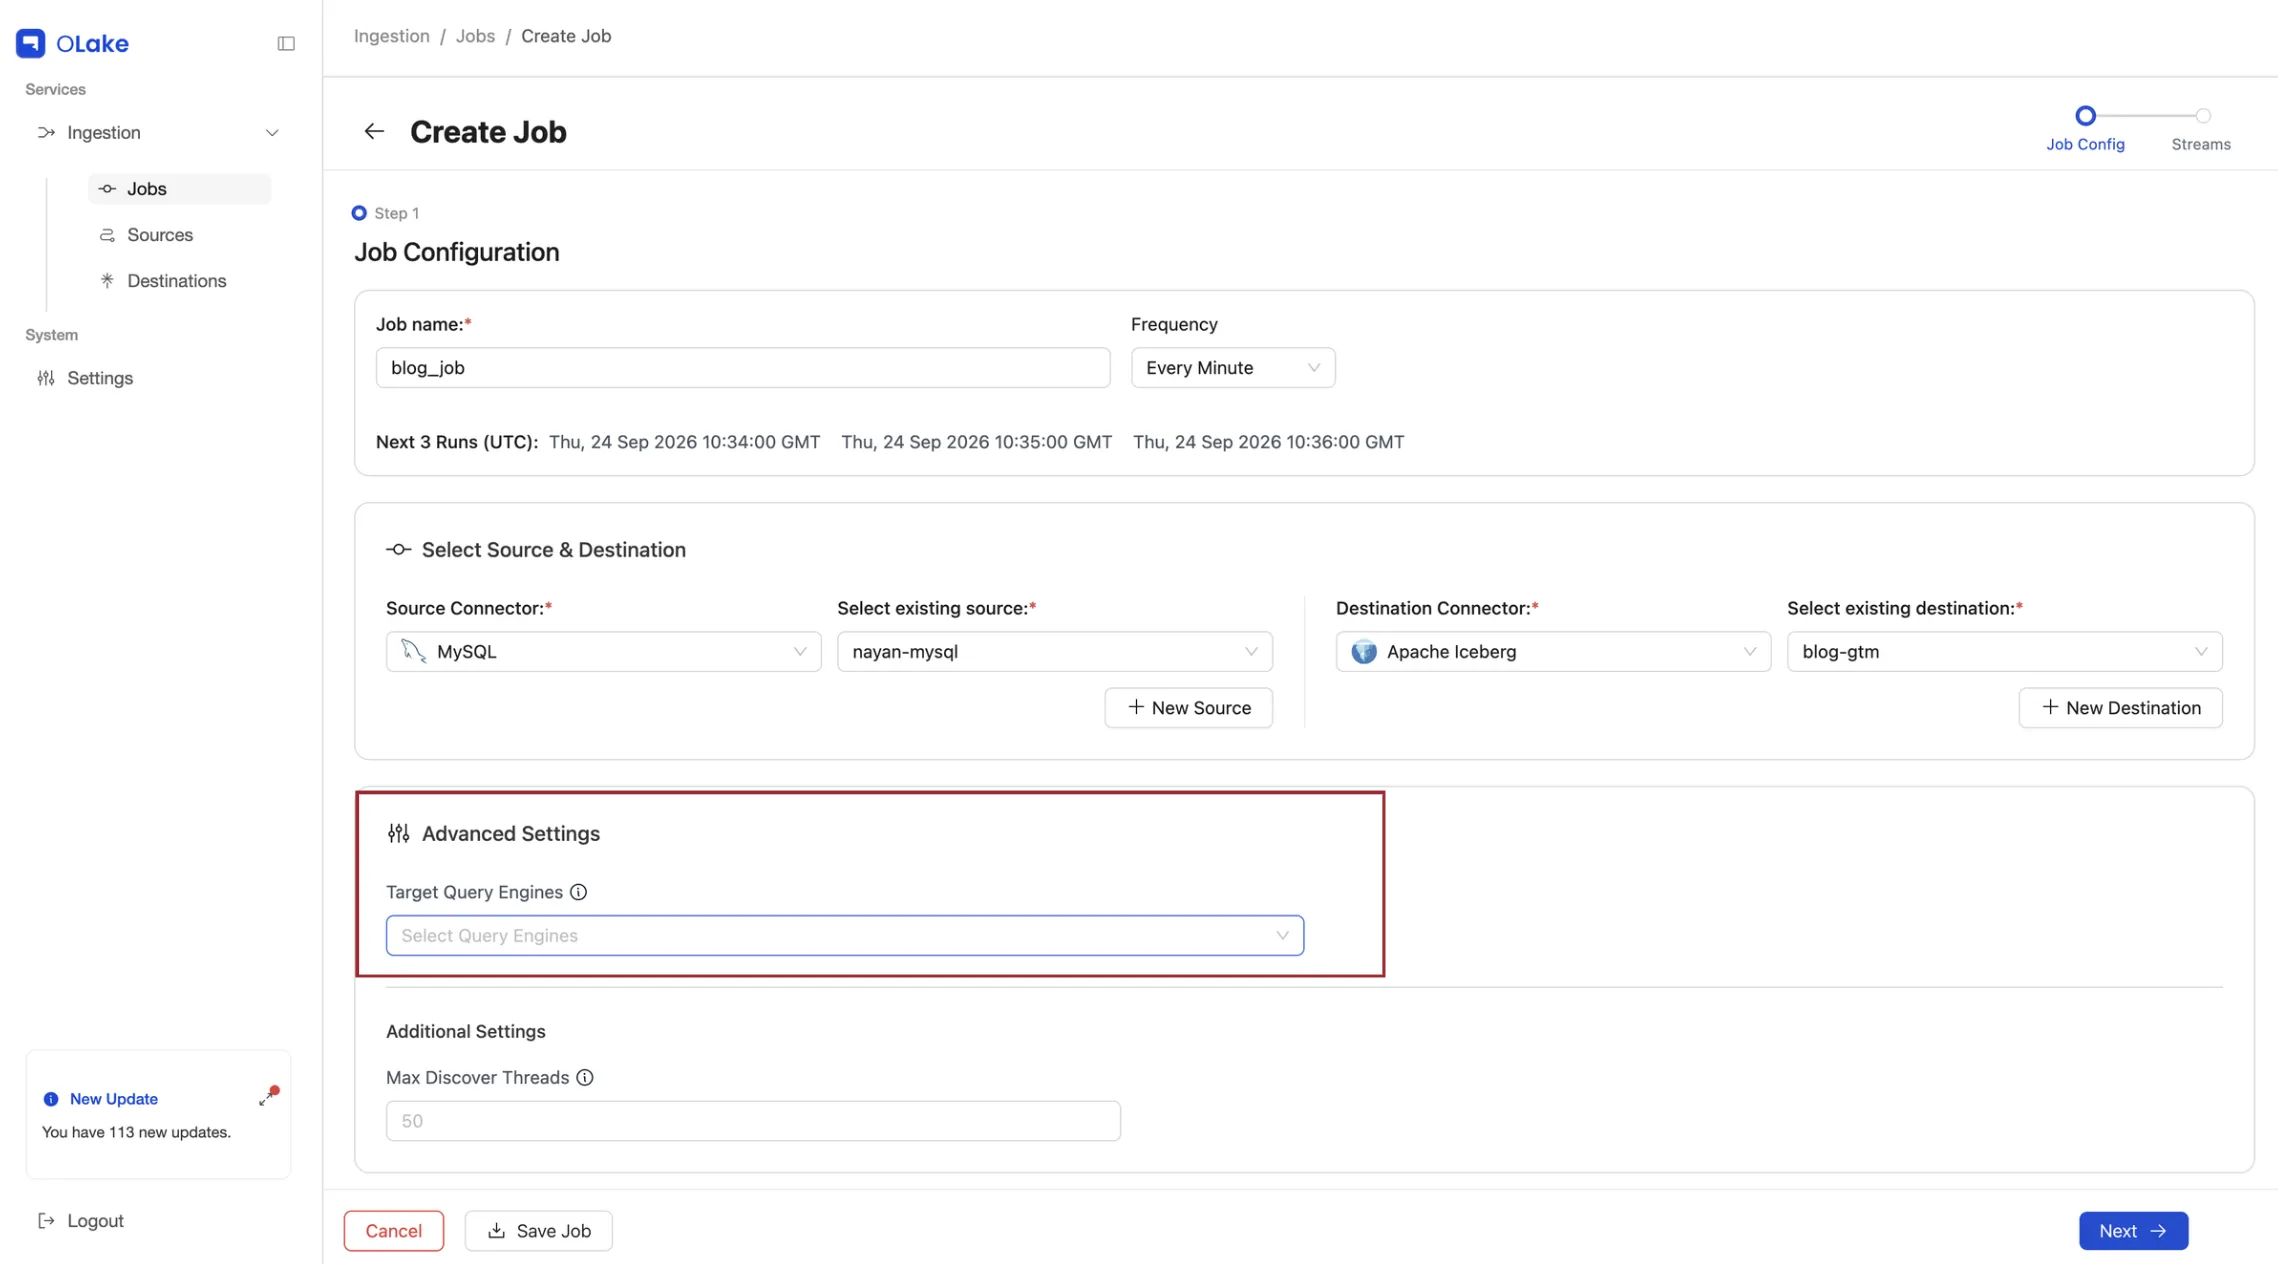
Under Advanced Settings, open the Target Query Engines dropdown and select Apache Spark. You can pick more than one engine, but this guide uses Spark only.
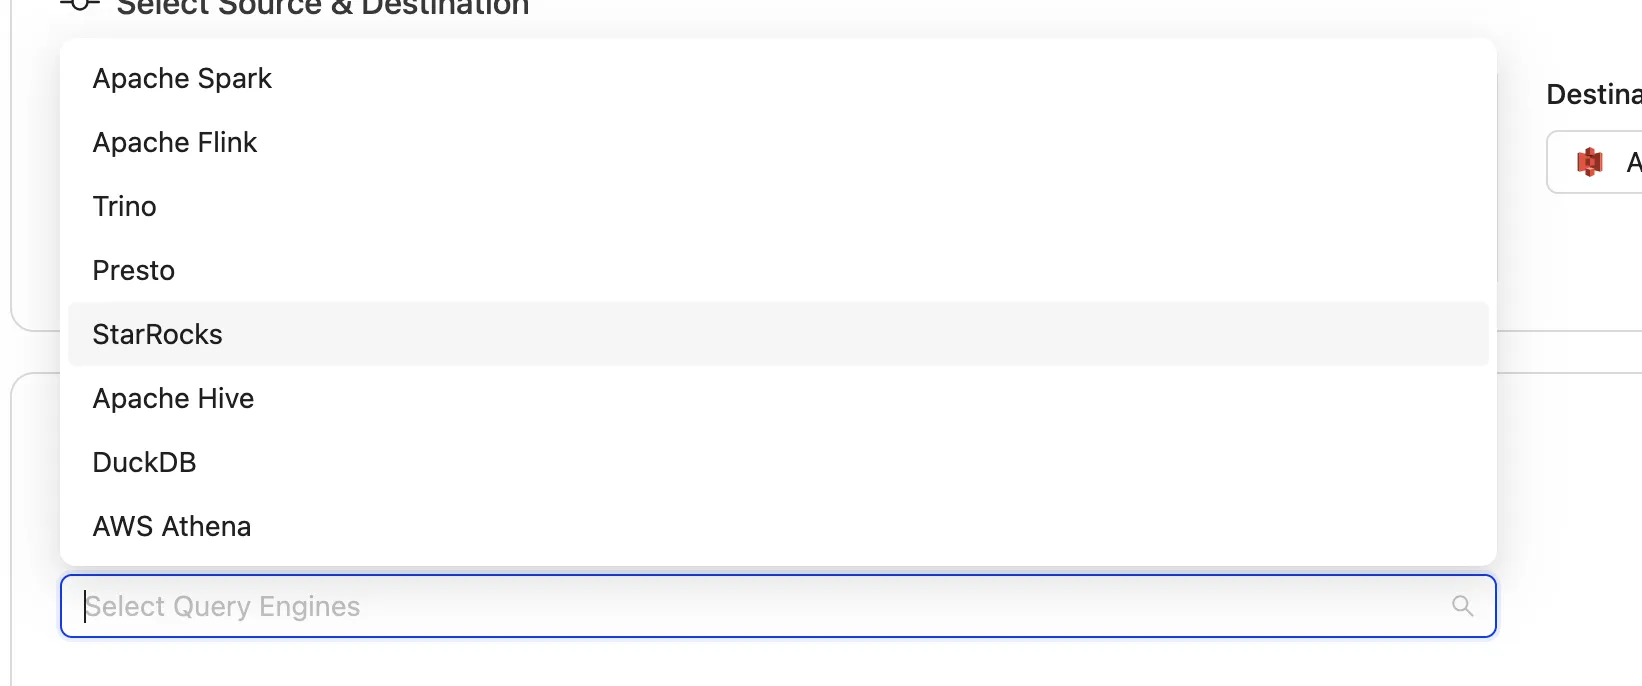
Click Next and you’ll be redirected to the Stream configuration page.
Step 3: Configure Streams
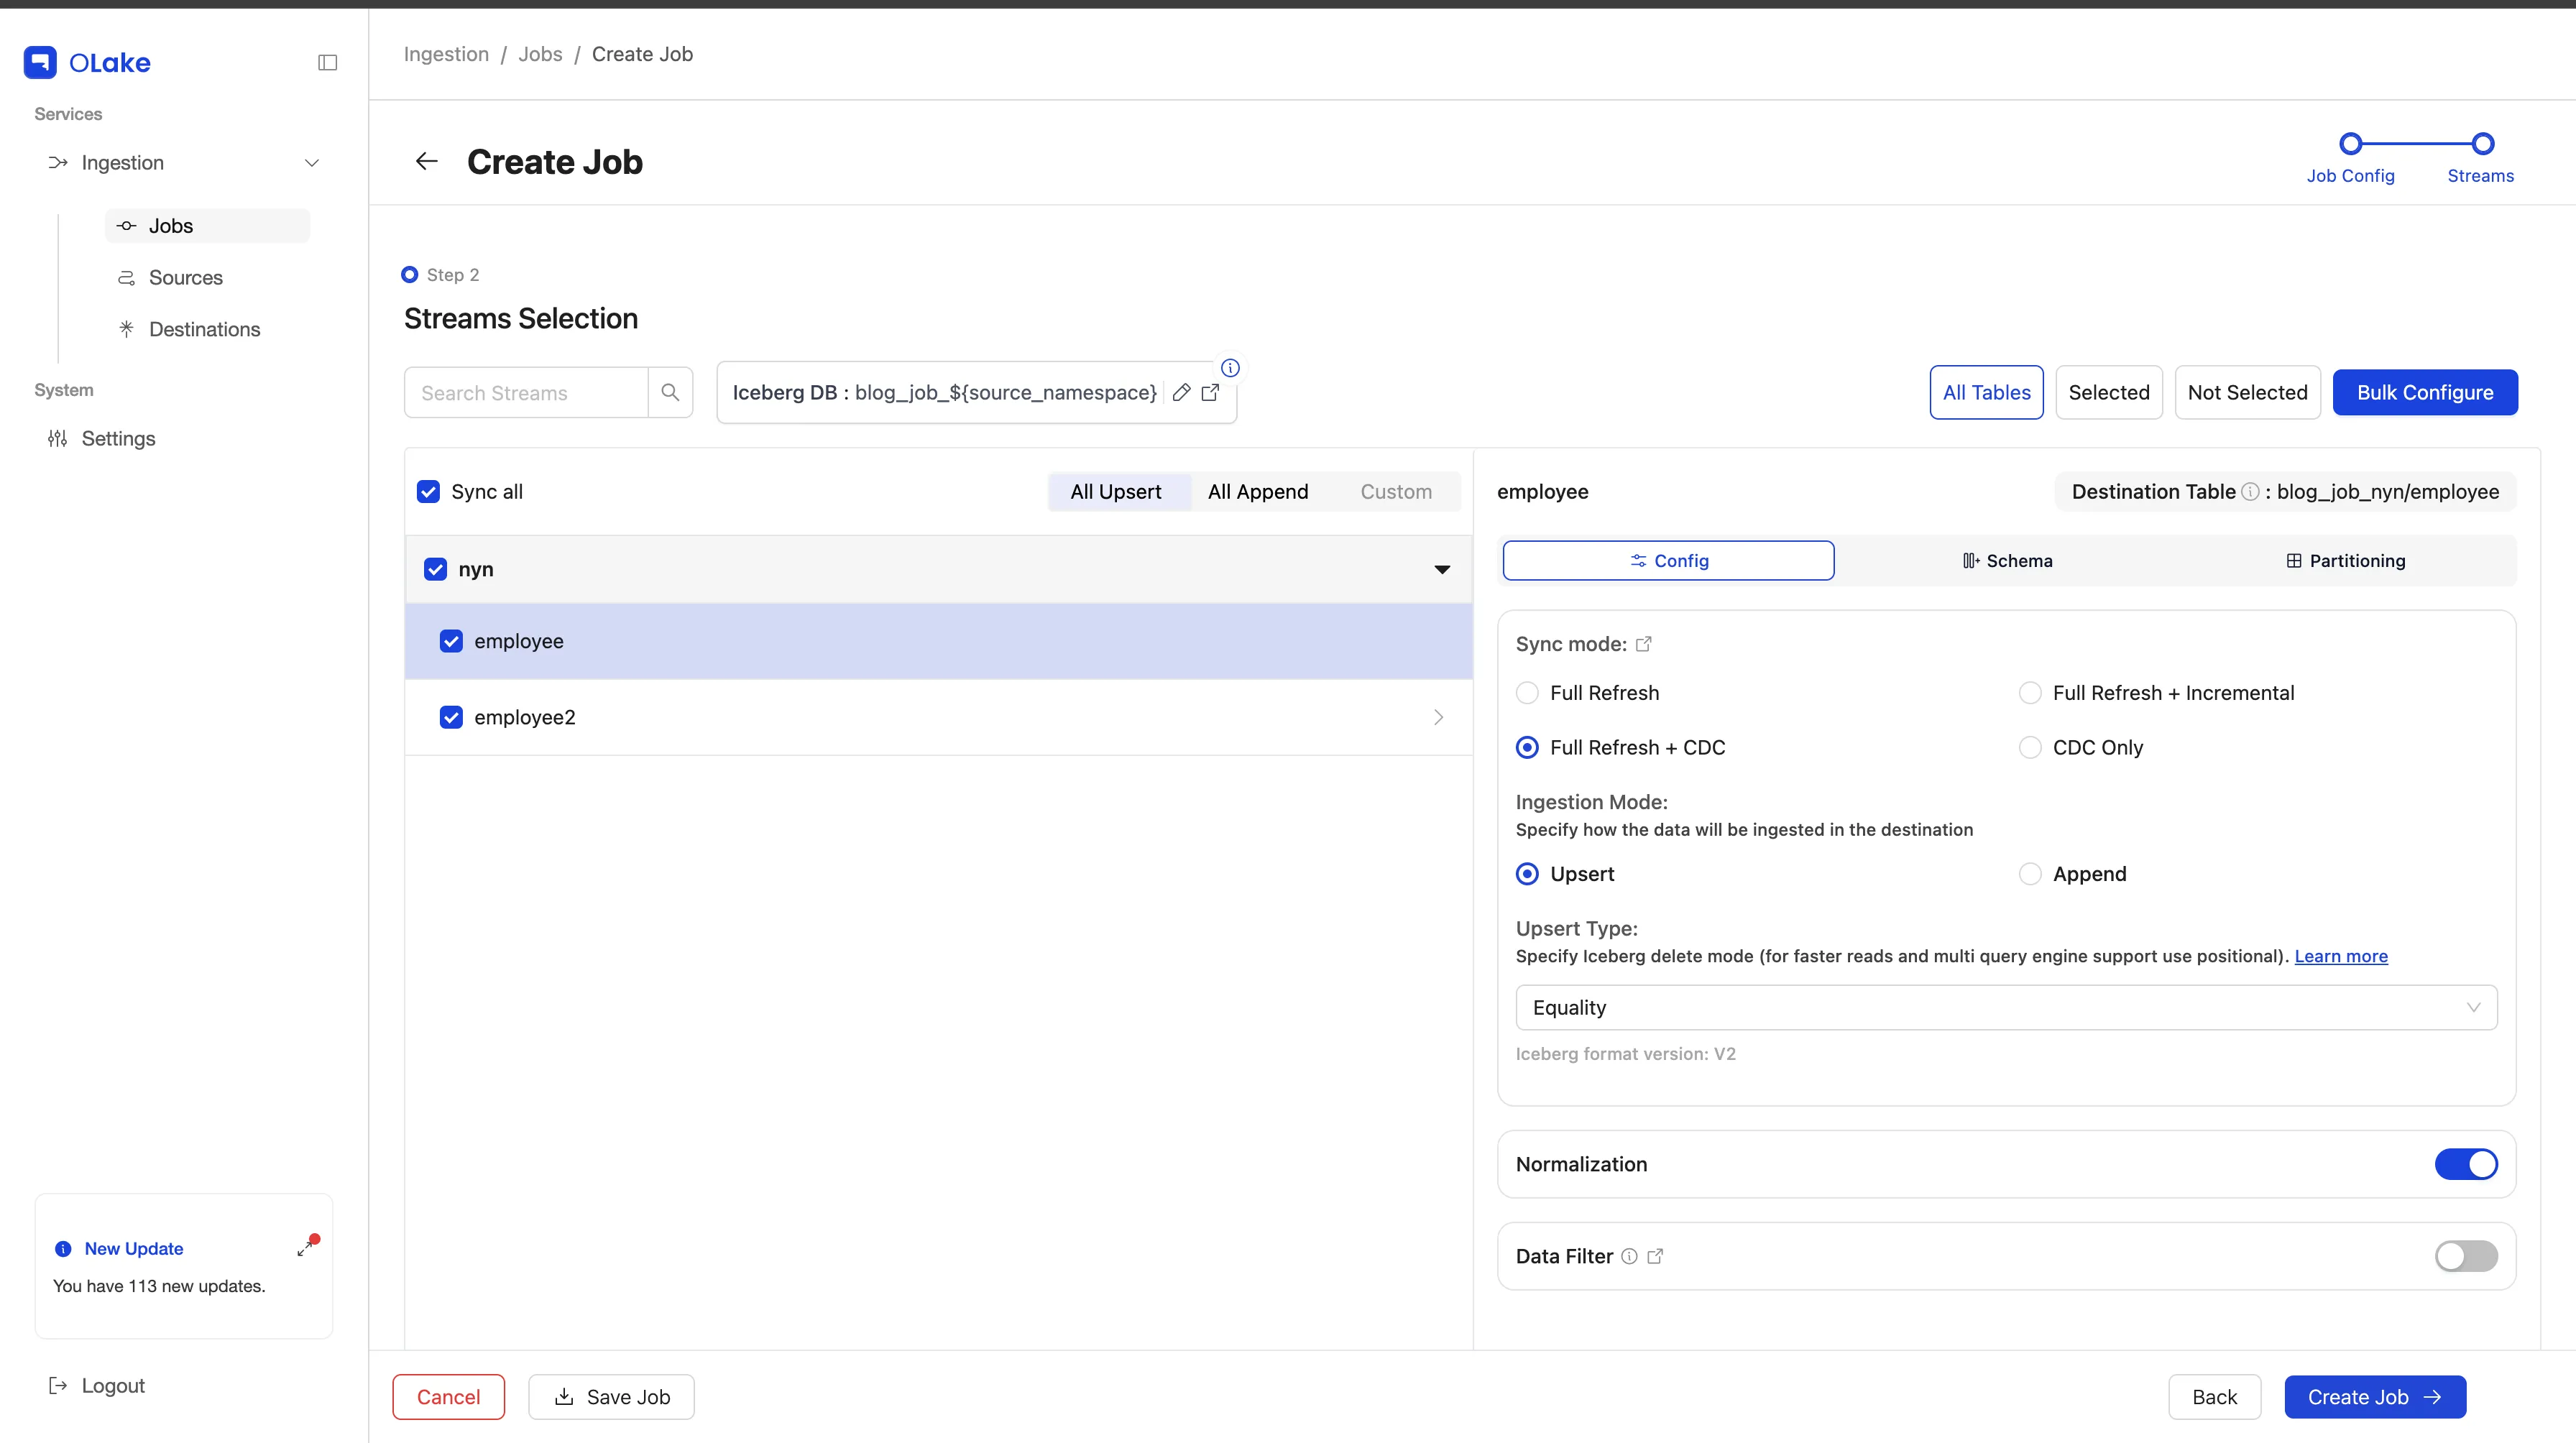
The Streams page lists every table in your MySQL database. Check the box next to each table you want to copy, or use Sync all to select everything. The Iceberg DB field at the top shows the database name your tables will land in, and you can click the edit icon to change it.
Click a table name to open its settings on the right. On the Config tab, you can:
- Pick a sync mode. Full Refresh + CDC copies all current rows first and then keeps copying new changes
- Choose an Ingestion Mode. Upsert updates existing rows when they change, while Append adds every change as a new row
- Turn on Normalization to store nested data as regular columns
The Schema tab shows the table's columns, and the Partitioning tab lets you group data by a column so queries run faster.
Step 3a: Specify Iceberg Delete Mode
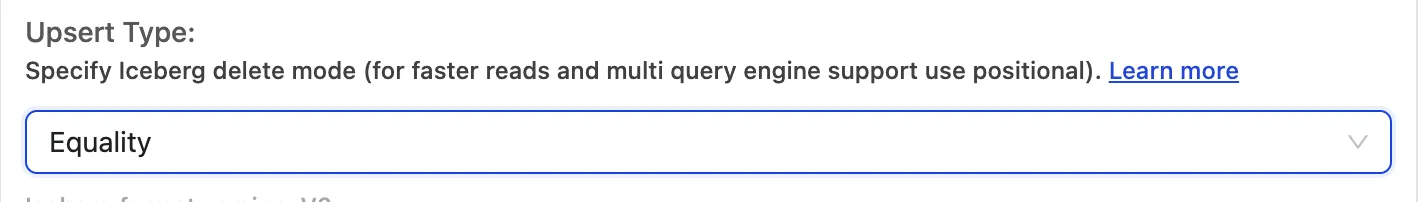
When the ingestion mode is Upsert, you can choose which type of delete file OLake Go writes to Iceberg.
Open the Upsert Type dropdown and select the delete type you want: Equality, Positional, or Deletion.
When you're done, click Create Job at the bottom right. A confirmation shows that your job was created, and clicking Jobs takes you back to the main Jobs page.
Step 4: Run the Sync
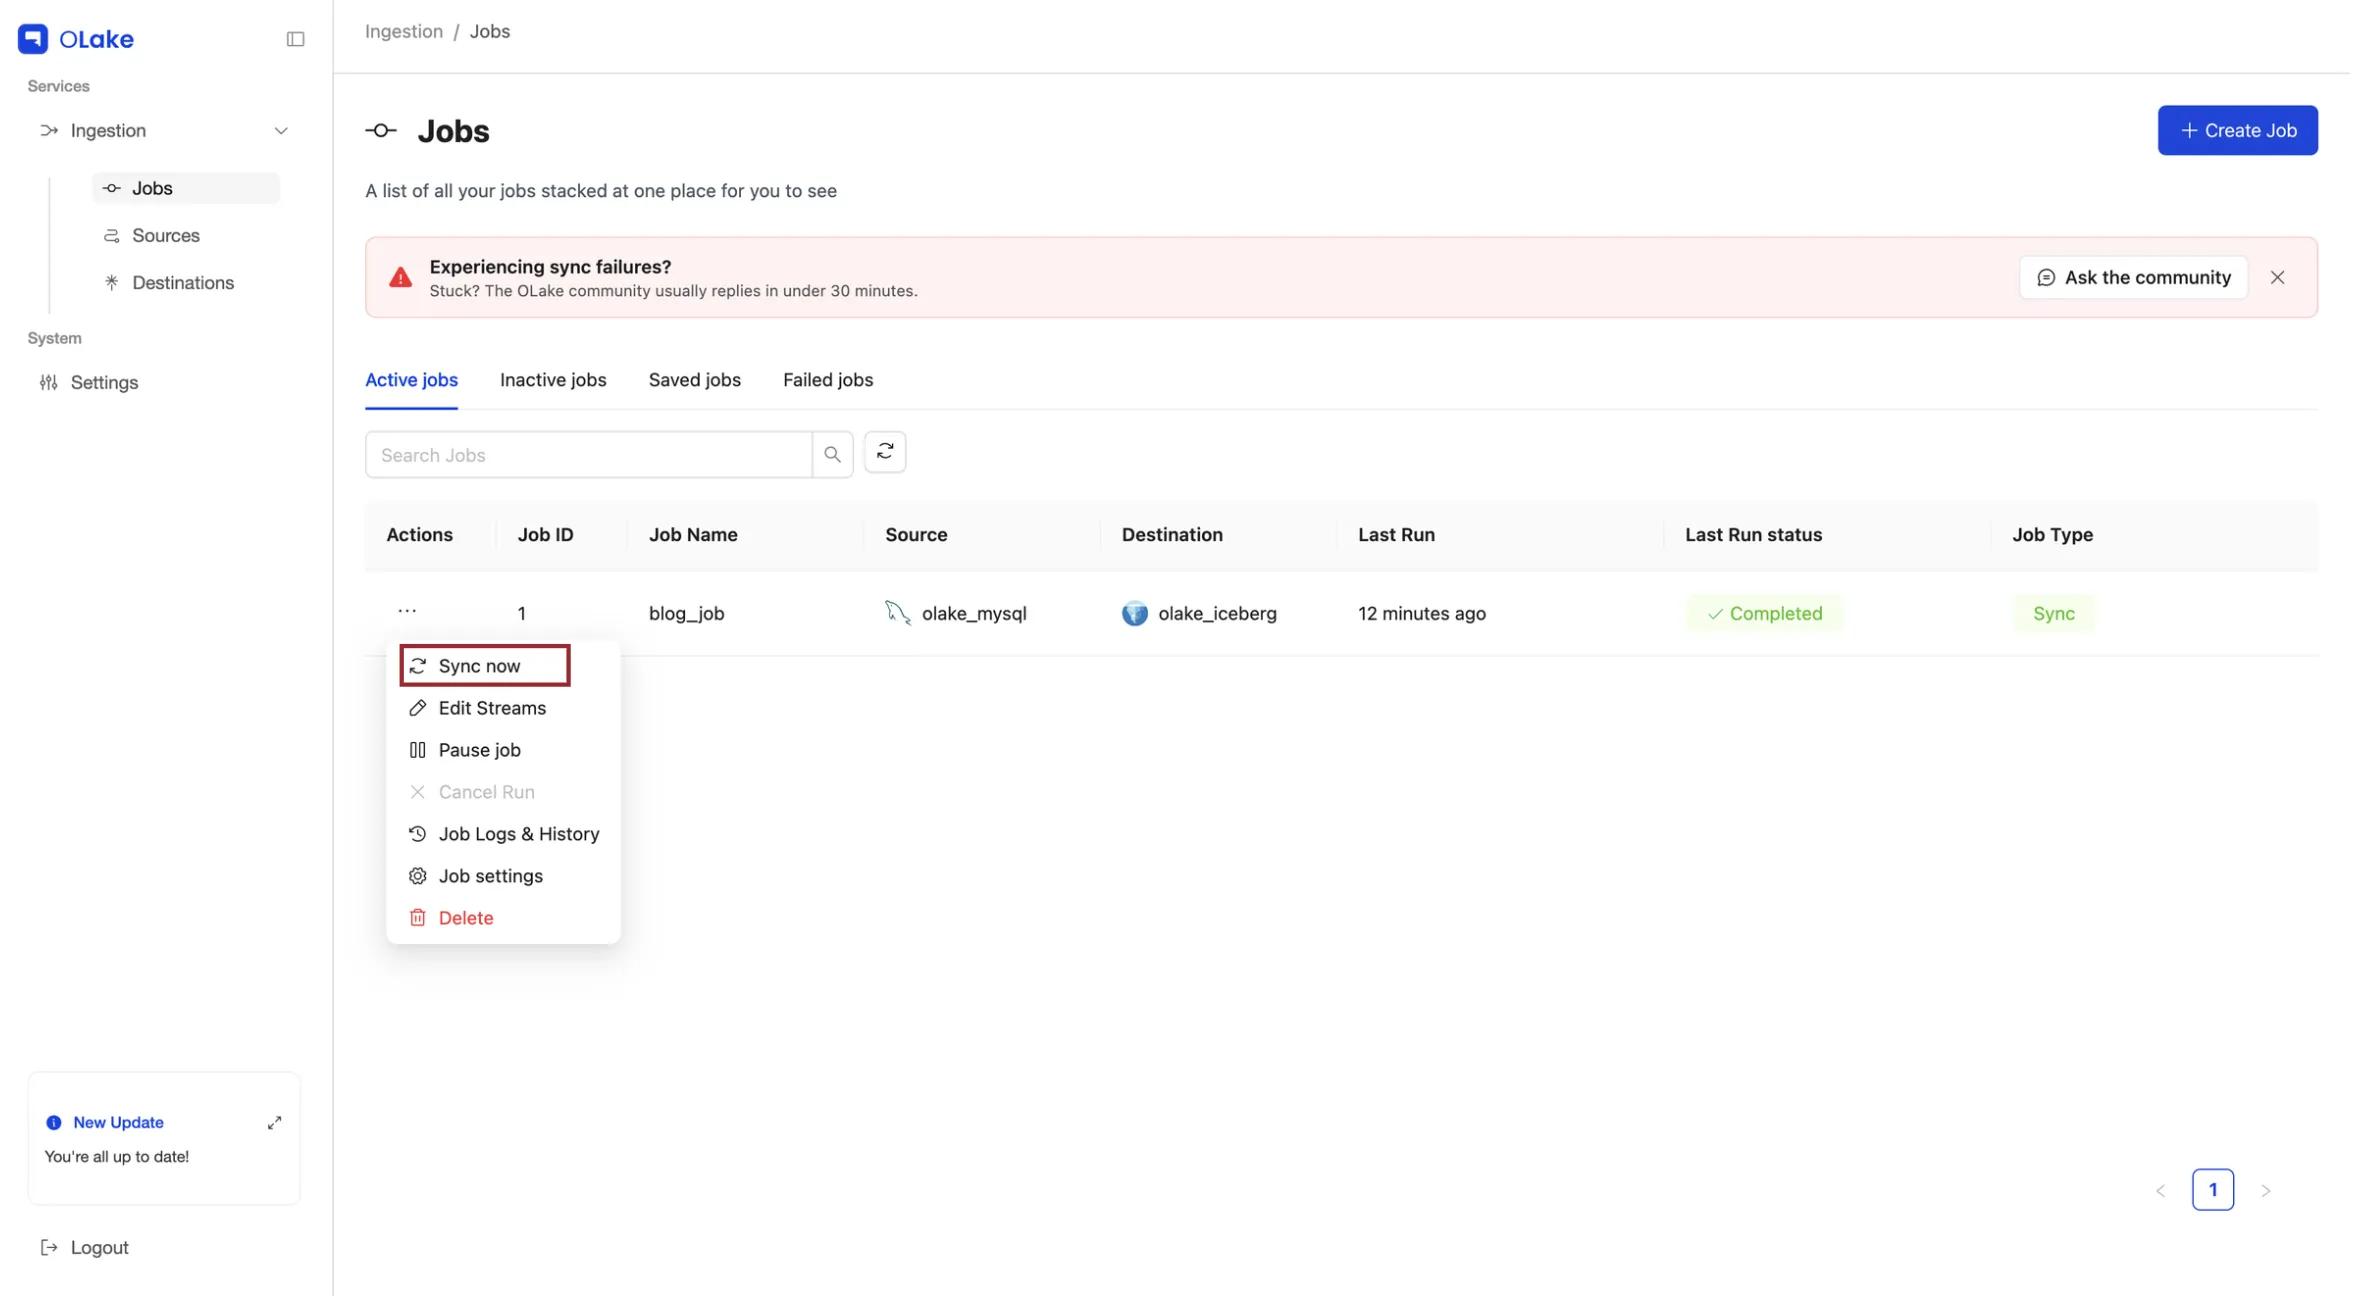
Your new job appears in the Active jobs tab. The Last Run status column shows whether each run is Running, Completed, or Failed.
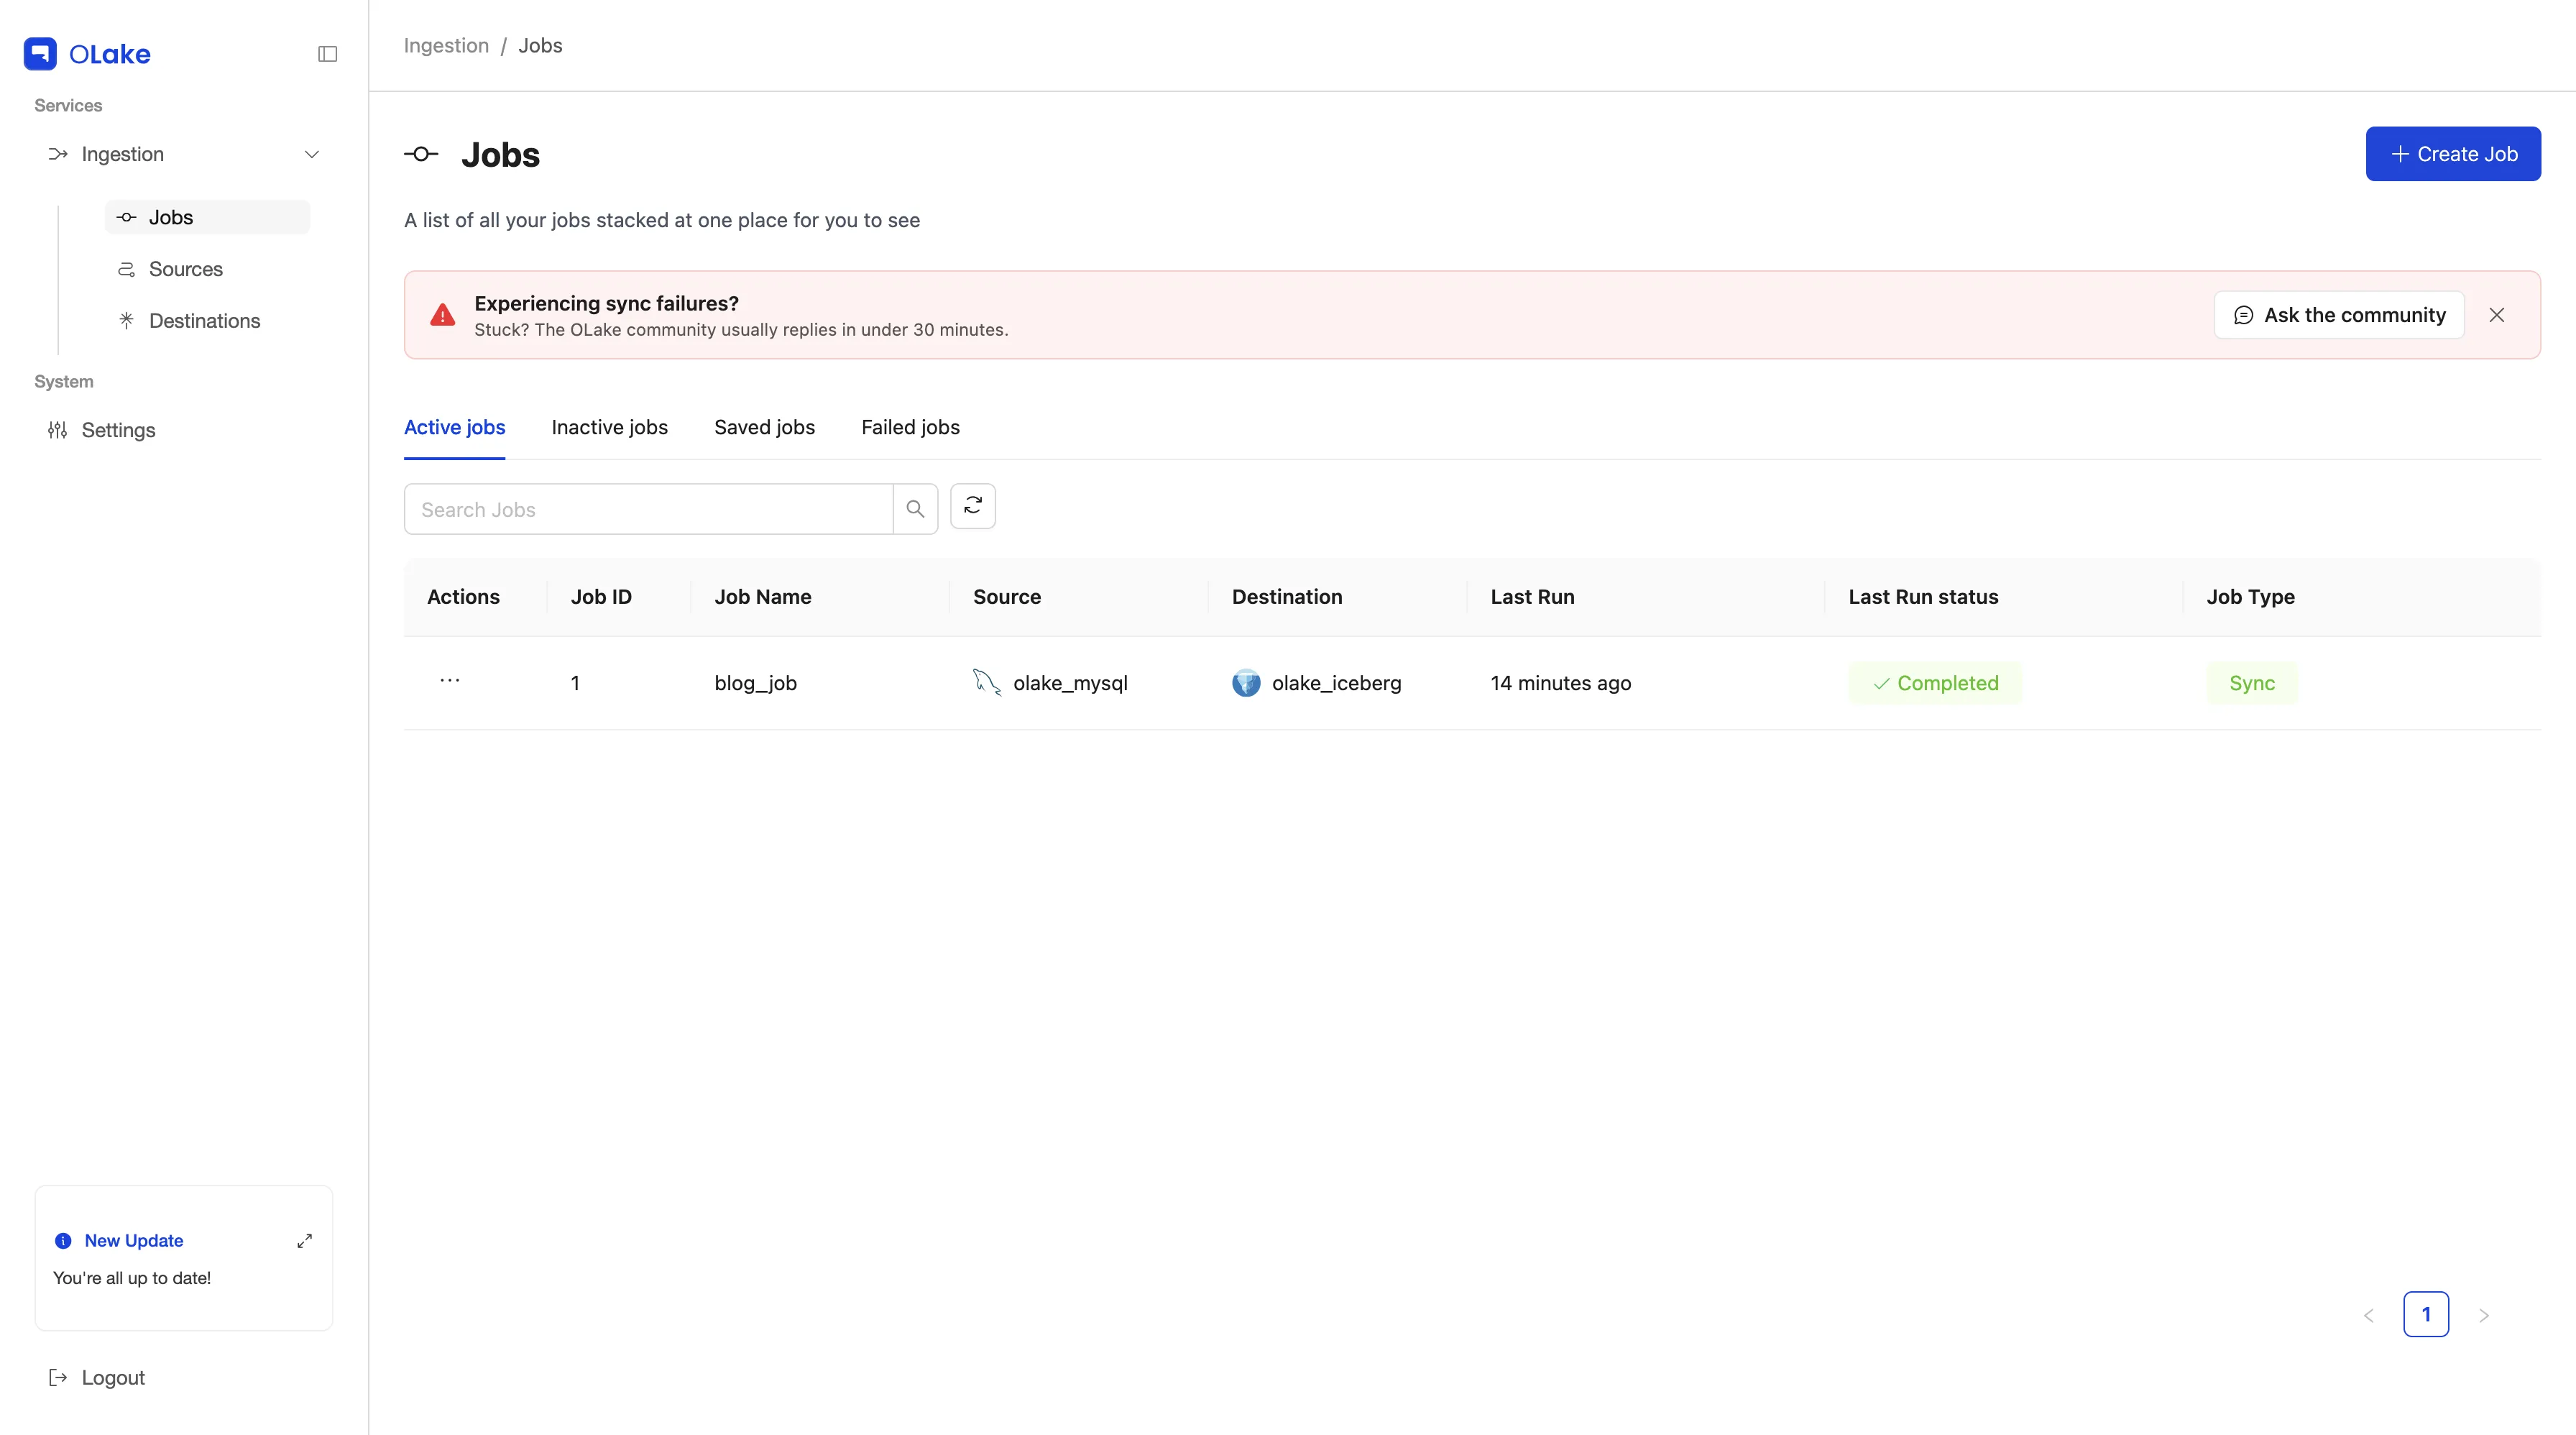
The job will run at its next scheduled time. To start it now, click the three dots in the Actions column next to your job and select Sync now.
To see how each run went, under Actions, select Job Logs & History. This page lists every run with its start time, runtime, and status.
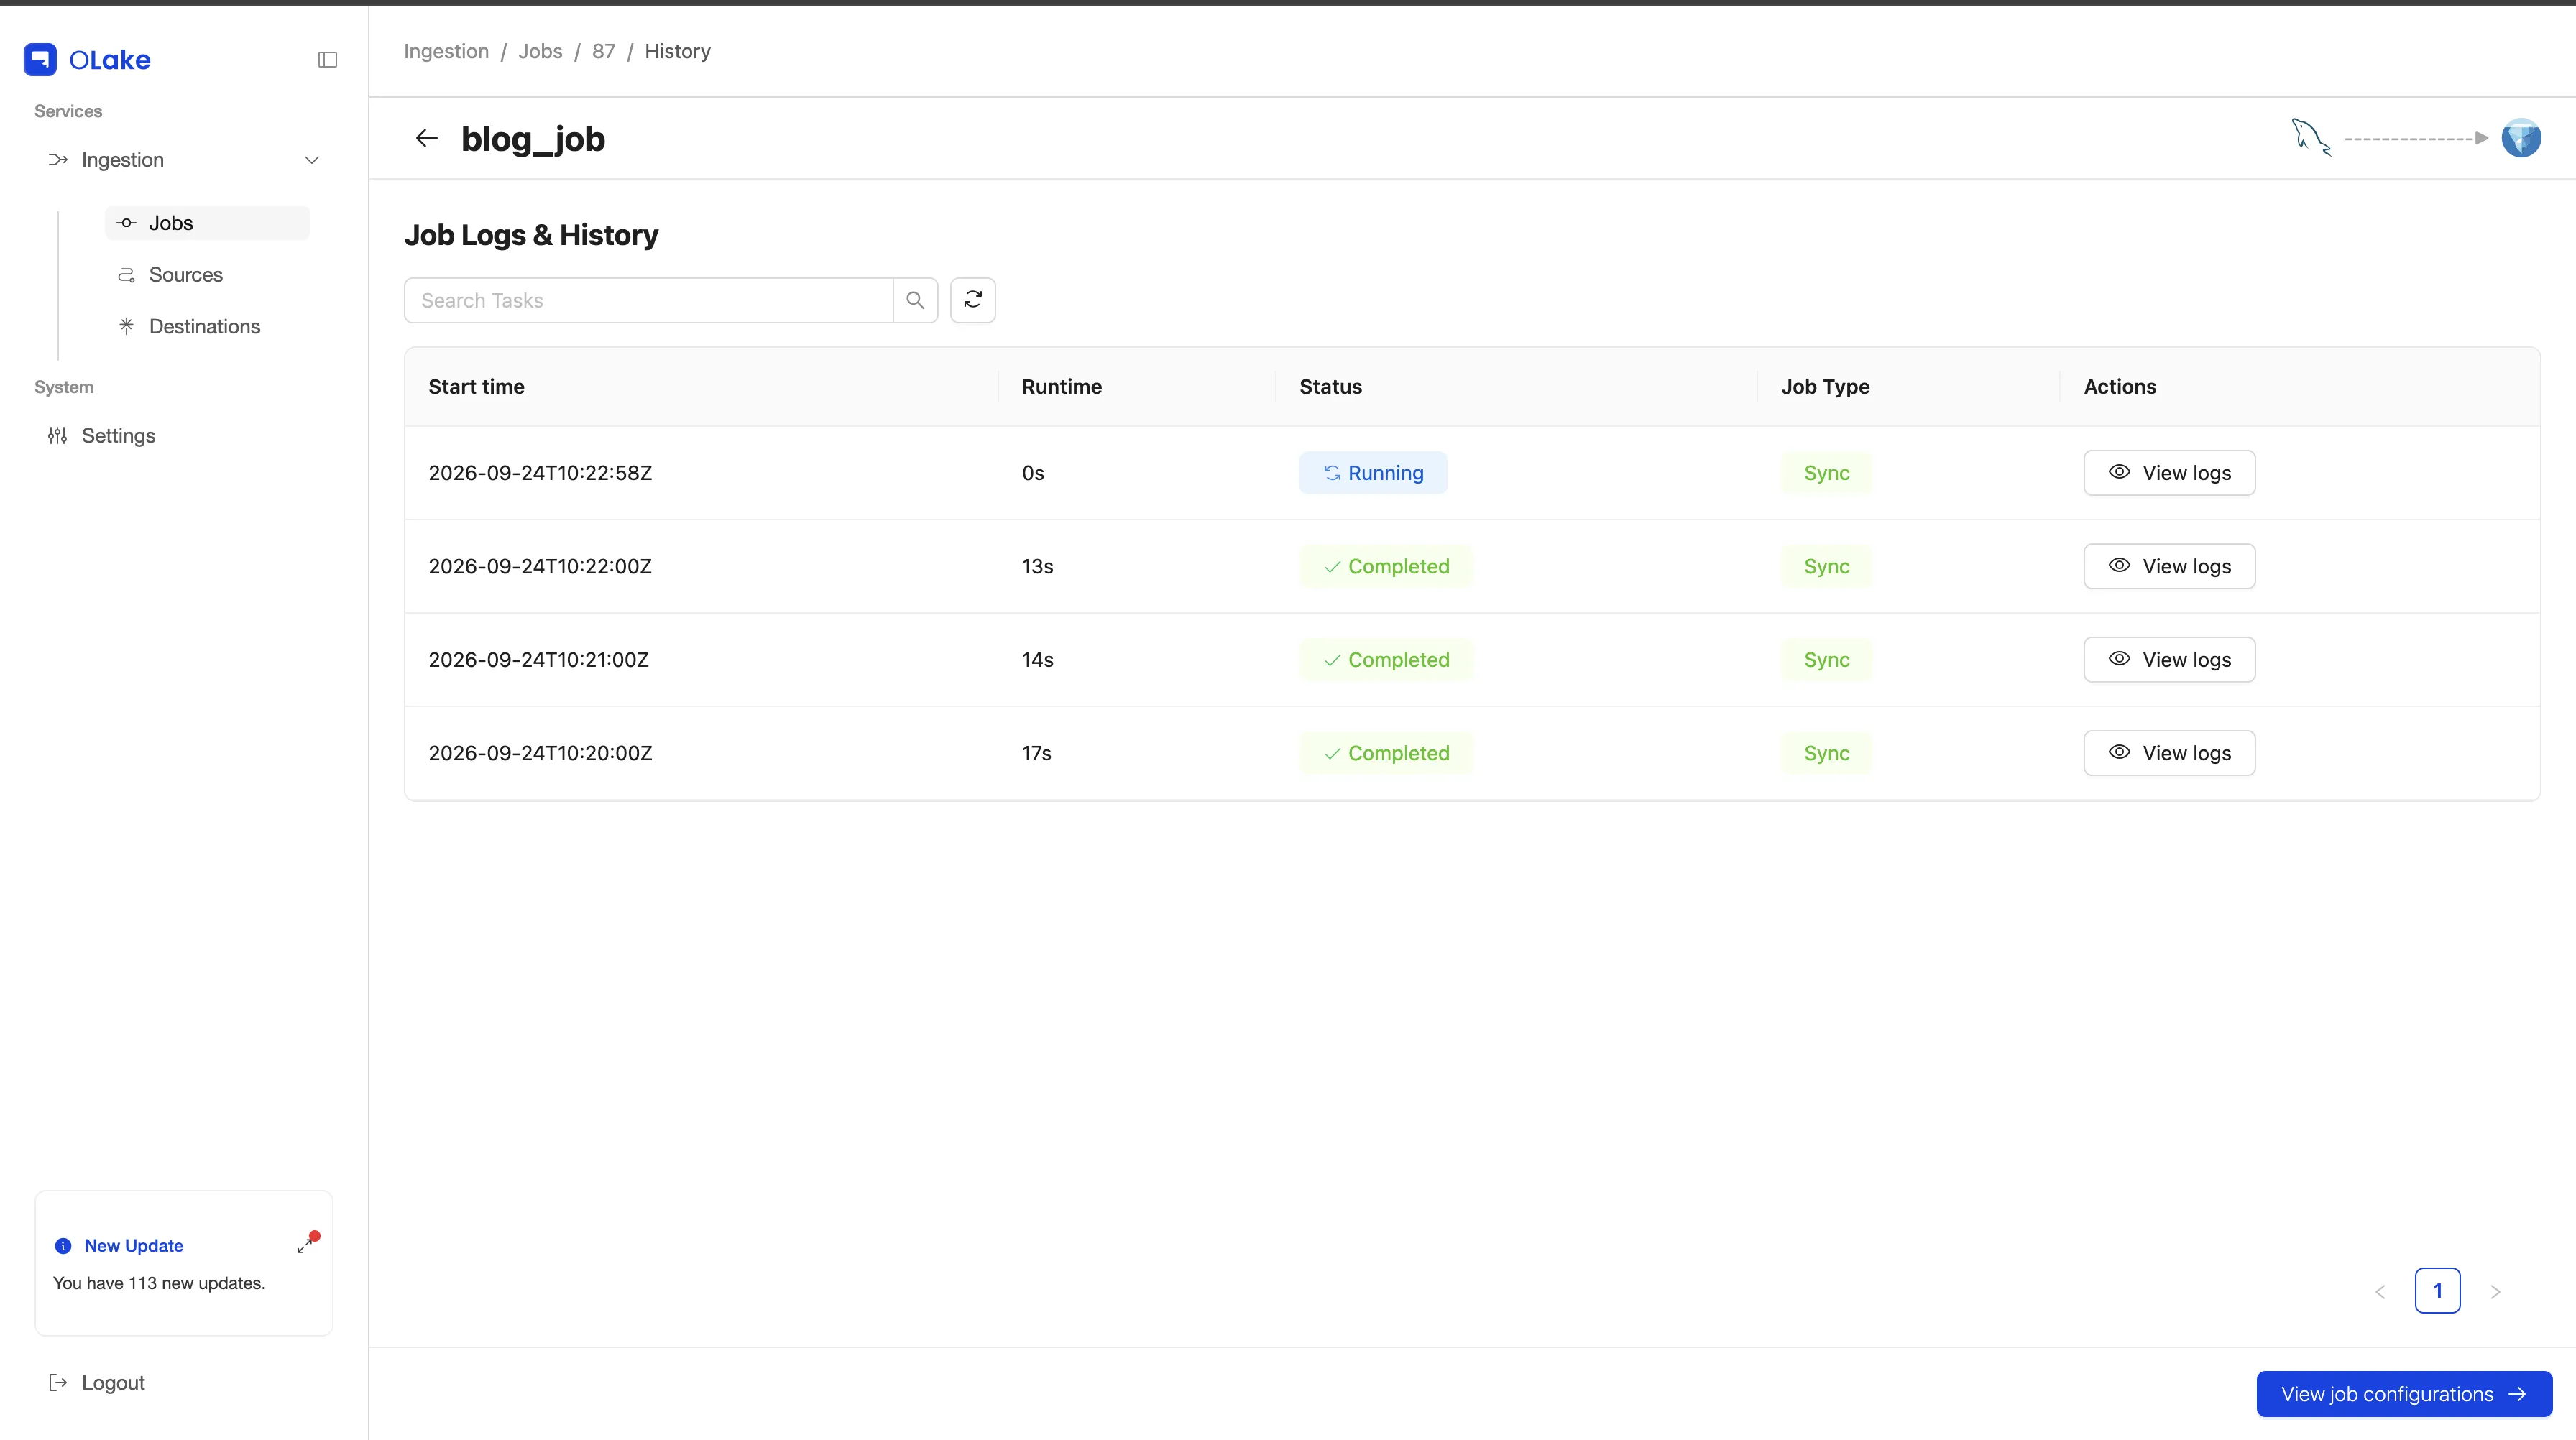
Click View logs next to any run to see its full log, including when MySQL CDC started, the total records read, and when the sync finished.
Once the sync finishes, the new Iceberg tables will be registered in your catalog and the data files will show up in your S3 bucket.
Step 5: Query with Apache Spark
Open Spark SQL and connect it to your AWS Glue catalog with this command:
spark-sql --packages org.apache.iceberg:iceberg-spark-runtime-3.5_2.12:1.12.0,org.apache.iceberg:iceberg-aws-bundle:1.12.0 \
    --conf spark.sql.defaultCatalog=my_catalog \
    --conf spark.sql.catalog.my_catalog=org.apache.iceberg.spark.SparkCatalog \
    --conf spark.sql.catalog.my_catalog.warehouse=s3://my-bucket/my/key/prefix \
    --conf spark.sql.catalog.my_catalog.type=glue \
    --conf spark.sql.catalog.my_catalog.io-impl=org.apache.iceberg.aws.s3.S3FileIO
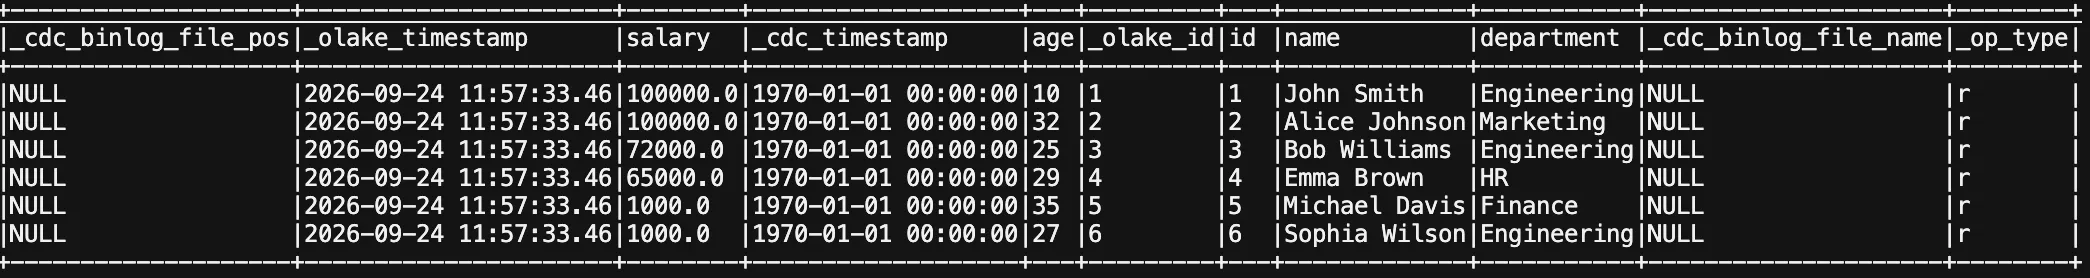
See the tables OLake Go created:
SELECT * FROM <catalog-name>.<namespace>.<table> LIMIT 10
Conclusion
Your pipeline now copies MySQL changes into Iceberg on the schedule you set, and Spark can query that data without slowing MySQL down. Because Iceberg is an open format, other engines like Trino, Flink, and DuckDB can read the same tables too. See the full list in the compatibility guide. Have questions? Join the OLake Slack community.