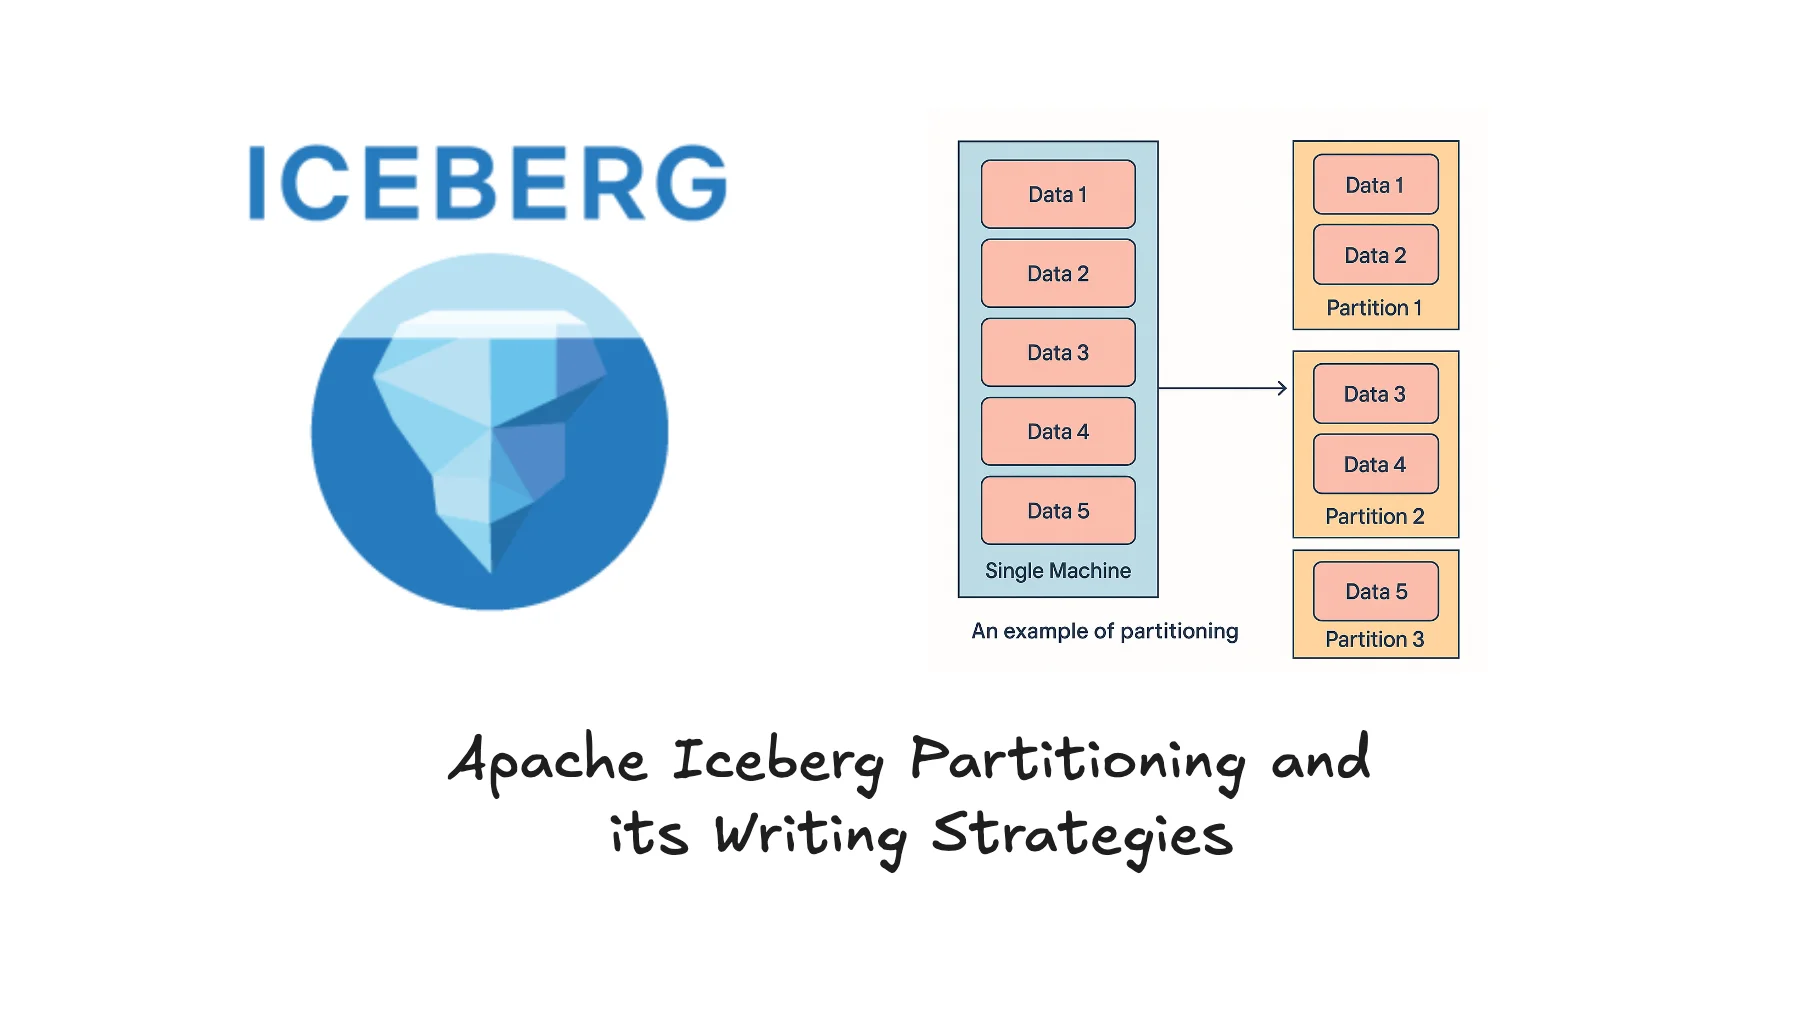
All about Iceberg Partitioning and Partitioning Writing Strategies
How Apache Iceberg partitioning works: PartitionSpec, query pruning, manifest explosion, and the fanout, clustered and partitioned writer strategies.
Engineering posts from the OLake team on database replication, CDC, Apache Iceberg, lakehouse tooling and OLake release news.
How Apache Iceberg partitioning works: PartitionSpec, query pruning, manifest explosion, and the fanout, clustered and partitioned writer strategies.
Replicate database data to Apache Iceberg on S3 with OLake, catalog it in AWS Glue and query the tables from Snowflake. A step-by-step setup guide.

Hive partitions by folder layout, Iceberg tracks partitions in metadata. Compare performance, management and scalability, with a Docker walkthrough.
Automate OLake data sync on AWS EC2 using Apache Airflow. Manage EC2 lifecycle, S3 configs, and Docker containers for seamless data integration.
Replicate MongoDB, Postgres or MySQL to Apache Iceberg with OLake, register tables in AWS Glue Data Catalog and query them serverlessly in Amazon Athena.
This is where the combination of OLake, Apache Iceberg, AWS Glue Data Catalog, and Trino provides a powerful, simple, and serverless solution