20 posts tagged with "CDC - Change Data Capture"
Blogs on the topic Change Data Capture
View All Tags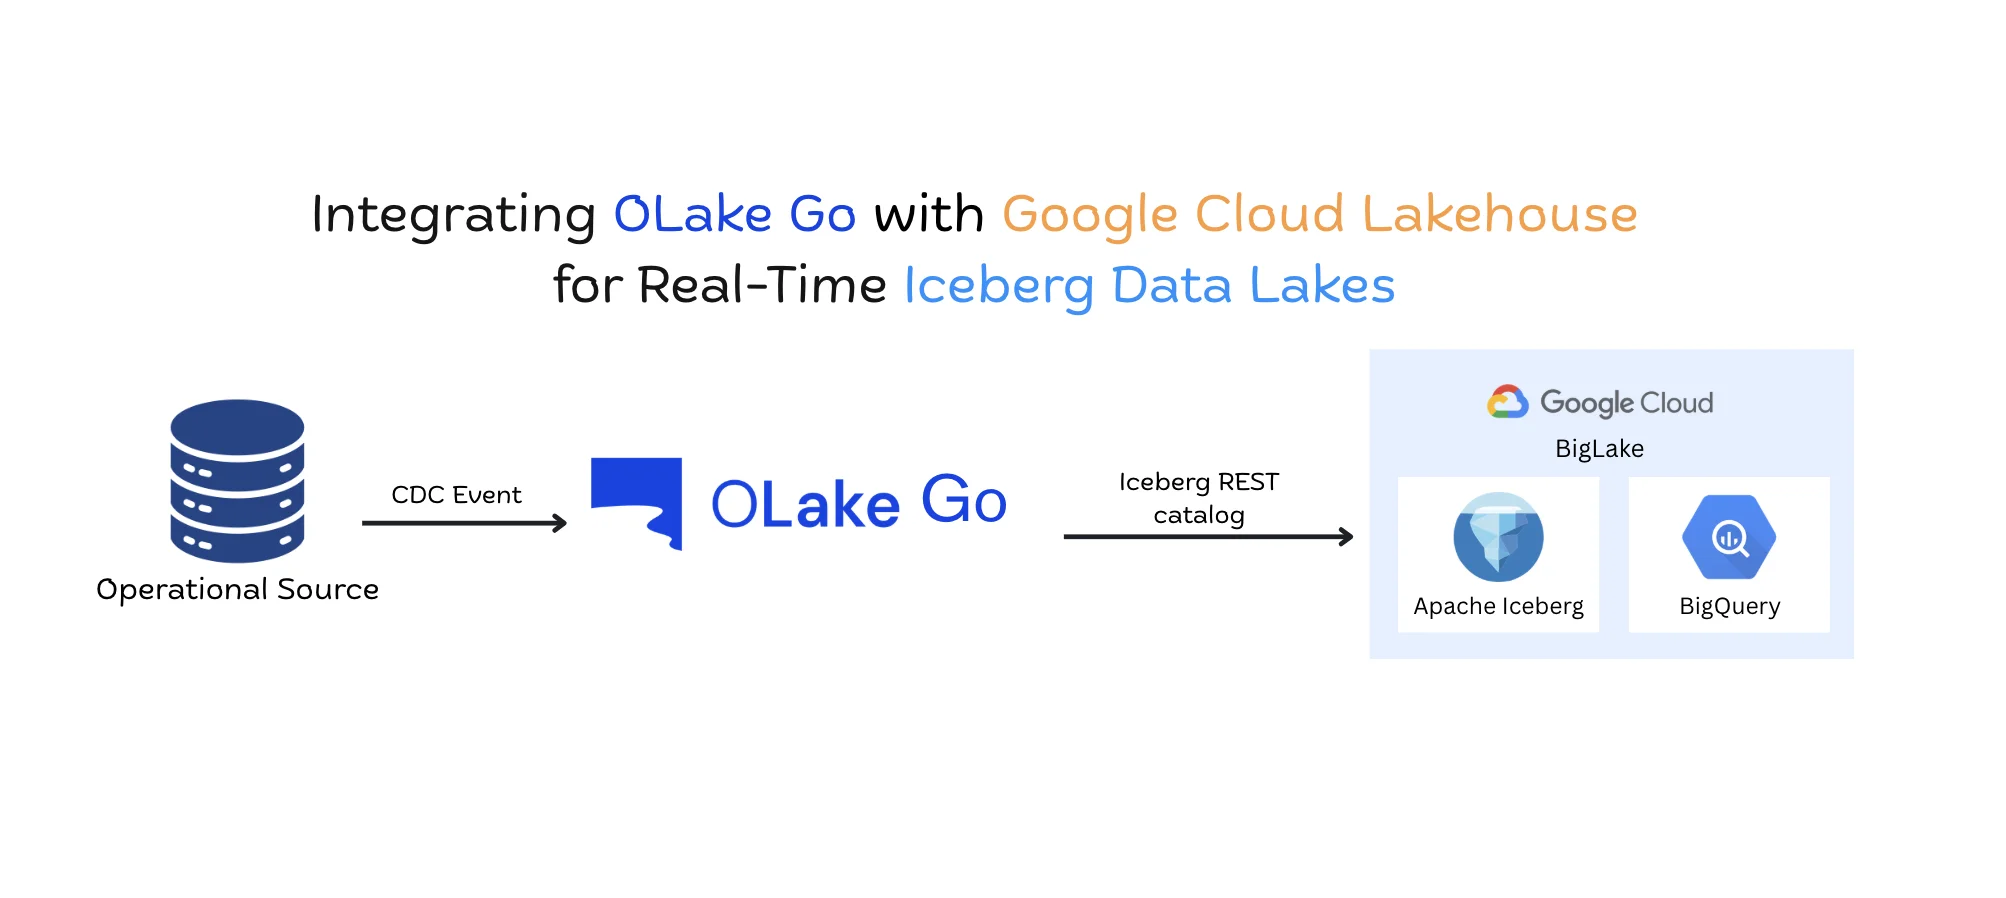
Integrating OLake Go with Google Cloud Lakehouse for Real-Time Iceberg Data Lakes
Stream Postgres CDC into Apache Iceberg tables on Google BigLake with OLake Go and query live data in BigQuery. A step-by-step setup with no Kafka or Spark.
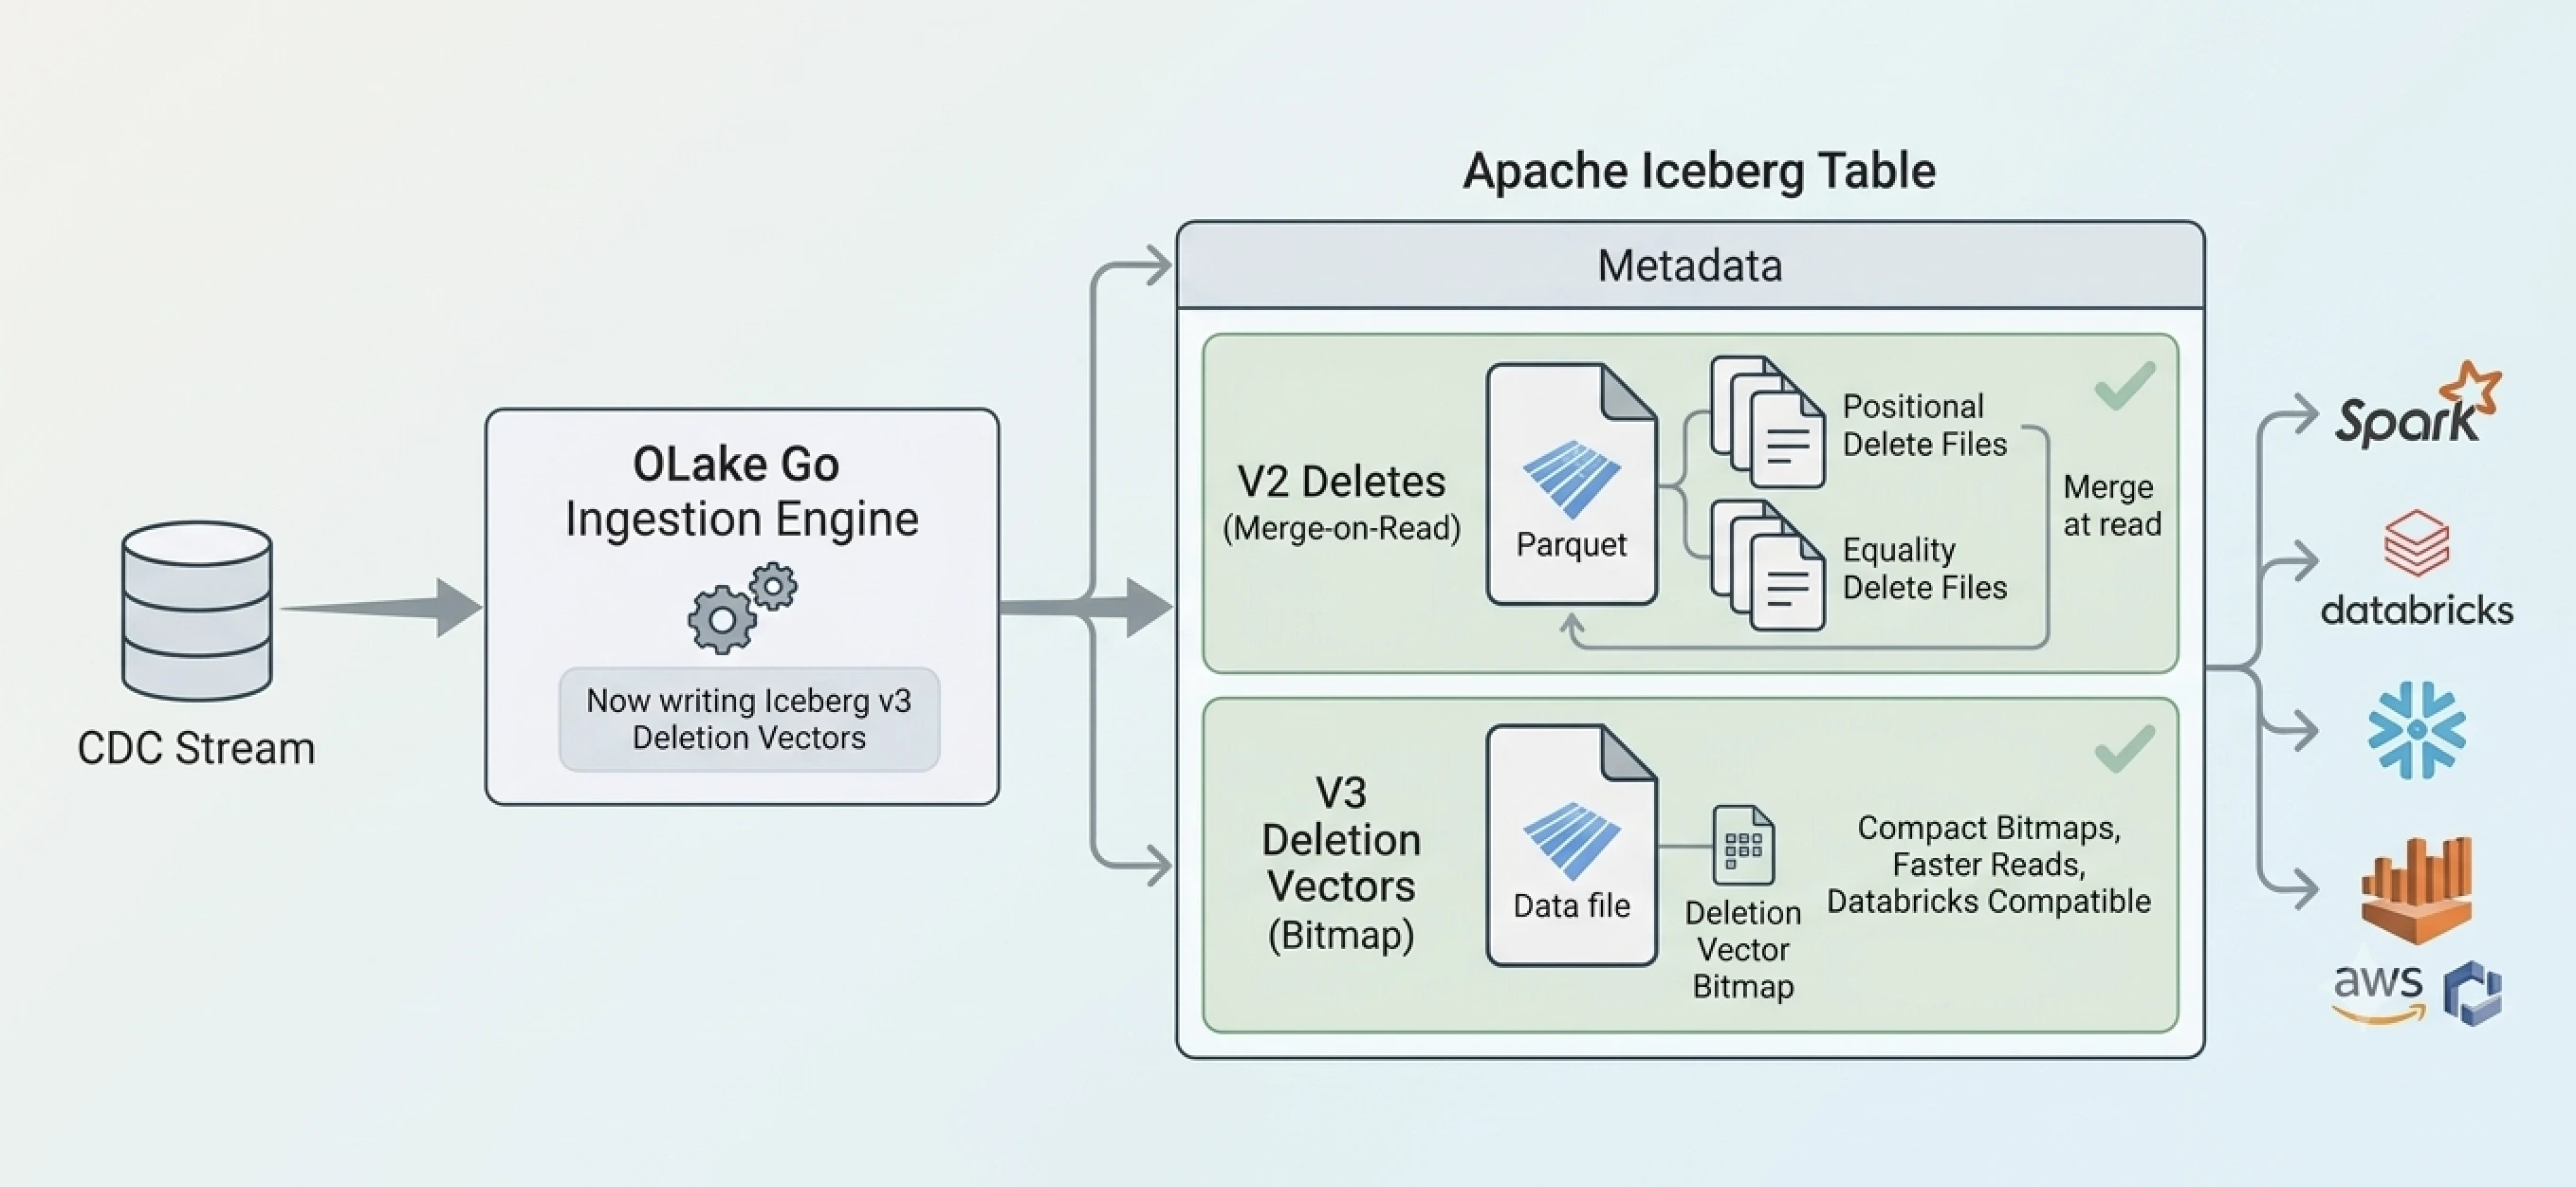
Interoperability Unlocked: OLake Go Now Writes Iceberg Deletion Vectors
OLake Go can now write Iceberg v3 deletion vectors for upserts and CDC. From immutable Parquet and merge-on-read to equality and positional deletes—and why bitmap deletion vectors close the gap with query engines.
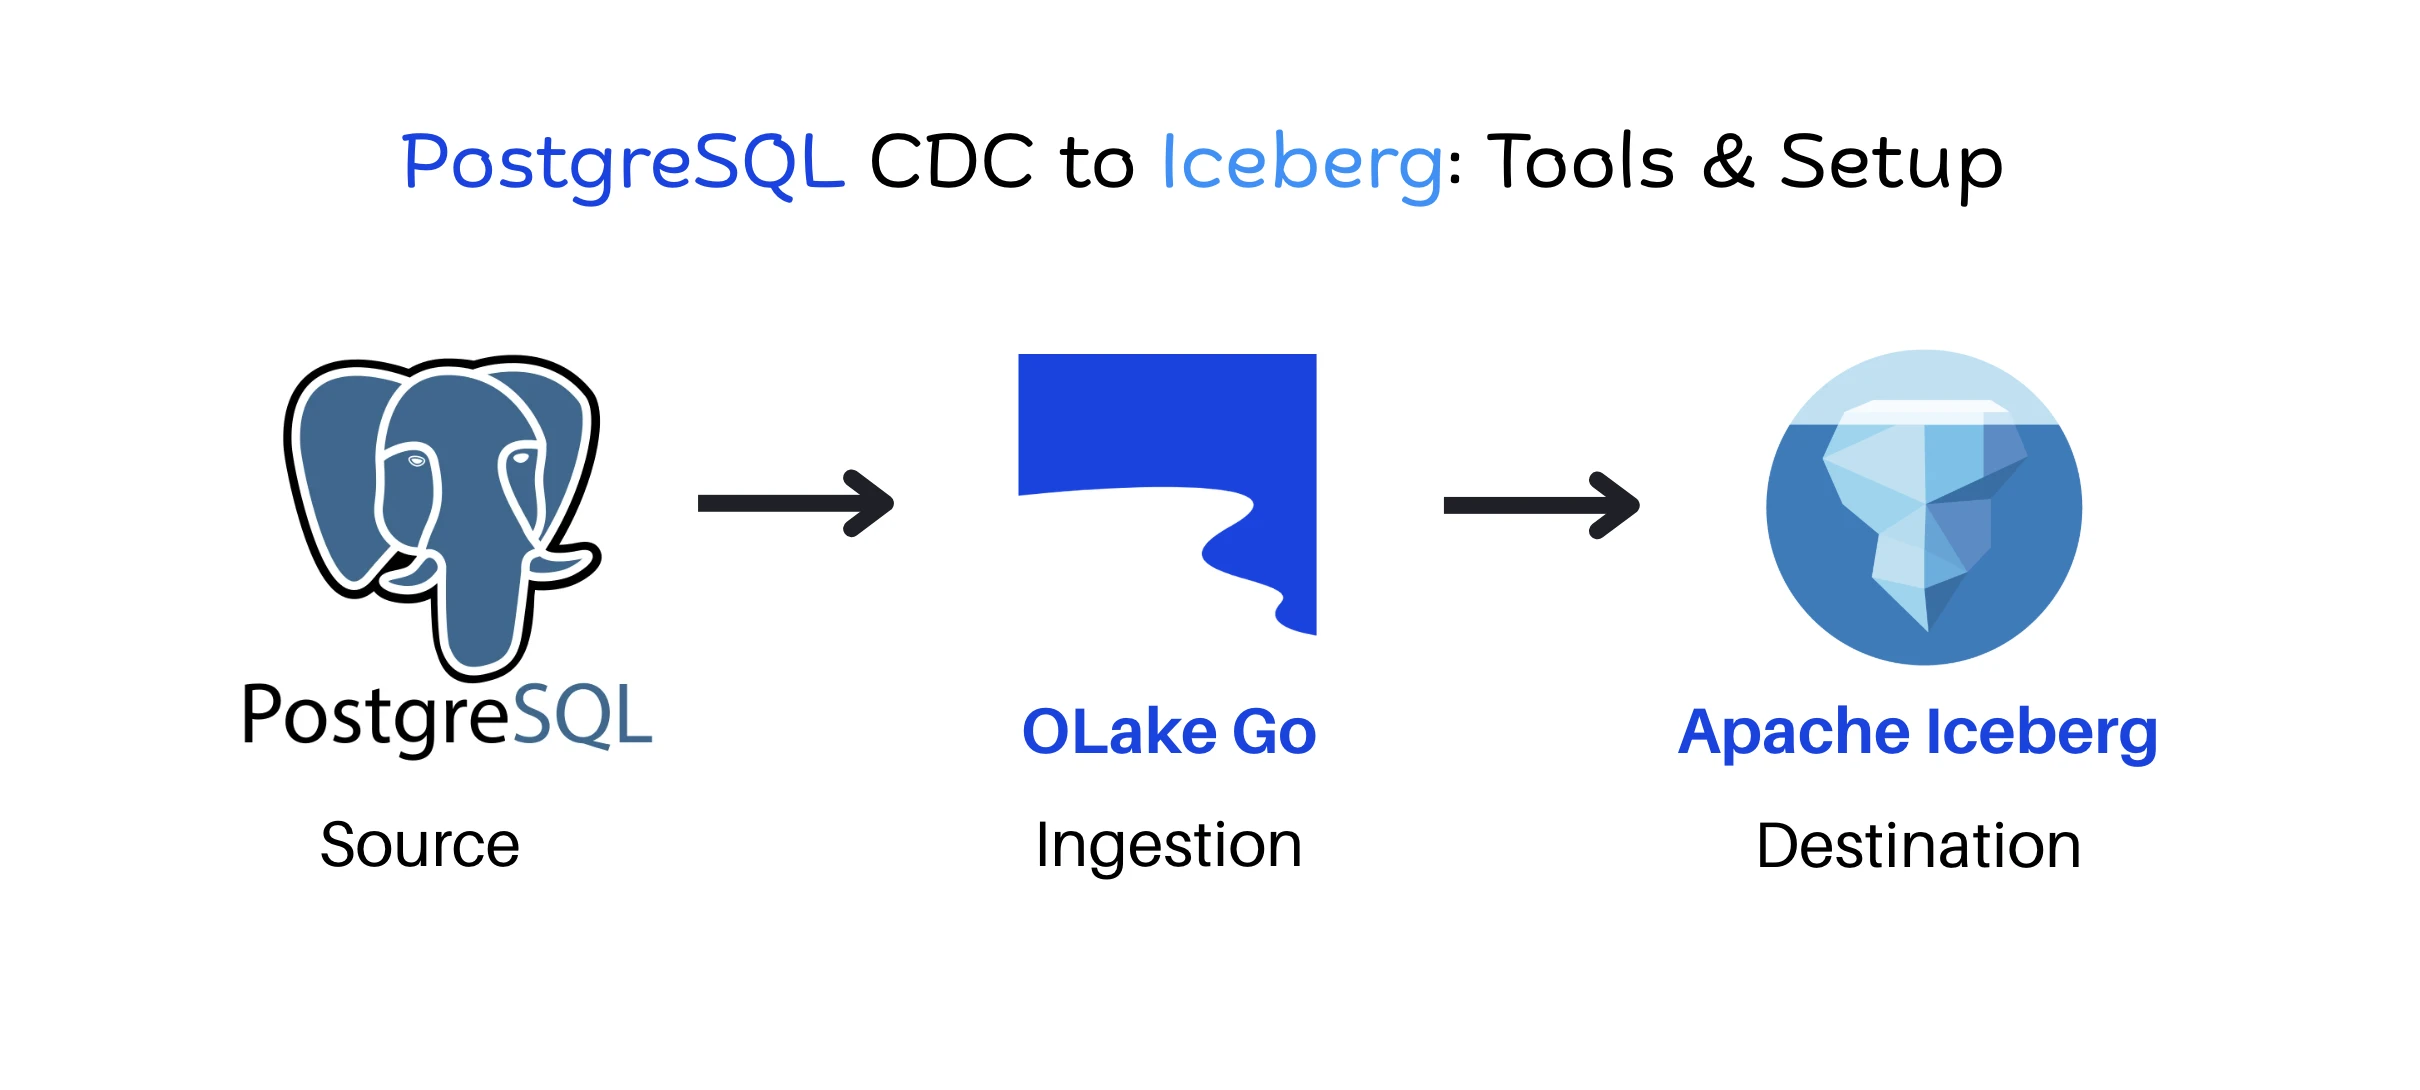
PostgreSQL CDC to Iceberg: Tools & Setup
Learn how to replicate PostgreSQL CDC data to Apache Iceberg without Spark using Kafka, Flink, or OLake, including setup, architecture, and best practices.
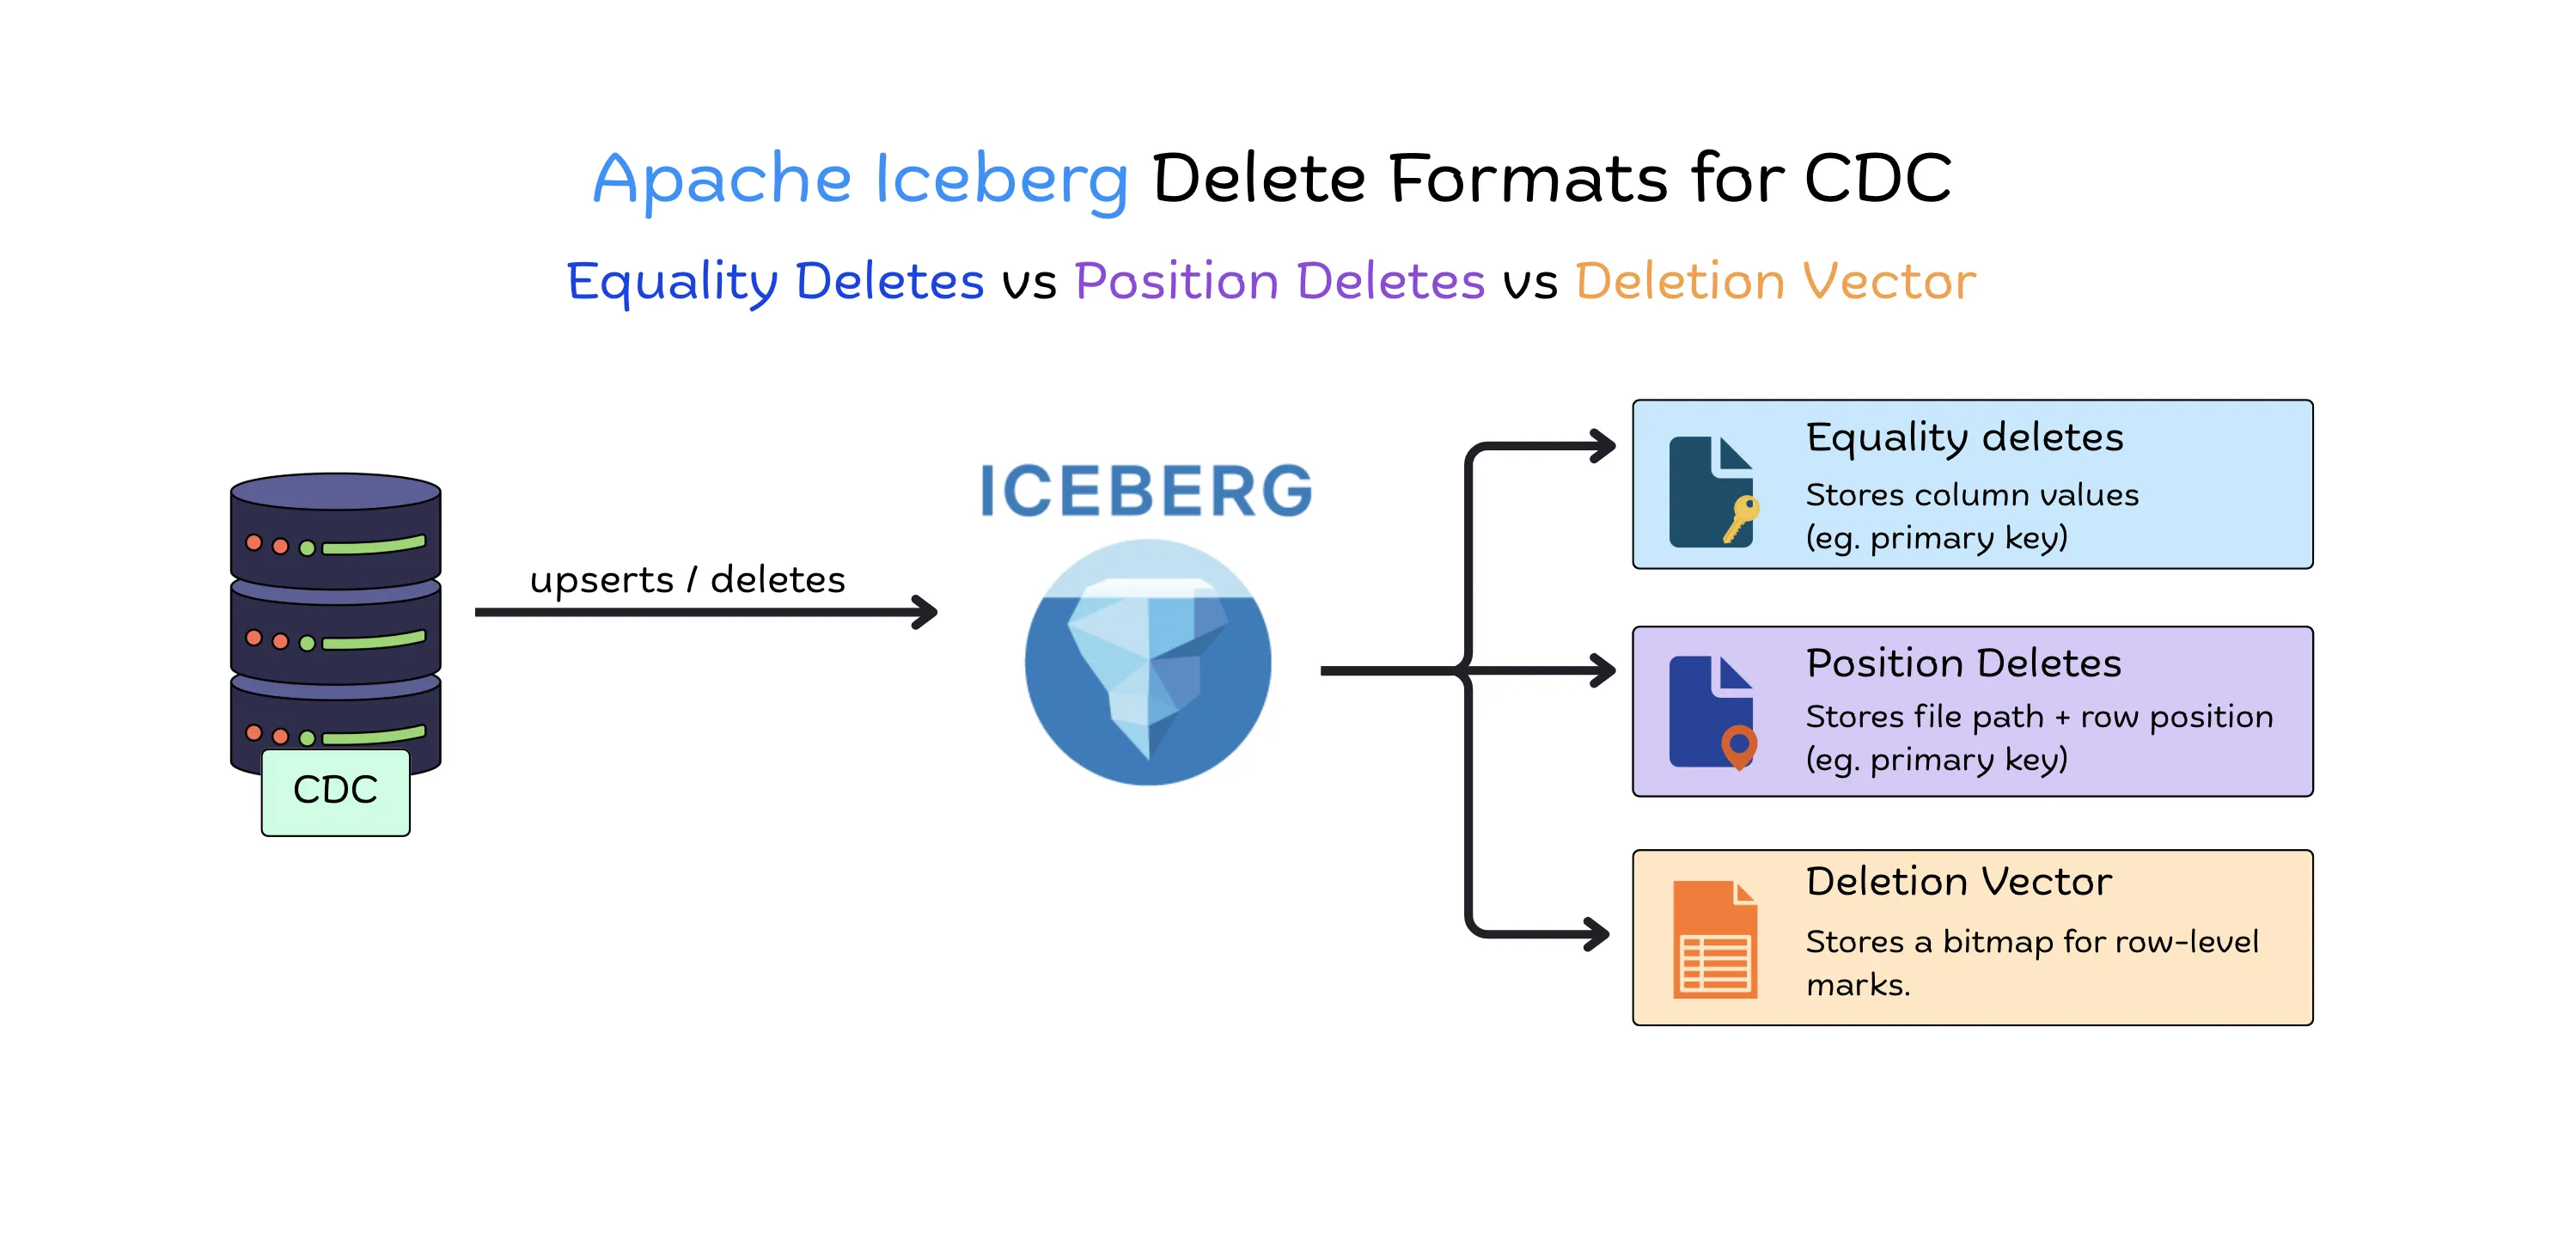
Apache Iceberg Delete Formats for CDC: Equality vs Positional Deletes vs Deletion Vectors
Equality deletes, position deletes, and deletion vectors compared for CDC pipelines: what each stores, which query engines can read them, what compaction fixes, and the table properties to set explicitly.
Deep dive into OLake Go architecture
How OLake Go works under the hood: eight sources driven by one sync engine, chunked parallel backfills, native CDC, state management, the Arrow write path to Apache Iceberg, and Parquet on S3-compatible storage.
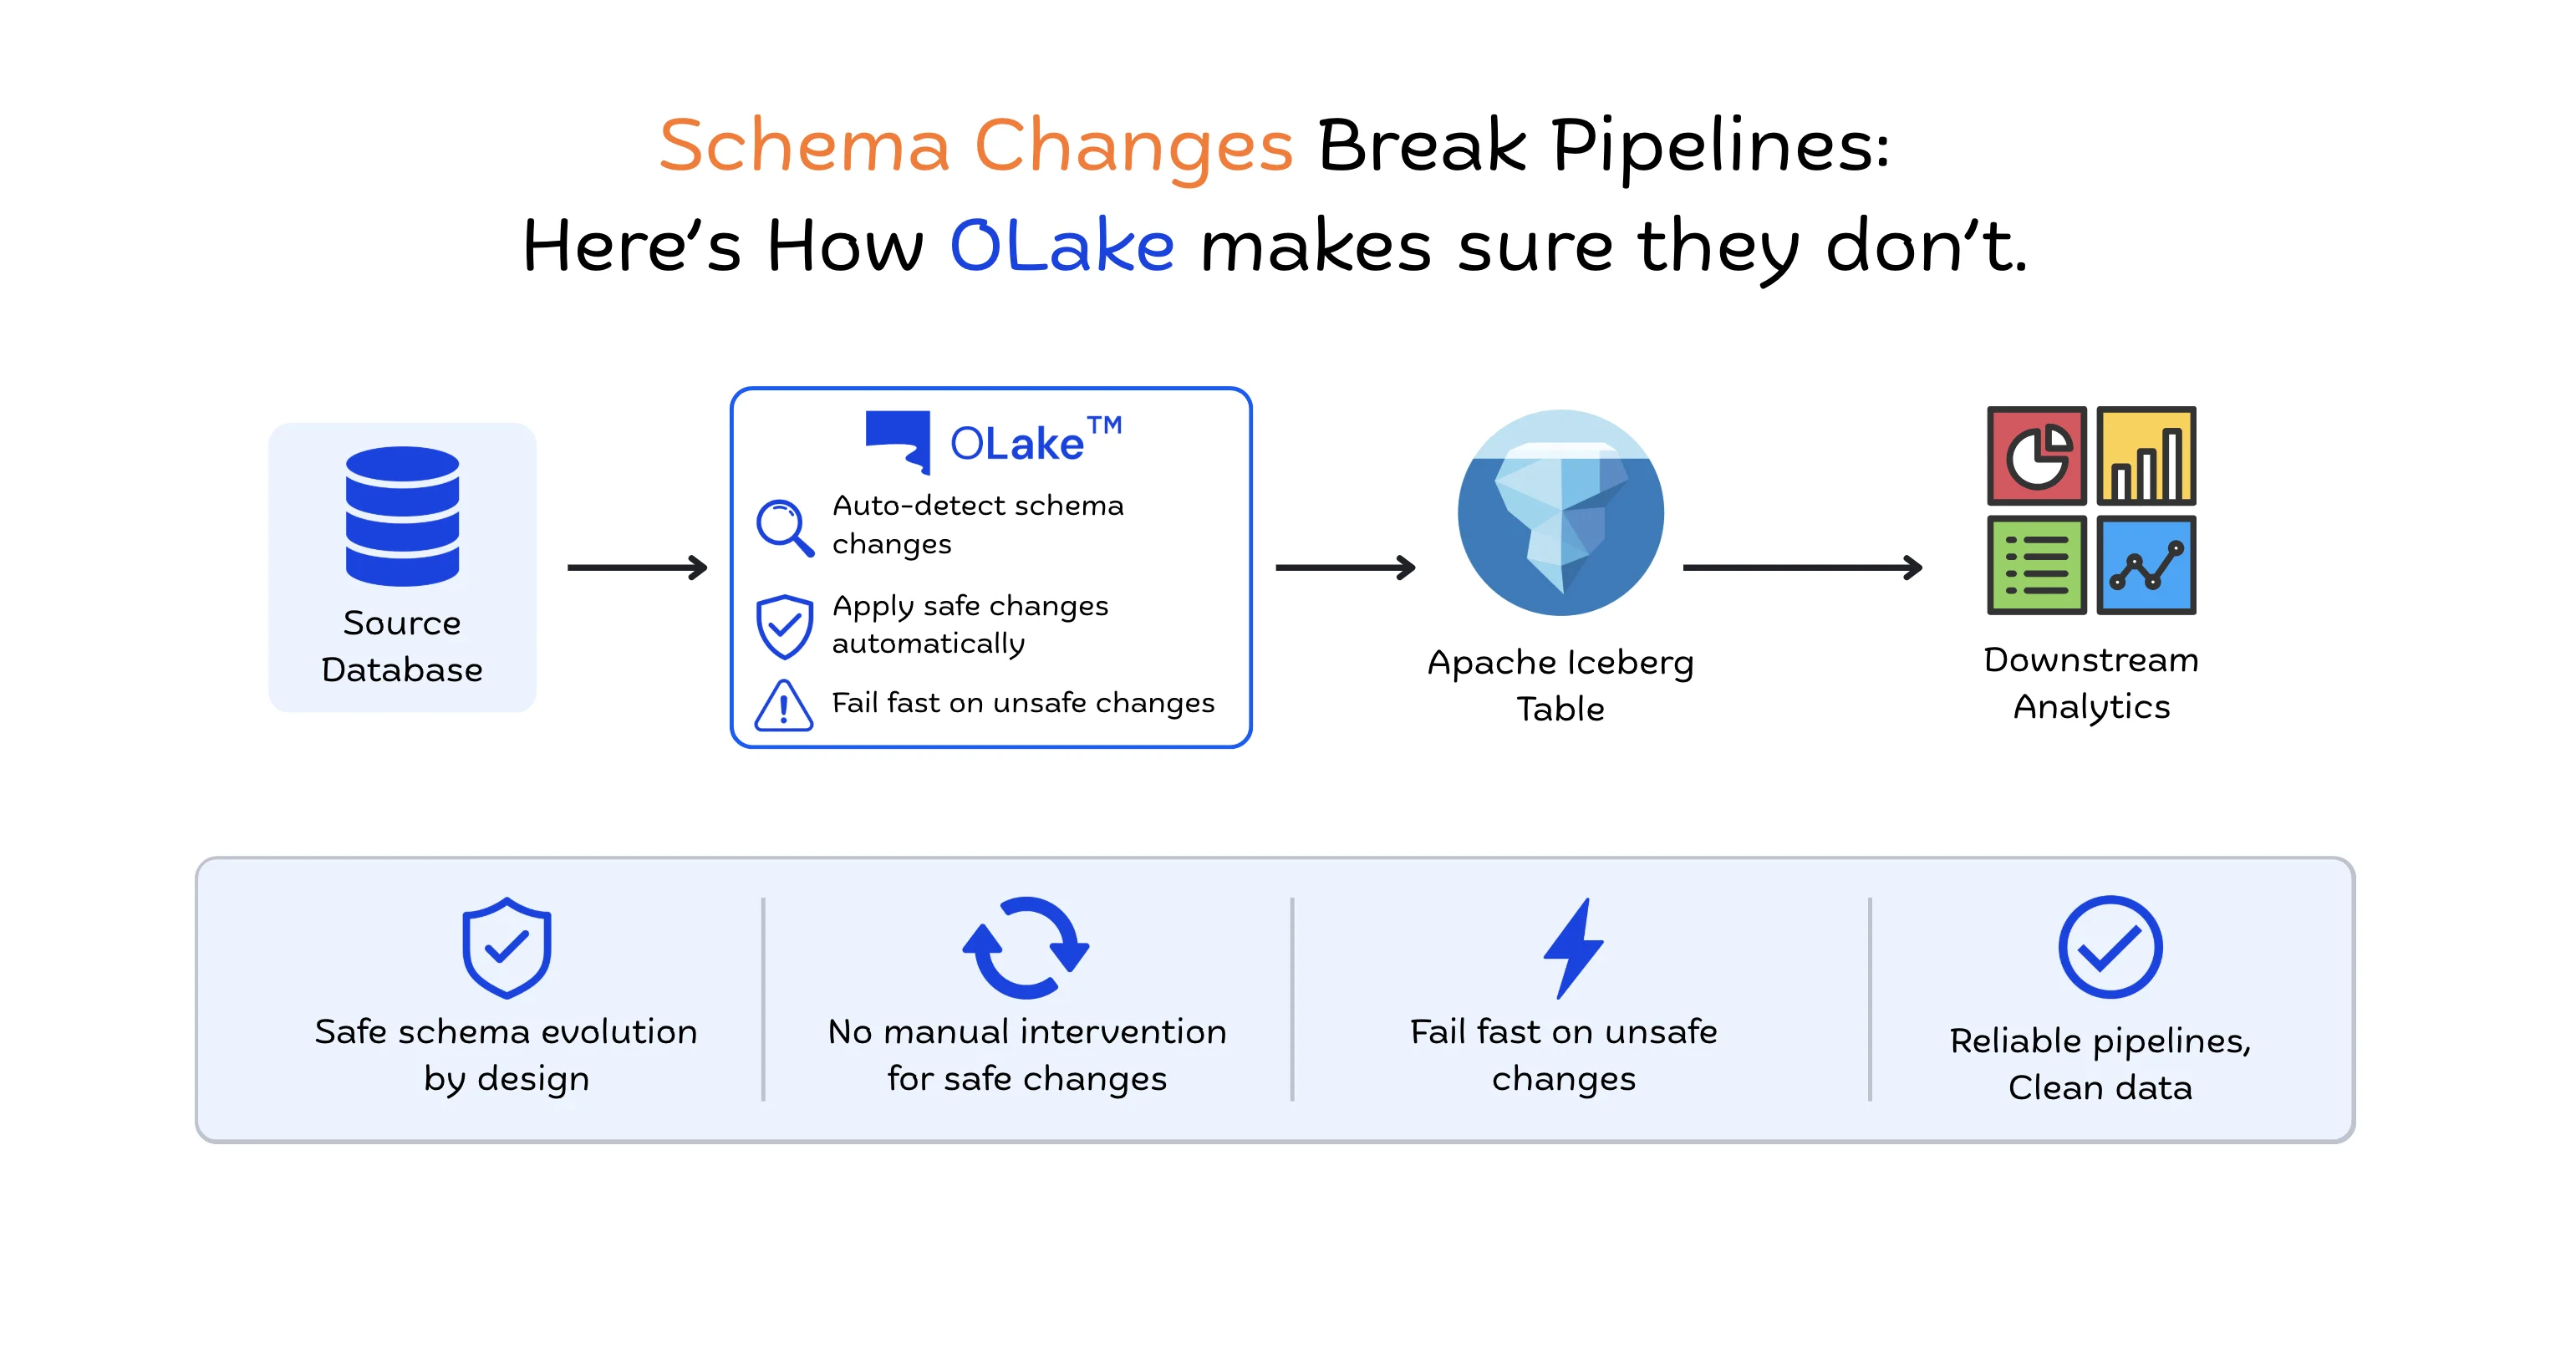
How OLake Go Handles Schema Evolution Without Breaking Your Pipeline
How OLake Go handles schema evolution into Apache Iceberg: automatic column adds, retained drops, safe type promotions, and explicit failures only where data would corrupt. Built on Iceberg's field-ID tracking, across Postgres, MySQL, MongoDB, and Kafka.