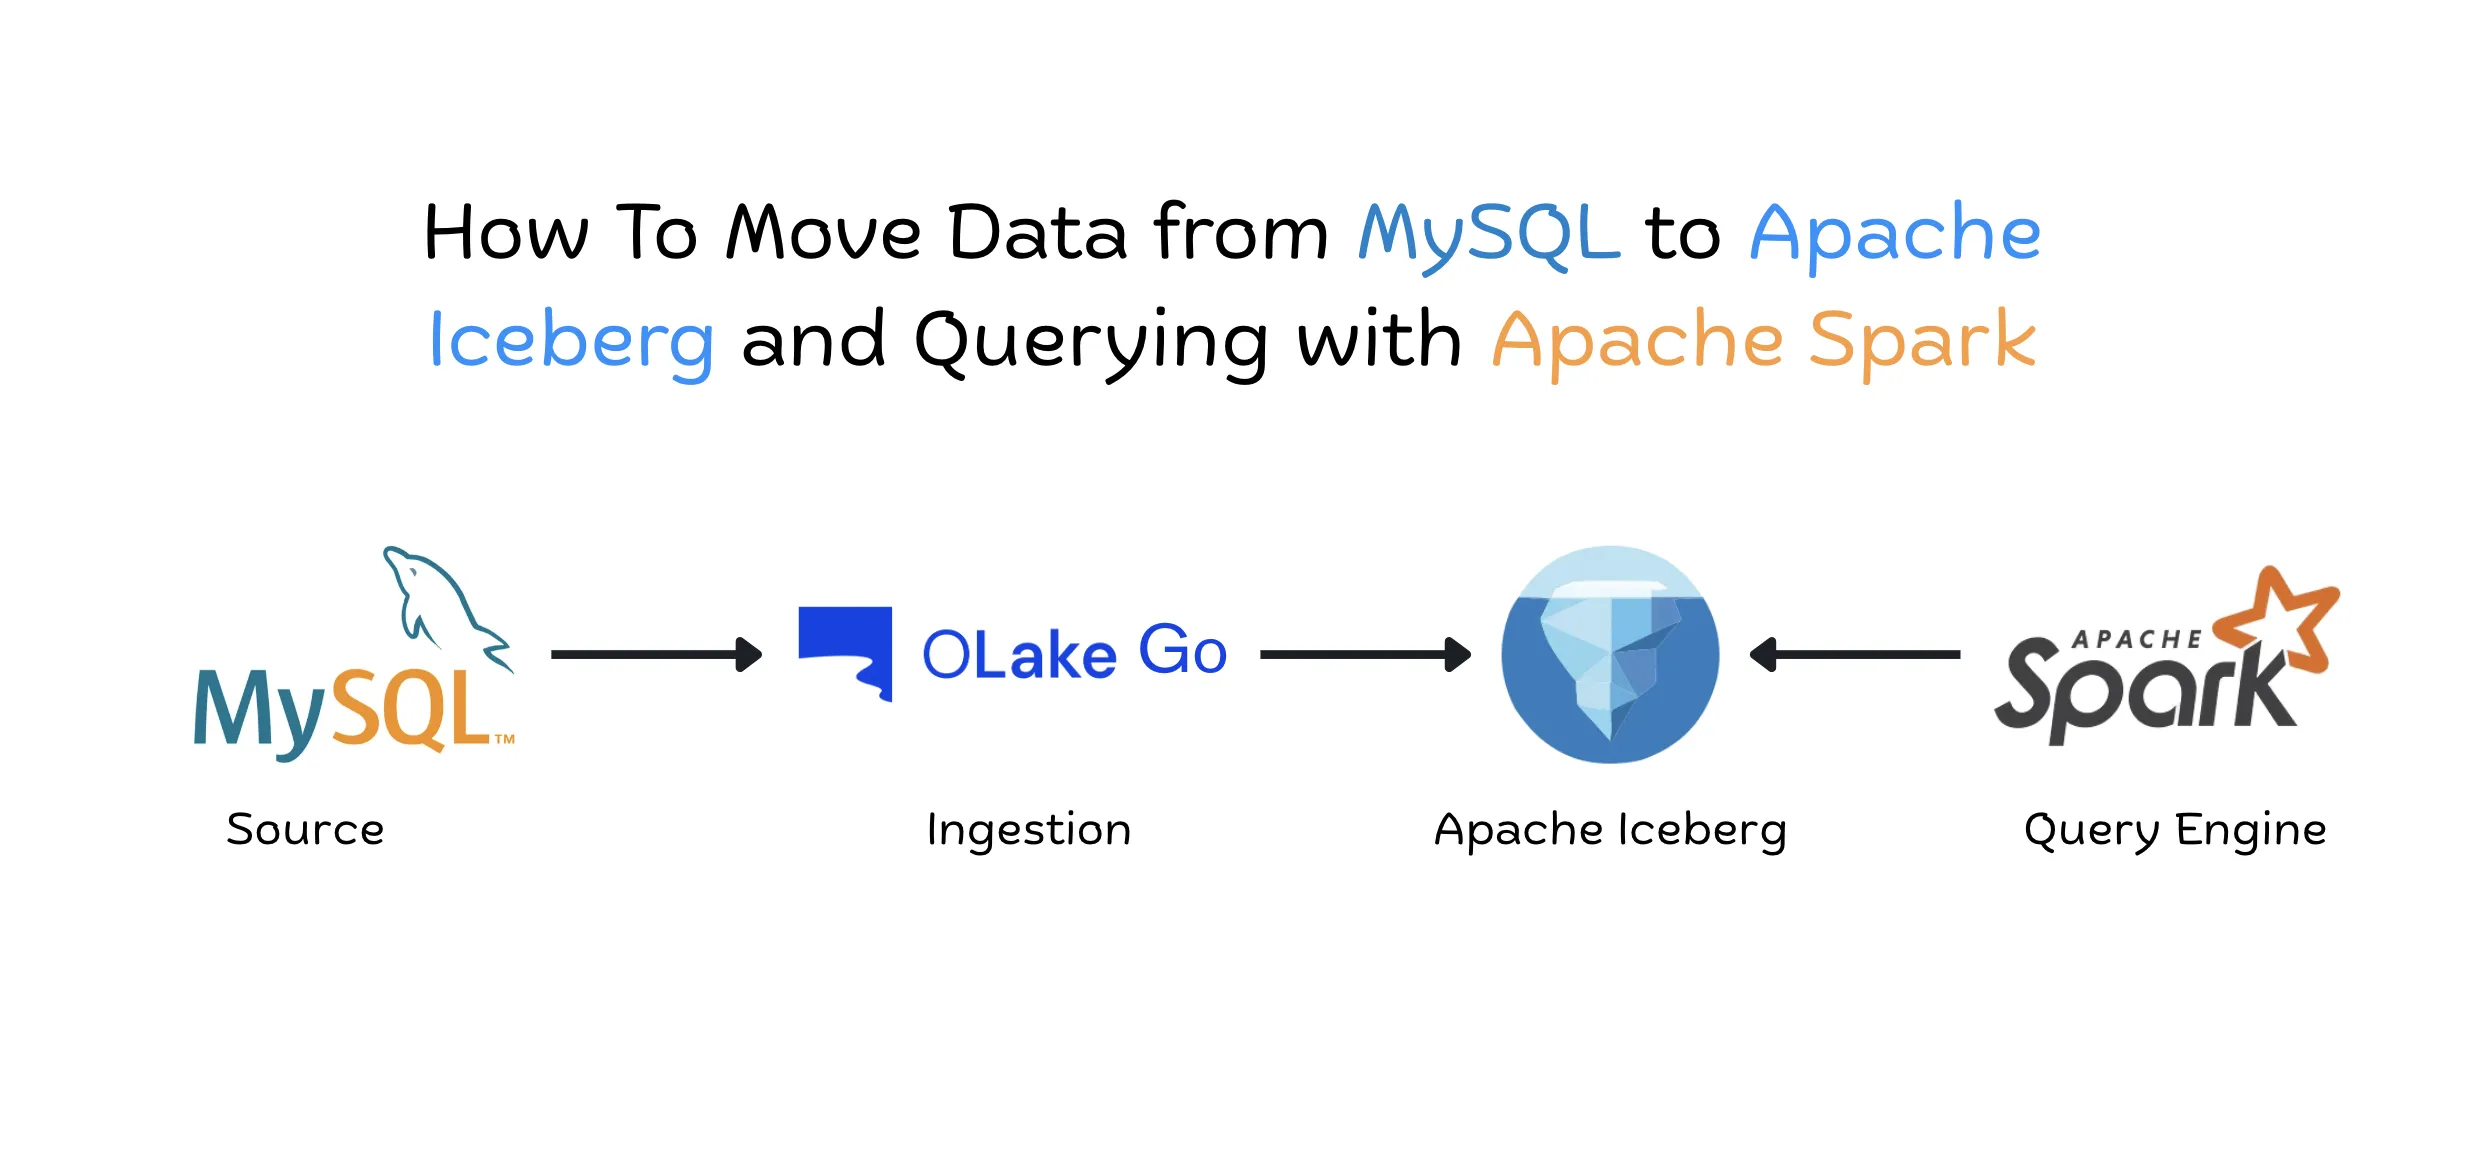
How To Move Data from MySQL to Apache Iceberg and Querying with Apache Spark
Replicate MySQL to Apache Iceberg with OLake Go and query it in Apache Spark. A step-by-step guide to setting up the source, catalog, job, sync and Spark SQL.
Blogs on the topic Apache Iceberg
View All TagsReplicate MySQL to Apache Iceberg with OLake Go and query it in Apache Spark. A step-by-step guide to setting up the source, catalog, job, sync and Spark SQL.
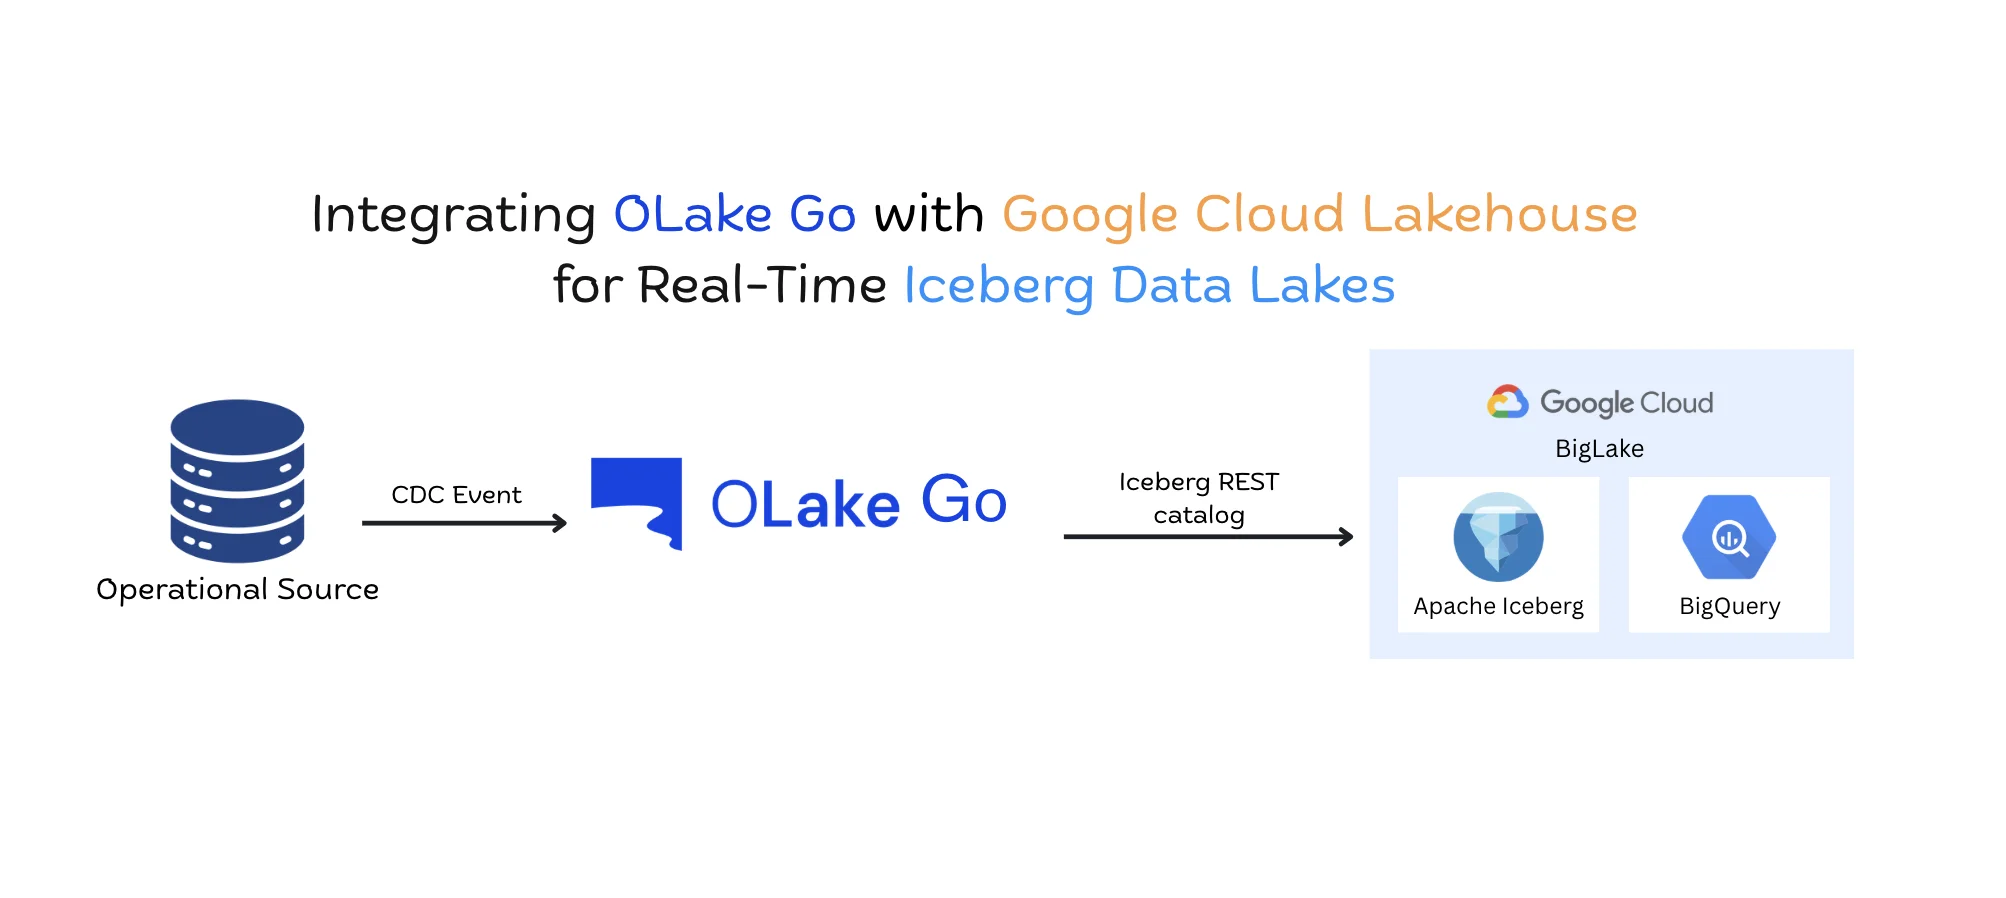
Stream Postgres CDC into Apache Iceberg tables on Google BigLake with OLake Go and query live data in BigQuery. A step-by-step setup with no Kafka or Spark.
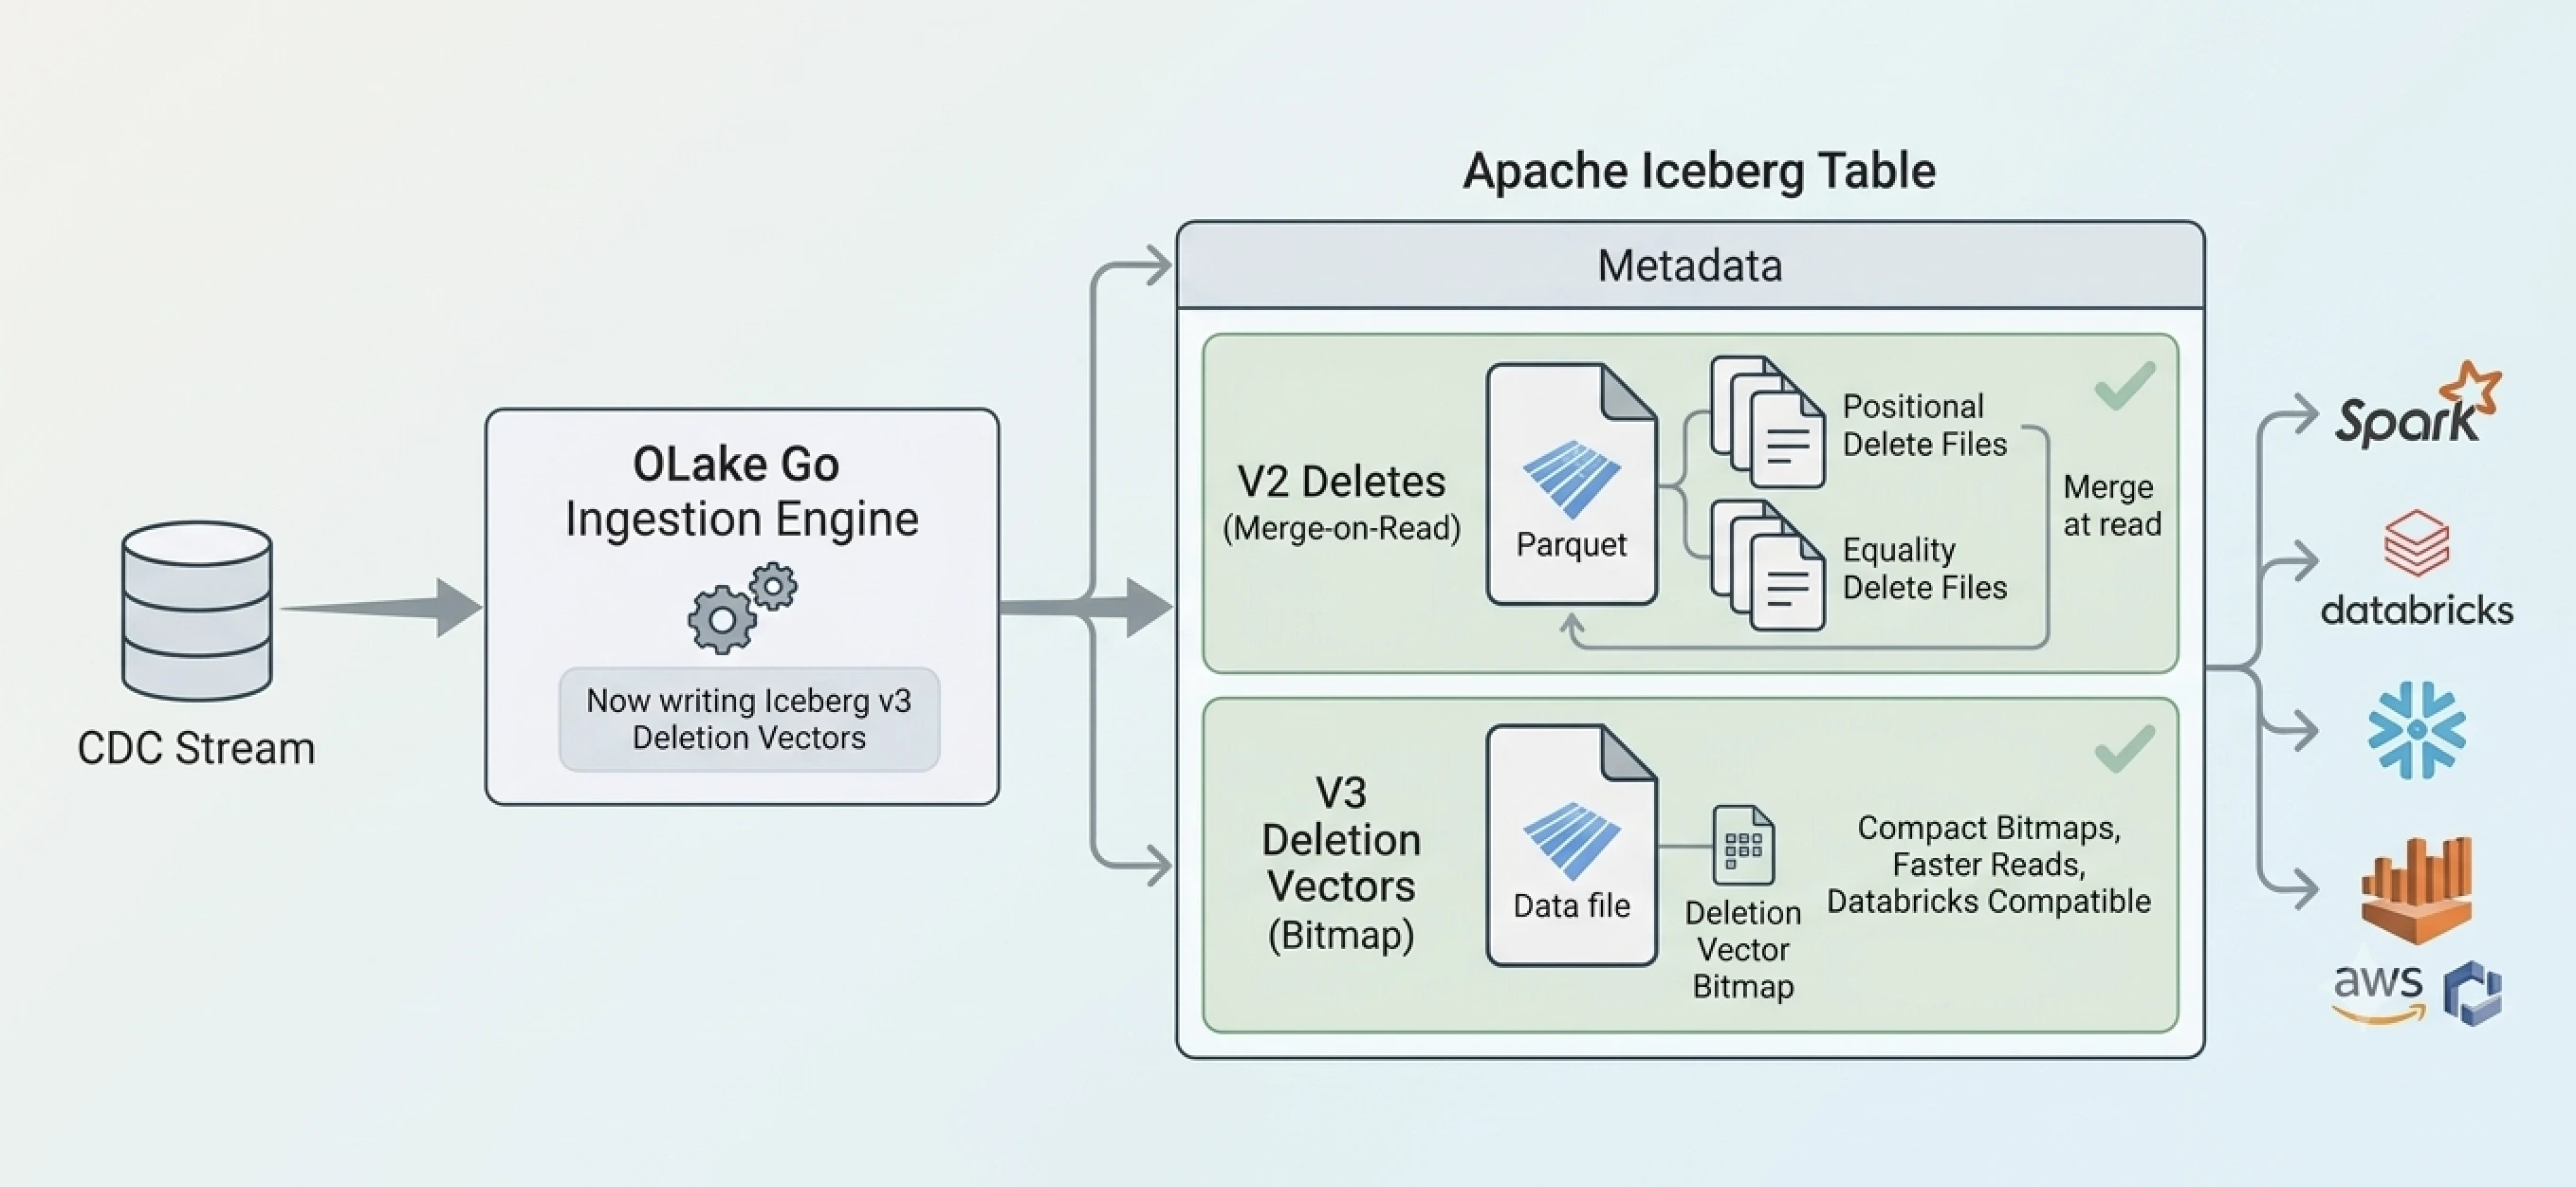
OLake Go can now write Iceberg v3 deletion vectors for upserts and CDC. From immutable Parquet and merge-on-read to equality and positional deletes—and why bitmap deletion vectors close the gap with query engines.
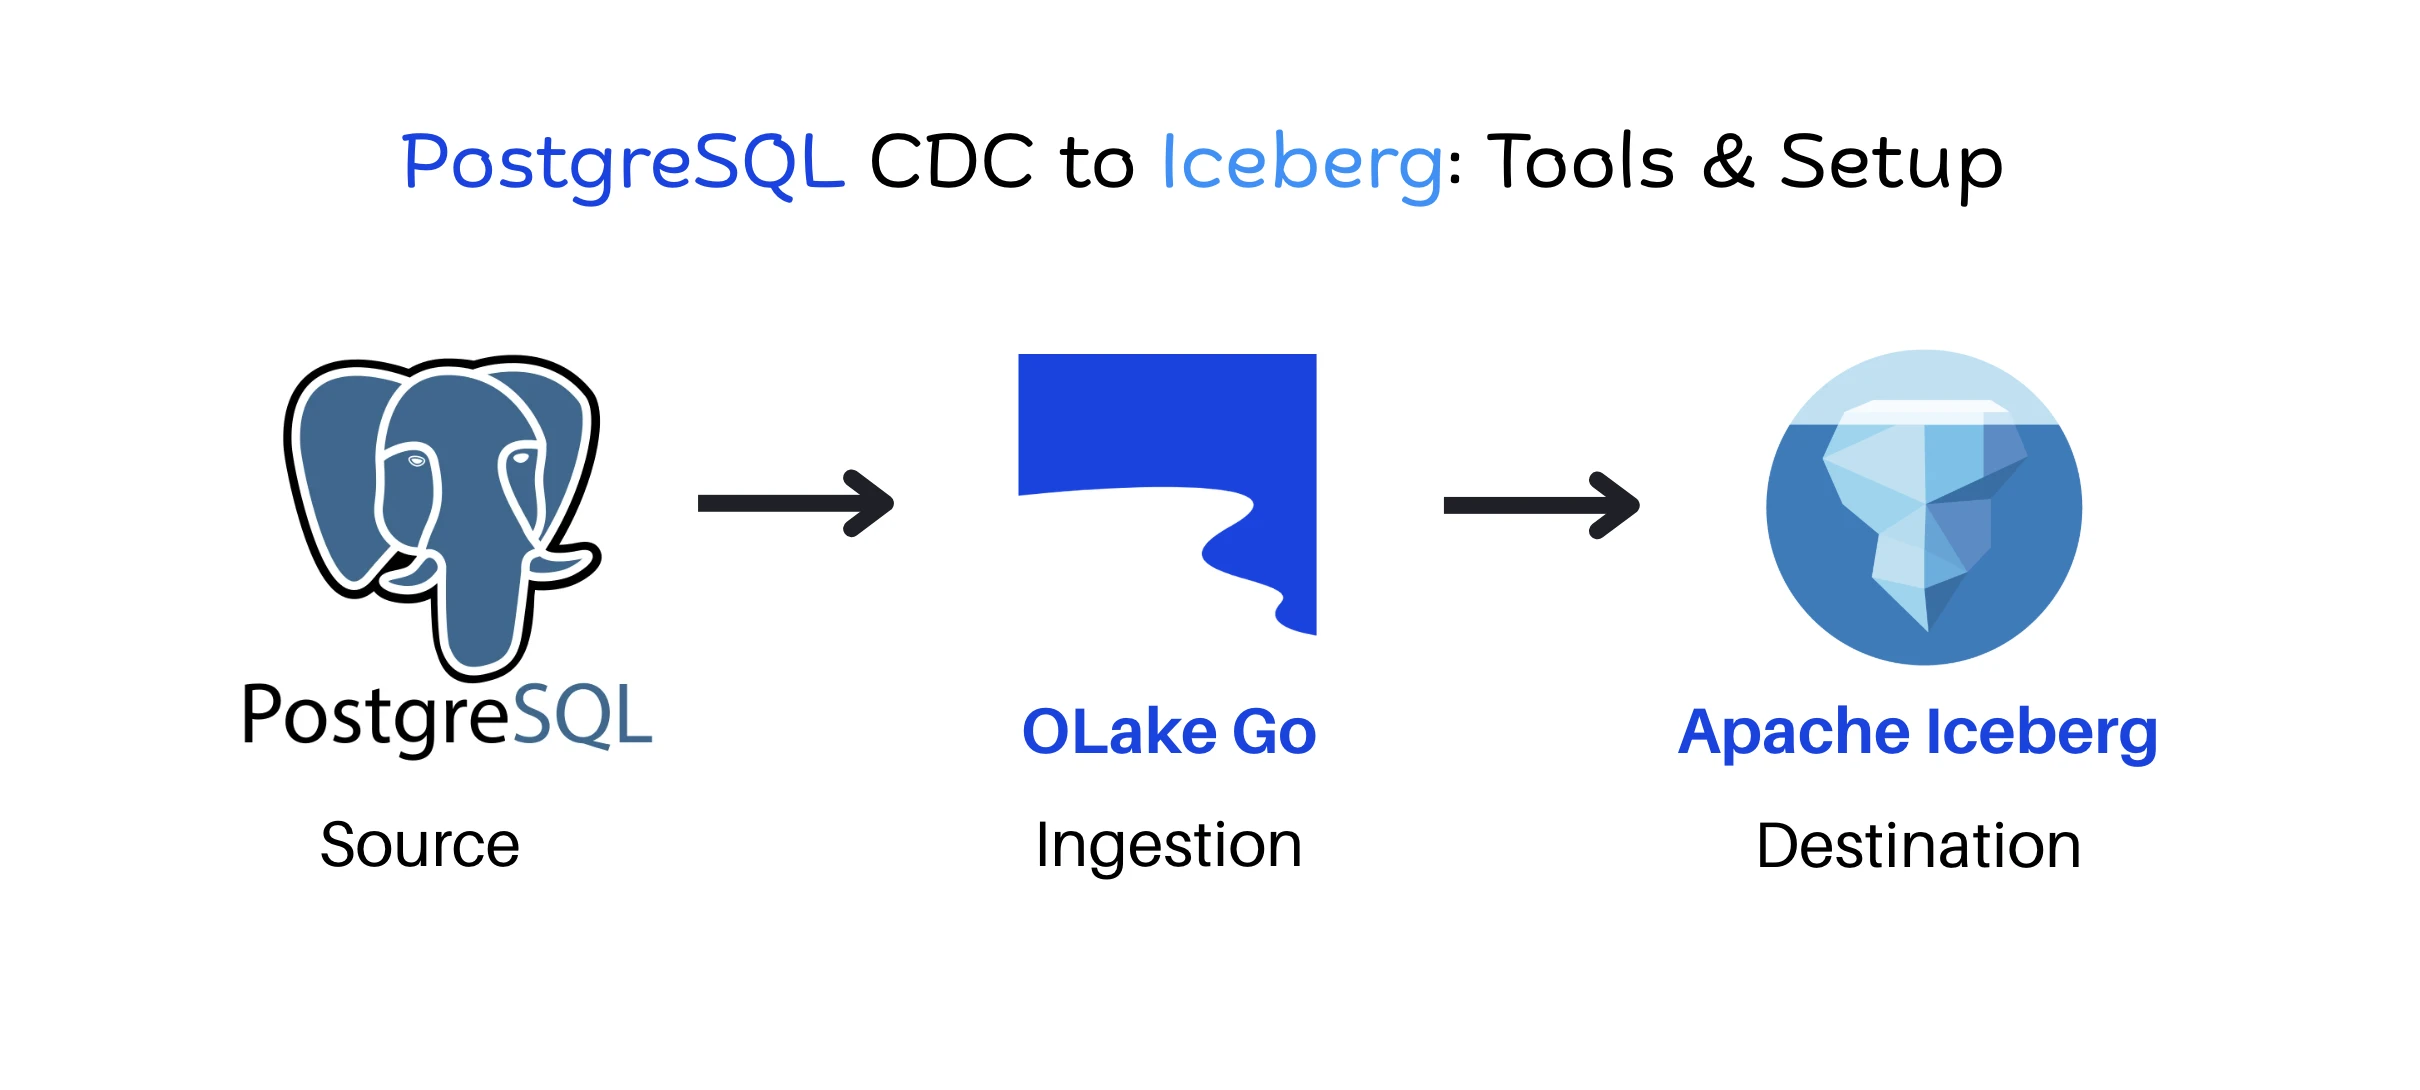
Learn how to replicate PostgreSQL CDC data to Apache Iceberg without Spark using Kafka, Flink, or OLake, including setup, architecture, and best practices.
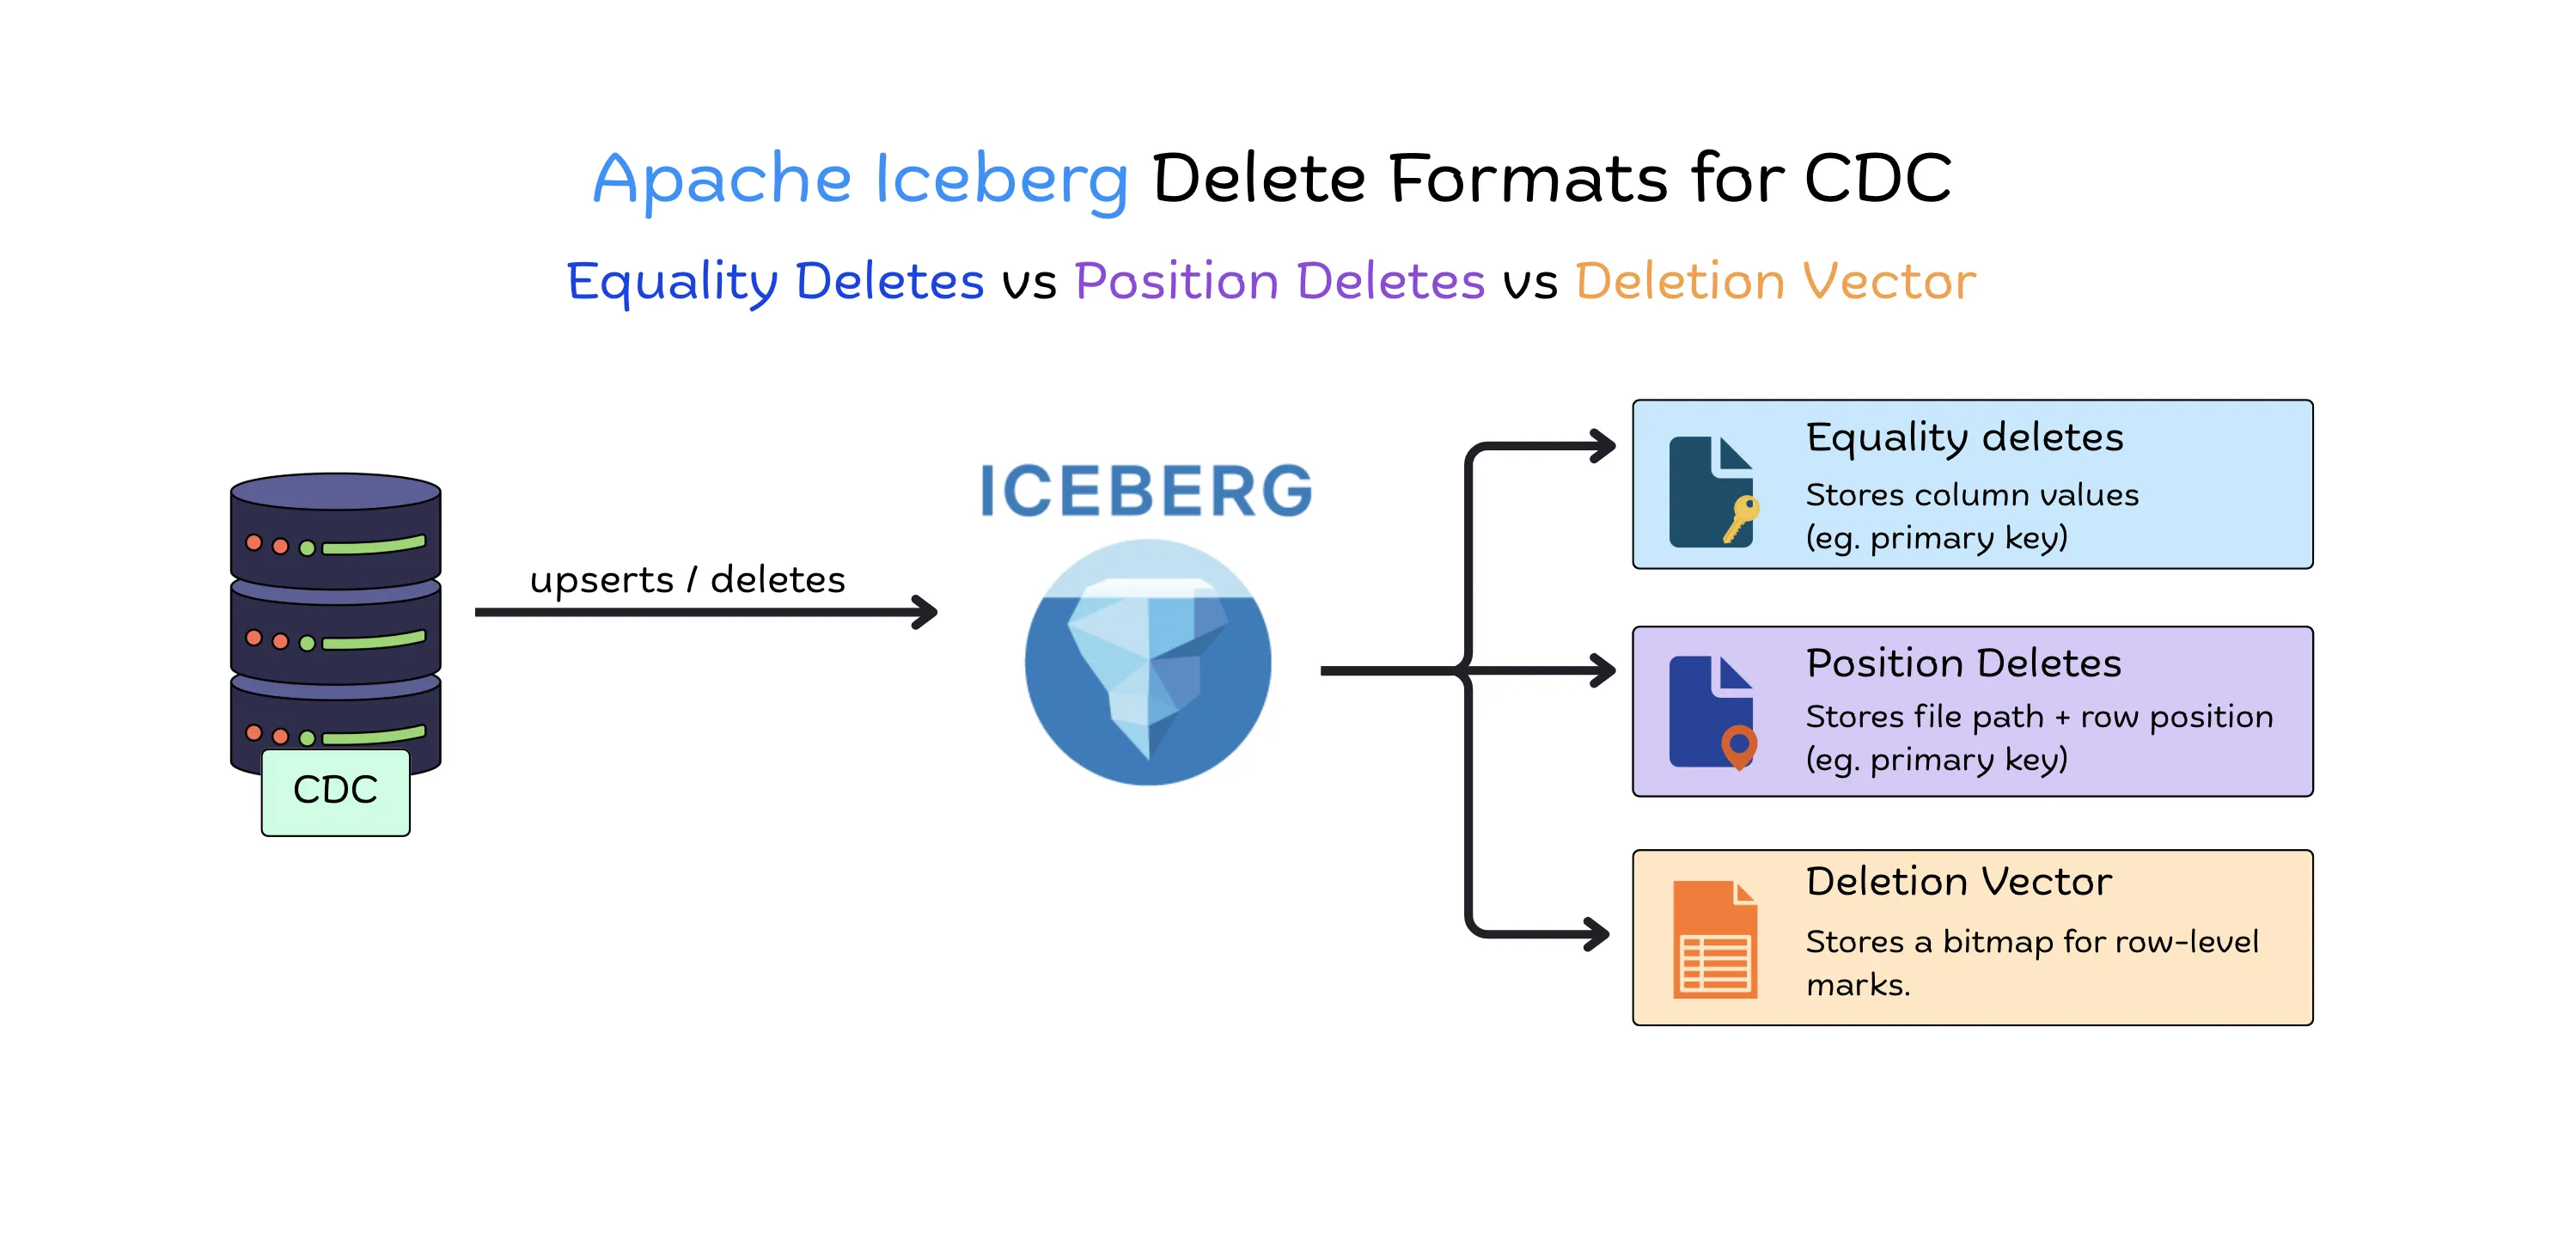
Equality deletes, position deletes, and deletion vectors compared for CDC pipelines: what each stores, which query engines can read them, what compaction fixes, and the table properties to set explicitly.
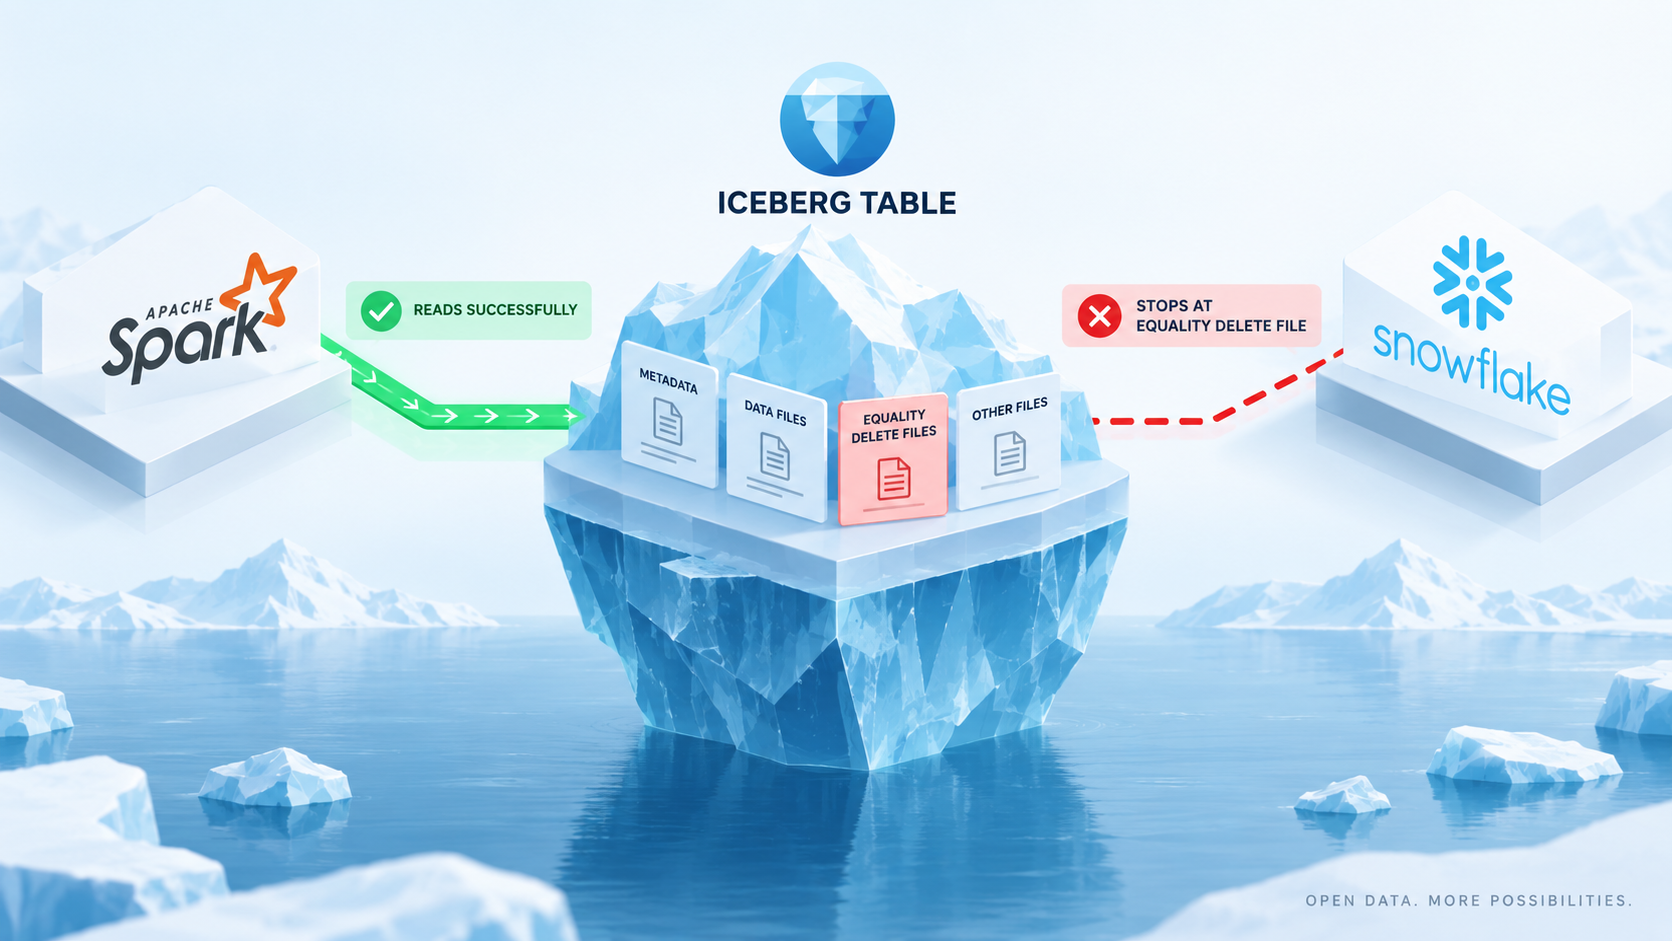
The Iceberg interoperability myth: how row-level delete support can leave a table readable in Spark but not in Snowflake, on the same catalog and data.