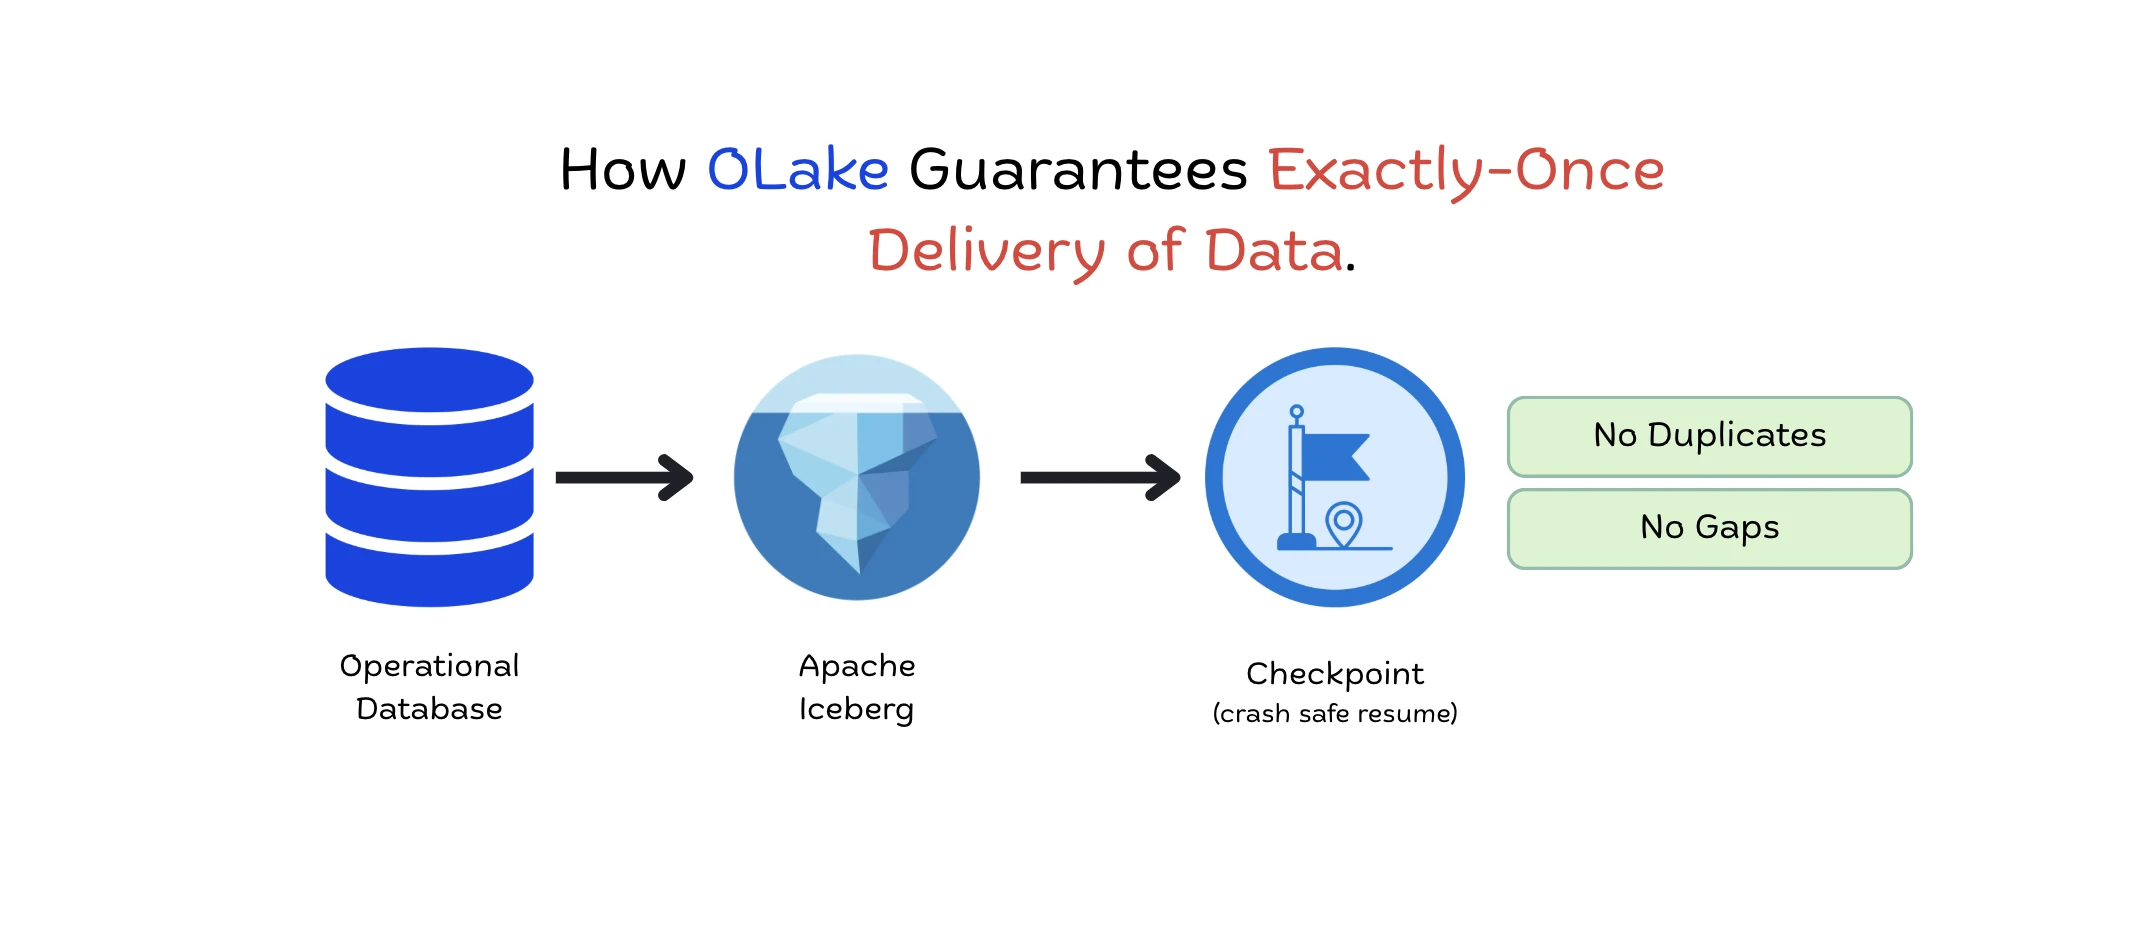
How OLake Go Guarantees Exactly-Once Delivery to Apache Iceberg
How OLake Go delivers exactly-once data into Apache Iceberg across Full Refresh, Incremental and CDC syncs, using atomic commits and checkpoint recovery.
Blogs on the topic Apache Iceberg
View All TagsHow OLake Go delivers exactly-once data into Apache Iceberg across Full Refresh, Incremental and CDC syncs, using atomic commits and checkpoint recovery.
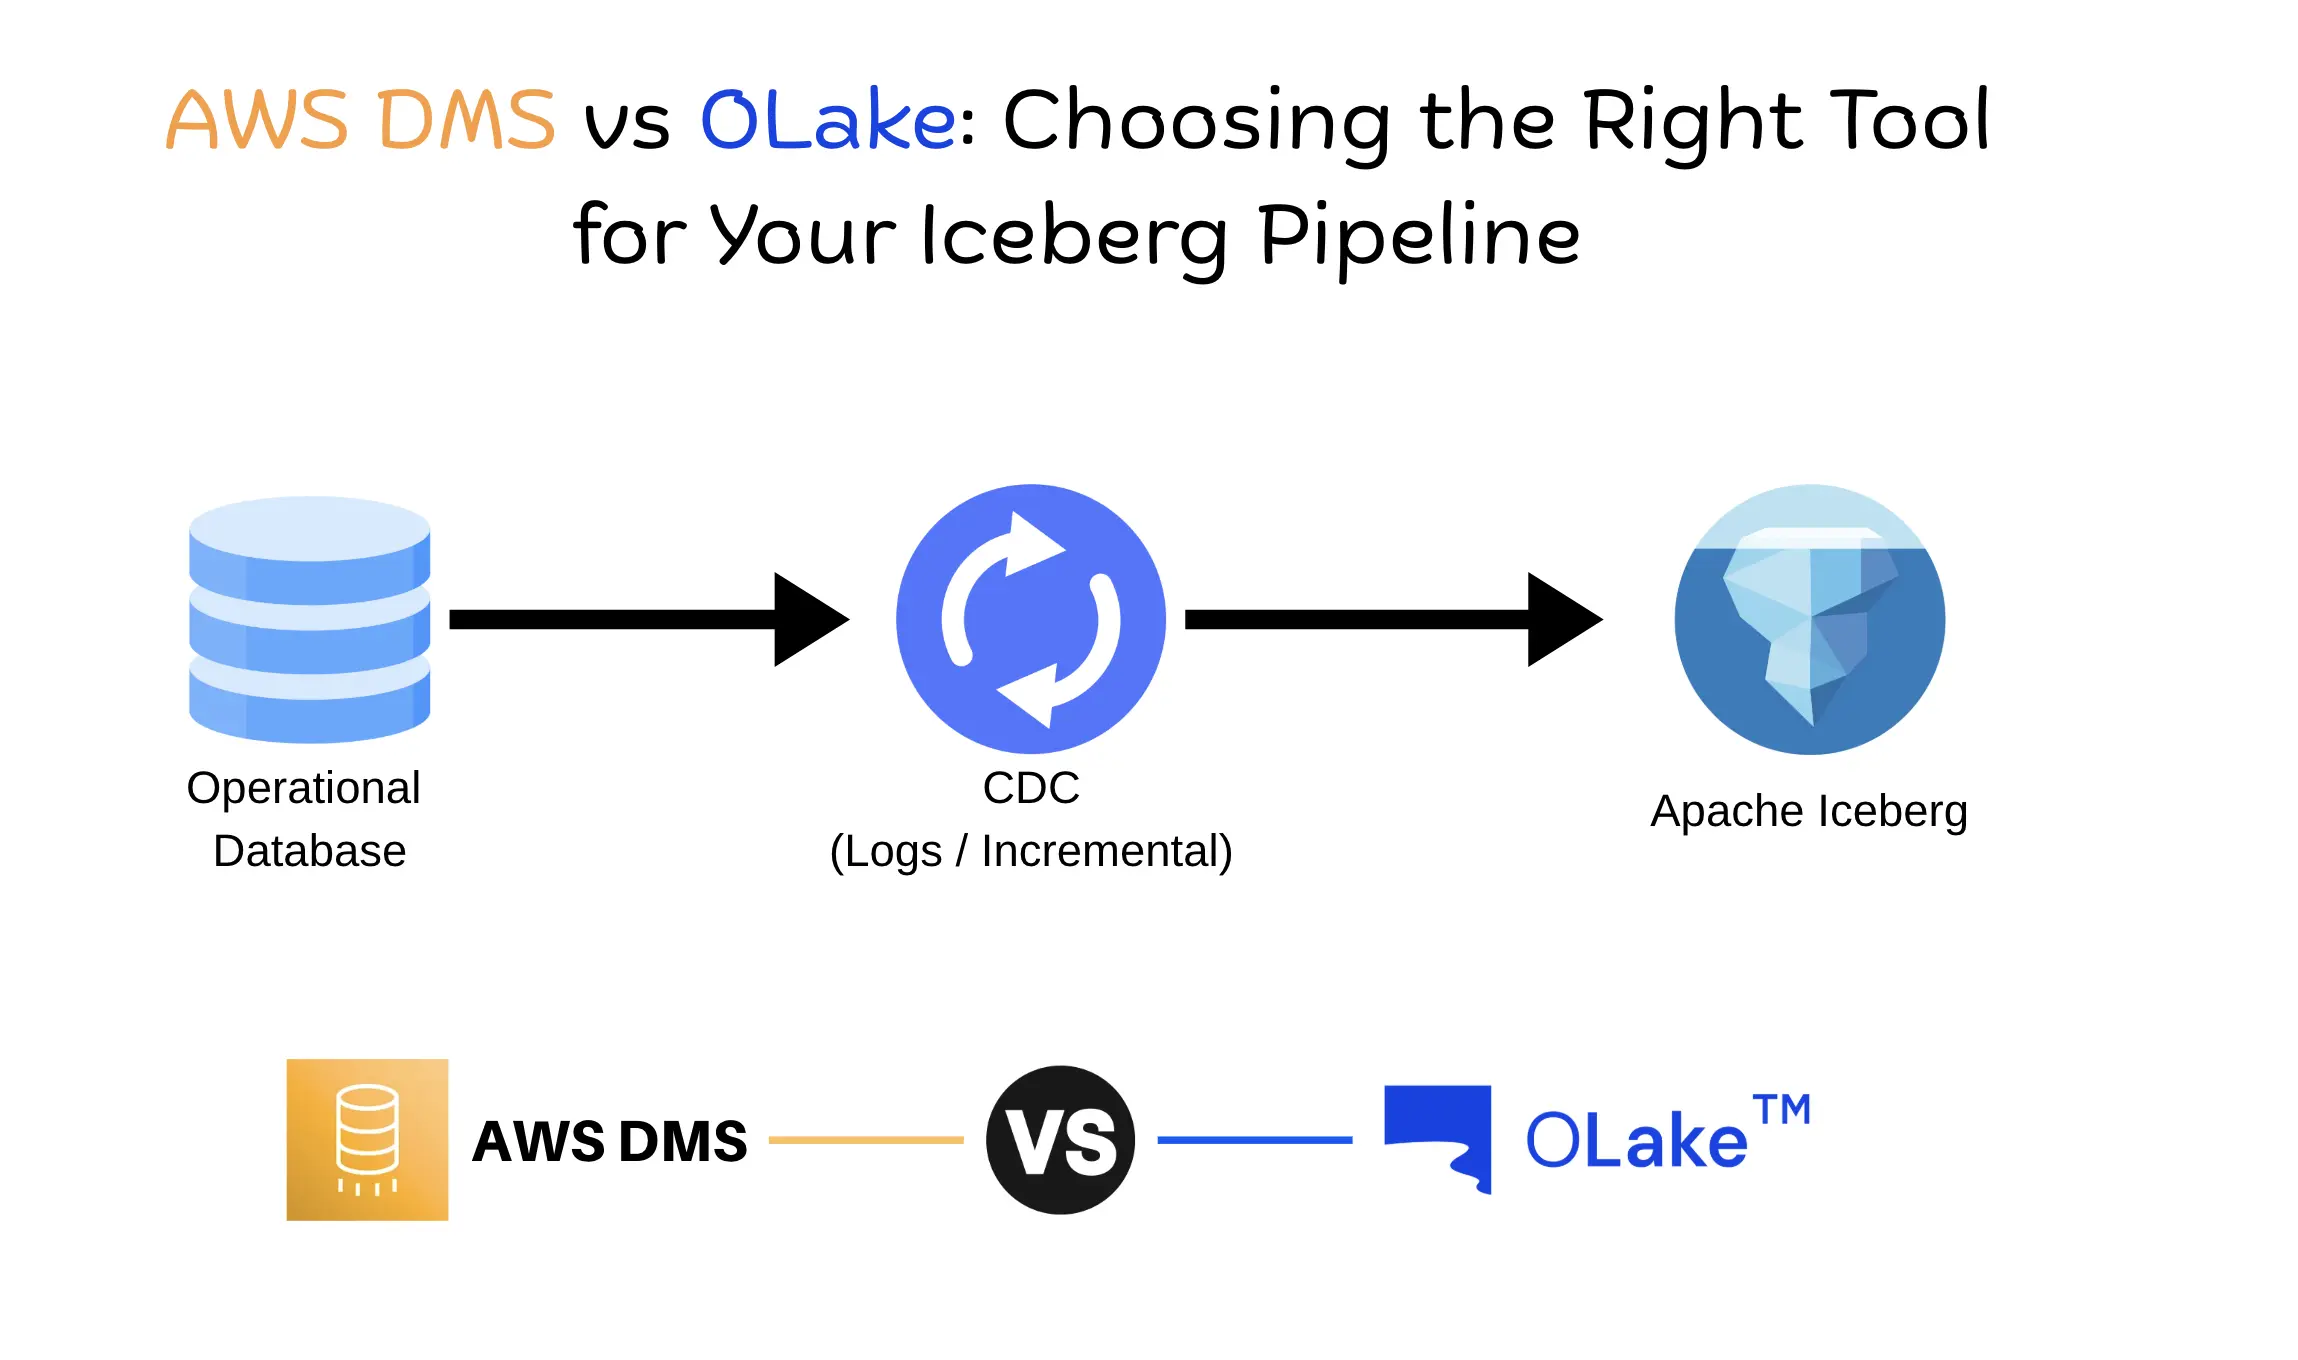
Compare AWS DMS and OLake Go for database-to-Iceberg pipelines: setup, CDC, schema evolution, scaling, and cost, with benchmark numbers on over 4 billion rows.
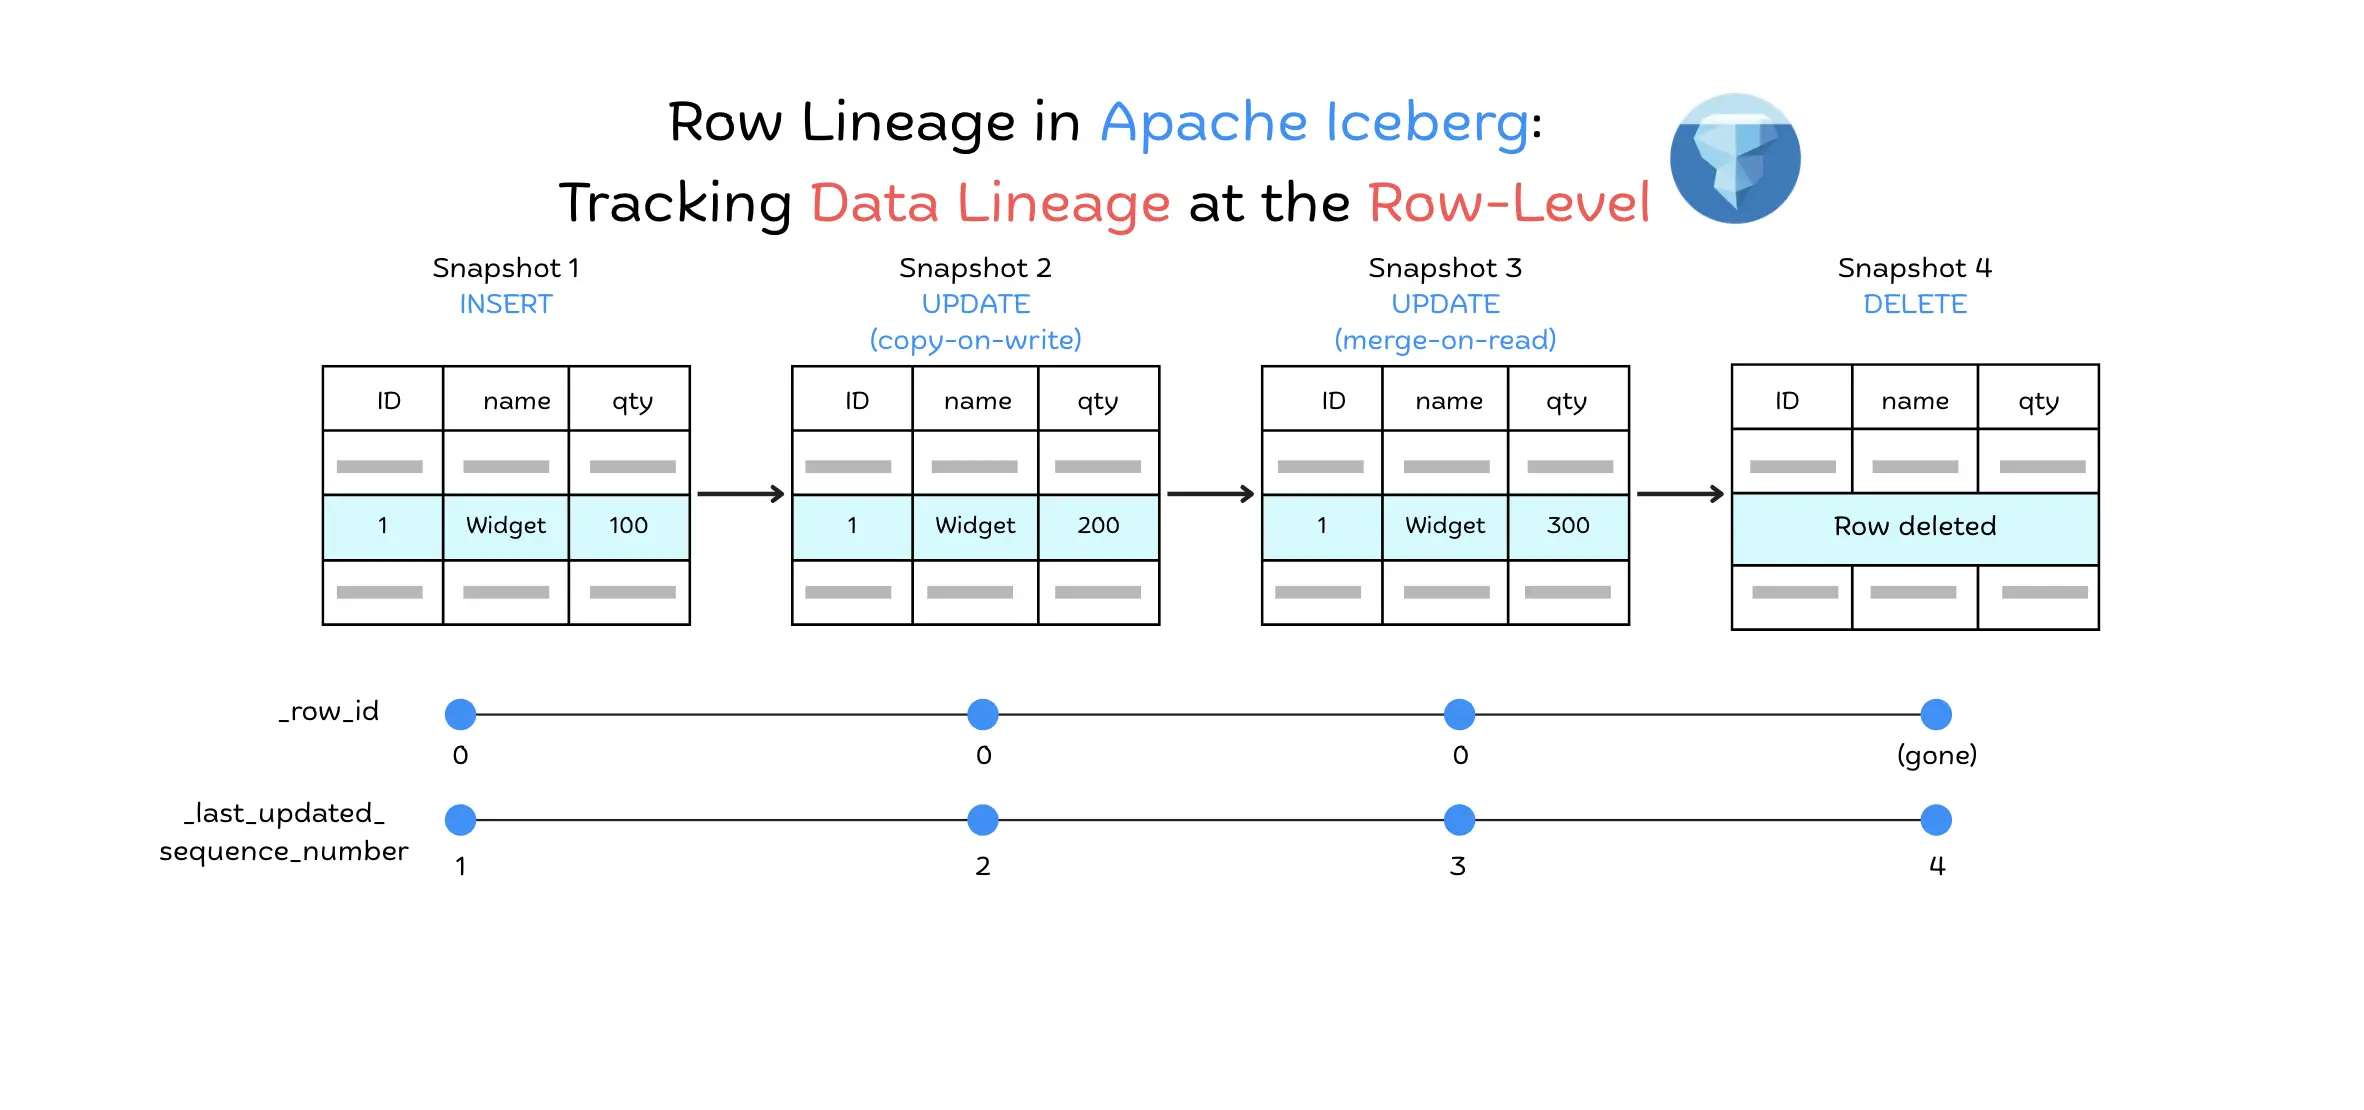
How Apache Iceberg v3 row lineage tracks row-level changes for CDC, with a tested look at _row_id preservation across Spark 3.5 and Iceberg 1.9 vs 1.10.
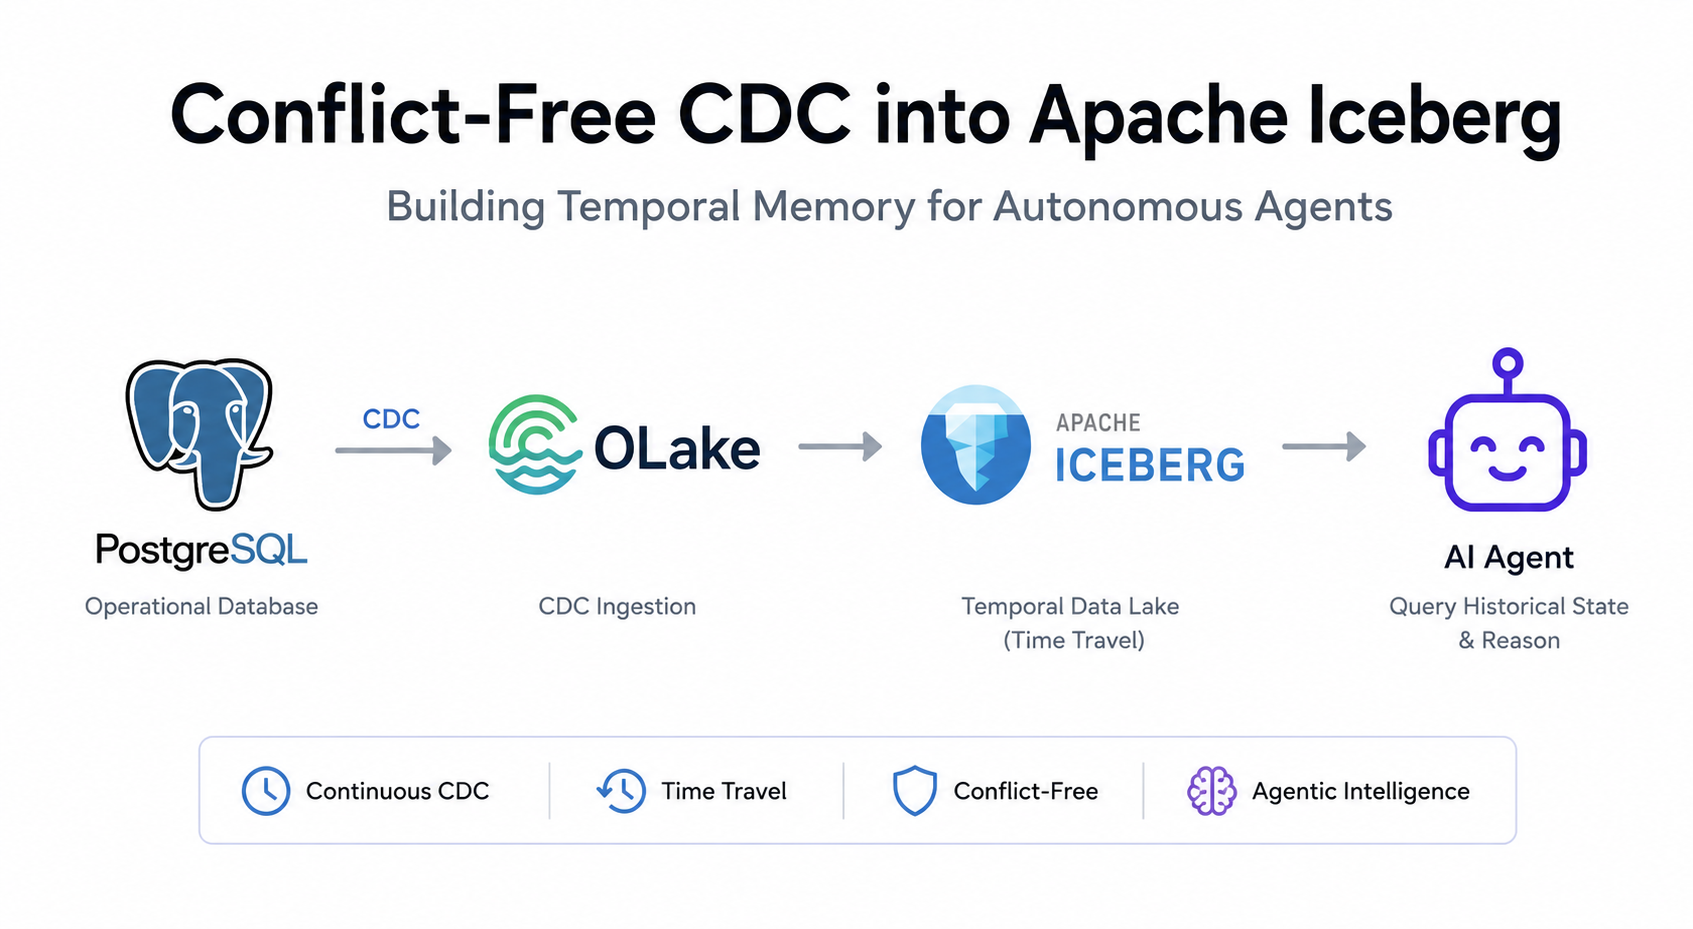
Conflict-free CDC into Apache Iceberg for AI agents: build temporal memory with OLake and ClickHouse and get past the Iceberg read amplification wall.
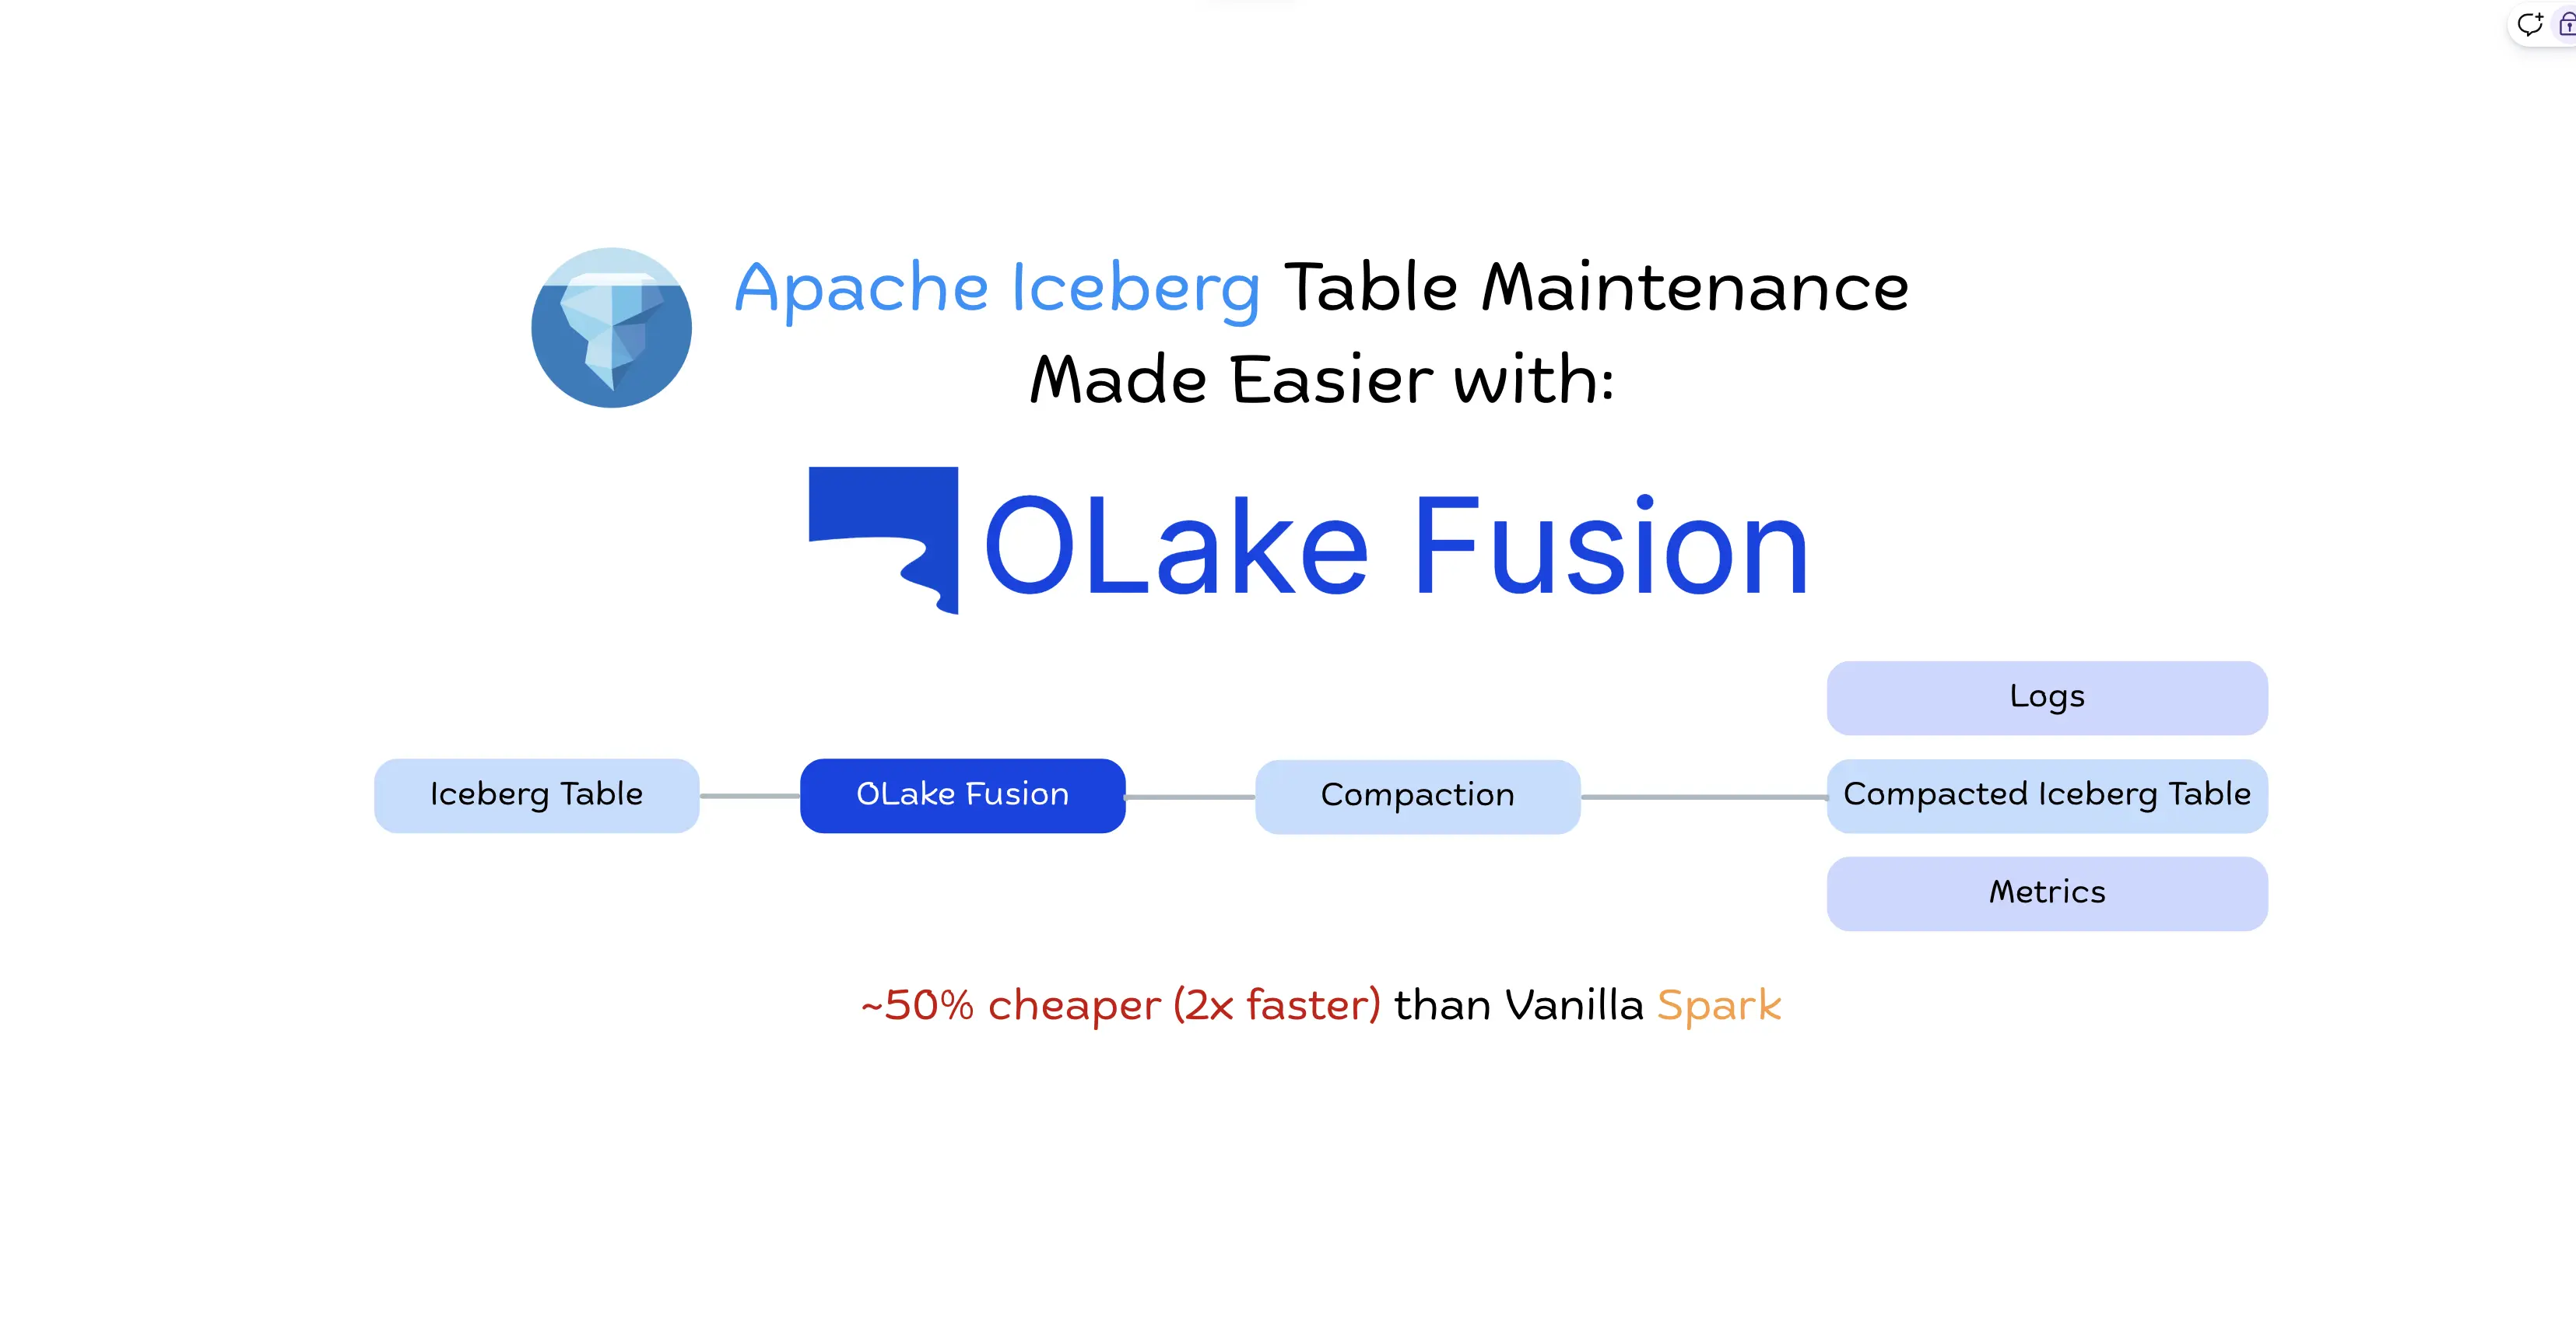
OLake Fusion handles Apache Iceberg table maintenance for CDC tables: tiered compaction for small and delete files, health metrics and lower Spark cost.
We benchmark Spark rewrite_data_files against OLake Fusion compaction on Apache Iceberg by running a full TPCH lineitem load from Postgres to GCP, applying 200k-record CDC batches every 2 minutes, and tracking TPC-H Query 6 performance, runtime, resource usage, and infrastructure cost.