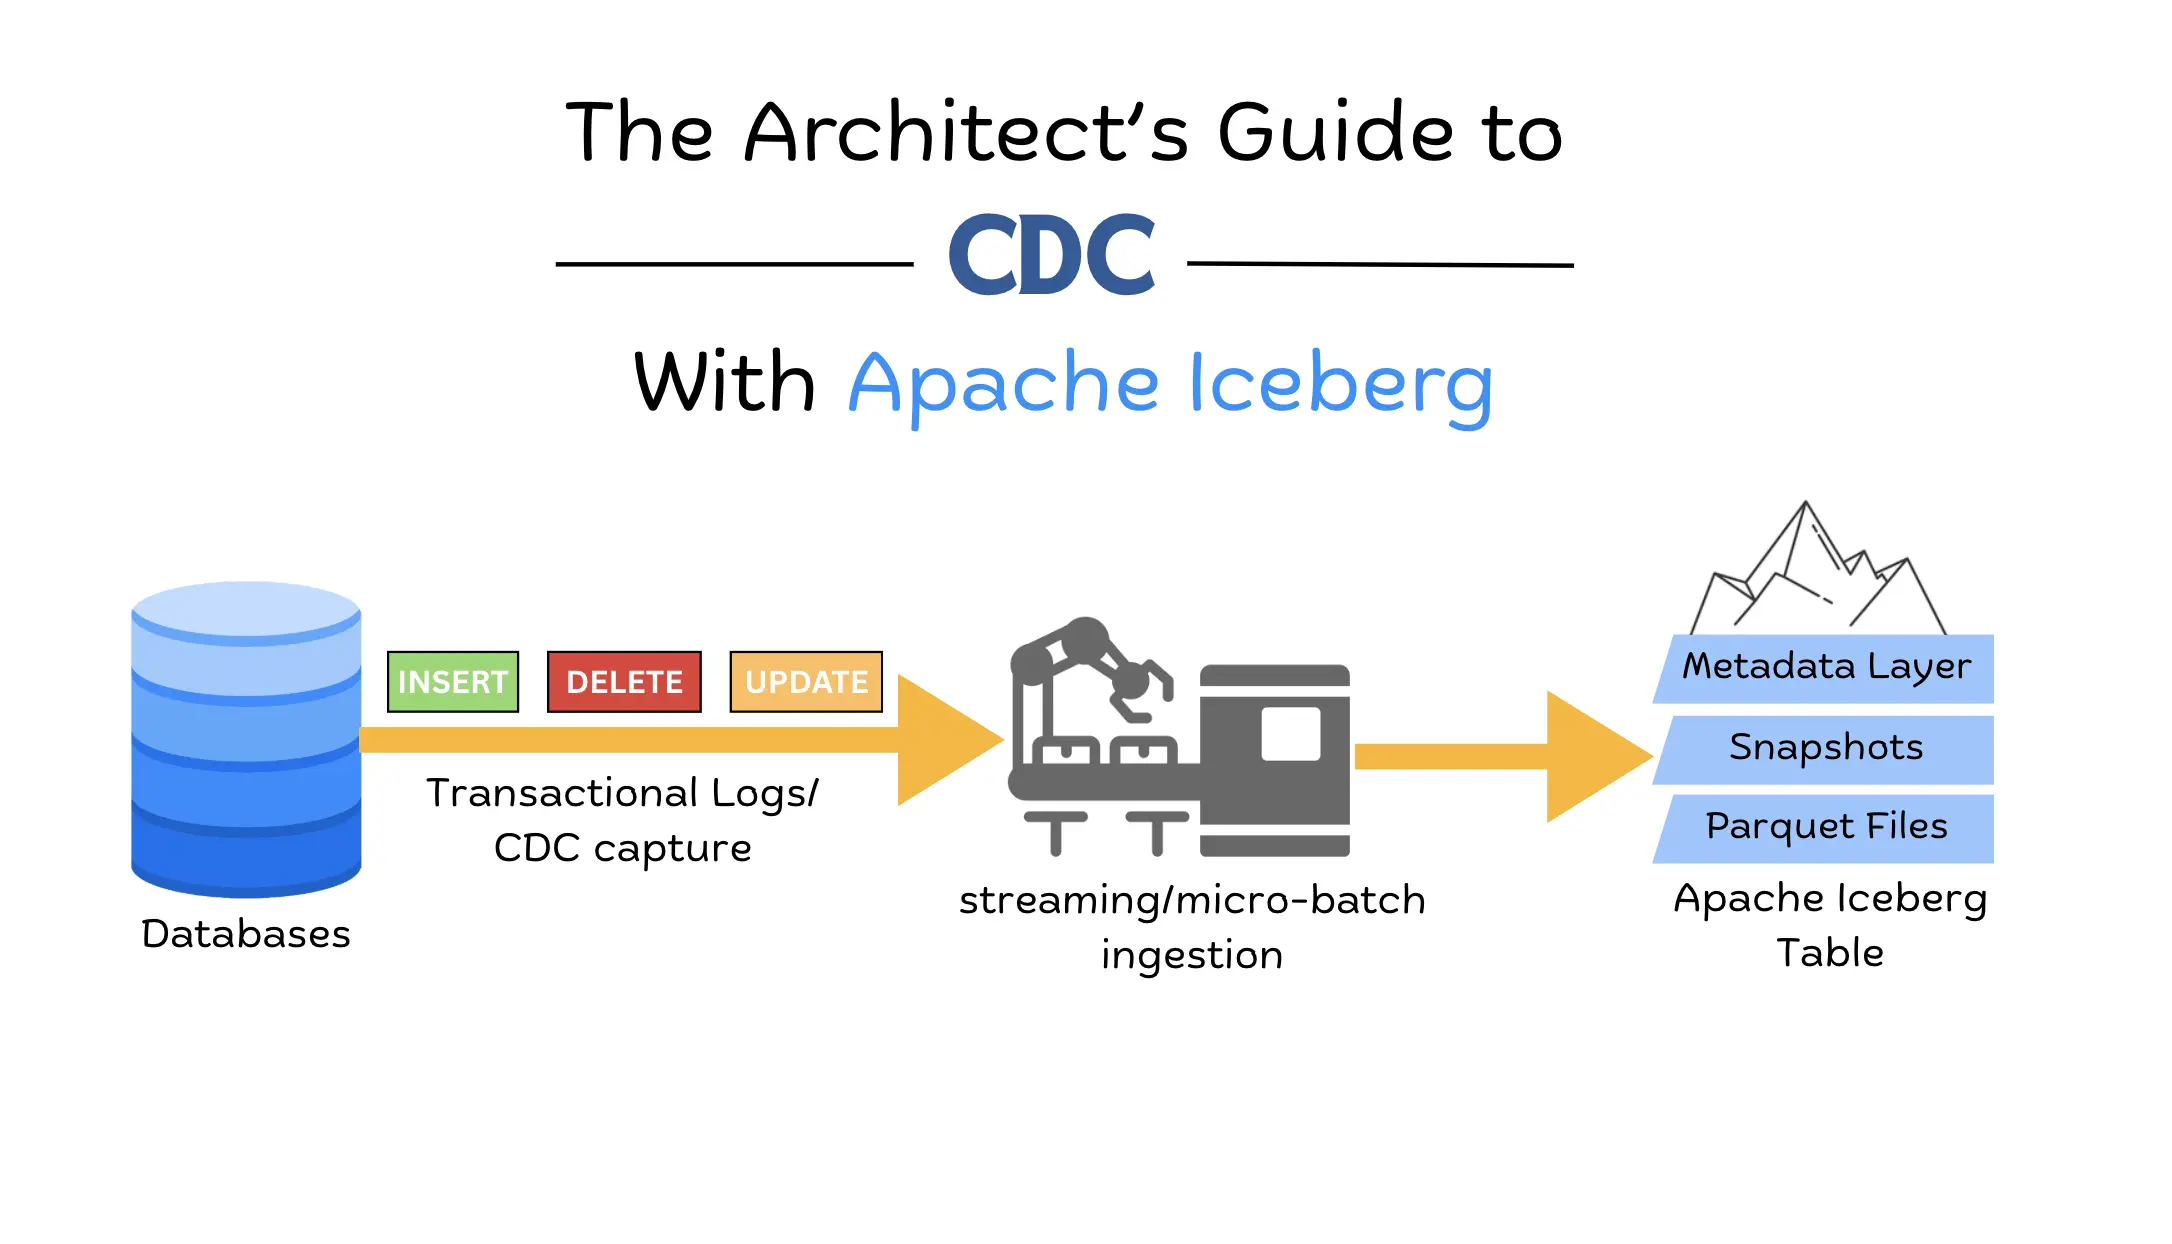
The Architect’s Guide to CDC with Apache Iceberg
Learn how to design reliable CDC pipelines into Apache Iceberg, covering ingestion patterns, delete handling, and architecture best practices.
Blogs on the topic Apache Iceberg
View All TagsLearn how to design reliable CDC pipelines into Apache Iceberg, covering ingestion patterns, delete handling, and architecture best practices.
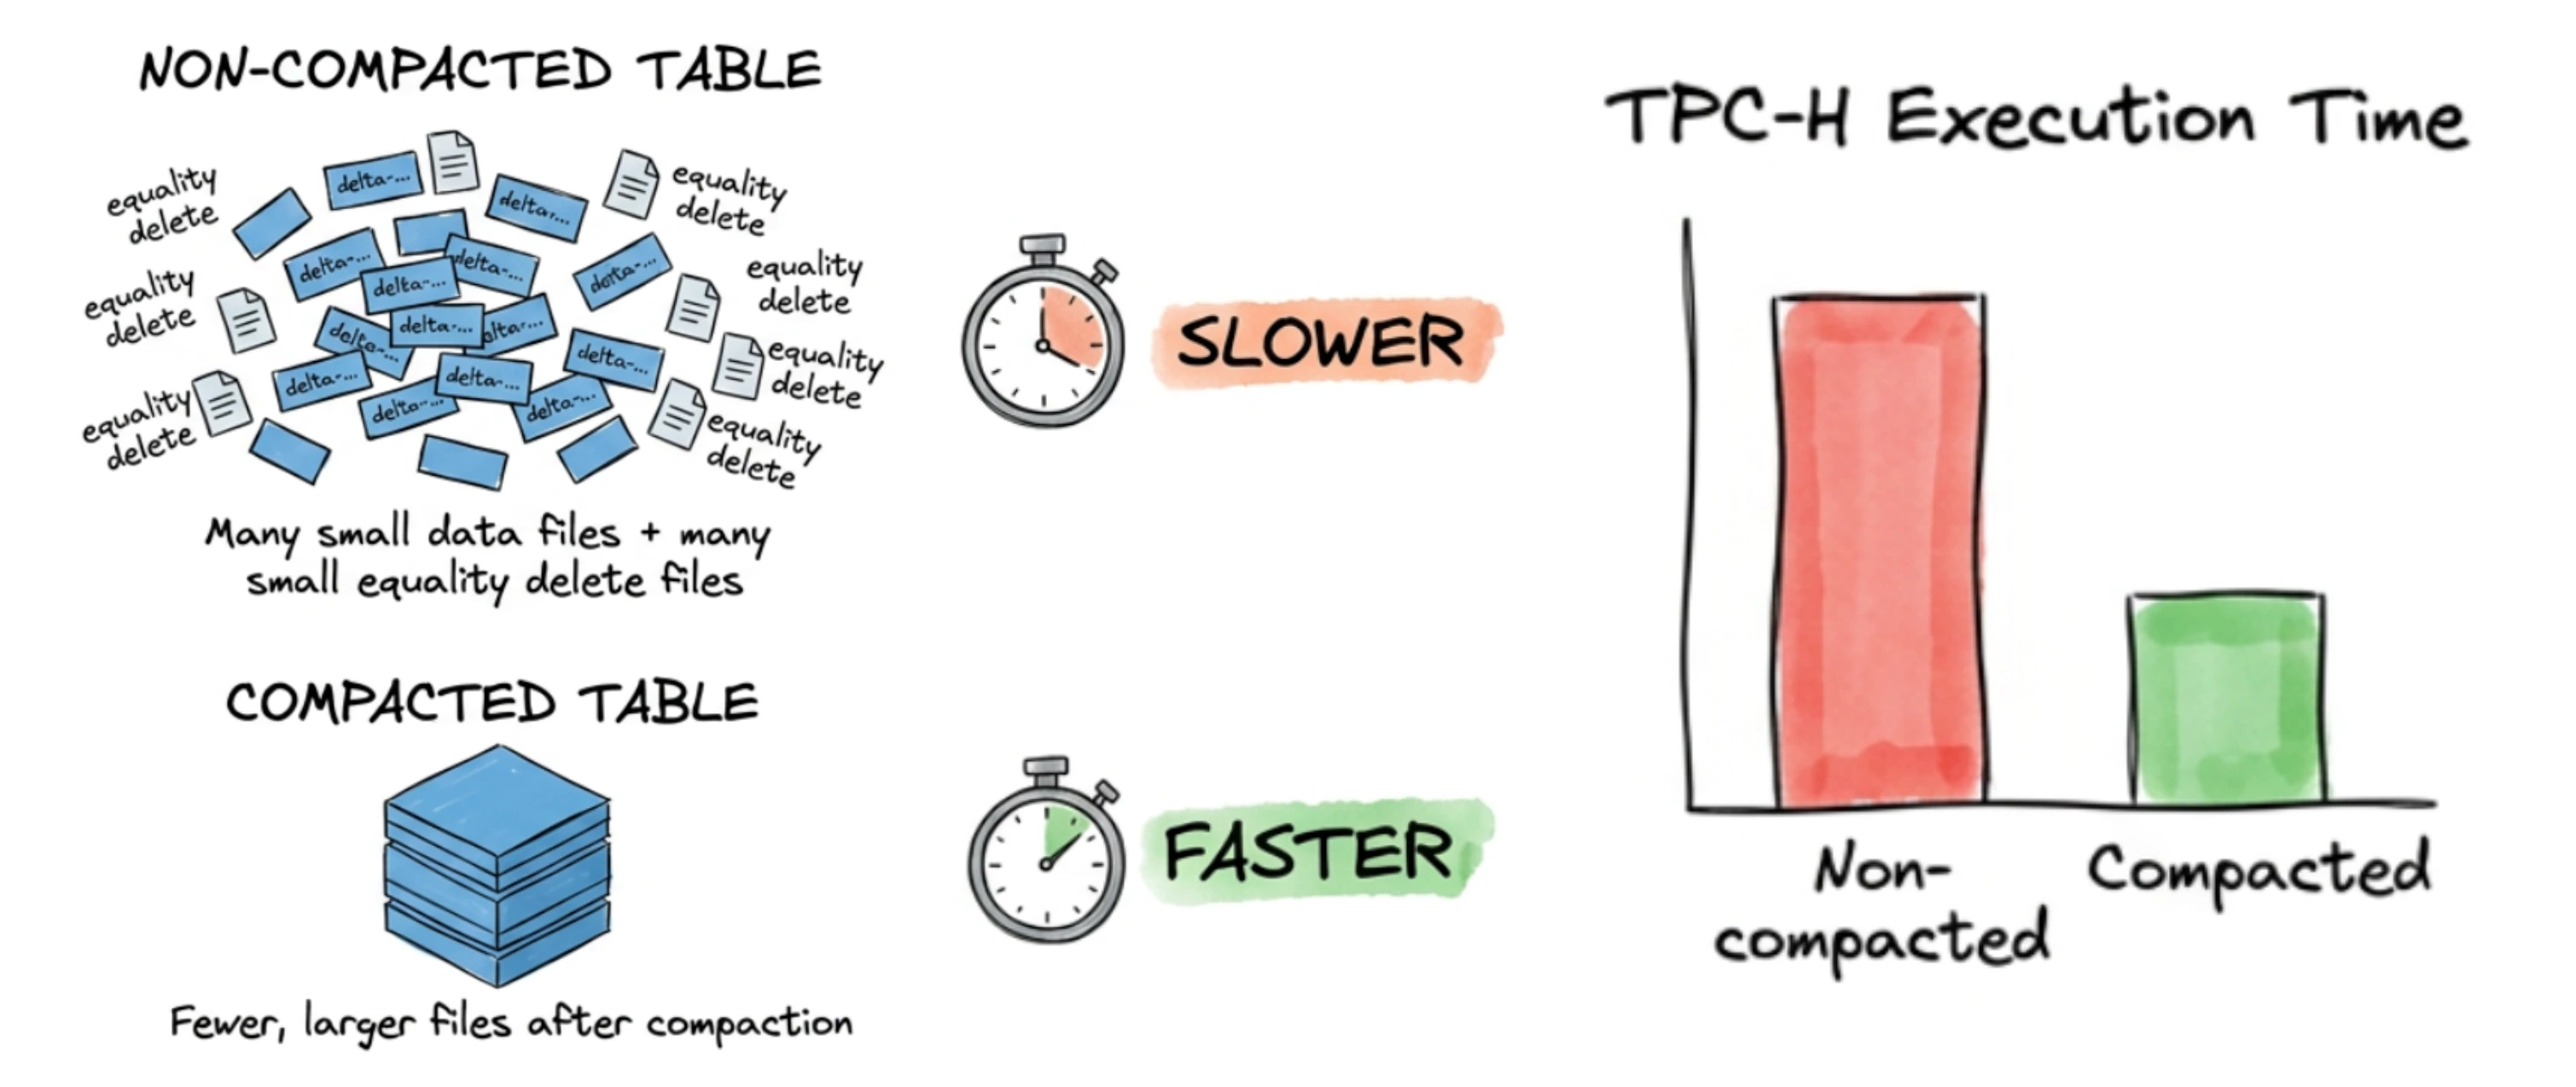
We ran TPC-H queries on Iceberg tables with many small files, then compacted them and ran the same queries again. Here's how much faster compaction made them.

Apache Iceberg observability: use metadata tables to monitor file counts, table growth and schema changes, then add alerts and metrics reporters.
Sync IBM Db2 LUW to Apache Iceberg with OLake Go: setup, configuration, sync modes, troubleshooting, and Db2 specifics like RUNSTATS and REORG.
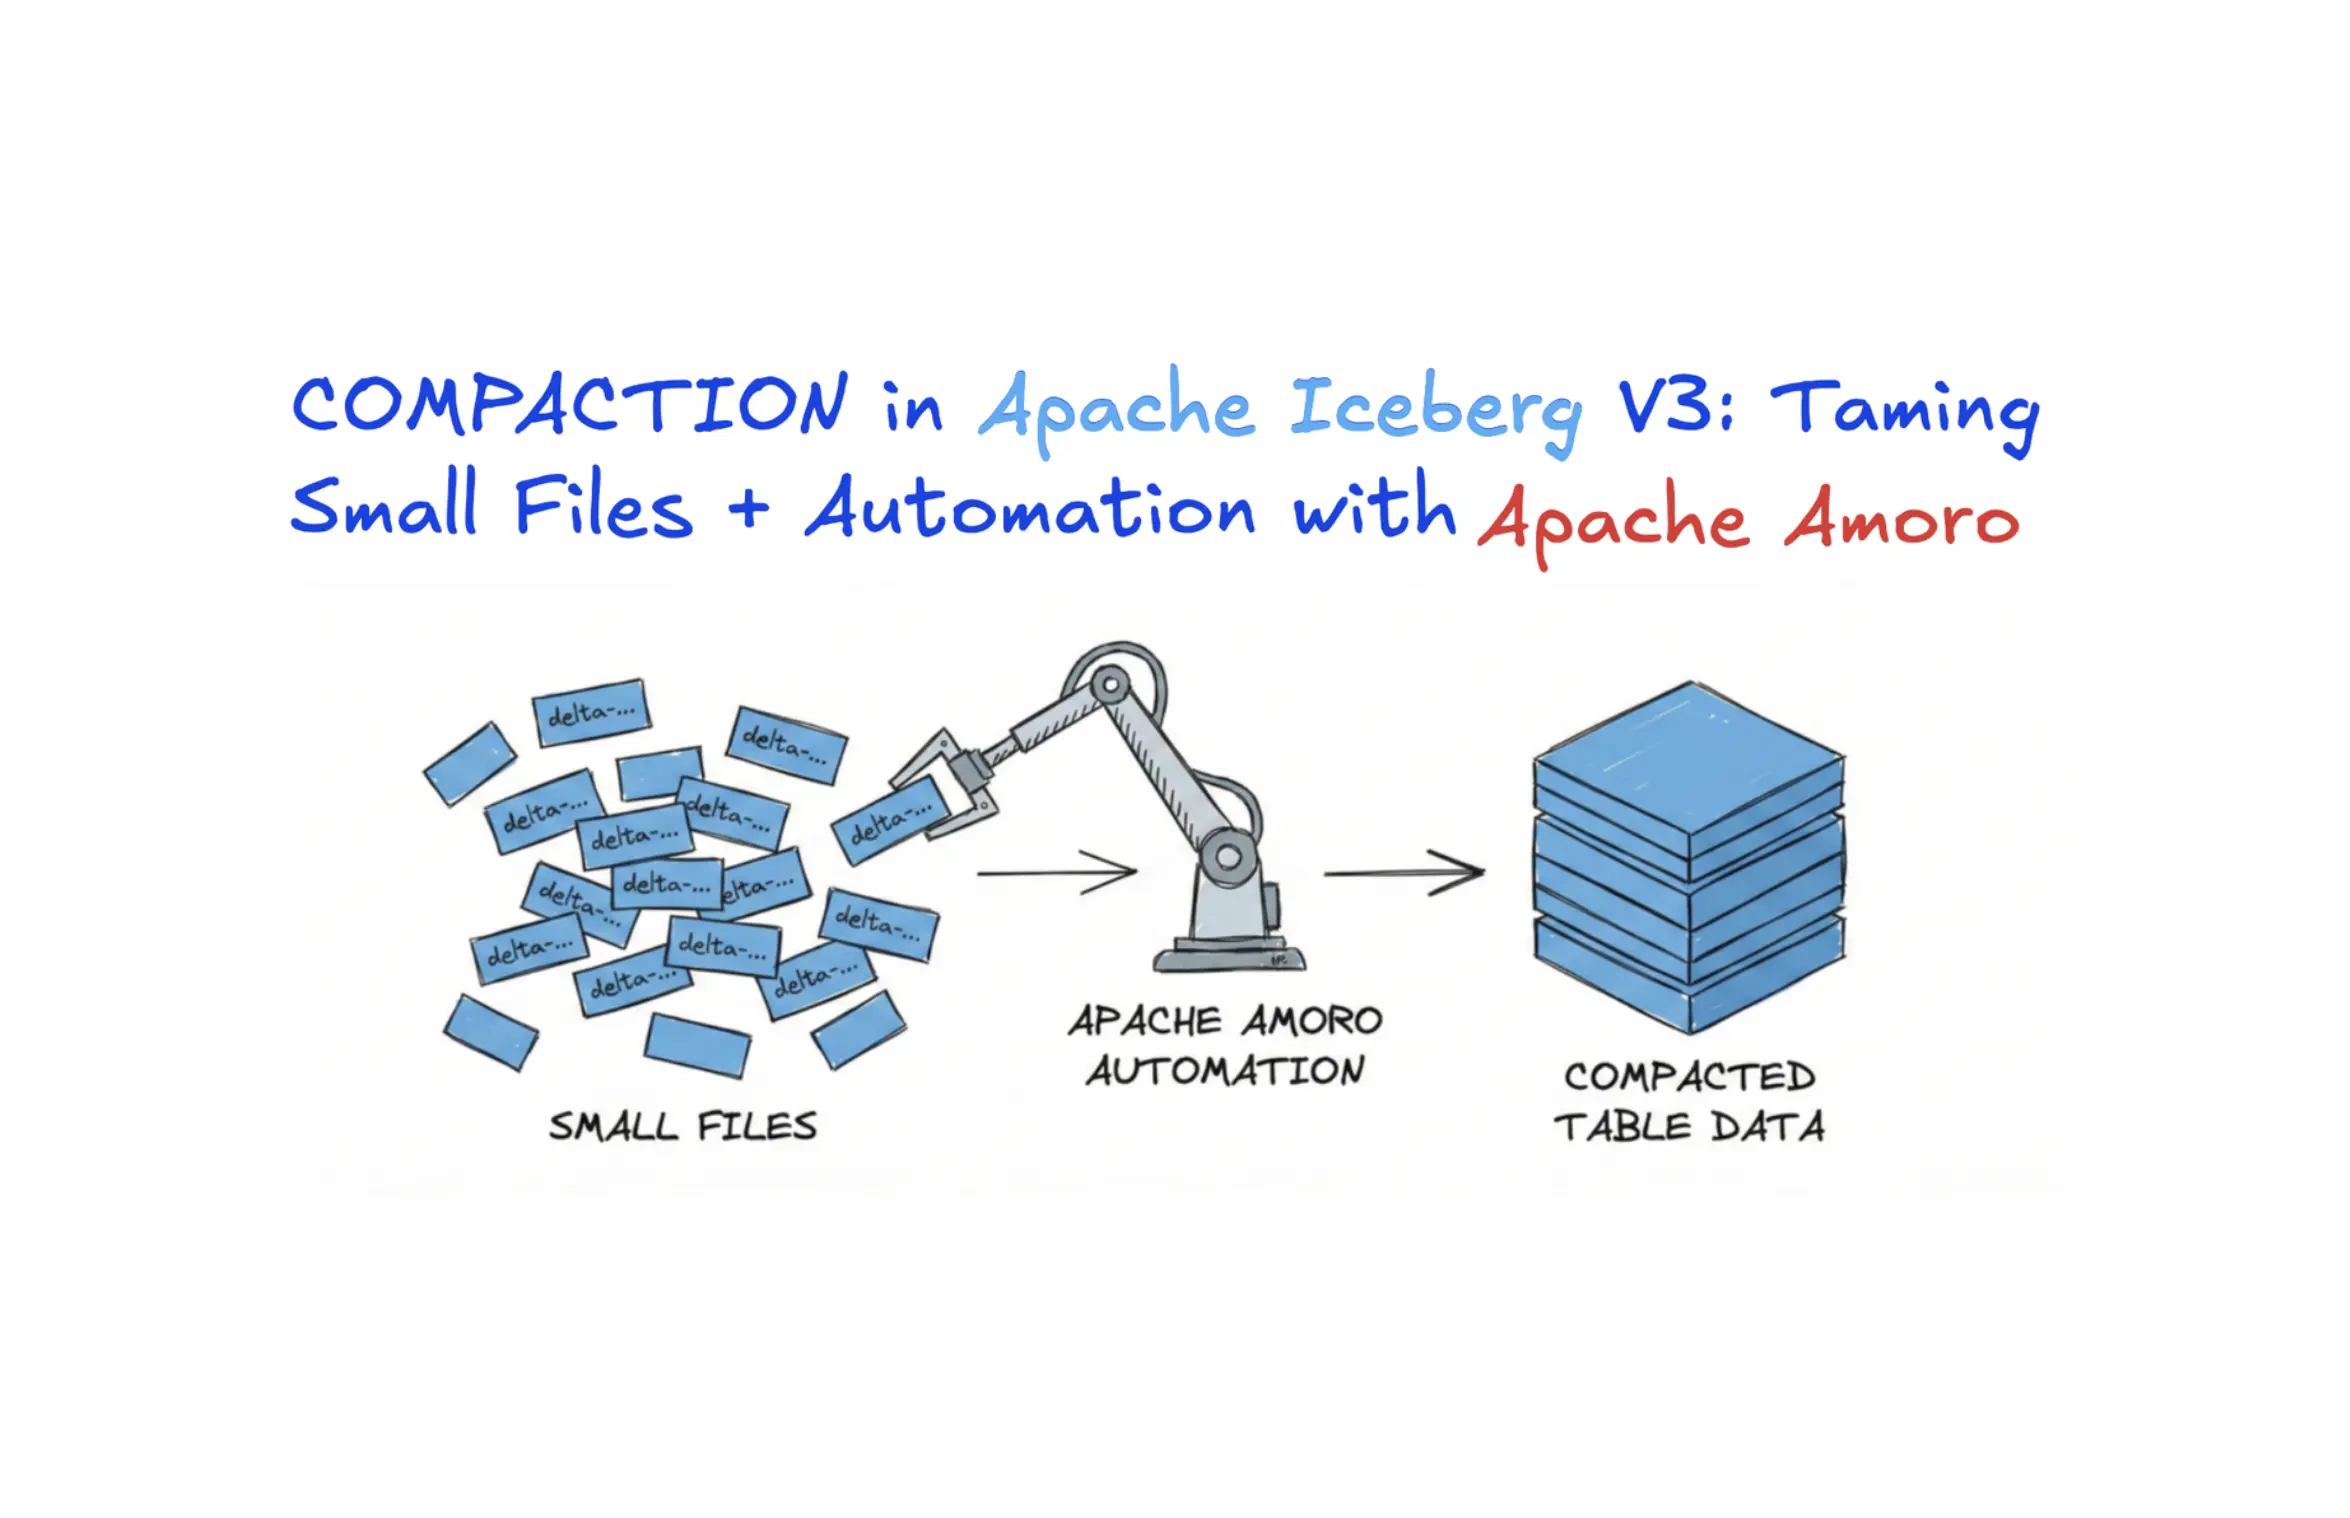
How to compact Apache Iceberg tables: fix small-file bloat, see when to run compaction and what gains to expect, and automate it with Apache Amoro.
Sync Microsoft SQL Server (MSSQL) to Apache Iceberg with OLake Go: sync modes, CDC setup, schema changes, data type mapping and troubleshooting.