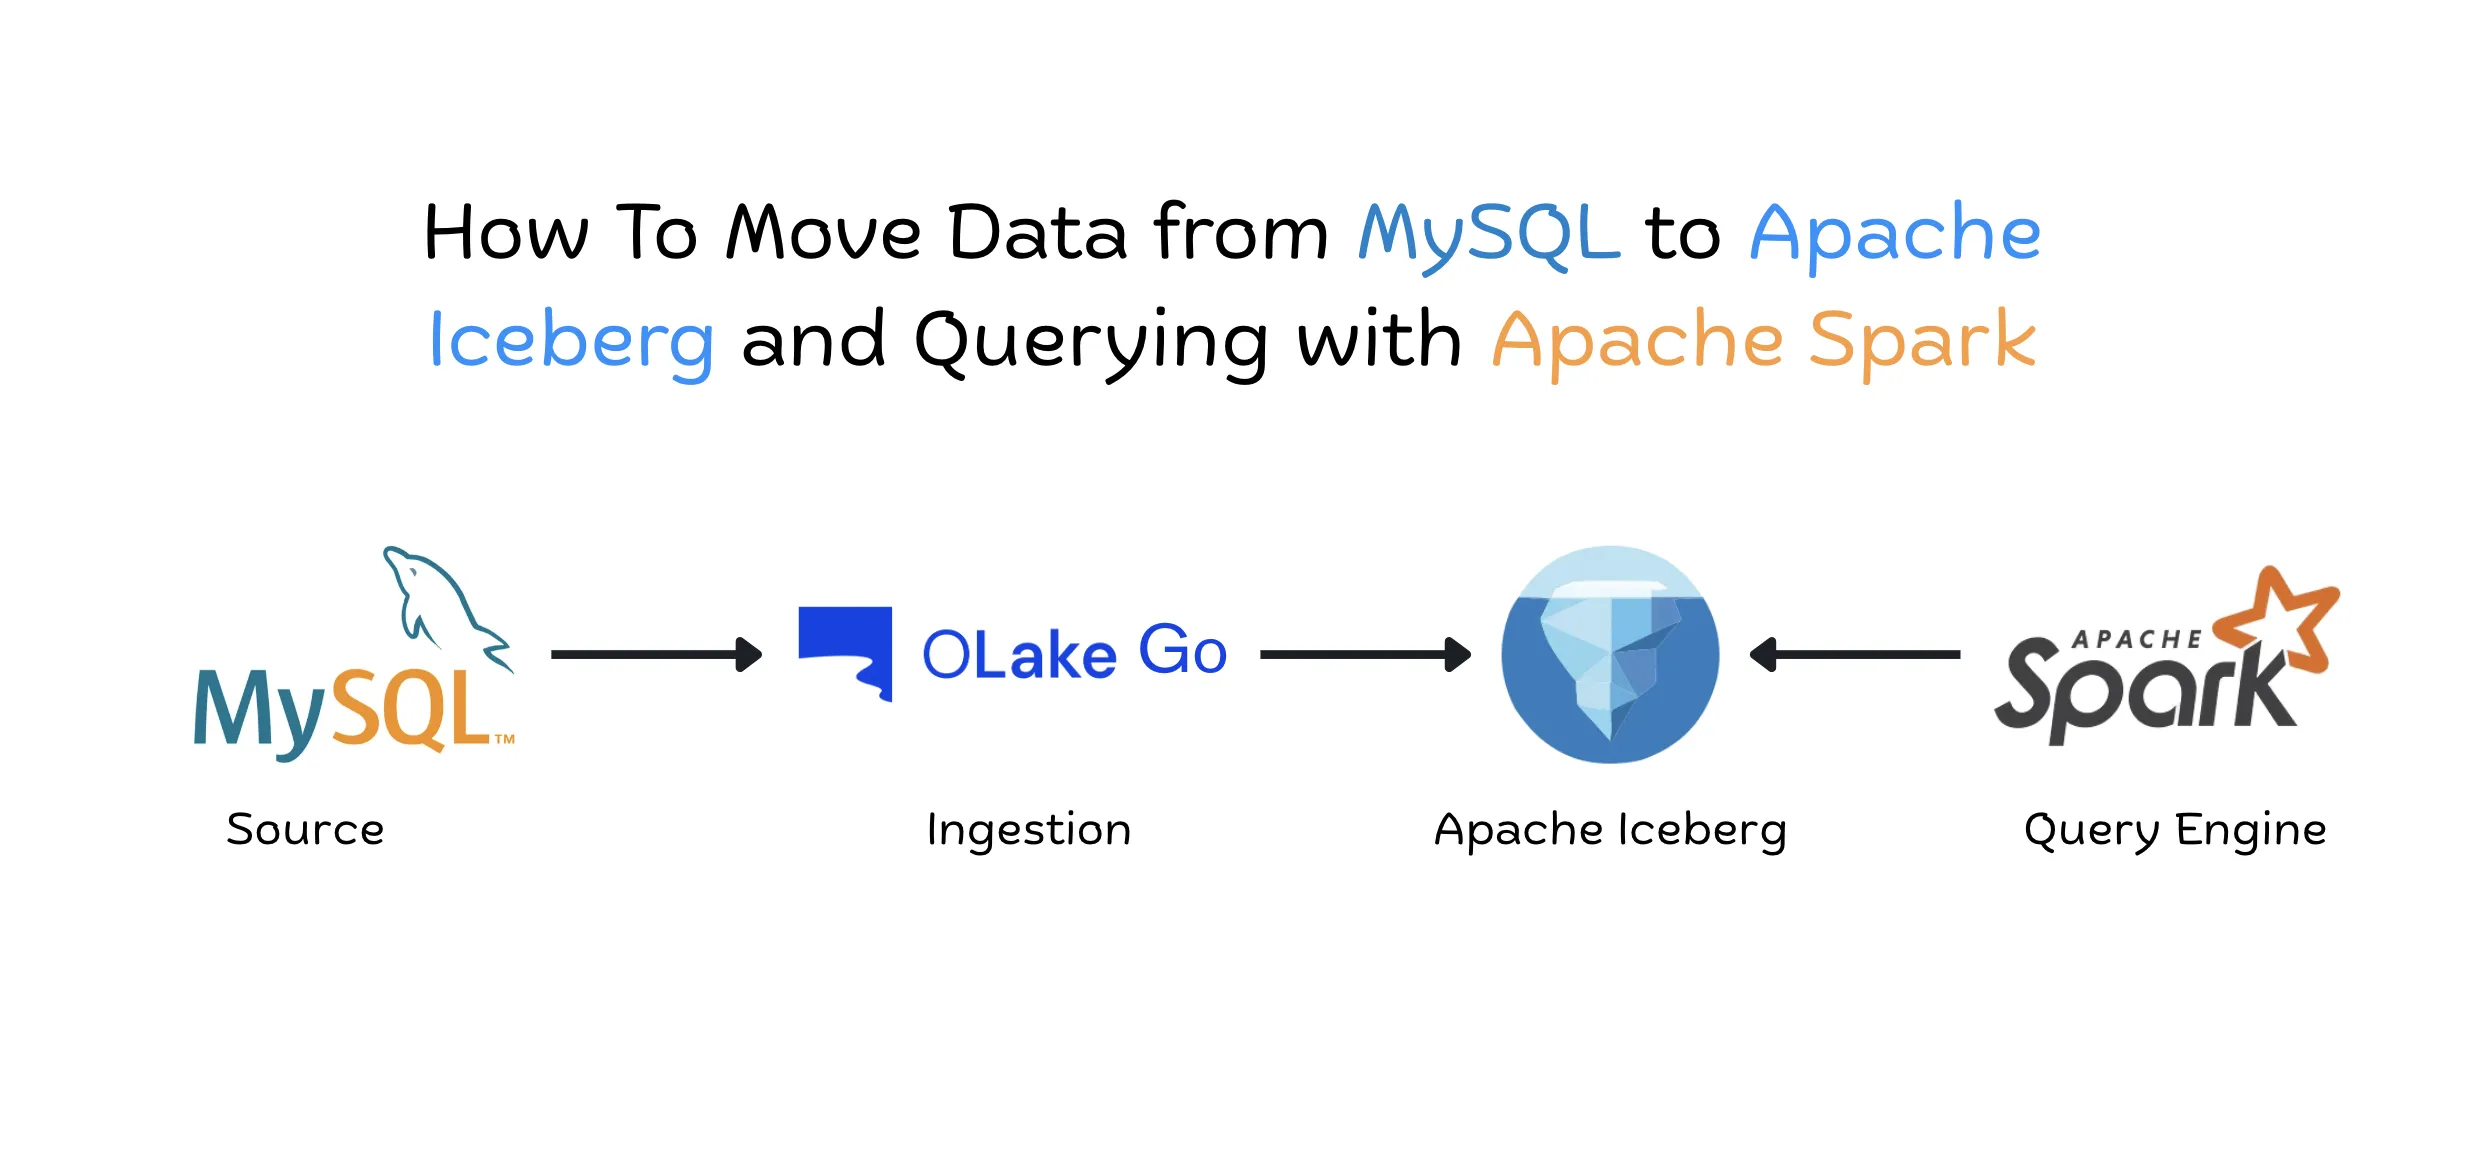
How To Move Data from MySQL to Apache Iceberg and Querying with Apache Spark
Replicate MySQL to Apache Iceberg with OLake Go and query it in Apache Spark. A step-by-step guide to setting up the source, catalog, job, sync and Spark SQL.
Blogs on the topic OLake
View All TagsReplicate MySQL to Apache Iceberg with OLake Go and query it in Apache Spark. A step-by-step guide to setting up the source, catalog, job, sync and Spark SQL.
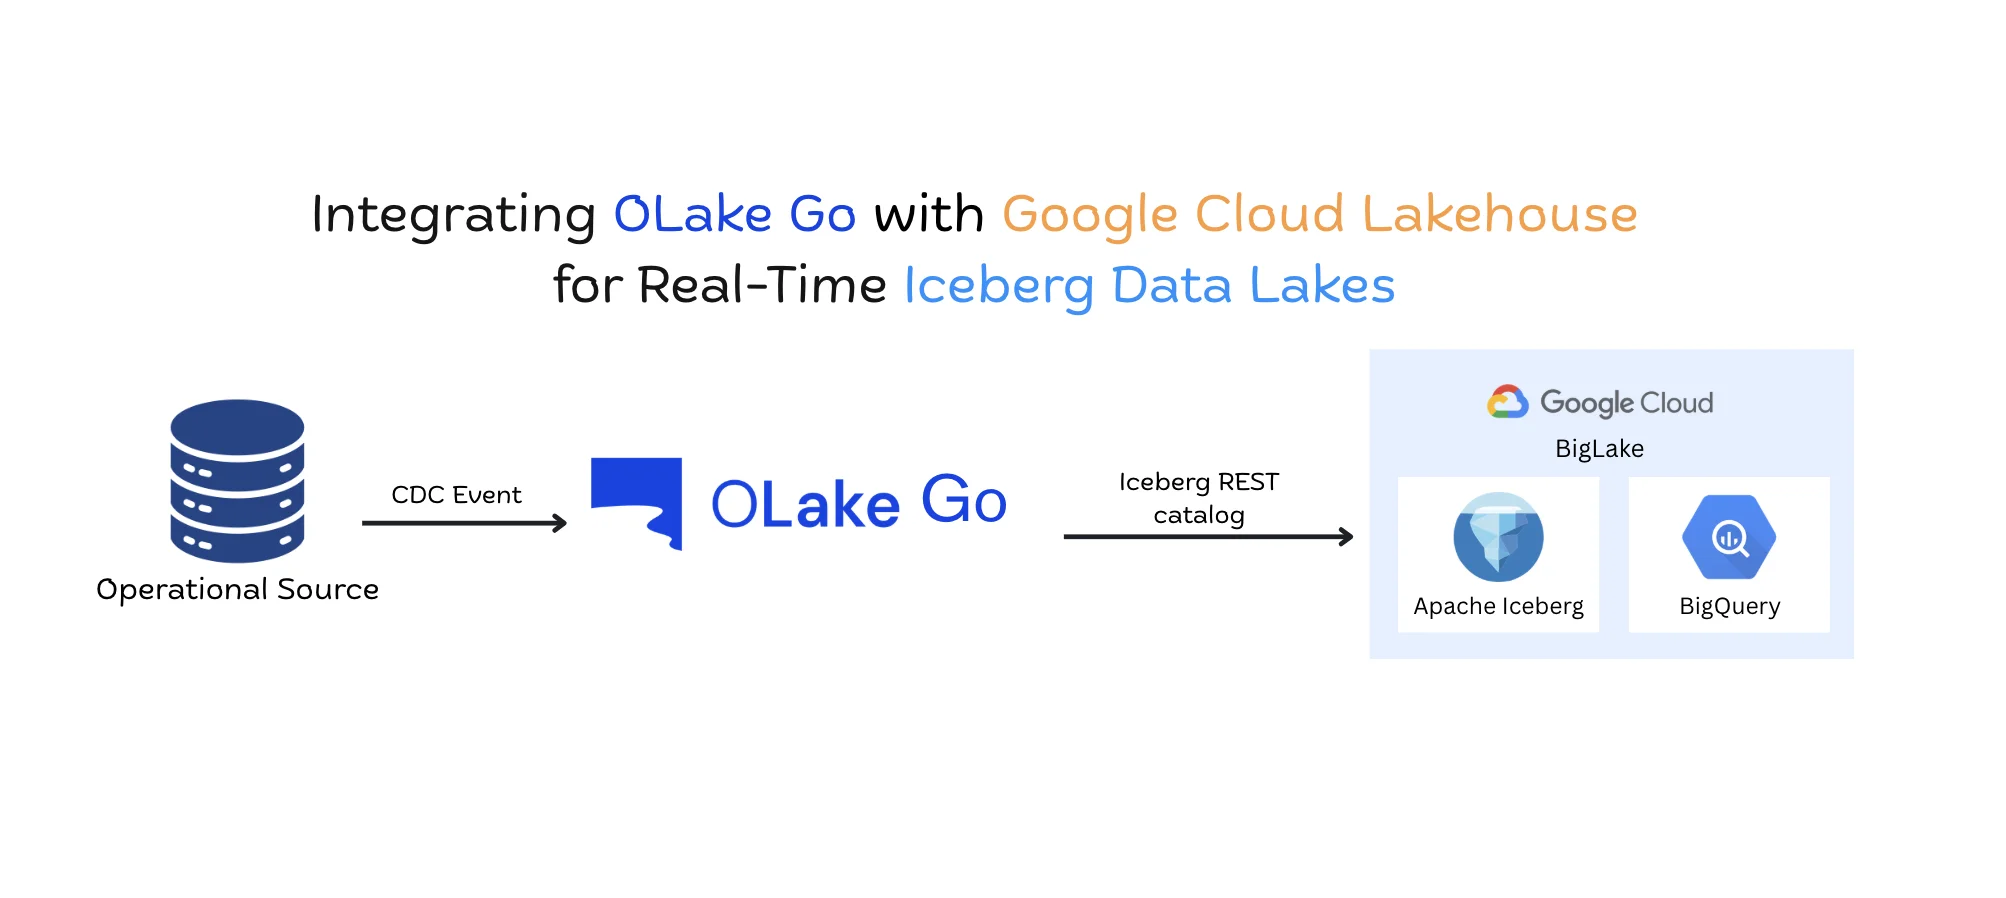
Stream Postgres CDC into Apache Iceberg tables on Google BigLake with OLake Go and query live data in BigQuery. A step-by-step setup with no Kafka or Spark.
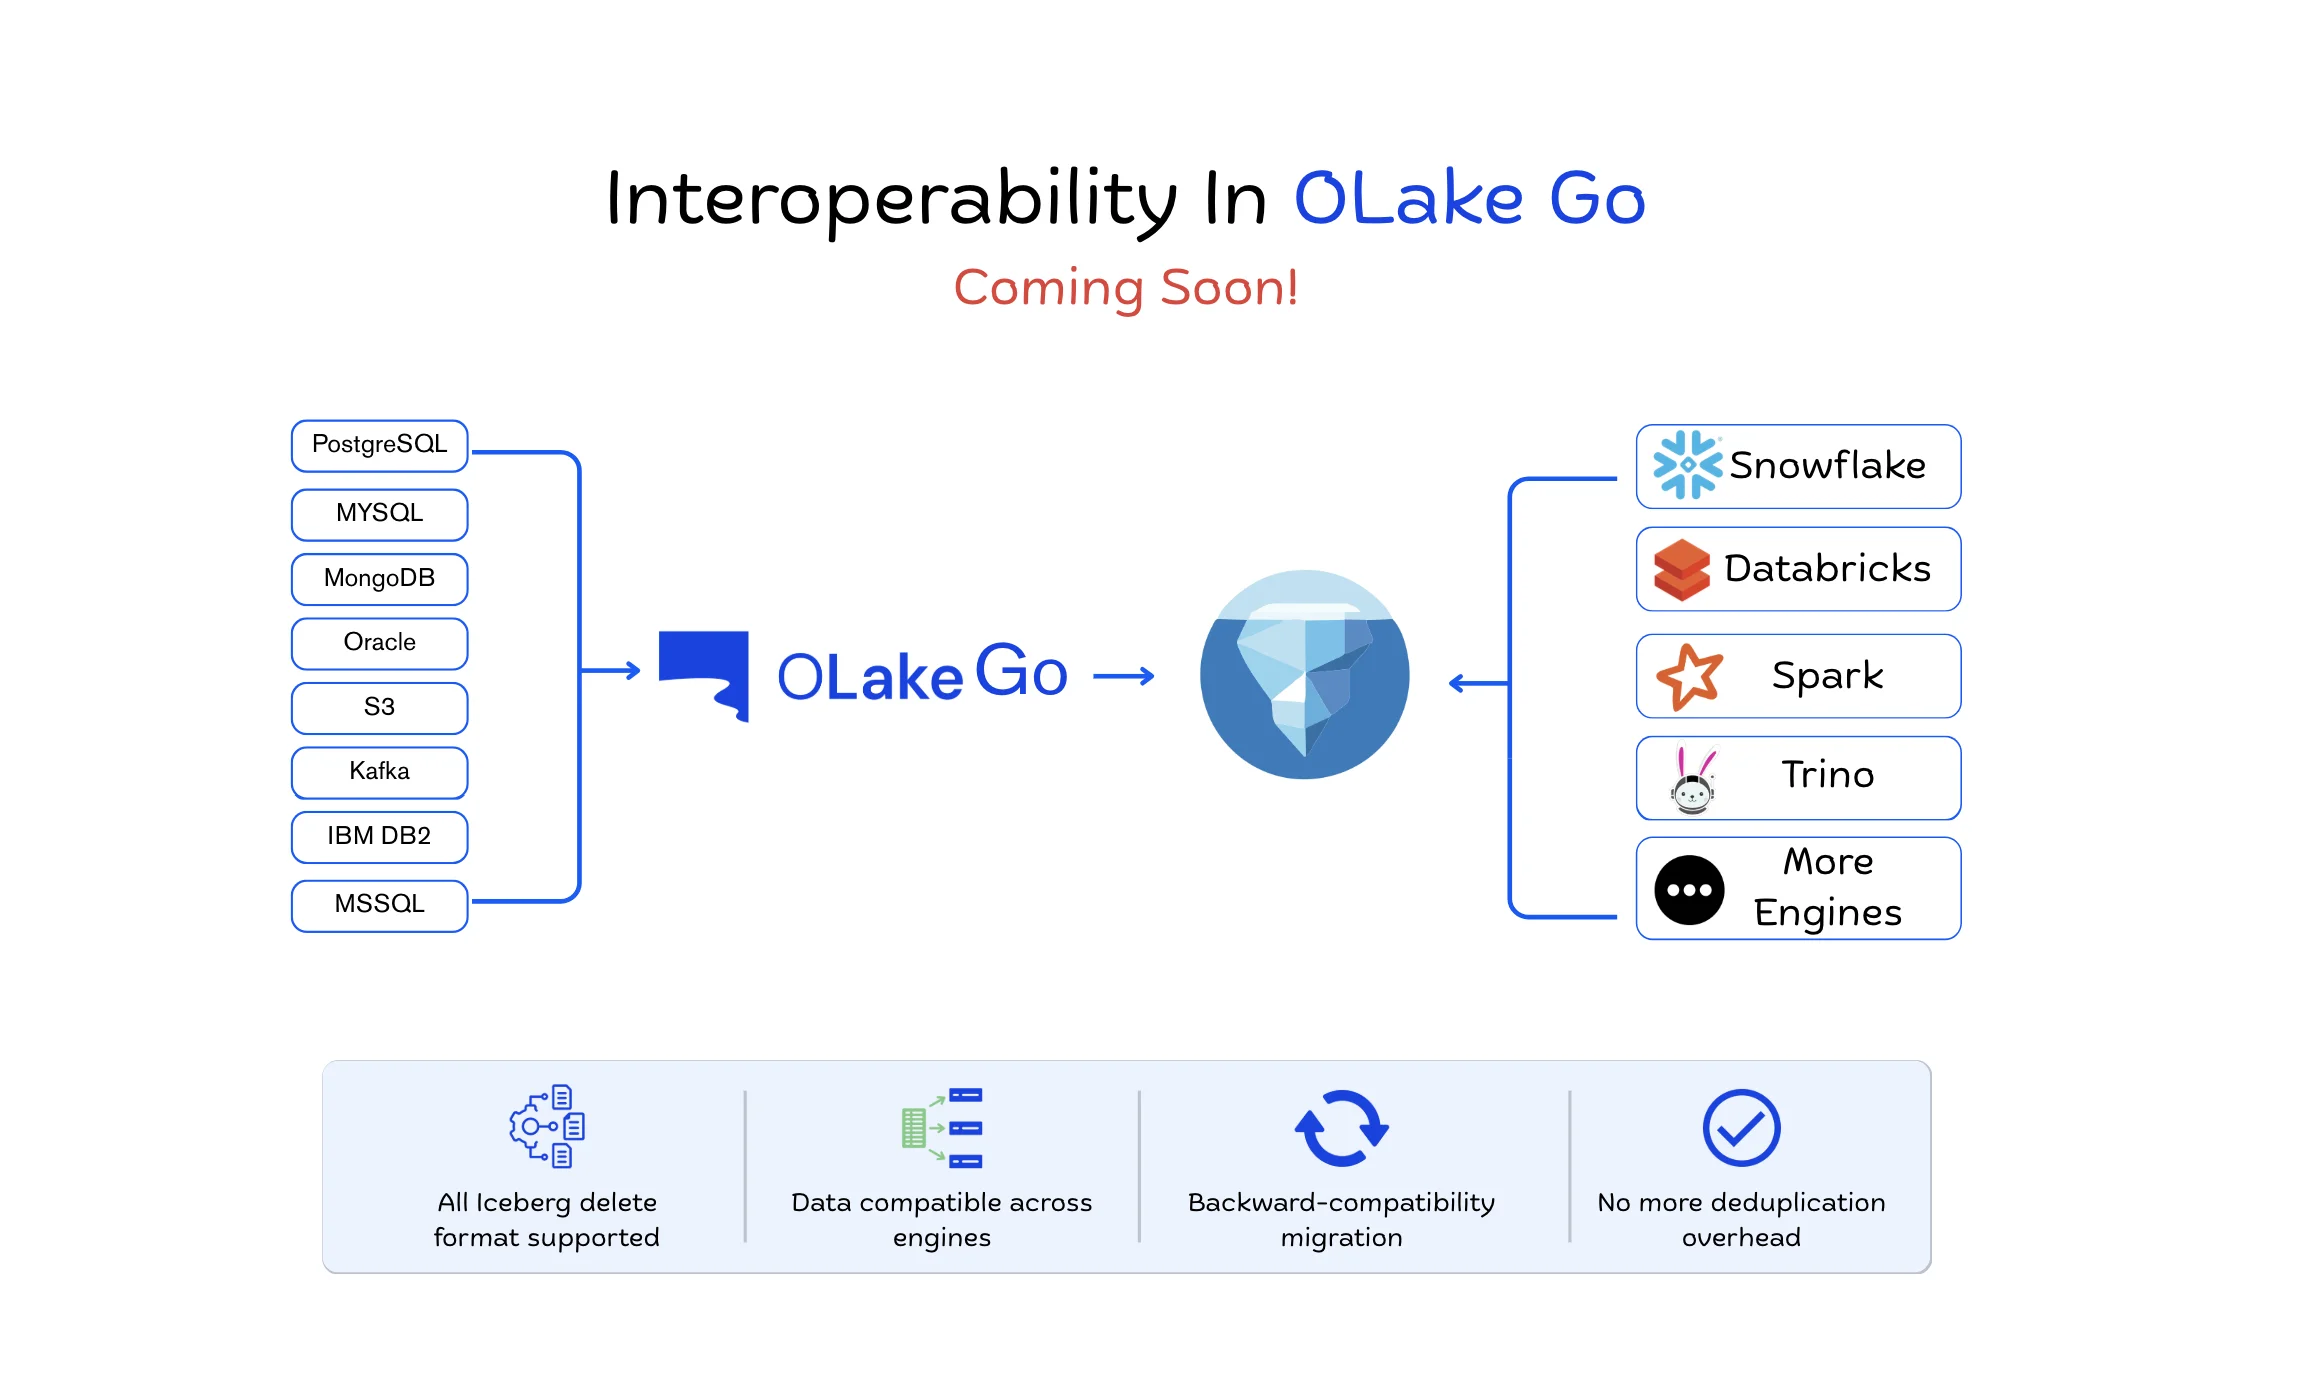
How OLake Go picks the right Iceberg delete format for your destination catalog and query engines, so tables are readable across Spark, Snowflake, Databricks, Athena, and Trino.
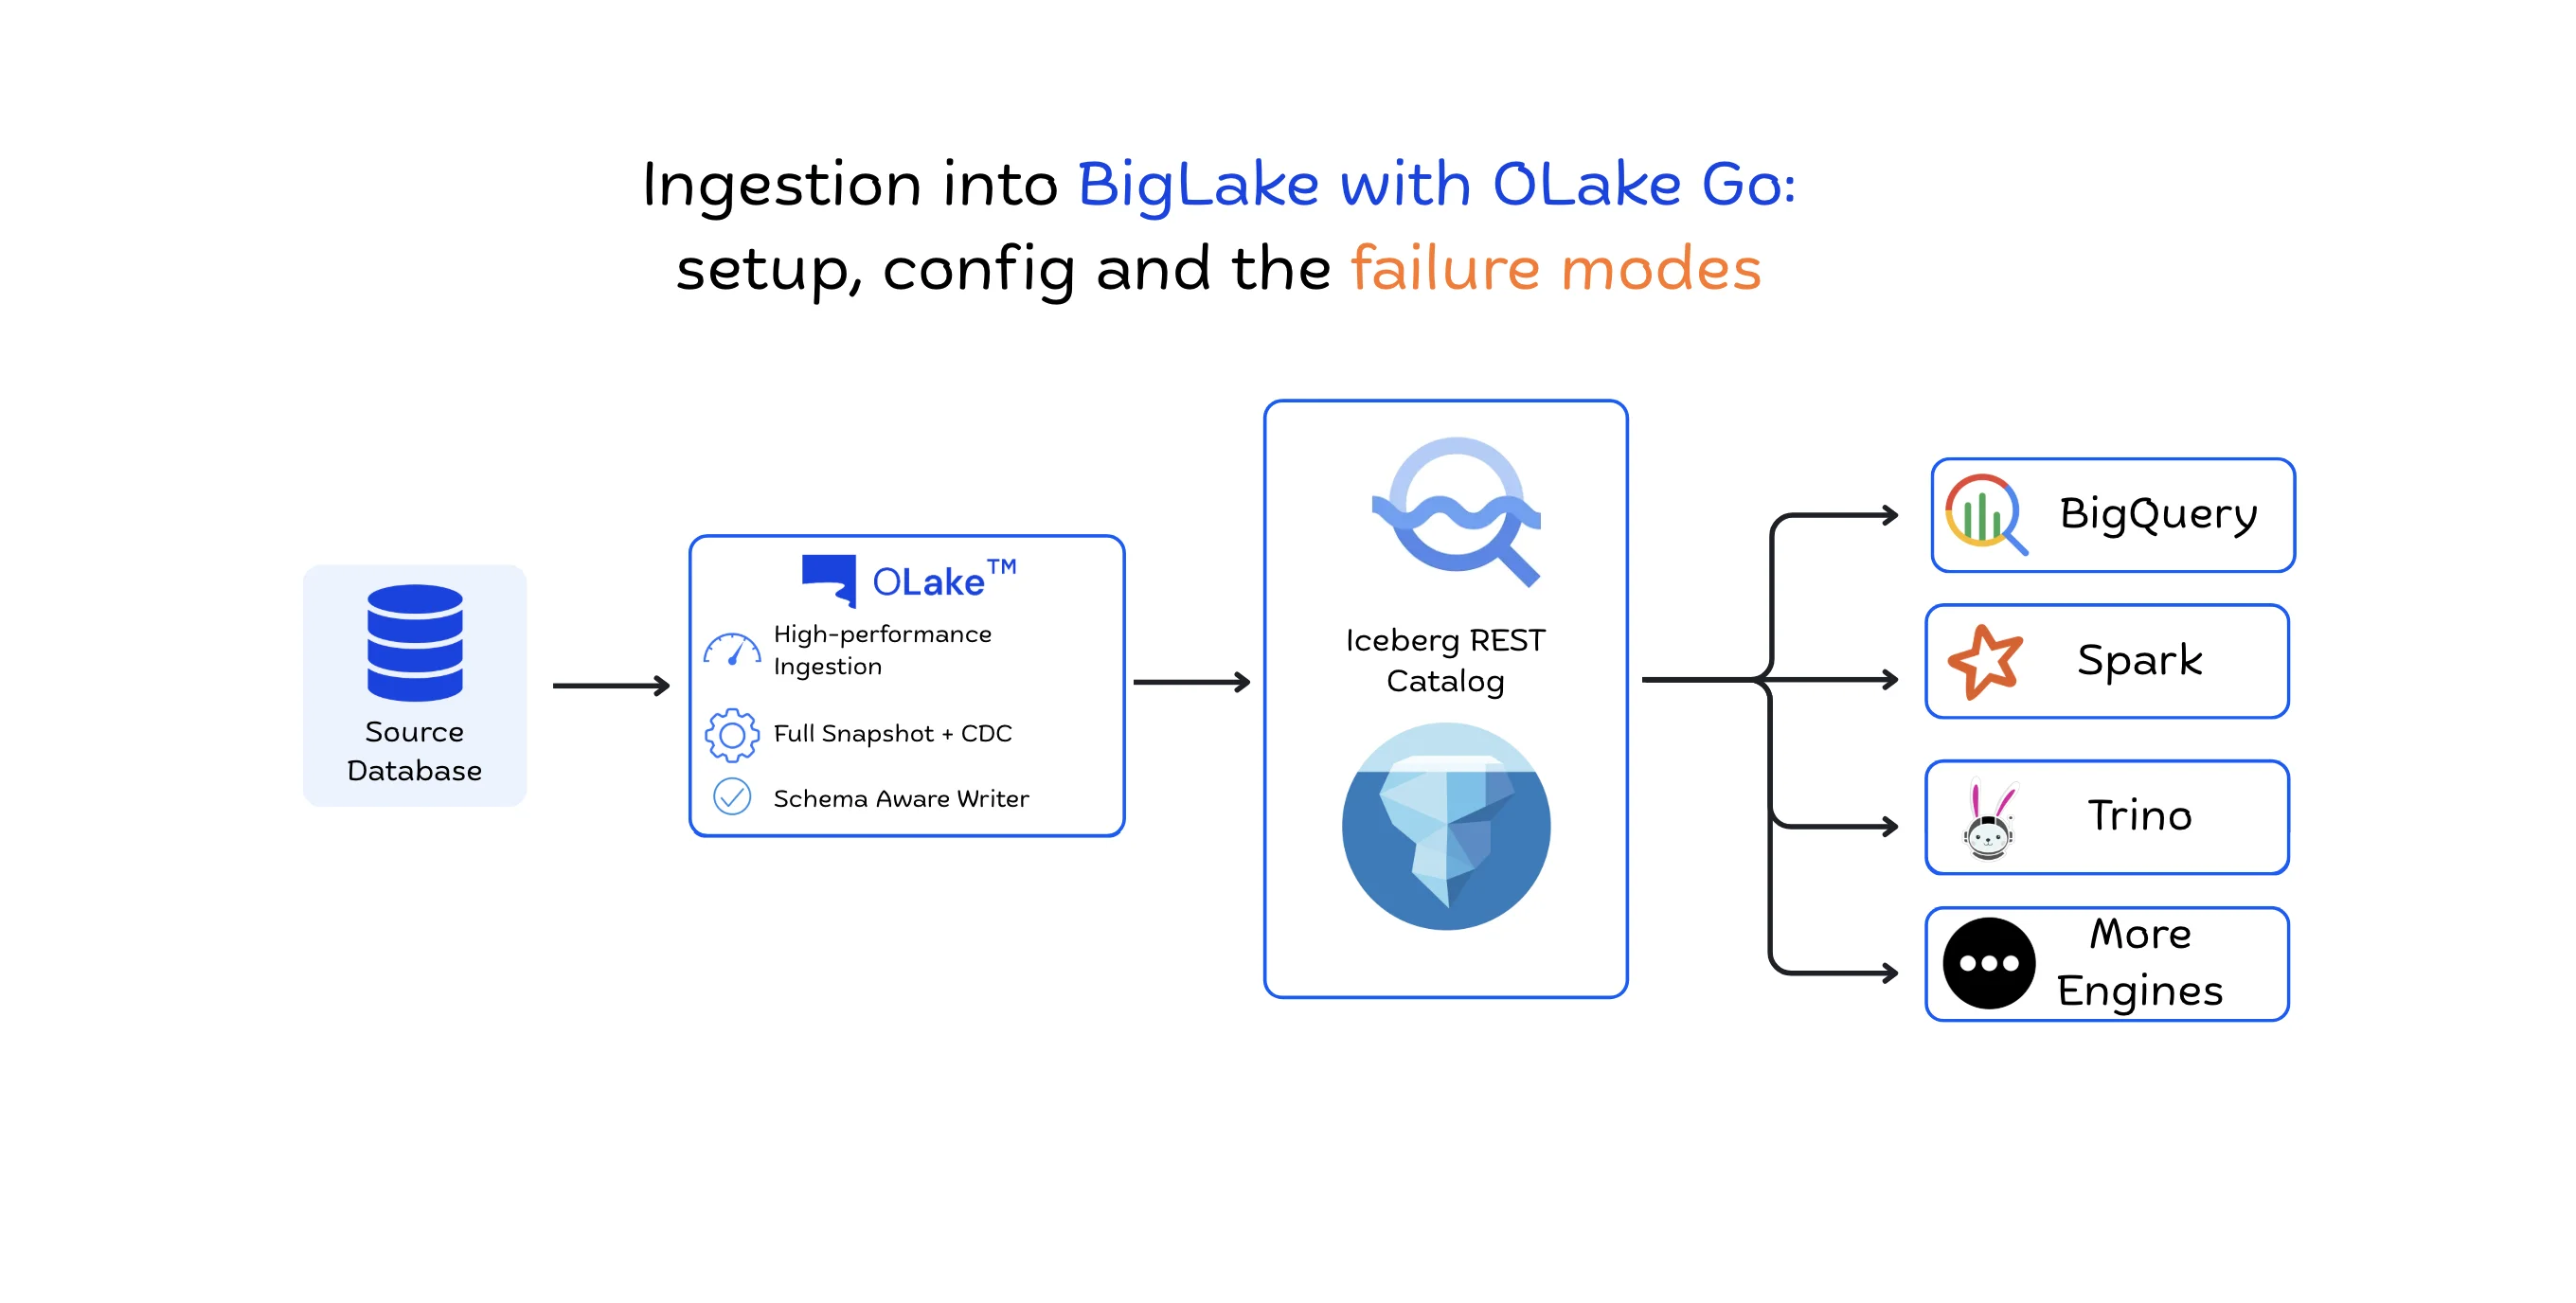
Write Apache Iceberg tables into Google BigLake with OLake Go: GCP prerequisites, REST catalog configuration field by field, and common failure modes.
OLake Go architecture deep dive: eight sources, one sync engine, chunked parallel backfills, native CDC, state and the Arrow write path to Iceberg.
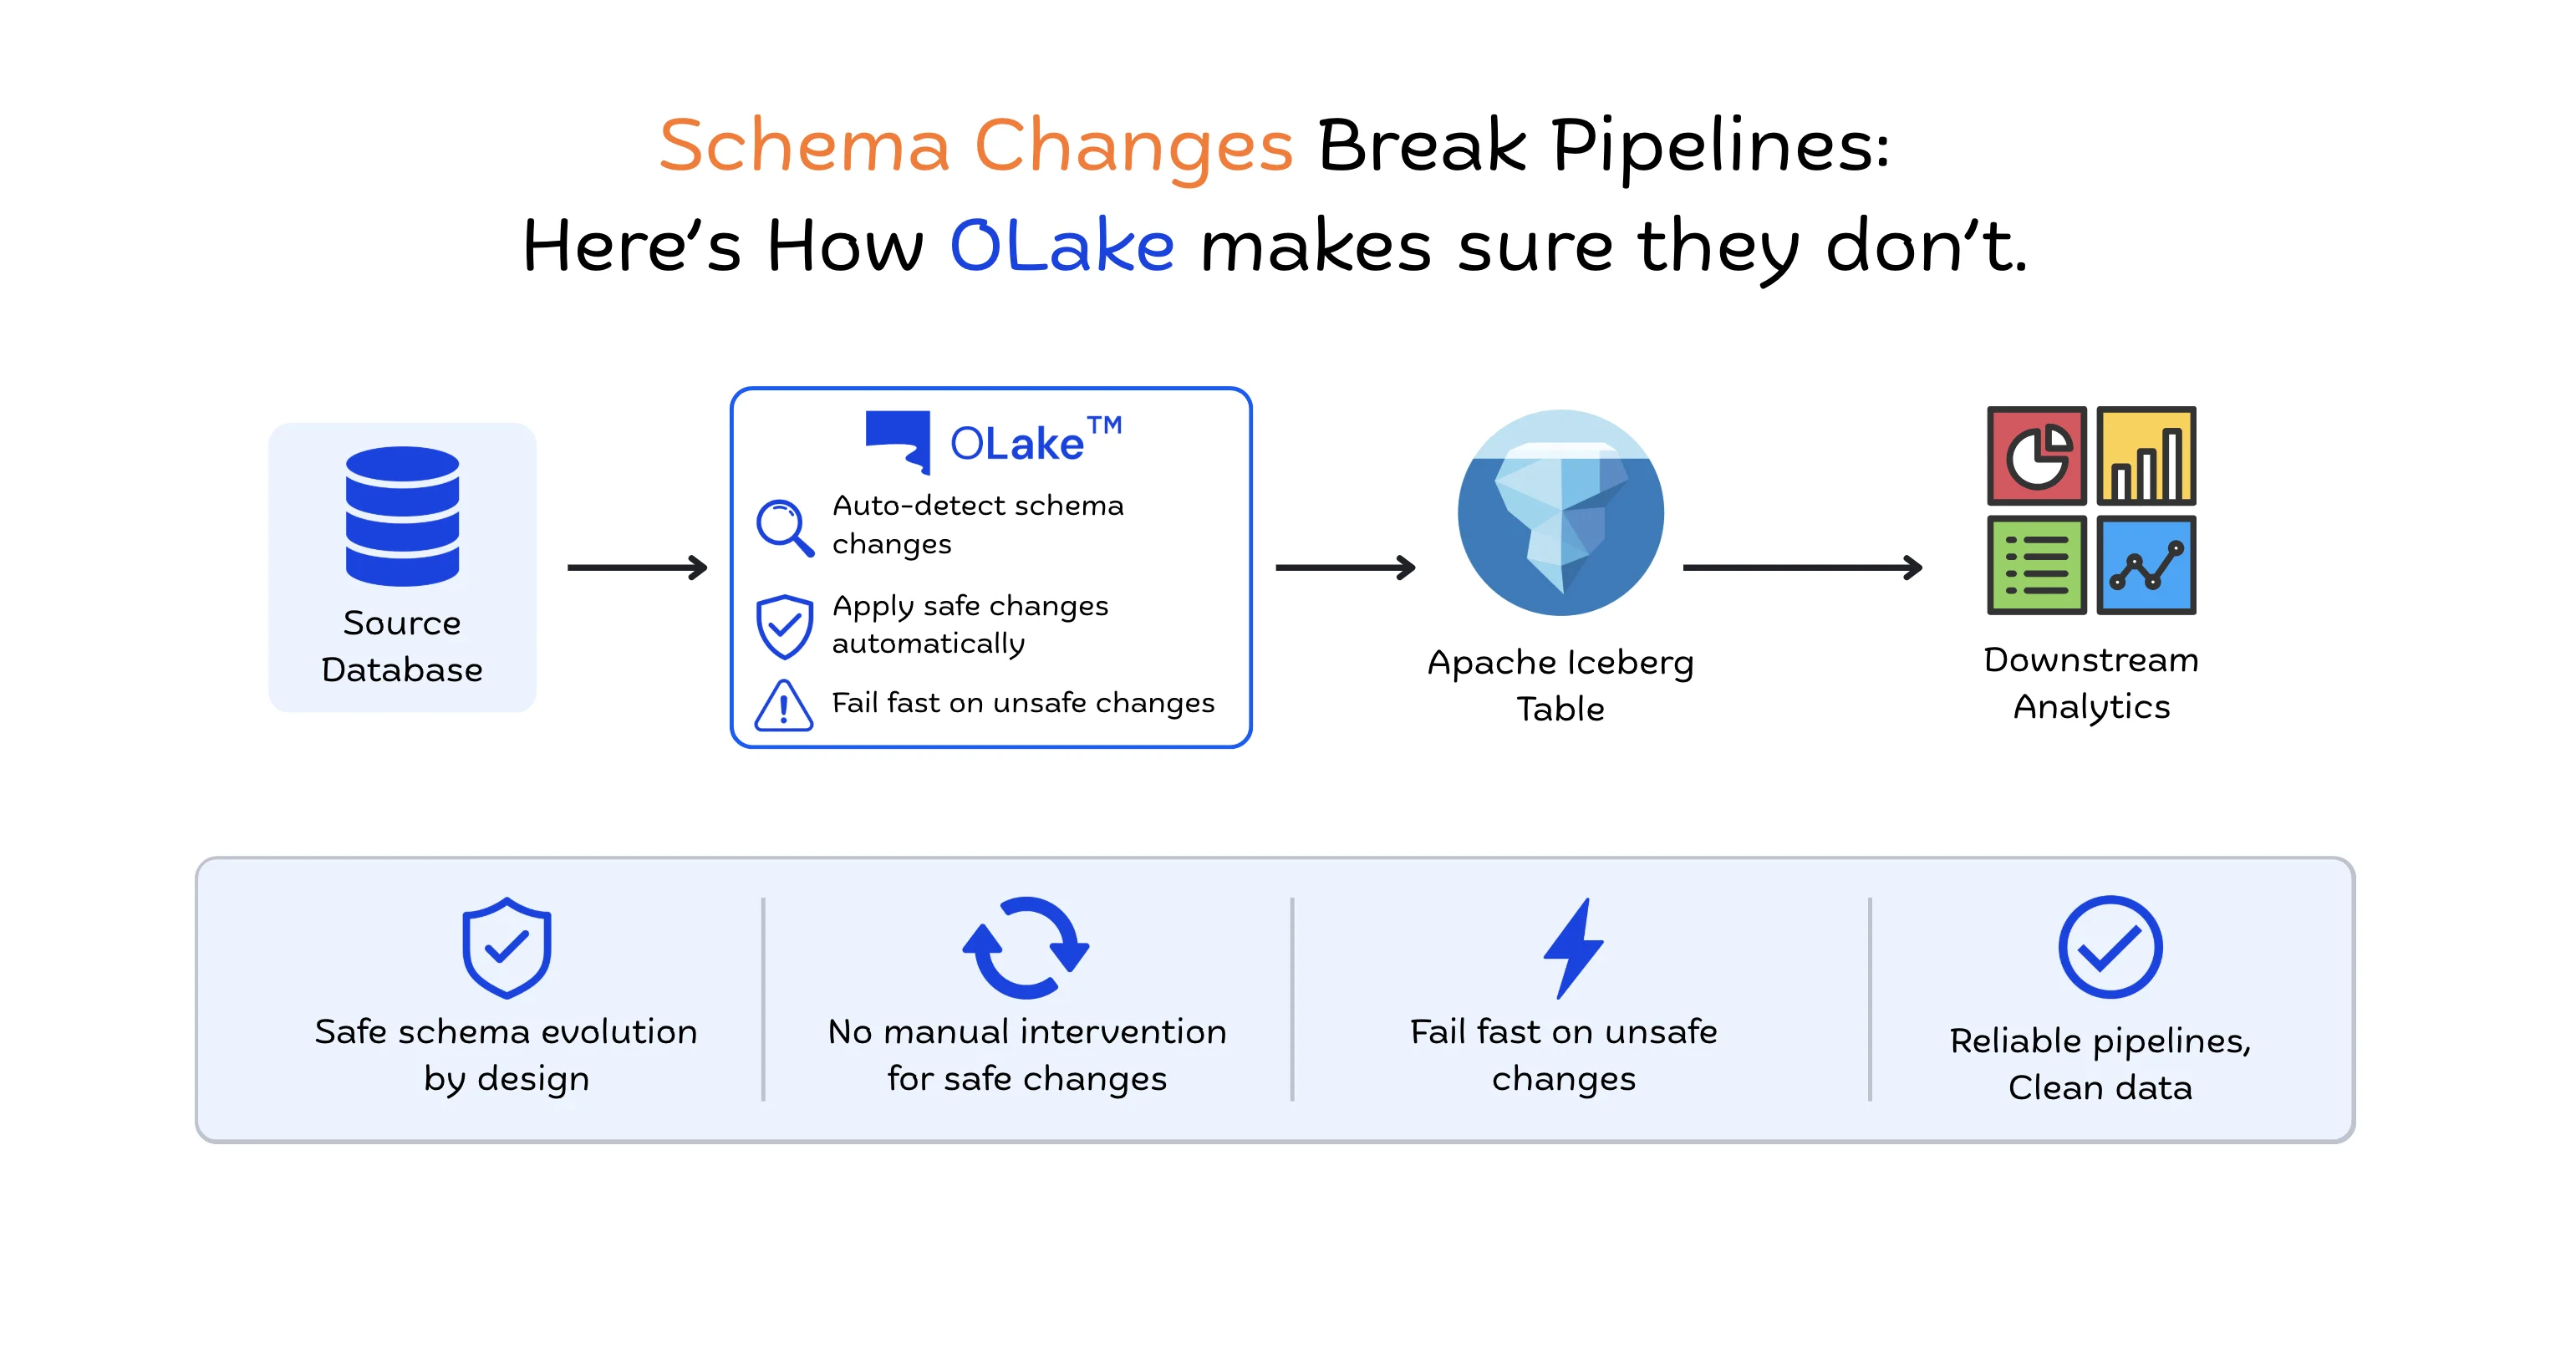
OLake Go schema evolution into Apache Iceberg: automatic column adds, retained drops, safe type promotions, and failures only where data would corrupt.