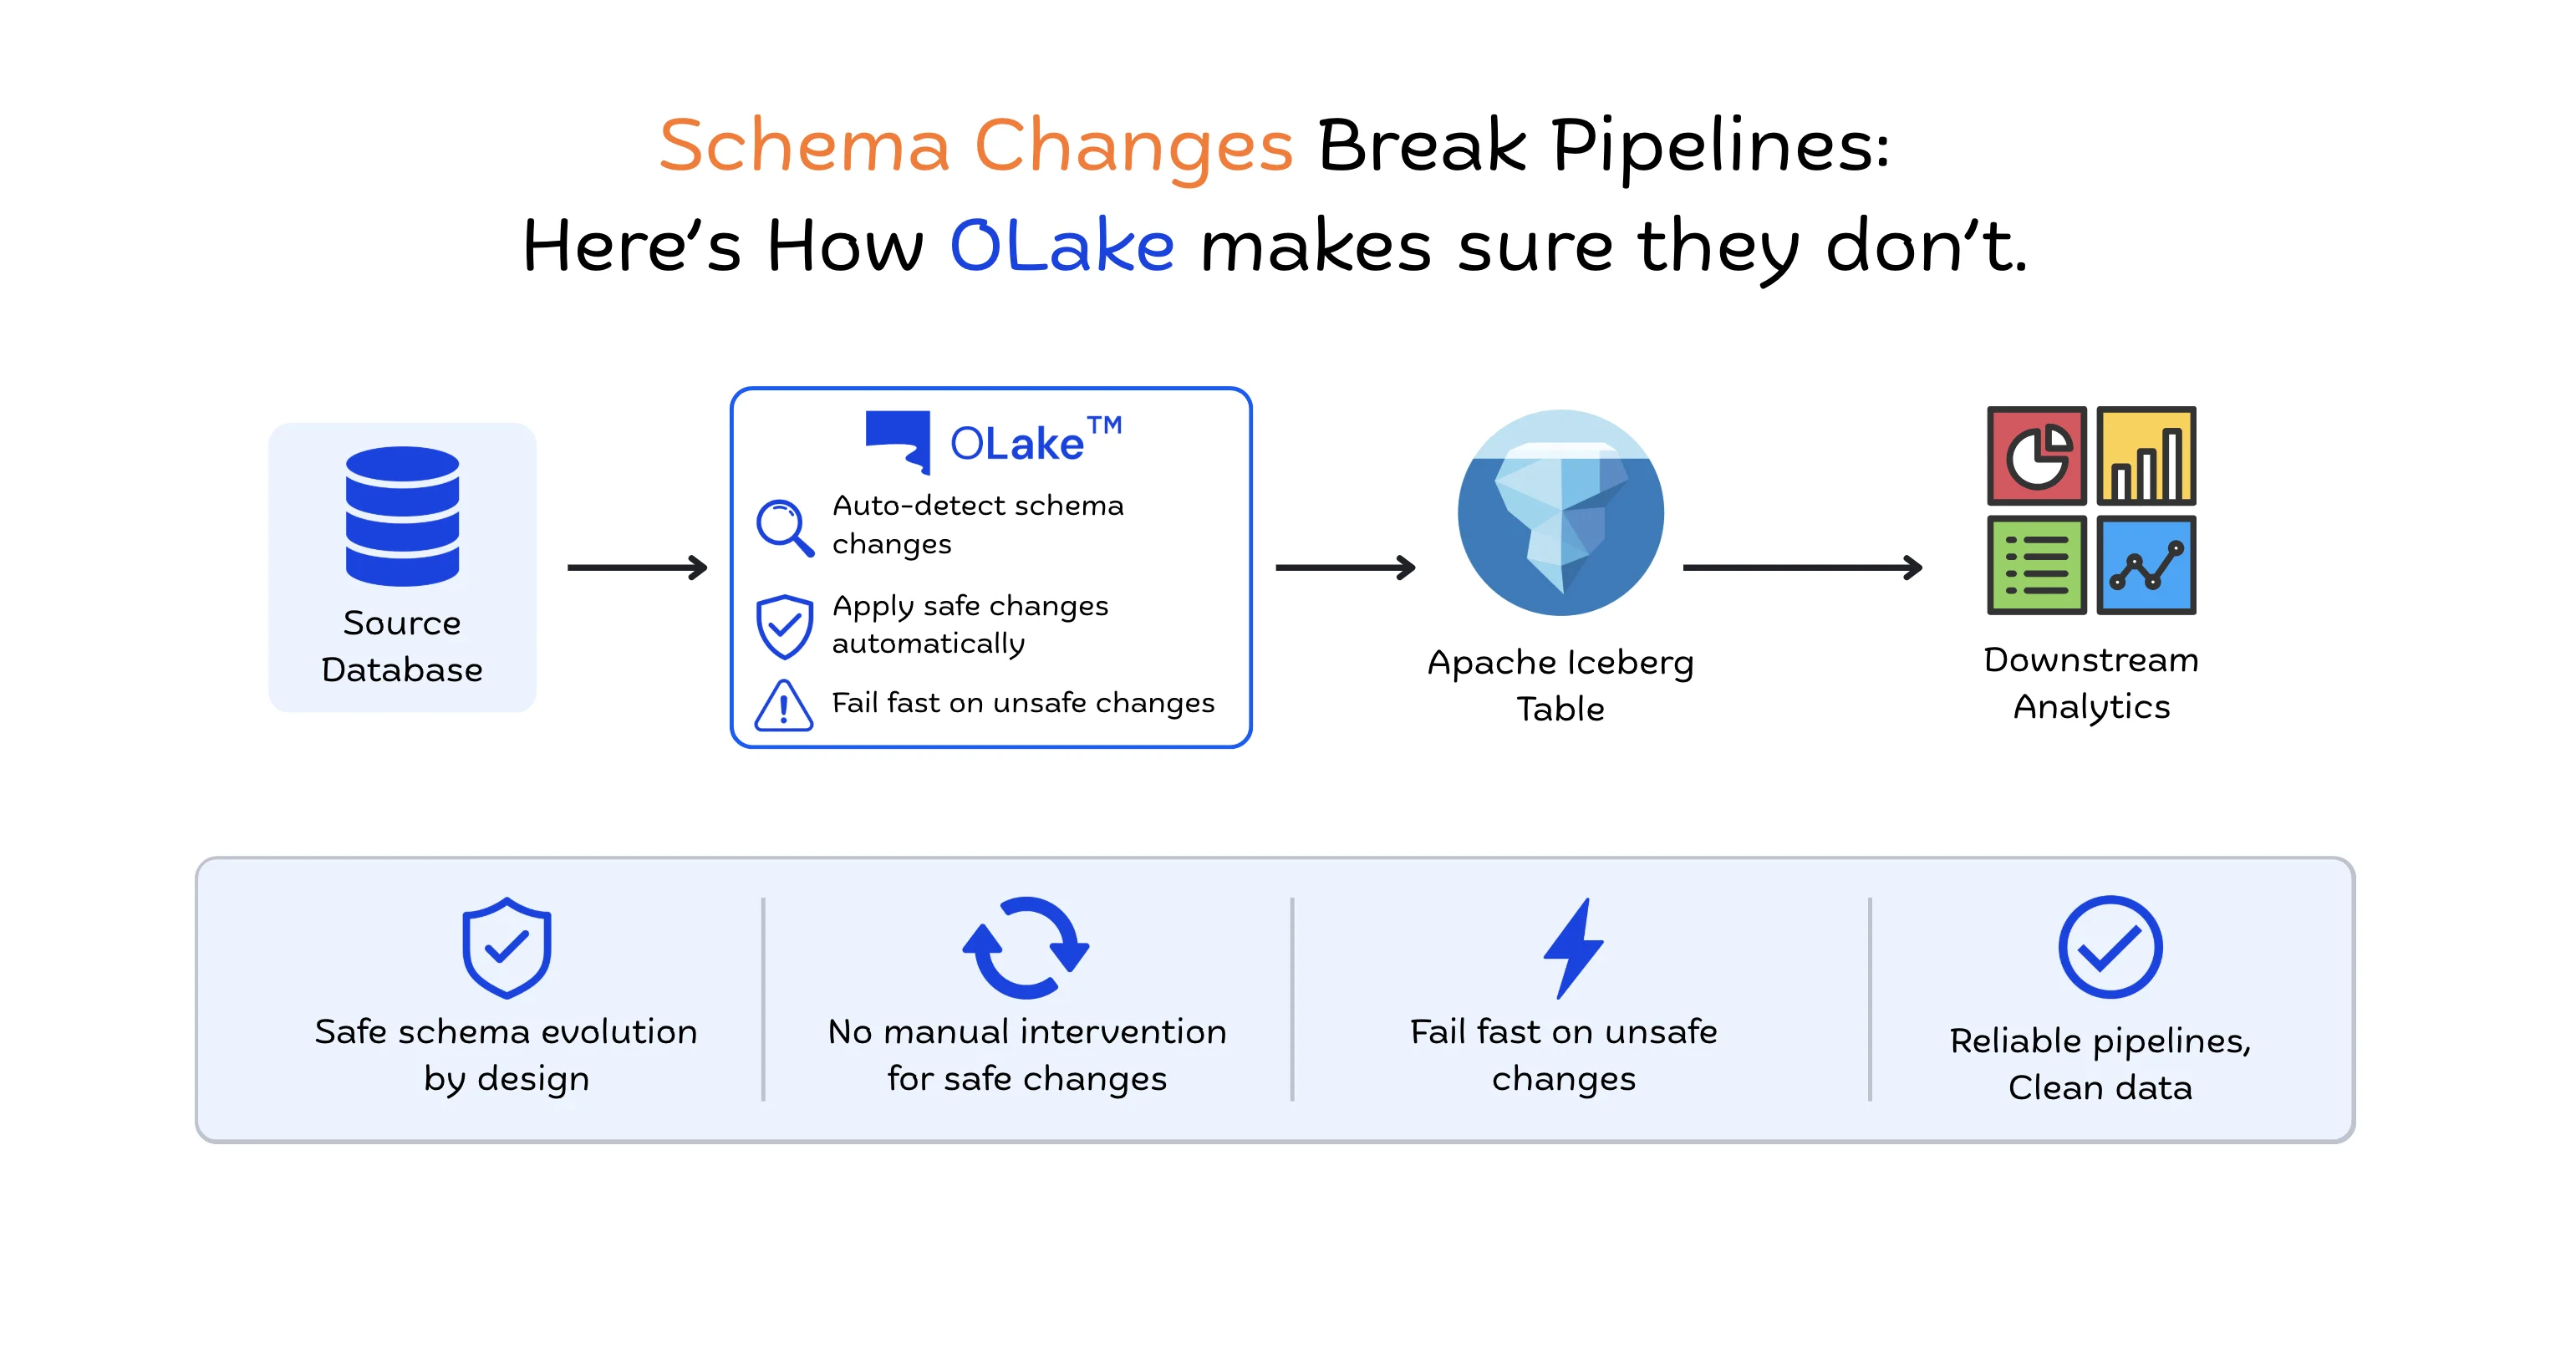
How OLake Go Handles Schema Evolution Without Breaking Your Pipeline
OLake Go schema evolution into Apache Iceberg: automatic column adds, retained drops, safe type promotions, and failures only where data would corrupt.
Blogs on the topic OLake
View All TagsOLake Go schema evolution into Apache Iceberg: automatic column adds, retained drops, safe type promotions, and failures only where data would corrupt.
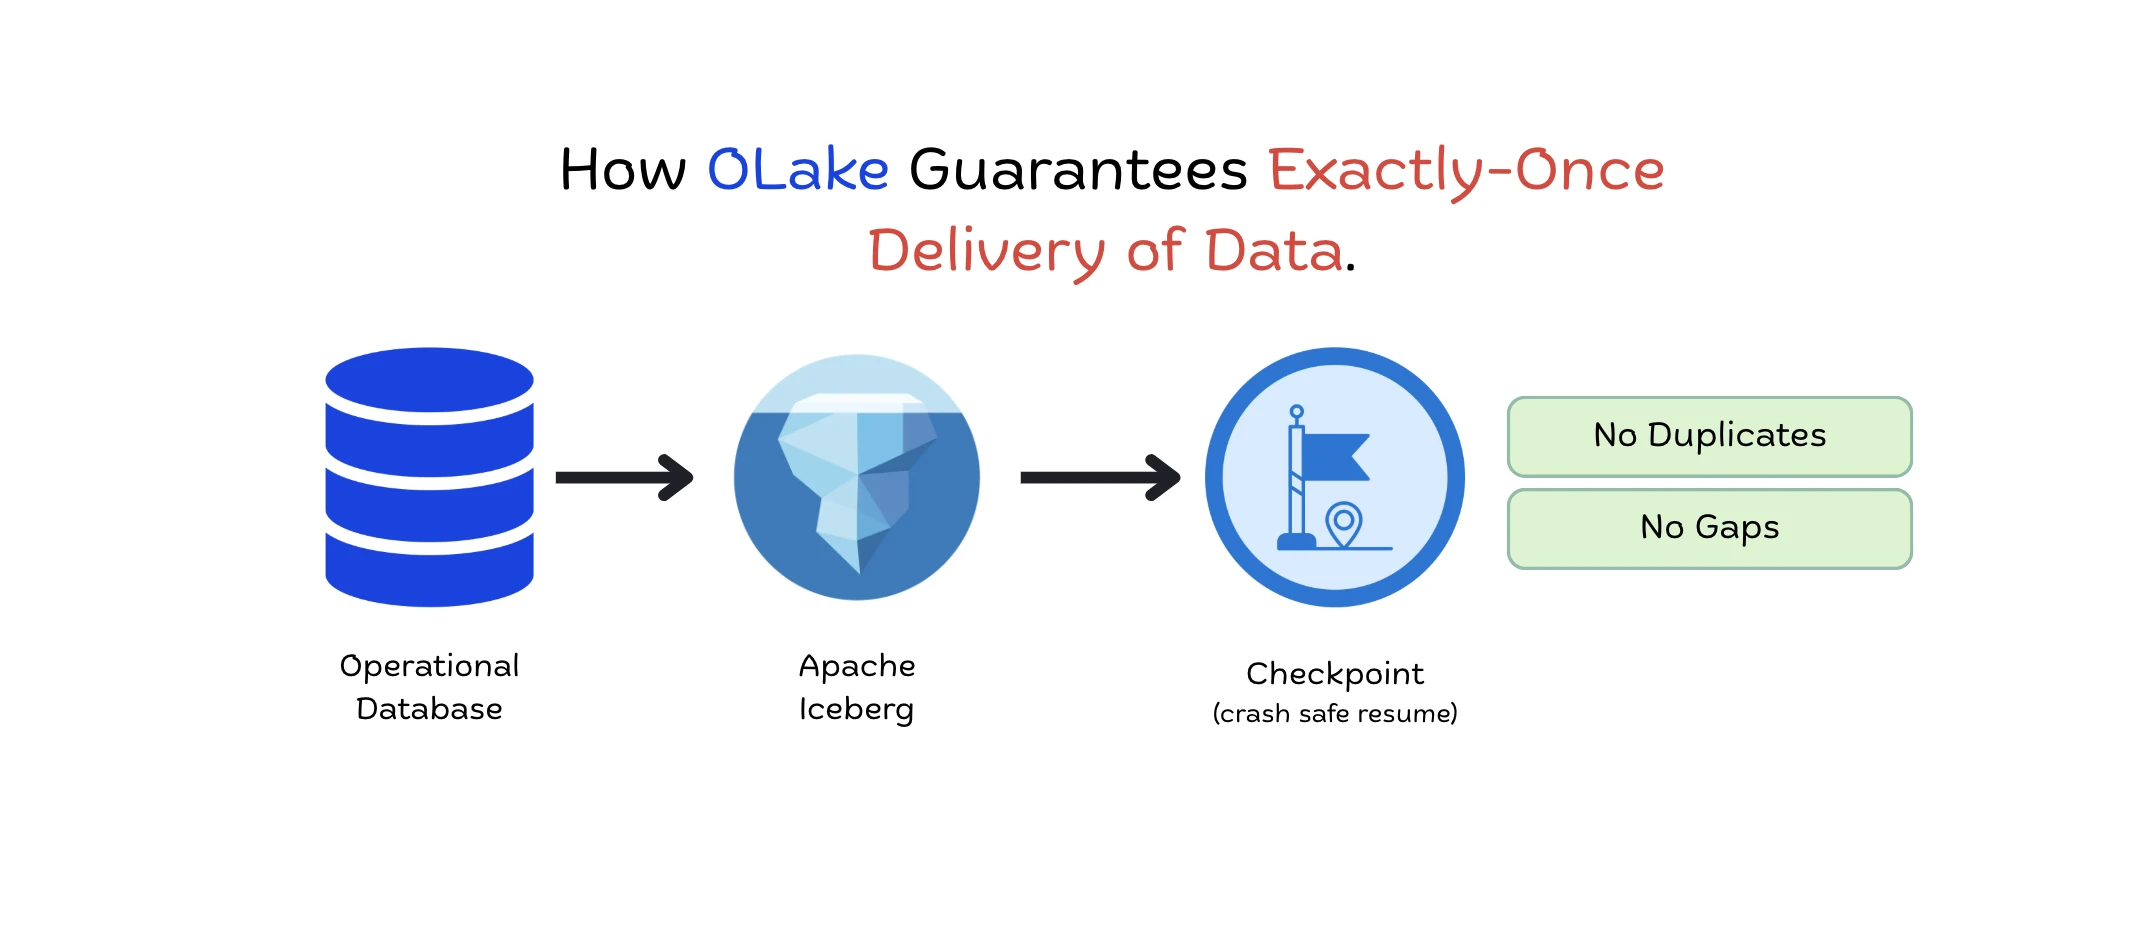
How OLake Go delivers exactly-once data into Apache Iceberg across Full Refresh, Incremental and CDC syncs, using atomic commits and checkpoint recovery.
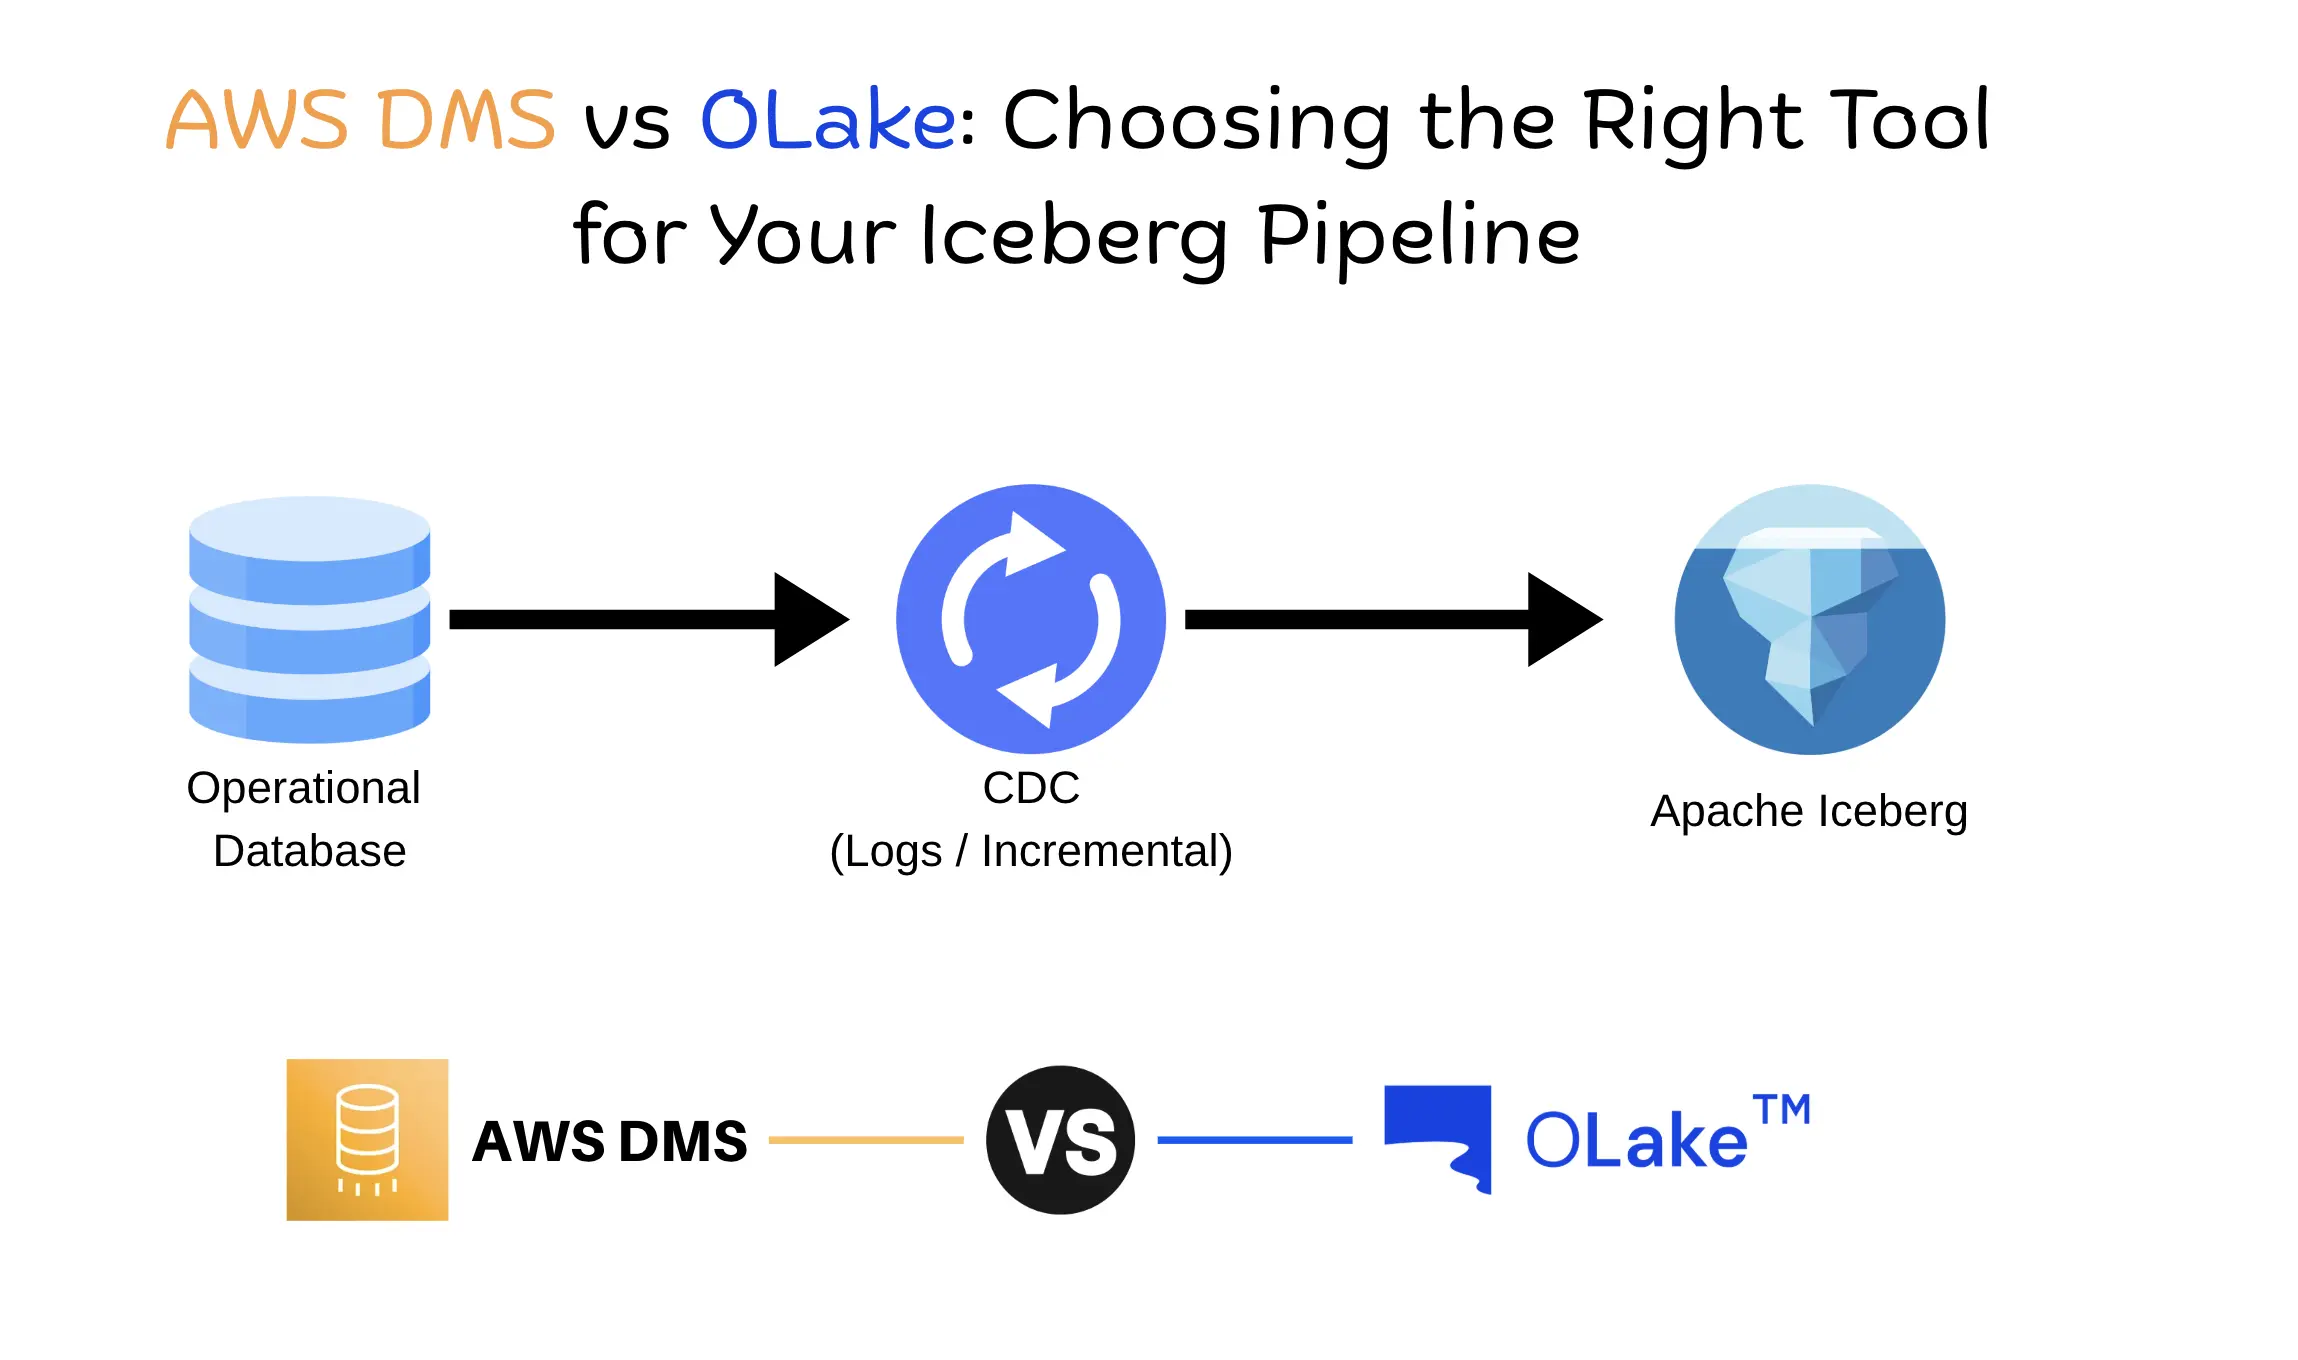
Compare AWS DMS and OLake Go for database-to-Iceberg pipelines: setup, CDC, schema evolution, scaling, and cost, with benchmark numbers on over 4 billion rows.
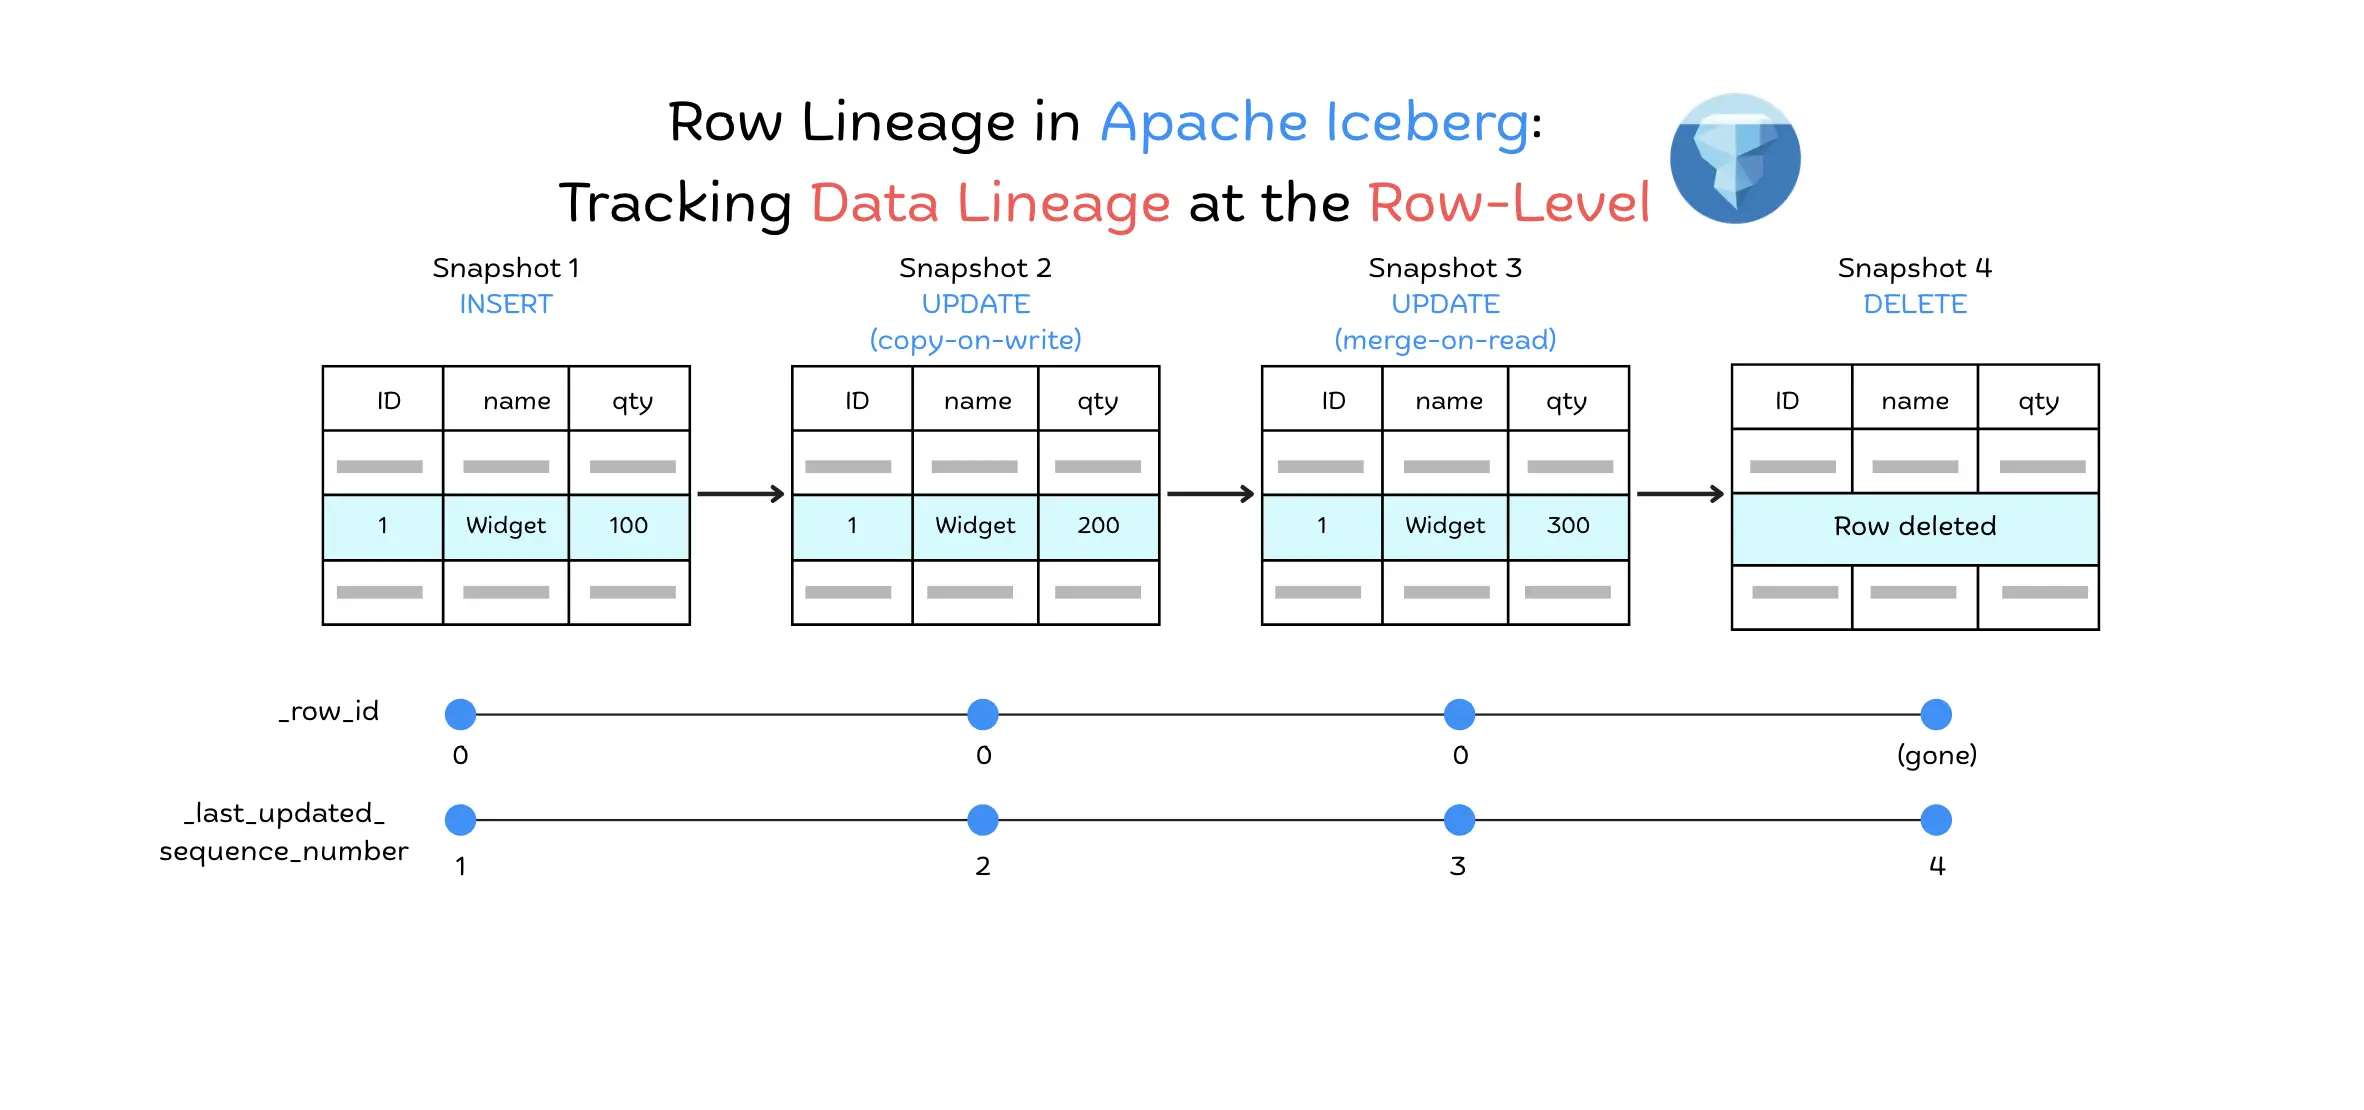
How Apache Iceberg v3 row lineage tracks row-level changes for CDC, with a tested look at _row_id preservation across Spark 3.5 and Iceberg 1.9 vs 1.10.
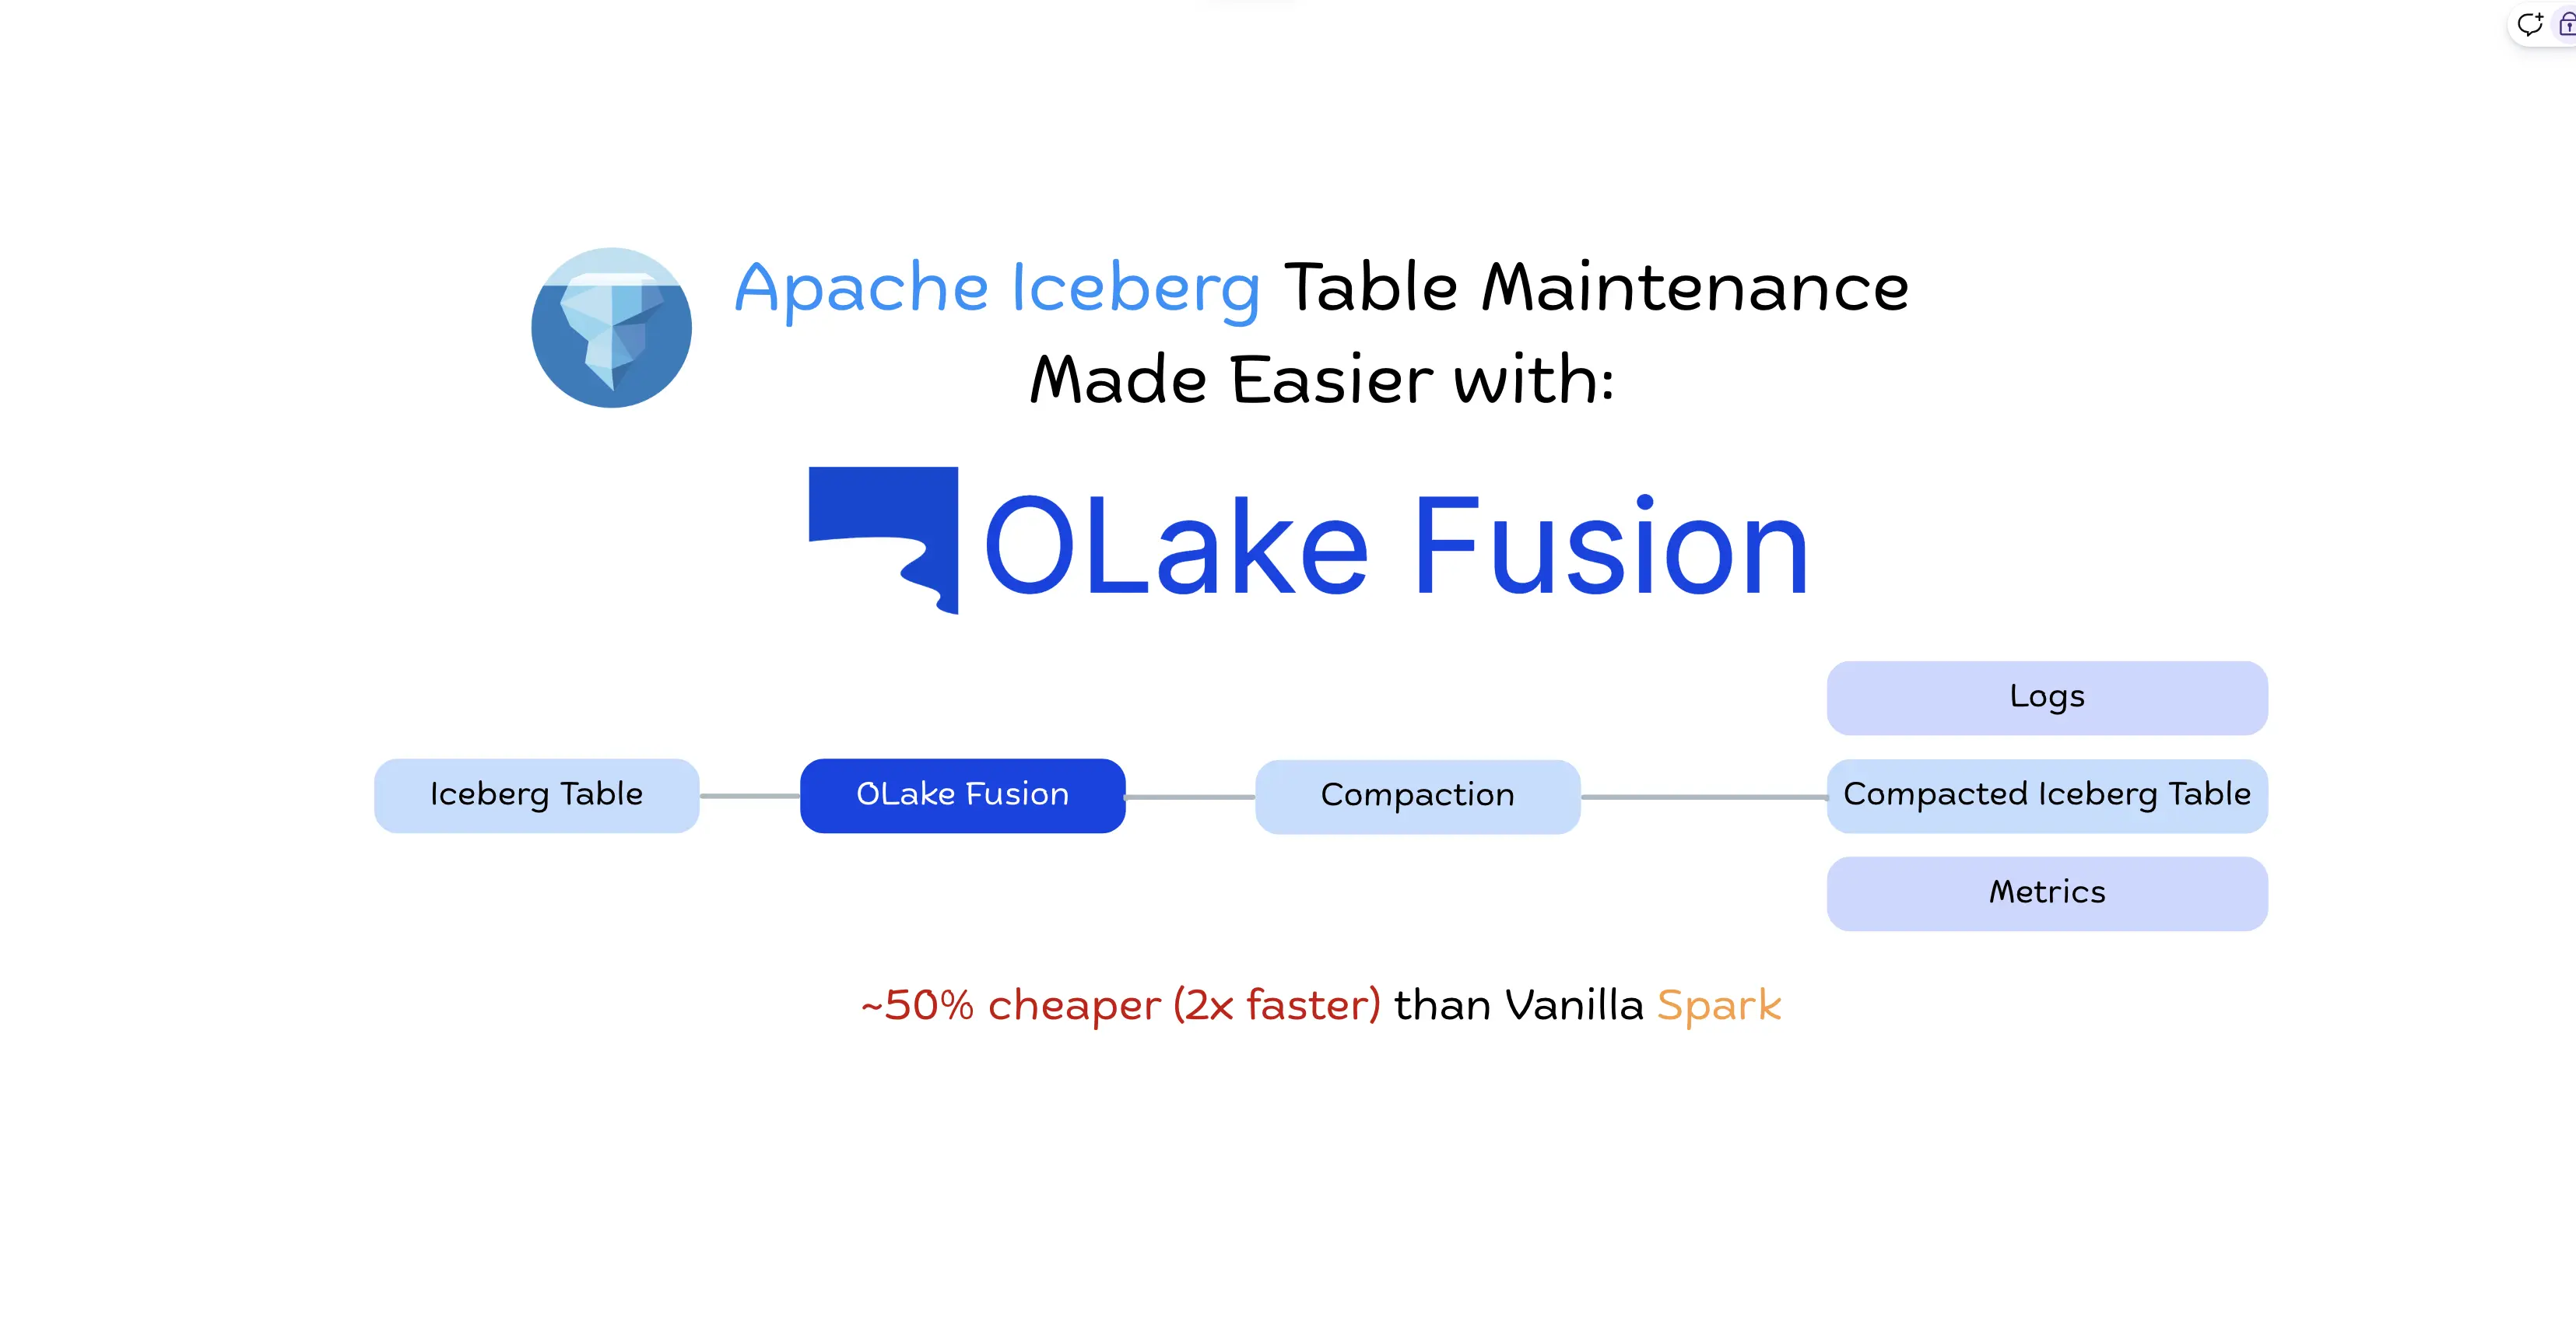
OLake Fusion handles Apache Iceberg table maintenance for CDC tables: tiered compaction for small and delete files, health metrics and lower Spark cost.
We benchmark Spark rewrite_data_files against OLake Fusion compaction on Apache Iceberg by running a full TPCH lineitem load from Postgres to GCP, applying 200k-record CDC batches every 2 minutes, and tracking TPC-H Query 6 performance, runtime, resource usage, and infrastructure cost.