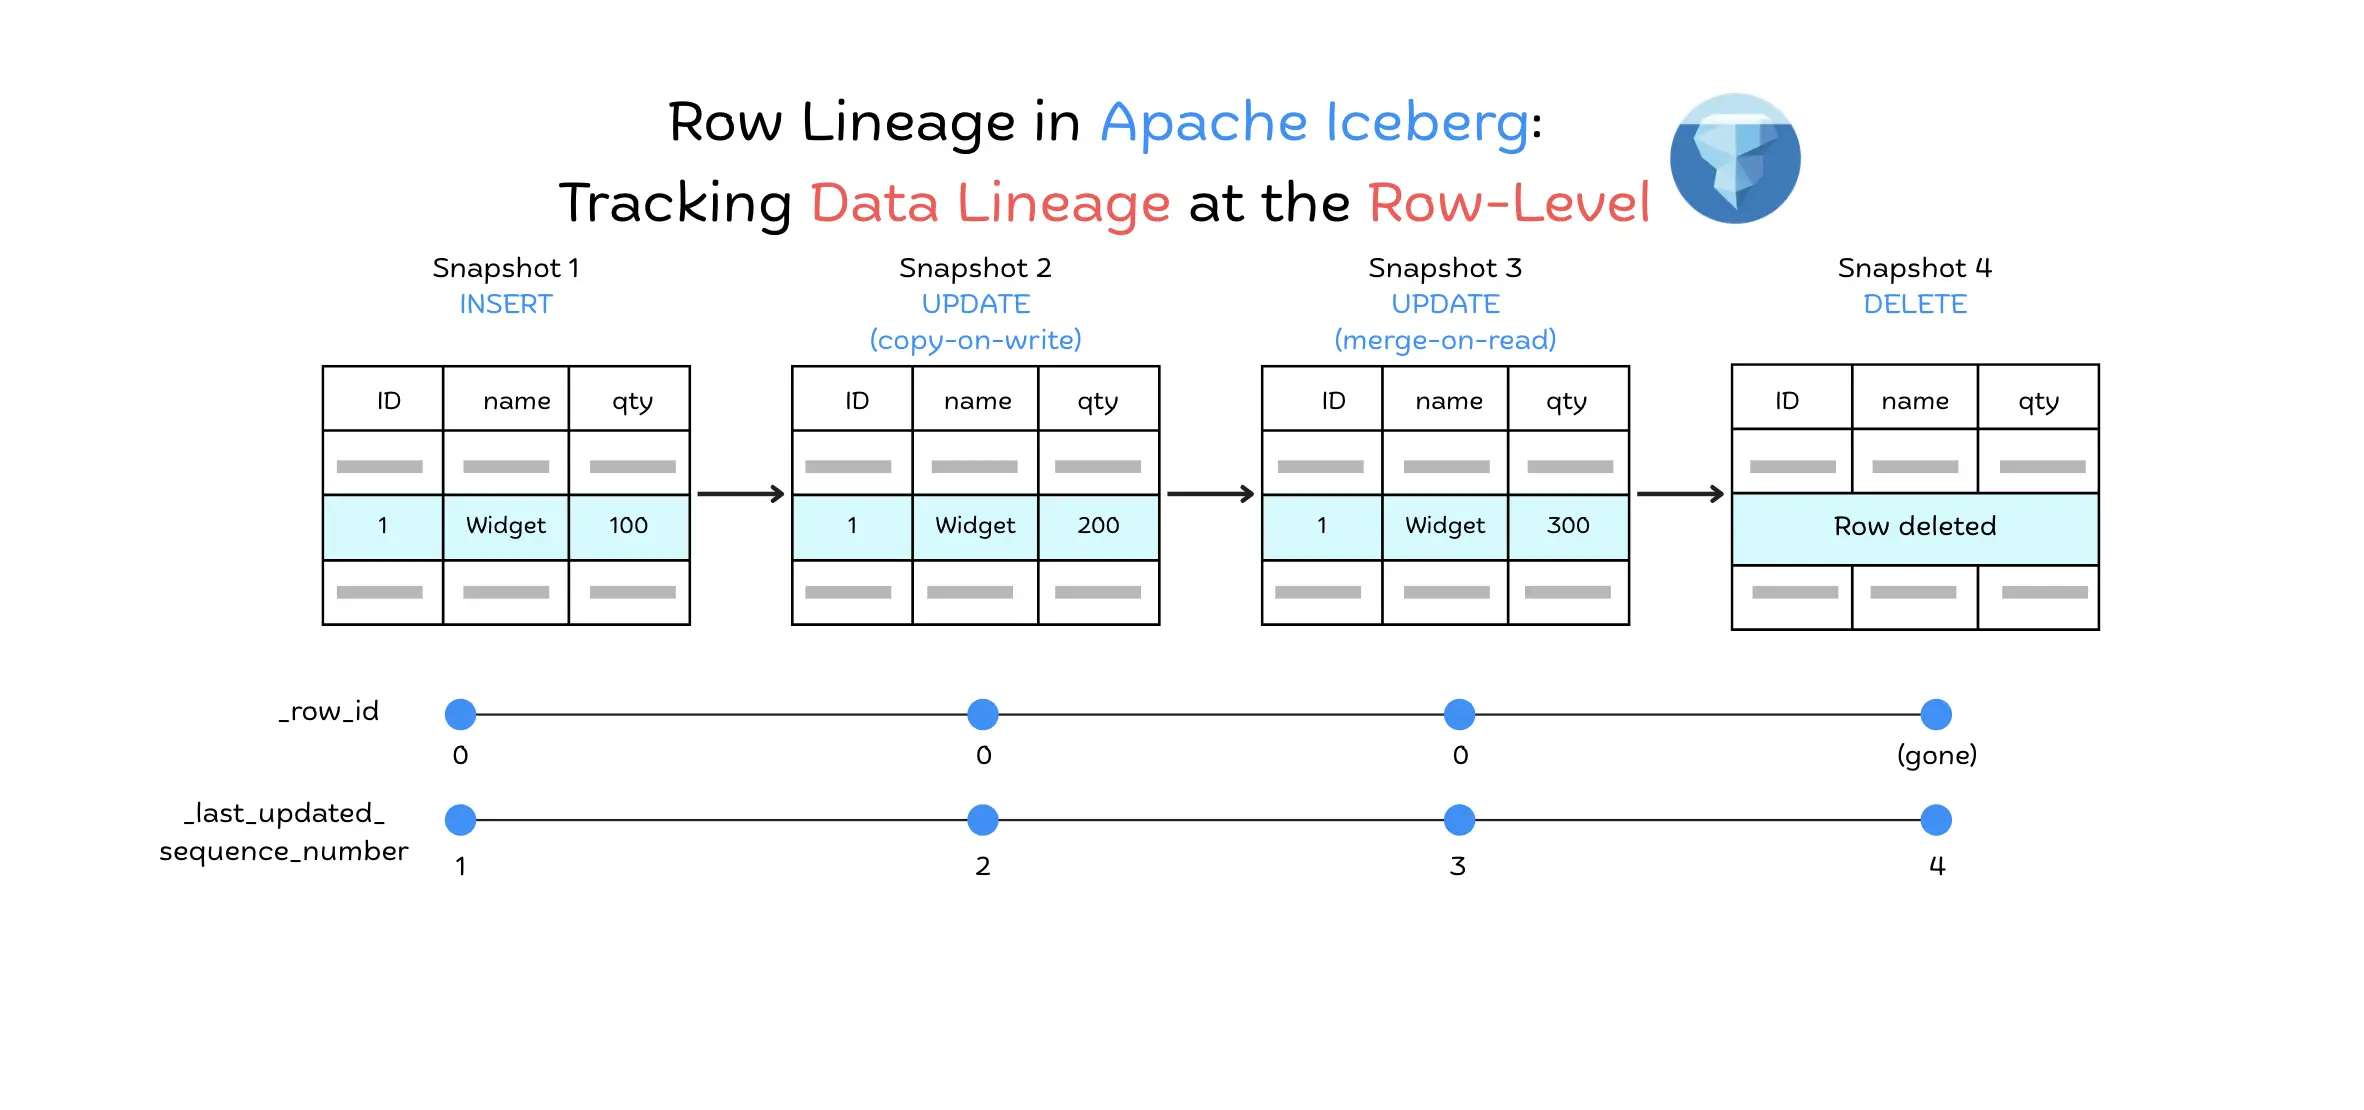
Apache Iceberg Row Lineage: Tracking Data Lineage at the Row-Level
How Apache Iceberg v3 row lineage tracks row-level changes for CDC, with a tested look at _row_id preservation across Spark 3.5 and Iceberg 1.9 vs 1.10.
Blogs on the topic OLake
View All TagsHow Apache Iceberg v3 row lineage tracks row-level changes for CDC, with a tested look at _row_id preservation across Spark 3.5 and Iceberg 1.9 vs 1.10.
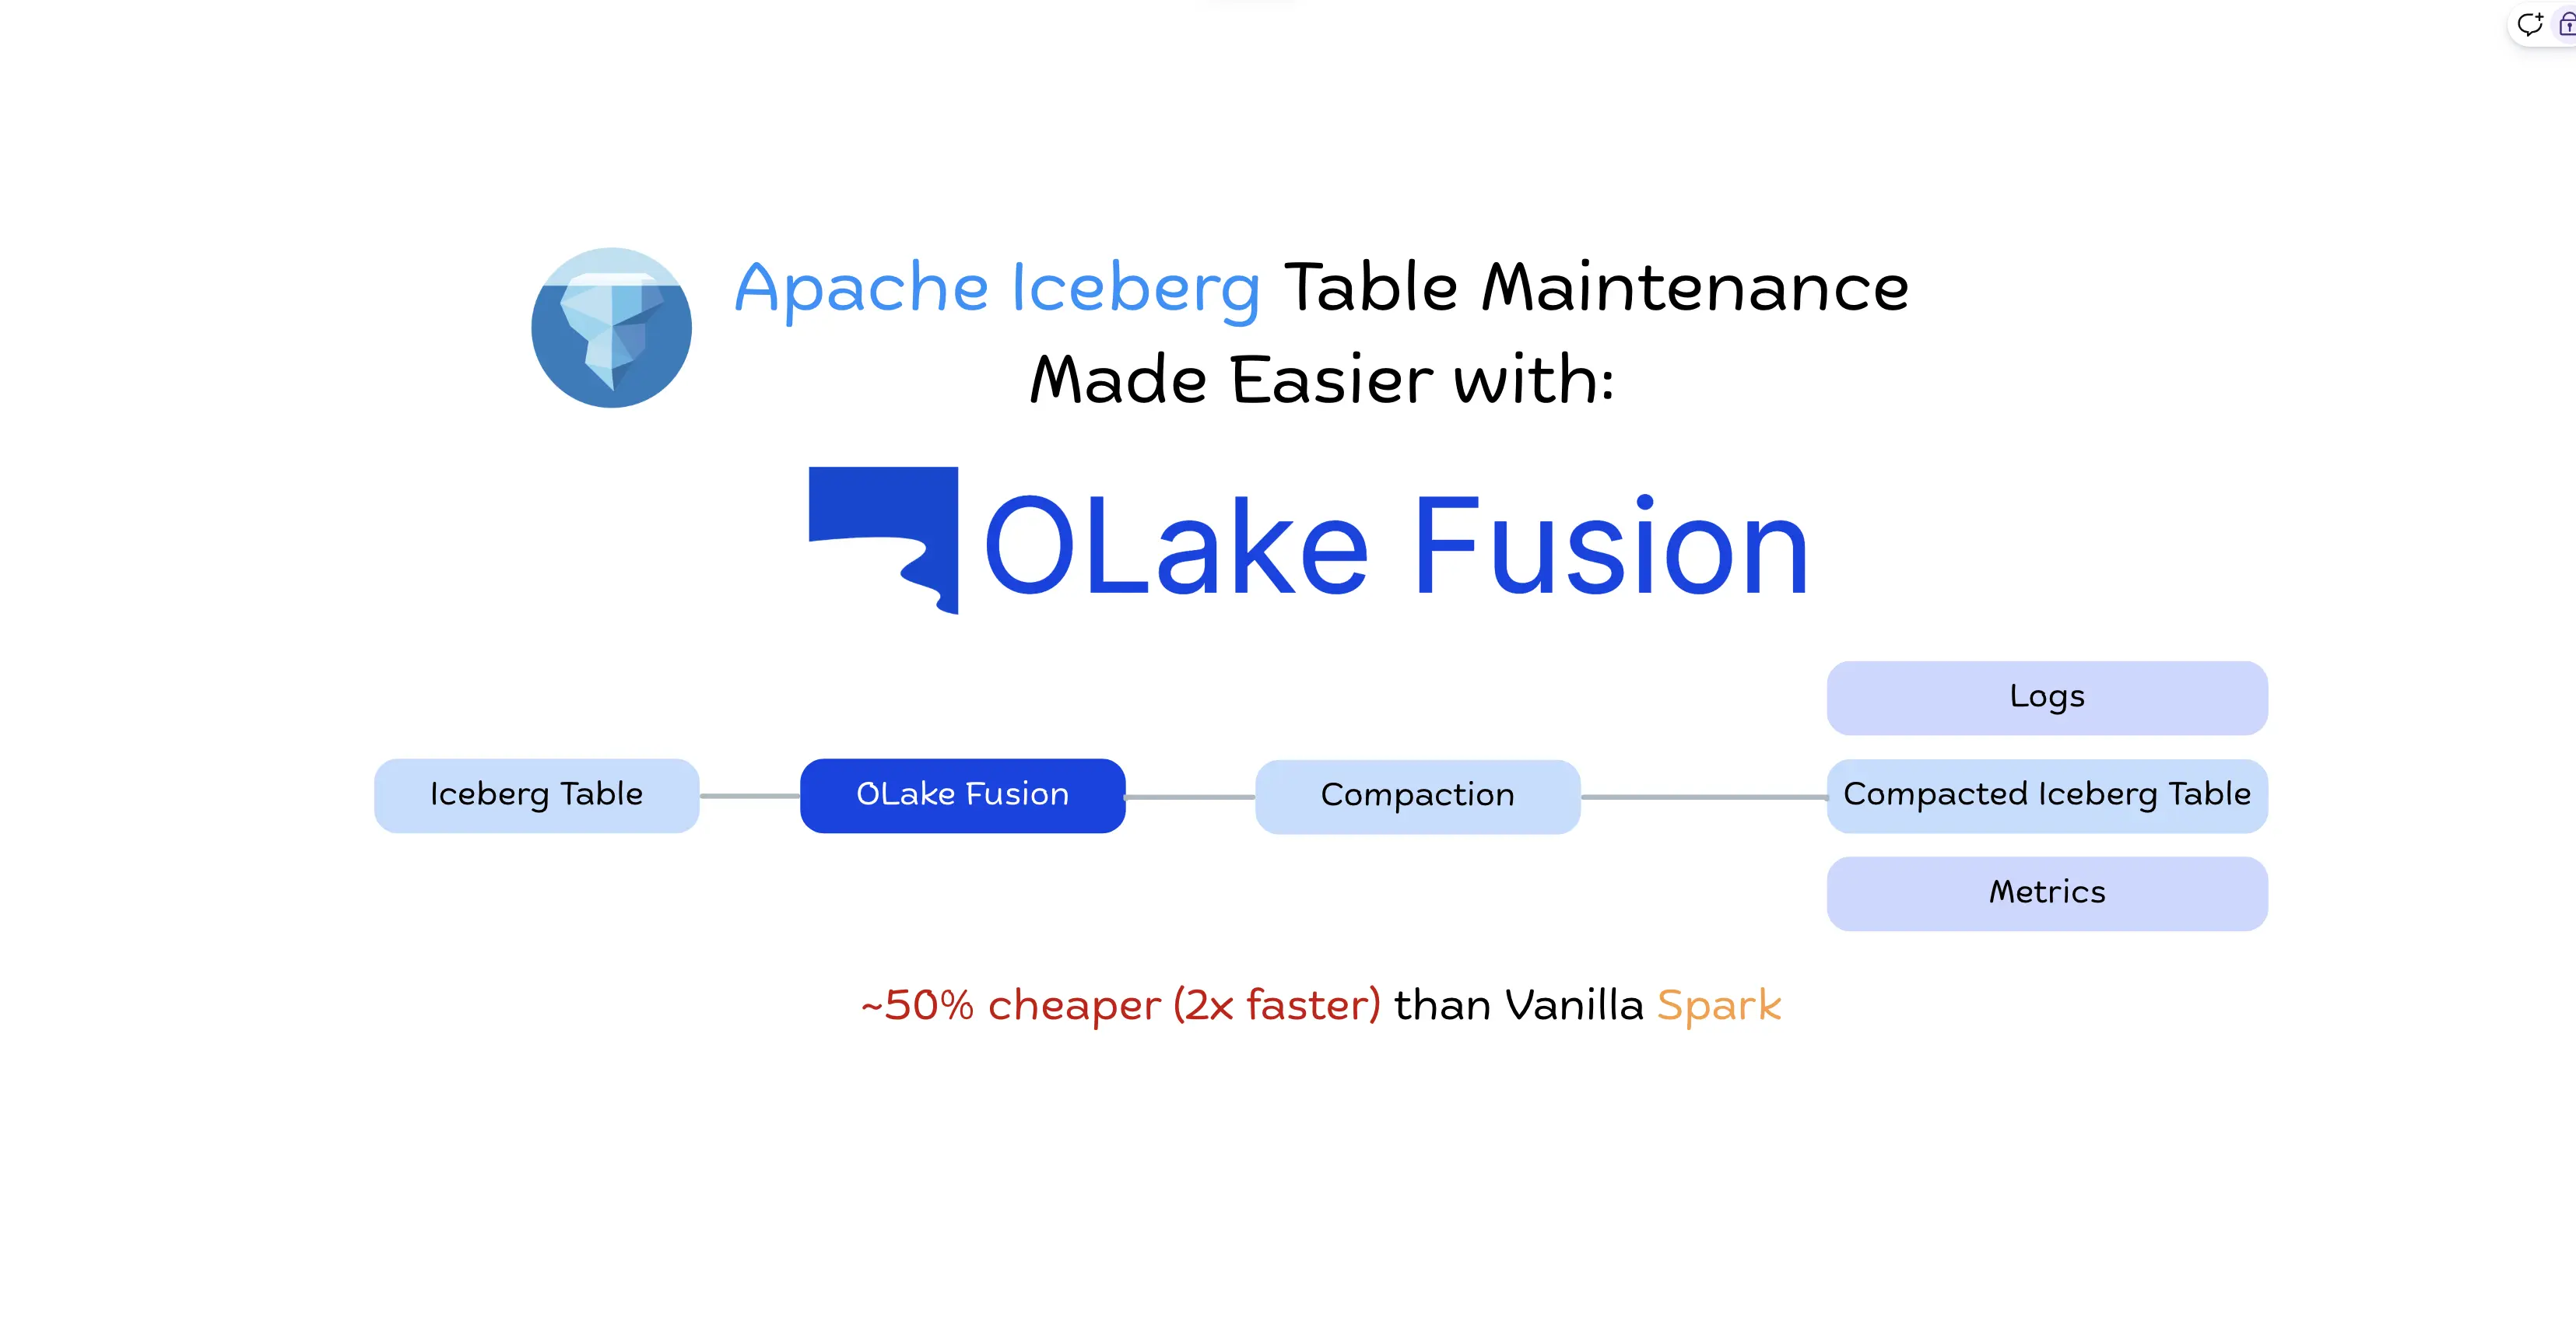
OLake Fusion handles Apache Iceberg table maintenance for CDC tables: tiered compaction for small and delete files, health metrics and lower Spark cost.
We benchmark Spark rewrite_data_files against OLake Fusion compaction on Apache Iceberg by running a full TPCH lineitem load from Postgres to GCP, applying 200k-record CDC batches every 2 minutes, and tracking TPC-H Query 6 performance, runtime, resource usage, and infrastructure cost.
Sync IBM Db2 LUW to Apache Iceberg with OLake Go: setup, configuration, sync modes, troubleshooting, and Db2 specifics like RUNSTATS and REORG.
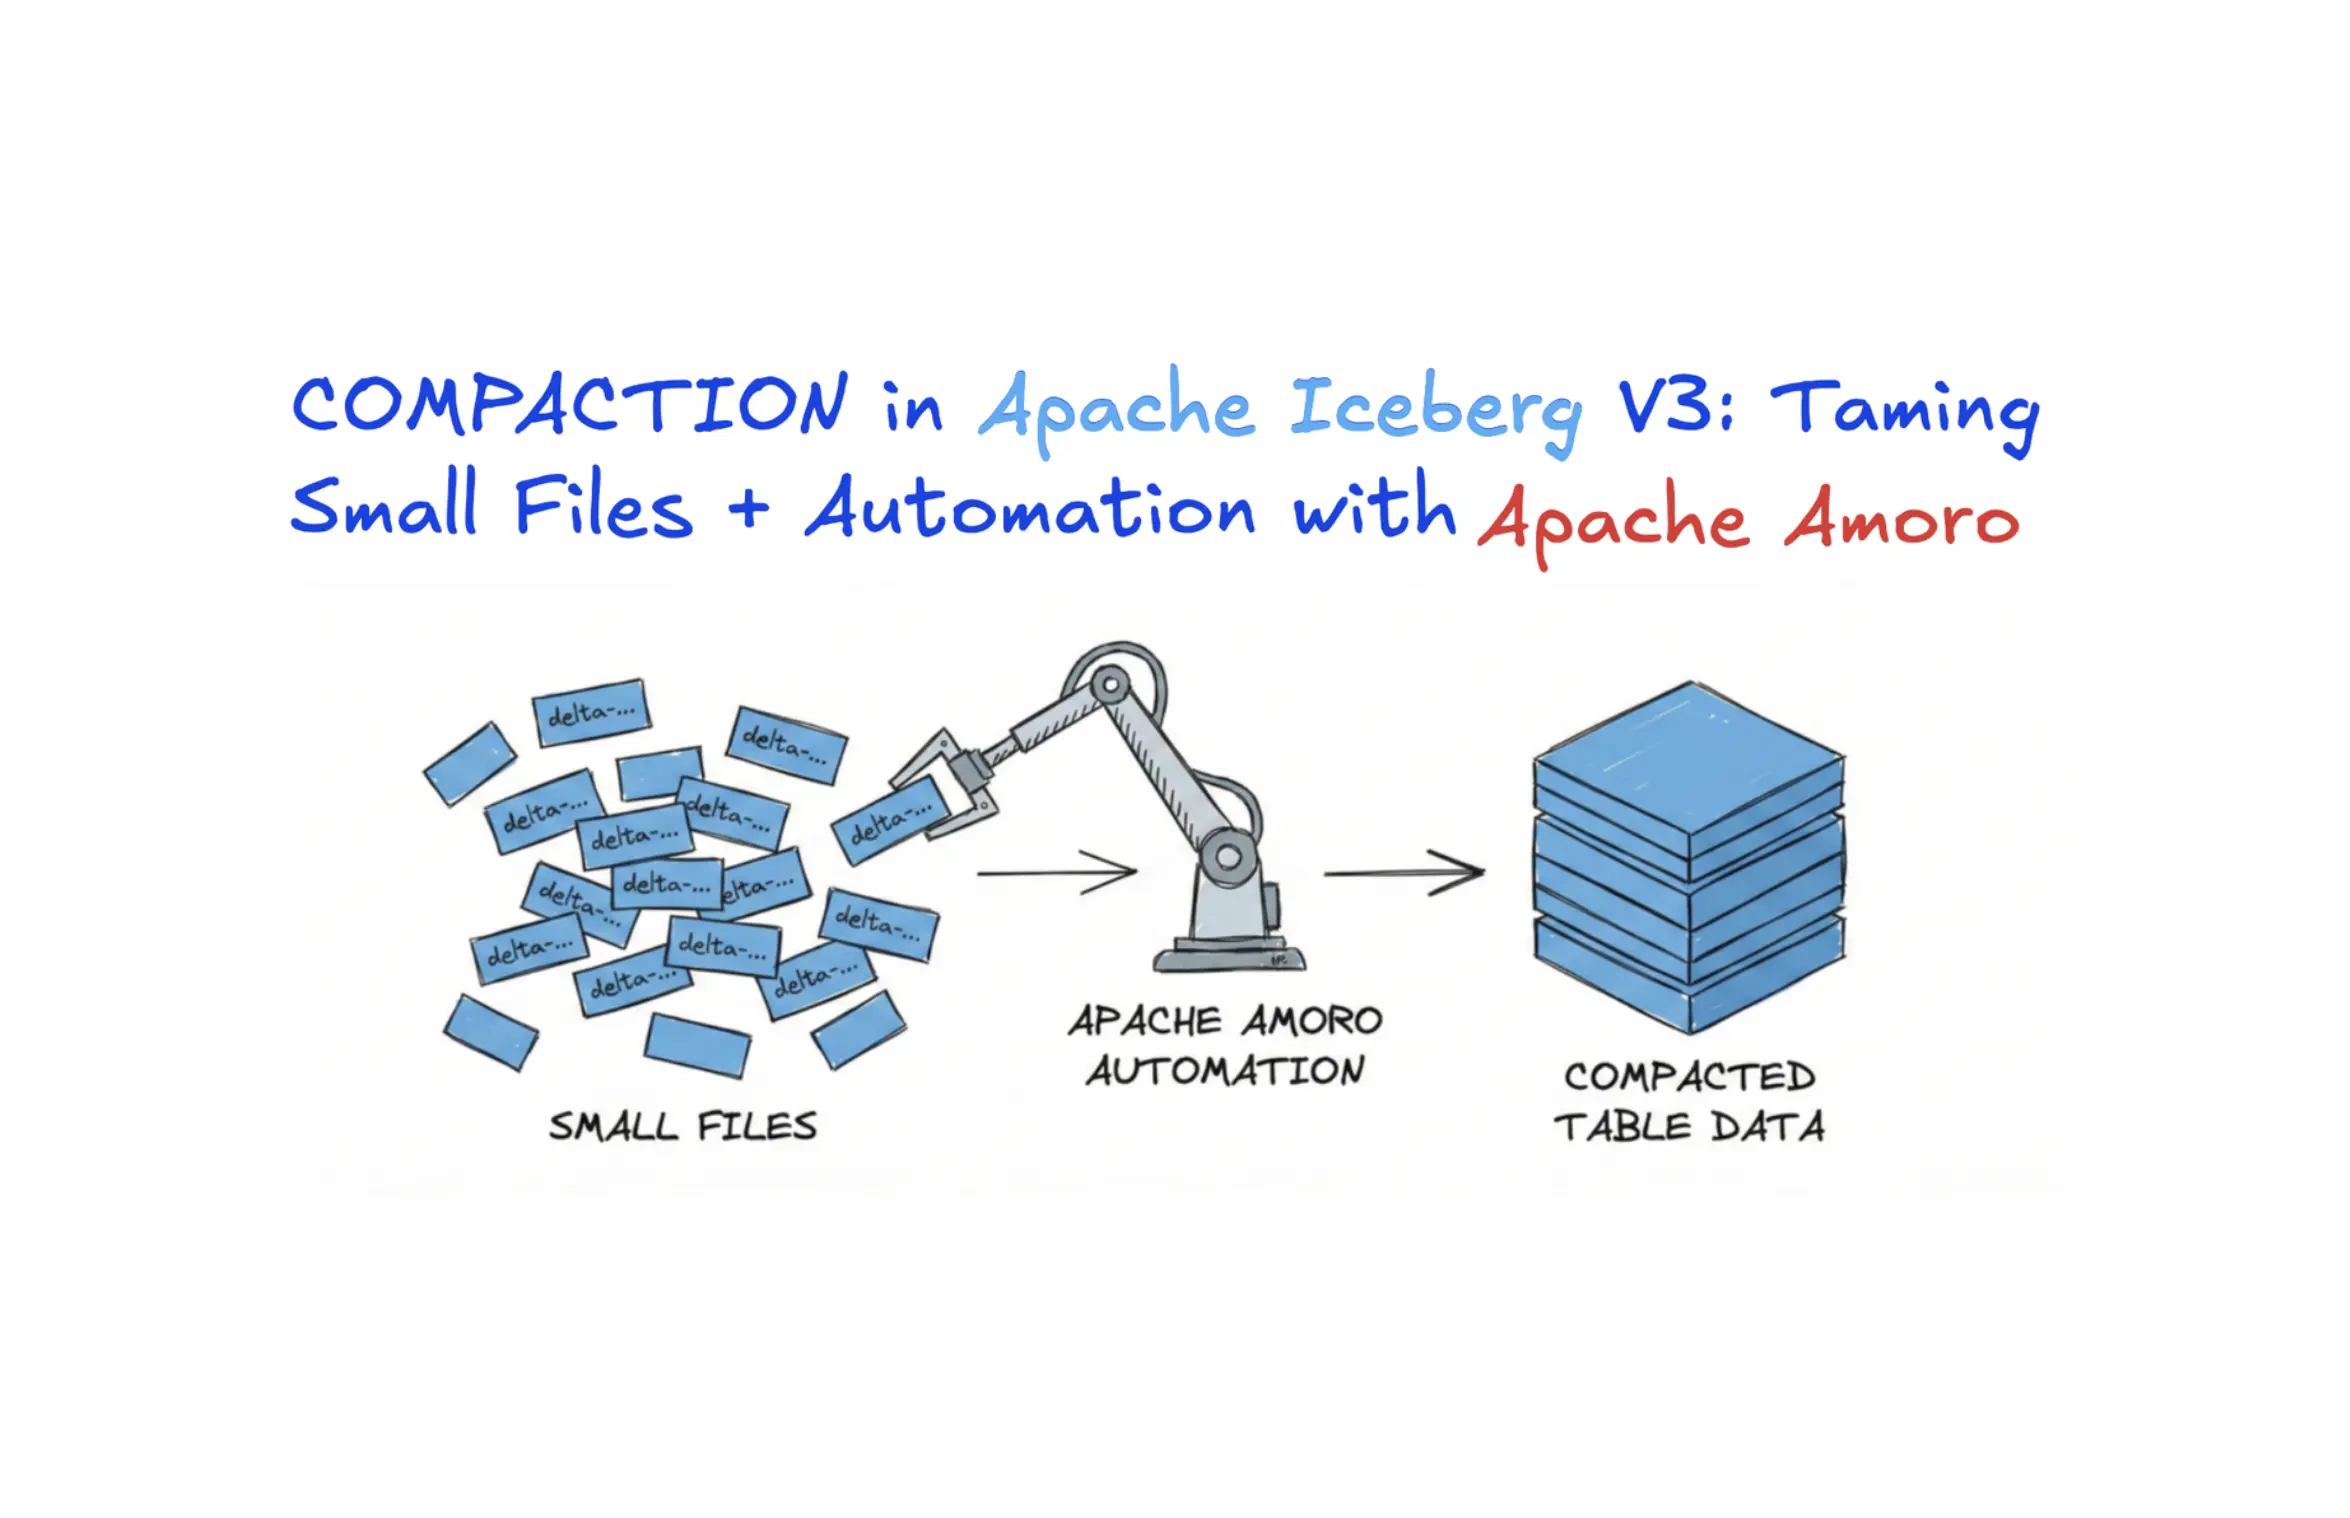
How to compact Apache Iceberg tables: fix small-file bloat, see when to run compaction and what gains to expect, and automate it with Apache Amoro.
Sync Microsoft SQL Server (MSSQL) to Apache Iceberg with OLake Go: sync modes, CDC setup, schema changes, data type mapping and troubleshooting.