Kafka to Redshift: Topics as Apache Iceberg
Kafka to Redshift usually means a Kafka Connect cluster with a Redshift sink, a Firehose stream, or a consumer that writes files for COPY, and tables that only Redshift can read. This guide takes a different route.
OLake Go reads the topics itself as a change data capture (CDC) stream and keeps one row per key. It writes the result once, as Apache Iceberg tables in the AWS Glue Data Catalog, with the files in your own S3 bucket.
Redshift maps the Glue database onto an external schema and queries the tables in place. Nothing else is in the path: no Kafka Connect, no Firehose, no load job. Athena and DuckDB read the same tables through the same catalog.
Key takeaways
- OLake Go turns Kafka topics into Iceberg tables in the Glue Data Catalog: each sync reads from the last committed offset and upserts messages on a deduplication key, so a repeated key updates its row instead of adding one.
- Redshift reads the Glue database through one
CREATE EXTERNAL SCHEMAstatement, with no refresh. Every change a sync commits is visible on the next query, on Serverless and RA3 alike. - The same tables, written once by OLake Go, are also queryable from Athena and DuckDB. In the run on this page all three engines returned identical rows.
The short answer. To stream Kafka to Redshift as Iceberg, run OLake Go with the Kafka cluster as the source and the AWS Glue Data Catalog as the destination. Put each topic in CDC Only mode with Upsert on a deduplication key.
The first sync reads every retained message; every later sync reads only the messages after the committed offsets. Redshift, Athena and DuckDB then query the same Iceberg tables, with no second copy.
How Kafka messages reach Redshift here
There is no separate snapshot phase, because the topic is the history. The first sync runs with a new consumer group, which has no committed offset, so it reads every message the broker still holds: on this page all 48.
OLake Go commits the Iceberg snapshot first and the consumer-group offsets second. A sync that fails mid-way therefore re-reads its messages on the next run. In Upsert mode the re-read is harmless; in Append mode it duplicates those rows.
Every later sync resumes from the committed offsets and reads only what arrived since. In Upsert mode a message whose deduplication key already exists in the table retires the old row with a positional delete and writes the new one.
A key seen for the first time becomes a new row. In Append mode every message is a row, which suits event logs that are never corrected.
One thing to keep an eye on: retention is the replay window. Kafka deletes messages past retention.ms, and OLake Go cannot read what is gone.
A job paused longer than the retention of its topics silently misses the expired messages. Set retention from your longest tolerable pause, not from disk size.
What you need
- A Kafka cluster on version 2.4 or later that OLake Go can reach, with JSON messages (or Avro plus a schema registry) on the topics you want. Amazon Managed Streaming for Apache Kafka (MSK), Confluent Cloud, Redpanda and self-hosted Kafka all work; the run on this page used a single-node Apache Kafka 4.3.1 in KRaft mode in Docker.
- A field that identifies each entity in every message, such as
id, when you want one row per key. Without it, run the topic in Append mode. - An AWS account with an S3 bucket for the files and an IAM user or role for OLake Go with Glue and S3 permissions. The run on this page used a bucket and a scoped IAM user in
ap-southeast-1. - Amazon Redshift, Serverless or an RA3 cluster, with an IAM role attached that can read Glue and the bucket. The run on this page used a Serverless workgroup at 8 RPU.
- OLake UI from the Docker Compose install, on OLake UI v0.7.1 or later with the OLake Go Kafka source on v0.12.1 or later, which is when Upsert mode for Kafka arrived. The run on this page used OLake Go v1.1.0.
- Docker, and about 40 minutes.
Step 1: Prepare the Kafka topics
Most readers point OLake Go at topics they already have. If you want to follow along with the exact data from this page, produce messages shaped like these first:
The two sample topics used on this page
Both topics have one partition and carry JSON values keyed by the entity id. The scripts ship with Apache Kafka under bin/; on Amazon Managed Streaming for Apache Kafka (MSK), run them from a client machine in the virtual private cloud (VPC) with the broker's bootstrap string.
kafka-topics.sh --bootstrap-server localhost:9092 --create --topic customers --partitions 1
kafka-topics.sh --bootstrap-server localhost:9092 --create --topic orders --partitions 1

# key<TAB>value, one message per line
printf '1\t{"id":1,"name":"Aarav Mehta","email":"aarav@example.com","city":"Mumbai","tier":"gold","created_at":"2026-10-29T15:22:04+00:00","updated_at":"2026-10-29T15:22:04+00:00"}\n' \
  | kafka-console-producer.sh --bootstrap-server localhost:9092 --topic customers --property parse.key=true --property key.separator=$'\t'

printf '1\t{"id":1,"customer_id":2,"product":"Headphones","amount":99.19,"status":"shipped","created_at":"2026-10-29T15:22:04+00:00","updated_at":"2026-10-29T15:22:04+00:00"}\n' \
  | kafka-console-producer.sh --bootstrap-server localhost:9092 --topic orders --property parse.key=true --property key.separator=$'\t'

# Then produce whatever you like. This page started with 8 customers and 40 orders.
Kafka is already a change stream, so there is no log to switch on. OLake Go reads each topic from its retained offsets and commits the position it reached in a consumer group. Four things must be in place before the first sync.
| Requirement | Value | Why it matters |
|---|---|---|
| Message format | JSON values, or Avro with a schema registry | OLake Go turns each message into a row. Anything else (Protobuf, plain text) cannot be mapped to columns. |
| A stable field per entity | For example id in the payload, or the message key | Upsert mode needs a deduplication key to know which earlier row a message replaces. Keep it in every message and never change it. |
| A consumer group for OLake Go only | One group per job | OLake Go stores its offsets there. Sharing the group with another consumer, or between two jobs, moves offsets under its feet. |
| Retention longer than your longest pause | For example 7 days | Kafka deletes messages past the retention limit. A job paused longer than that cannot read them, and they are gone. |
If the cluster enforces access control lists (ACLs), the user OLake Go connects with needs Read and Describe on the topics and Read on its consumer group. This is what the setup looked like for the run on this page, with the scripts that ship with Apache Kafka; Redpanda's rpk topic create and rpk security acl create do the same:
# 1. The topics, with retention long enough to cover a pause
kafka-topics.sh --bootstrap-server localhost:9092 --create --topic customers --partitions 1 --config retention.ms=604800000
kafka-topics.sh --bootstrap-server localhost:9092 --create --topic orders --partitions 1 --config retention.ms=604800000

# 2. If ACLs are on: a principal for OLake Go (one command per resource type)
kafka-acls.sh --bootstrap-server localhost:9092 --add --allow-principal User:olake \
--operation Read --operation Describe --topic customers --topic orders
kafka-acls.sh --bootstrap-server localhost:9092 --add --allow-principal User:olake \
--operation Read --group olake_<job_name>
Each message needs the entity's identifier in its value, and the key is the natural place to repeat it. A record for the sample customers topic looks like this, with _kafka_key set to the same id:
{"id": 3, "name": "Liam Carter", "email": "liam@example.com", "city": "Austin", "tier": "gold",
 "created_at": "2026-10-29T15:22:04+00:00", "updated_at": "2026-10-29T15:22:04+00:00"}
A topic with retention.ms of one day keeps one day of messages. If the job is paused for two, the first day is gone before OLake Go reads it, and nothing in the destination tells you. Set retention from the longest pause you can tolerate, and alert when a job has not run for a good fraction of it.
Step 2: Set up the Glue catalog
Redshift reads Iceberg tables through a catalog. AWS Glue Data Catalog is the one this page uses: OLake Go creates a Glue database per job and registers each table there. The files sit in your S3 bucket.
Redshift, Athena, Amazon Elastic MapReduce (EMR) and DuckDB all read from the same catalog. Redshift reaches it through an external schema, with the IAM role attached to the workgroup or cluster.
| Catalog | OLake Go writes | Amazon Redshift reads | Verified on this page |
|---|---|---|---|
| AWS Glue | Yes | Yes: external schema from the Glue Data Catalog | Yes, end to end |
- AWS Glue
AWS Glue Data Catalog is the default catalog in OLake Go. The tables live as Parquet and metadata files in an S3 bucket you own, and Glue holds the pointer to the current metadata file. Athena, Redshift, EMR, Spark and DuckDB read the same tables through Glue, which is why it is the catalog to pick when more than one AWS engine will read the data.
You need:
- An S3 bucket for the table files, in the region where your engines run.
- An IAM user or role for OLake Go with Glue and S3 permissions. The exact policy is on the AWS Glue catalog page.
- No Glue database in advance: OLake Go creates one per job, named after the source database and schema (for example
pg_to_snowflake_shop_public).
Glue has no built-in compaction for tables written by external engines, so plan on OLake Fusion or Spark for maintenance once the change volume grows.
The run on this page gave OLake Go a scoped IAM user with this inline policy. Redshift got a role with AmazonS3ReadOnlyAccess and read access to Glue:
{
  "Version": "2012-10-17",
  "Statement": [
    { "Effect": "Allow", "Action": ["s3:ListBucket", "s3:GetBucketLocation"], "Resource": "arn:aws:s3:::<bucket>" },
    { "Effect": "Allow", "Action": ["s3:GetObject", "s3:PutObject", "s3:DeleteObject", "s3:AbortMultipartUpload", "s3:ListMultipartUploadParts"], "Resource": "arn:aws:s3:::<bucket>/*" },
    { "Effect": "Allow",
      "Action": ["glue:GetDatabase", "glue:GetDatabases", "glue:CreateDatabase", "glue:GetTable", "glue:GetTables", "glue:CreateTable", "glue:UpdateTable", "glue:DeleteTable"],
      "Resource": ["arn:aws:glue:<region>:<account>:catalog", "arn:aws:glue:<region>:<account>:database/*", "arn:aws:glue:<region>:<account>:table/*/*"] }
  ]
}
Step 3: Connect Kafka to OLake Go
- OLake UI
- OLake CLI
- In the OLake UI, open Sources and click Create Source. Pick Kafka as the connector, give the source a name and keep the OLake Go version on the latest release.
- The Enable CDC toggle under Change data capture (CDC) reads not supported for Kafka and stays off. That is expected: the topic is the change stream, and the job's CDC Only sync mode reads it.
- Under Connection details, fill in Bootstrap Servers (
host:port, comma-separated for several brokers), a Consumer Group ID for this job only, and a Topic Pattern regular expression that matches only the topics you want. Pick the Security Protocol the cluster uses:PLAINTEXT,SASL_PLAINTEXTorSASL_SSL, with the SASL mechanism and credentials when needed. Turn on Use Schema Registry only for Avro topics. - Leave Additional configuration at its defaults, or set Max Threads to the number of partitions you want read in parallel.
- Click Set up source. OLake Go pings the brokers. Topics are matched against the pattern at discovery, when the job is created; if the pattern matches nothing, the Streams page comes up empty and the sync log names every topic it skipped.
Here is the source form from the run on this page. Kafka ran in another container, so the bootstrap server is host.docker.internal:19092; the topic pattern ^(customers|orders)$ keeps discovery to the two sample topics.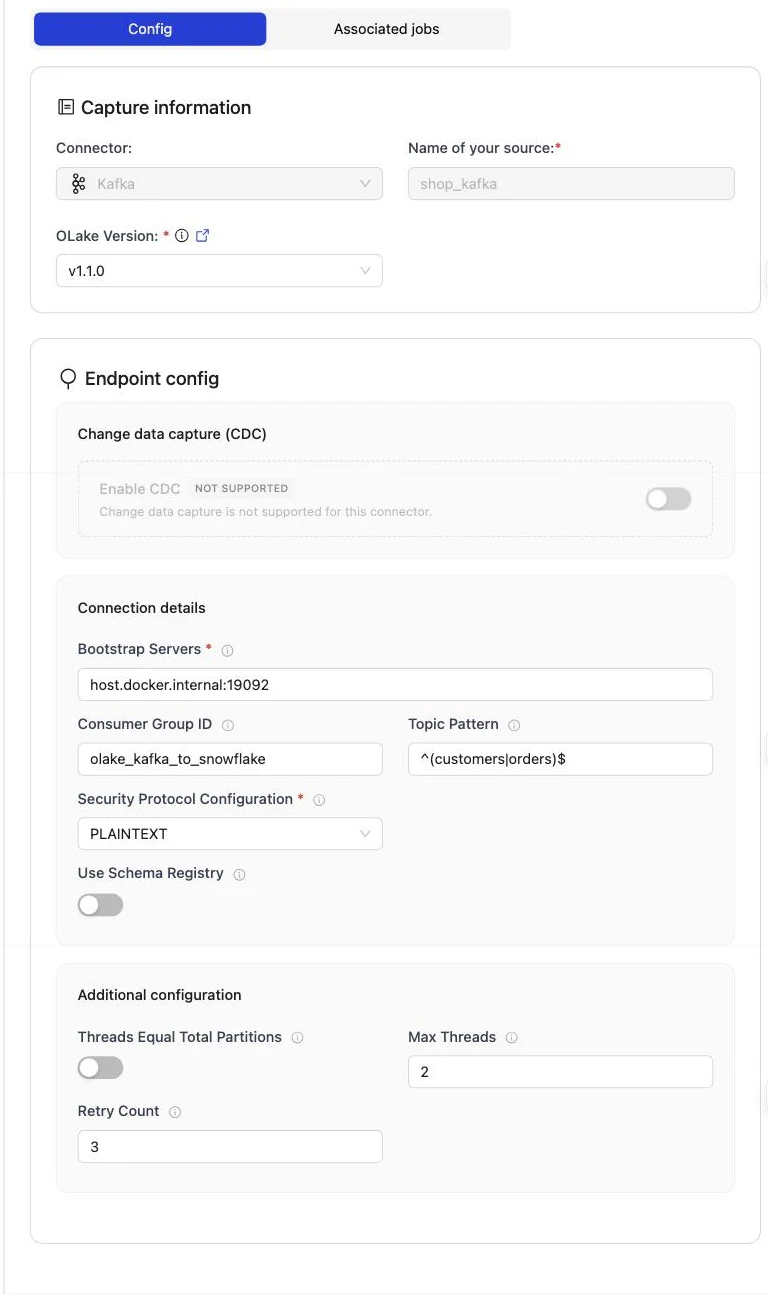
Set up source pings the brokers before anything is saved. The consumer group is created on the first sync; it does not need to exist yet.
The full field reference, including SASL and schema-registry options, is on the Kafka connector page.
Create source.json in your config folder. bootstrap_servers, protocol and consumer_group_id are the fields that matter; topic_pattern keeps discovery to the topics you want:
{
    "bootstrap_servers": "broker:9092, broker:9093",
    "protocol": {
      "security_protocol": "SASL_SSL",
      "sasl_mechanism": "SCRAM-SHA-512",
      "sasl_jaas_config": "org.apache.kafka.common.security.scram.ScramLoginModule required username=\"YOUR_KAFKA_USERNAME\" password=\"YOUR_KAFKA_PASSWORD\";"
    },
    "consumer_group_id": "example-consumer-group",
    "max_threads": 3,
    "threads_equal_total_partitions": false,
    "backoff_retry_count": 3,
    "topic_pattern": "^orders-.*",
    "schema_registry": {
      "endpoint": "http://localhost:8081",
      "username": "dummy",
      "password": "password"
  }
}
Then confirm OLake Go can reach the brokers:
docker run --pull=always \
  -v "$PWD/config:/mnt/config" \
  olakego/source-kafka:latest \
  check --config /mnt/config/source.json
A working setup returns "status": "SUCCEEDED". A wrong address returns failed to ping kafka brokers: unable to dial, which means the container cannot reach the port, not that the credentials are wrong. Every field is described on the Kafka connector page.
Step 4: Configure the Iceberg destination
- AWS Glue
- OLake UI
- OLake CLI
- Open Destinations and click Create Destination.
- Pick Apache Iceberg as the connector and AWS Glue as the catalog type.
- Enter the S3 path, the AWS region and the access key pair (or leave the keys empty to use the instance role).
- Click Create.
| Parameter | Sample Value | Description |
|---|---|---|
S3 Path required | s3://<BUCKET_NAME>/ | S3 bucket path where Iceberg table data and metadata files will be stored. |
AWS Region required | ap-south-1 | AWS Region where your S3 bucket and Glue Data Catalog exist. Required so OLake Go calls the correct regional S3 and Glue endpoints. |
| AWS Access Key | XXX | AWS access key ID for authentication. Optional if using IAM roles or instance profiles. If using IAM: Docker Compose: add the required IAM environment variables under x-envs in your compose file. See Service Environment Variables for setup details.Kubernetes: set up pod IAM in Cloud Integration. |
| AWS Secret Key | XXX | AWS secret access key for authentication. Optional if using IAM roles or instance profiles. If using IAM: Docker Compose: add the required IAM environment variables under x-envs in your compose file. See Service Environment Variables for setup details.Kubernetes: set up pod IAM in Cloud Integration. |
| S3 Endpoint | https://glue.ap-south-1.amazonaws.com | S3 API endpoint for writing Iceberg data files. Optional for AWS S3 but required for S3-compatible storage like MinIO. |
| Custom Glue Endpoint Configuration | true/false | Enable custom Glue catalog configuration when Glue catalog settings differ from S3 (different credentials, region, or endpoint). Shows additional Glue configuration fields. Leave off when Glue and S3 use the same AWS setup. |
| Enable Arrow Writes | true/false | Writes data and delete files using Apache Arrow based writer and registers them in Iceberg. |
The following fields appear in the UI after Custom Glue Endpoint Configuration is turned on. Configure Glue catalog connection settings here separately from the S3 fields above.
| Parameter | Sample Value | Description |
|---|---|---|
| Glue Catalog ID | 123456789012 | AWS account ID used as the Glue Data Catalog identifier. |
| Glue Access Key | XXX | Access key for authenticating Glue catalog requests. Required when Glue credentials differ from S3 credentials. |
| Glue Secret Key | XXX | Secret key for authenticating Glue catalog requests. Required when Glue credentials differ from S3 credentials. |
| Glue Endpoint | https://glue.ap-south-1.amazonaws.com | Custom endpoint URL for AWS Glue or a Glue-compatible catalog service. |
| Glue Region | ap-south-1 | Region for the Glue catalog, if different from the S3 region. Falls back to AWS Region if not set. |
{
    "type": "ICEBERG",
    "writer": {
      "catalog_type": "glue",
      "catalog_name": "olake_iceberg",
      "iceberg_s3_path": "s3://<BUCKET_NAME>/",
      "aws_region": "<AWS_REGION>",
      "aws_access_key": "<AWS_ACCESS_KEY>",
      "aws_secret_key": "<AWS_SECRET_KEY>",
      "arrow_writes": false
    }
}
| Parameter | Sample Value | Description |
|---|---|---|
iceberg_s3_path required | s3://<BUCKET_NAME>/ | S3 bucket path where Iceberg table data and metadata files will be stored. |
aws_region required | ap-south-1 | AWS Region where your S3 bucket and Glue Data Catalog exist. Required so OLake Go calls the correct regional S3 and Glue endpoints. |
| aws_access_key | XXX | AWS access key ID for S3 authentication. Optional if using IAM roles or instance profiles. If using IAM: add the required IAM environment variables in your shell or runtime environment. |
| aws_secret_key | XXX | AWS secret access key for S3 authentication. Optional if using IAM roles or instance profiles. If using IAM: add the required IAM environment variables in your shell or runtime environment. |
| s3_endpoint | https://glue.ap-south-1.amazonaws.com | S3 API endpoint for reading/writing Iceberg data files. Optional for AWS S3 but required for S3-compatible storage like MinIO. |
| glue_additional_config | true/false | Enable custom Glue catalog configuration when Glue catalog settings differ from S3 (different credentials, region, or endpoint). Leave off when Glue and S3 use the same AWS setup. |
| arrow_writes | false | Writes data and delete files using Apache Arrow based writer and registers them in Iceberg. |
When using separate Glue catalog settings, set glue_additional_config to true in destination.json and add the fields below. These configure Glue catalog connection settings separately from the S3 fields above.
| Parameter | Sample Value | Description |
|---|---|---|
| glue_catalog_id | 123456789012 | AWS account ID used as the Glue Data Catalog identifier. |
| glue_access_key | XXX | Access key for authenticating Glue catalog requests. Required when Glue credentials differ from S3 credentials. |
| glue_secret_key | XXX | Secret key for authenticating Glue catalog requests. Required when Glue credentials differ from S3 credentials. |
| glue_endpoint | https://glue.ap-south-1.amazonaws.com | Custom endpoint URL for AWS Glue or a Glue-compatible catalog service. |
| glue_region | ap-south-1 | Region for the Glue catalog, if different from the S3 region. Falls back to AWS Region if not set. |
Here is the destination form from the run on this page. It holds the bucket path OLake Go writes under, the region of the bucket and the Glue catalog, and the access key pair of the IAM user from step 2.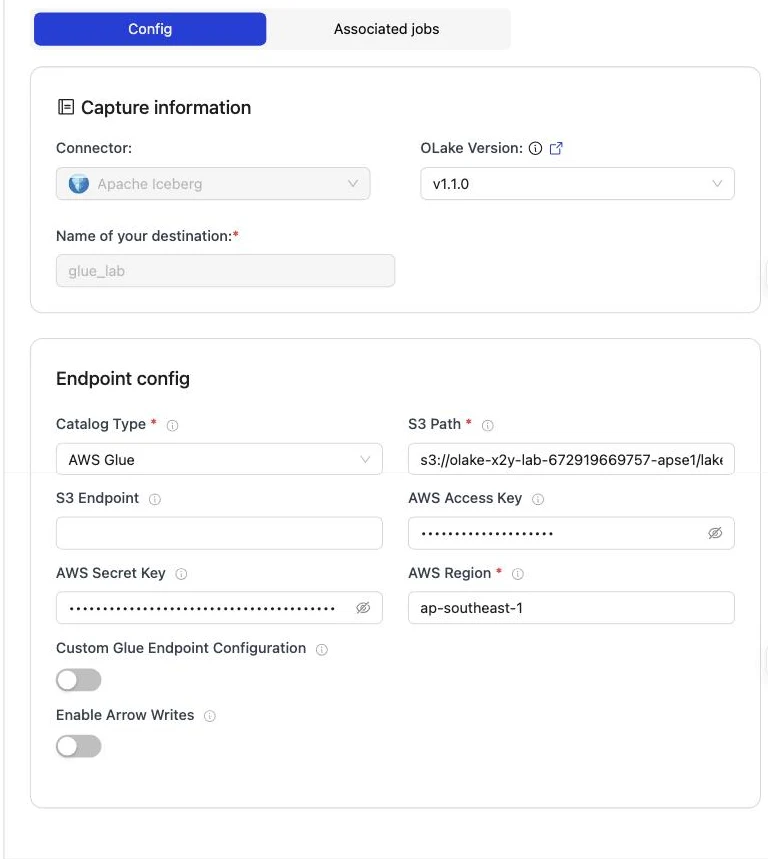
Step 5: Create the job and run the first sync
Redshift is not in OLake Go's target engine picker yet. This job therefore lists Athena and DuckDB as target engines.
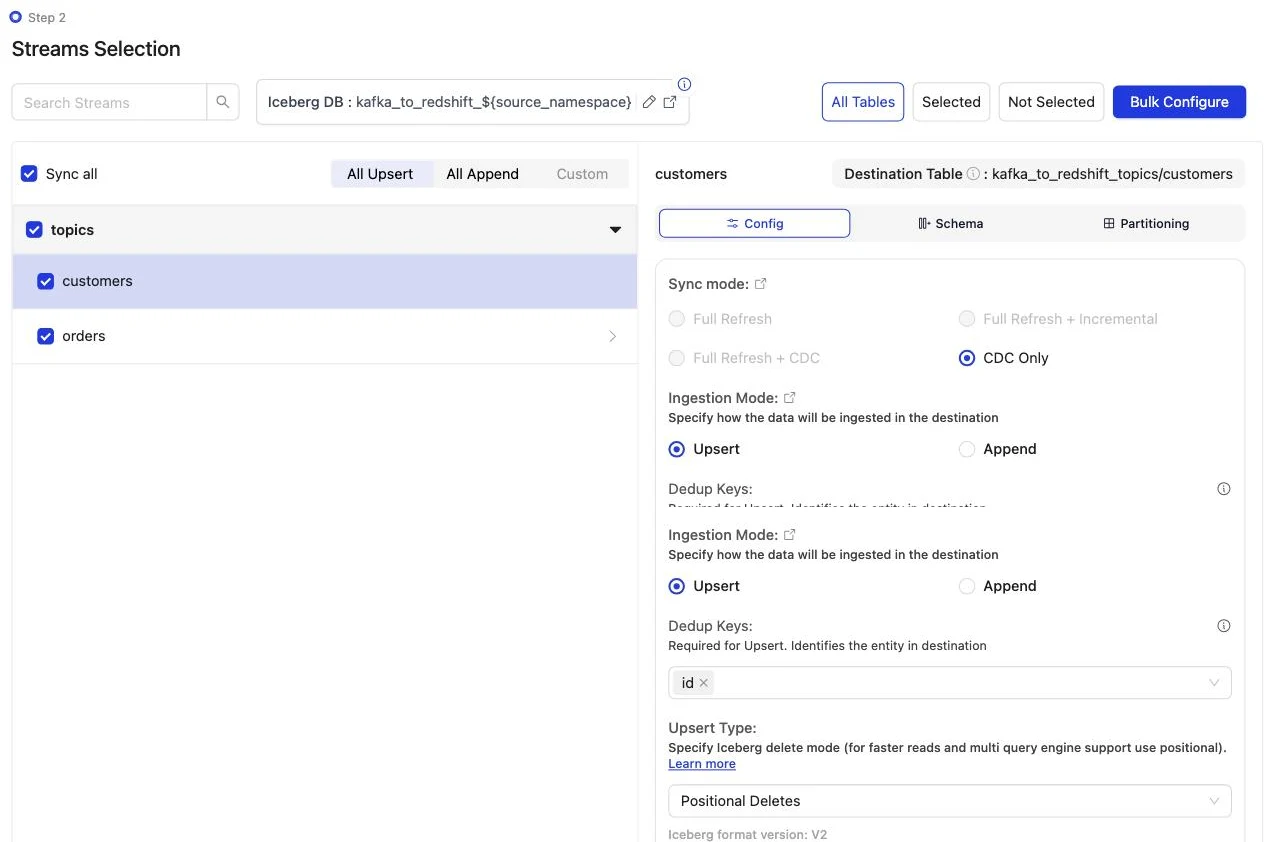
Kafka streams offer one sync mode, CDC Only, and the upsert type on this job is Positional Deletes, the format Redshift reads. From OLake Go v1.1.1 and OLake UI v0.8.2 Kafka upserts can also write deletion vectors. The decisions on the Streams page are the ingestion mode and the deduplication key.
- OLake UI
- OLake CLI
- Open Jobs and click Create Job. Give it a name and a schedule. Every Day at a fixed hour, or a cron expression, both work; the schedule is how often the change stream is drained, not how often a full copy runs.
- Select the source and the destination you created.
- Under Advanced Settings, set Target Query Engines to AWS Athena and DuckDB (Redshift is not in the list yet; it reads what Athena reads). OLake Go then resolves an Iceberg delete format every one of those engines can read, so you never pick one by hand.
- Click Next. OLake Go discovers the topics and opens the Streams page.
- Tick the topics to replicate. For each one, set the sync mode to CDC Only and the ingestion mode to Upsert. Under Dedup Keys, pick
id: that is the field OLake Go uses to match a later message to the row it replaces. Leave the Upsert Type as OLake Go resolved it (Positional Deletes in the run on this page). - Click Create Job, then open the job's menu and choose Sync Now for the first run.
Discover the topics, choose the streams, then sync:
docker run --pull=always \
-v "$PWD/config:/mnt/config" \
olakego/source-kafka:latest \
discover --config /mnt/config/source.json
discover writes two files: available_streams.json (every topic it found, do not edit) and selected_streams.json (the topics you want and their settings). In selected_streams.json, set sync_mode to {props.cliSyncMode ?? 'cdc'} for each topic and pick the delete format your readers can open:
{
"selected_streams": {
  "topics": [
    {
      "stream_name": "customers",
      "sync_mode": "strict_cdc",
      "normalization": true,
      "append_mode": false,
      "dedup_keys": ["id"],
      "update_type": "pos"
    }
  ]
}
}
update_type accepts eq (equality deletes, the default), pos (positional deletes) and dv (deletion vectors). Positional deletes and deletion vectors keep a small index between runs, so give the container a persistent directory for it through OLAKE_INDEX_DB_DIR. The first sync runs without a state file; OLake Go writes one at the end of the run:
docker run --pull=always \
-v "$PWD/config:/mnt/config" \
-e OLAKE_INDEX_DB_DIR=/mnt/config/index-db \
olakego/source-kafka:latest \
sync \
--config /mnt/config/source.json \
--selected-streams /mnt/config/selected_streams.json \
--available-streams /mnt/config/available_streams.json \
--destination /mnt/config/destination.json
Every later run adds --state /mnt/config/state.json to the same command, which is how OLake Go knows to replay only the changes since the last run. The full selected_streams.json reference is on the Docker CLI page; the index directory is described under index DB setup.
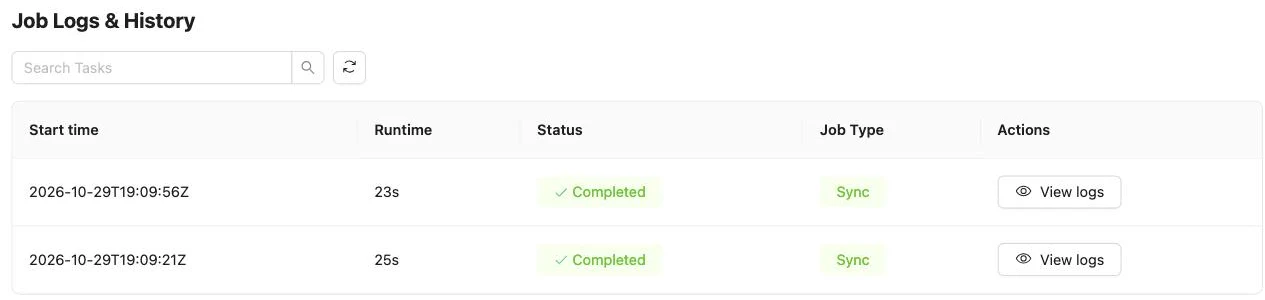
On this page the first run read 8 customer and 40 order messages (48 records, 9.00 KB) and finished in 25 seconds, container start included. OLake Go names the Glue database after the job and the source namespace.
The namespace for every Kafka topic is topics, so kafka_to_redshift produced kafka_to_redshift_topics. The Iceberg DB field at the top of the Streams page changes it before the first sync.
Step 6: Query the tables in Redshift
- AWS Glue
Redshift reads the Glue Data Catalog through an external schema: one statement maps a Glue database onto a schema name in your Redshift database, and every Iceberg table OLake Go commits there is queryable at once, with no refresh. Redshift Serverless and RA3 clusters both do this; the IAM role attached to the namespace or cluster needs read access to Glue and to the bucket.
-- Once: map the Glue database OLake Go created (schema = <job name>_<source database>_<source schema>)
CREATE EXTERNAL SCHEMA lakehouse
FROM DATA CATALOG
DATABASE 'kafka_to_redshift_topics'
IAM_ROLE default;

-- Then query the Iceberg tables like any other schema
SELECT id, name, city, tier FROM lakehouse.customers ORDER BY id;
SELECT status, count(*) AS n, round(sum(amount), 2) AS total
FROM lakehouse.orders GROUP BY status ORDER BY status;
IAM_ROLE default uses the default role of the namespace (Serverless) or cluster; name a role ARN instead when you keep several. Redshift reads Iceberg v2 tables with positional deletes, which is why the job on this page uses that upsert type. The external schema is read-only: OLake Go is the writer, and INSERT or DELETE on these tables fails.
OLake Go adds four columns to every table: _olake_id (a hash of the primary key), _op_type, _olake_timestamp and _cdc_timestamp. _op_type is r for a row from the first snapshot, c for an insert, u for an update and d for a delete. Filter them out of dashboards, or use them to see when a row last changed.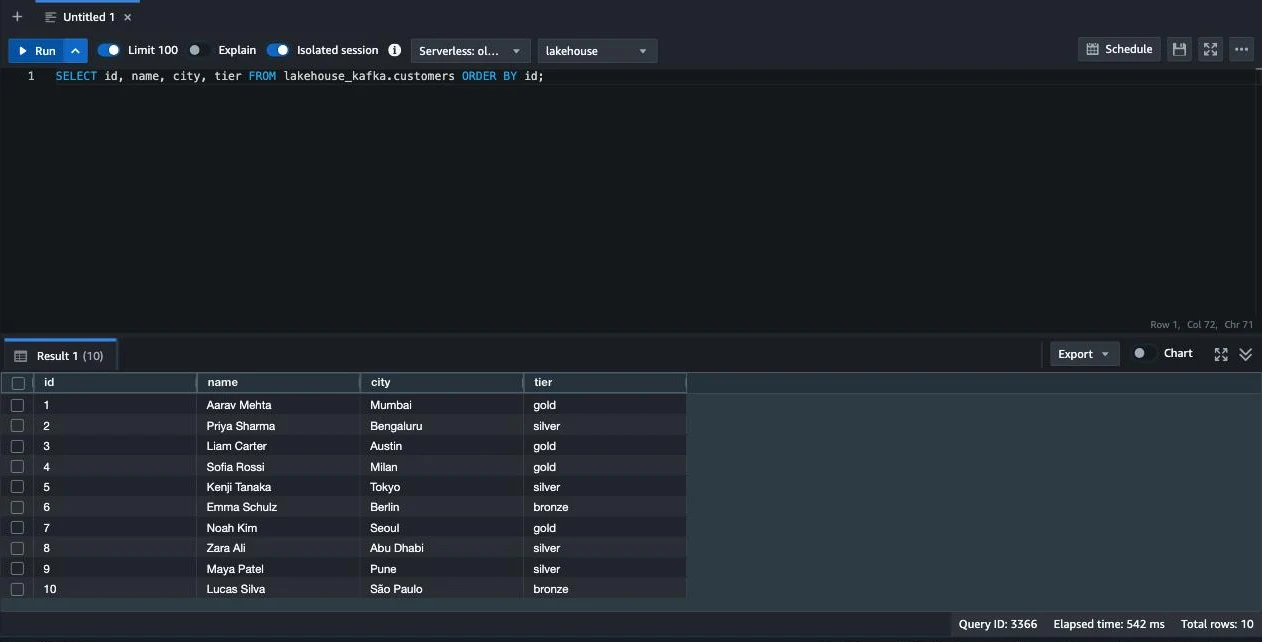
Step 7: Produce new messages and sync again
To see the change path work, the run on this page produced 12 more messages after the first sync. Seven carry new keys; five repeat an existing key with a changed value.
# customers: two new keys, two repeated keys
9   {"id":9,"name":"Maya Patel","email":"maya@example.com","city":"Pune","tier":"silver", ...}
10  {"id":10,"name":"Lucas Silva","email":"lucas@example.com","city":"São Paulo","tier":"bronze", ...}
3   {"id":3,"name":"Liam Carter","email":"liam@example.com","city":"Austin","tier":"gold", ...}
8   {"id":8,"name":"Zara Ali","email":"zara@example.com","city":"Abu Dhabi","tier":"silver", ...}

# orders: five new keys (41 to 45), three repeated keys (1, 4, 7) with status "delivered"
41  {"id":41,"customer_id":9,"product":"Laptop","amount":1299.0,"status":"placed", ...}
1   {"id":1,"customer_id":2,"product":"Headphones","amount":99.19,"status":"delivered", ...}
The second sync read 12 records (2.26 KB) from the two topics and finished in 23 seconds end to end. For customers that meant one new data file with 4 rows: the 2 new keys plus the new versions of the 2 repeated keys.
One small positional delete file retires the 2 old versions. OLake Go's commit report in the sync log shows it directly: addedDataFiles=1, addedRecords=4, addedPositionalDeleteFiles=1, addedPositionalDeletes=2. The orders table has the same shape with 8 rows and 3 deletes.
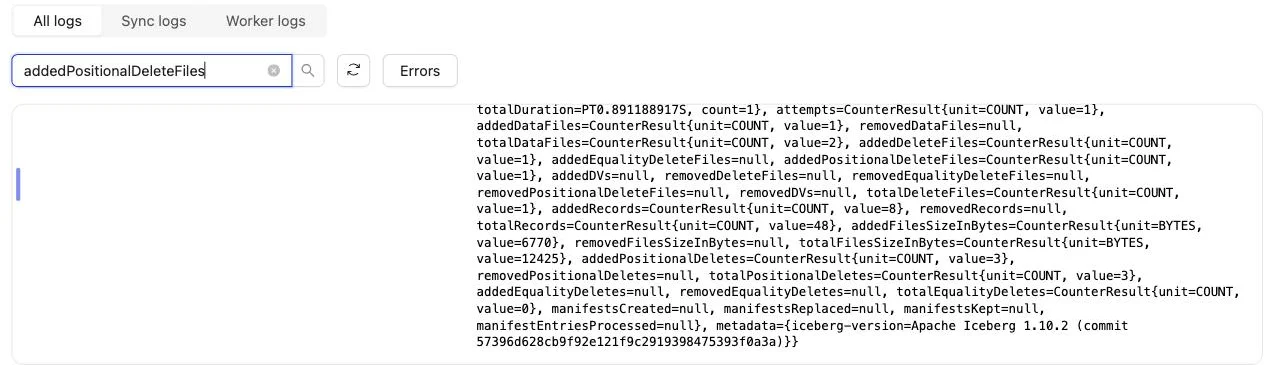
Redshift shows the result on the next query, with no refresh. Liam Carter is gold, Zara Ali moved to Abu Dhabi, and the two new customers are there, with still one row per key. The _op_type column shows how each row arrived (c for a first-seen key, u for a repeated key) and _kafka_offset shows which message it came from.
Schema changes. When a new field appears in the messages, OLake Go adds it as a column on the next sync and updates the Glue table definition. Redshift shows it on the next query of the external schema.
A field whose type changes in an incompatible way fails the sync rather than corrupt the table. Full rules are on the schema evolution page.
Query the same tables from Athena and DuckDB
This is the point of writing Iceberg instead of loading Redshift tables. Nothing is exported, copied or refreshed: both engines read the files OLake Go wrote, through the same Glue database.
- Amazon Athena
- DuckDB
Athena reads the Glue Data Catalog natively: the Glue database OLake Go created shows up in the query editor's database list, and the Iceberg tables in it need no registration and no refresh. Pick a workgroup with a query result location in S3, select the database, and query.
SELECT id, name, city, tier FROM kafka_to_redshift_topics.customers ORDER BY id;
SELECT status, count(*) AS n, round(sum(amount), 2) AS total
FROM kafka_to_redshift_topics.orders GROUP BY status ORDER BY status;
Athena engine v3 reads Iceberg v2 tables with positional and equality deletes, and cannot read v3 tables at all. Keep the job on positional or equality deletes, never deletion vectors, while Athena is a reader. From the command line, aws athena start-query-execution --work-group <workgroup> --query-execution-context Database=${props.schema ?? 'postgres_to_redshift_shop_public'} --query-string "..." runs the same queries; aws athena get-query-results returns the rows.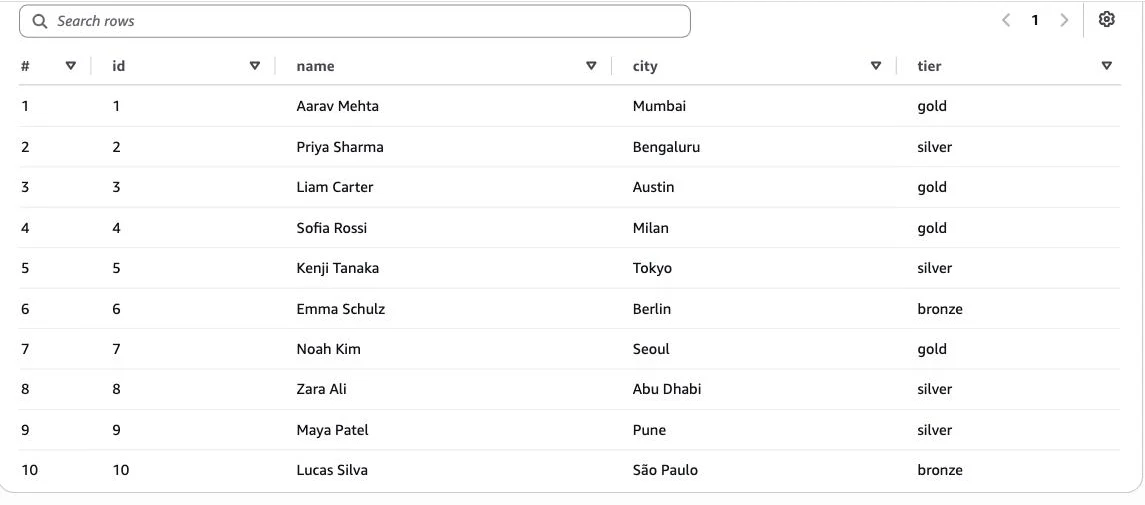
DuckDB reads an Iceberg table from its current metadata file, which Glue holds as the table's metadata_location. Ask Glue for it, then scan: no catalog to configure, and the same S3 keys you gave OLake Go are enough.
aws glue get-table --database-name <glue database> --name customers \
  --query 'Table.Parameters.metadata_location' --output text
INSTALL iceberg; LOAD iceberg;
INSTALL httpfs;  LOAD httpfs;

CREATE SECRET lake (TYPE s3, KEY_ID '<access key>', SECRET '<secret key>', REGION '<region>');

SELECT id, name, city, tier
FROM iceberg_scan('s3://<bucket>/lakehouse/kafka_to_redshift_topics.db/customers/metadata/<latest>.metadata.json')
ORDER BY id;
Each sync writes a new metadata file, so fetch the location again before a fresh read, or wrap the two steps in a script. DuckDB can also attach the Glue Data Catalog as an Iceberg REST catalog (ATTACH '<account id>' AS glue (TYPE iceberg, ENDPOINT_TYPE 'glue')), which needs Lake Formation permissions on the catalog; that path is not covered on this page. DuckDB reads positional deletes, and deletion vectors from duckdb-iceberg 1.5.3.
DuckDB 1.5.5 returned the same 10 customers and the same orders roll-up as Redshift and Athena in the run on this page. It read the current metadata file of each table.
An orders roll-up matched the latest message per key in all three engines. It gave 16 delivered orders for 8659.68, 18 placed for 10522.26, 11 shipped for 6397.25.
Data types: Kafka JSON to Iceberg to Redshift
A Kafka message has no schema of its own, so OLake Go infers one from a sample of messages at discover time and maps it to Iceberg types.
Redshift then maps Iceberg types to its own through the external schema. Four Kafka columns are added to every row. This is what the run on this page produced:
| In the JSON value | Iceberg (written by OLake Go) | Redshift shows | Notes |
|---|---|---|---|
Integer ("id": 3) | long | BIGINT | |
Decimal ("amount": 99.19) | double | DOUBLE PRECISION | The orders.amount sums on this page matched the messages to the cent in every engine; round at query time when you need exact decimal arithmetic. |
ISO 8601 timestamp string ("2026-10-29T15:22:04+00:00") | timestamptz (UTC) | TIMESTAMP | Strings that parse as timestamps are stored as timestamps and shown as UTC instants. |
| Other strings | string | VARCHAR | |
_kafka_key | string | VARCHAR | The message key, base64-encoded (3 arrives as Mw==). |
_kafka_partition, _kafka_offset | int, long | INTEGER, BIGINT | Where the row's latest message sat on the topic. |
_kafka_timestamp | timestamptz | TIMESTAMP | The message timestamp: produce time or broker append time, depending on the topic's message.timestamp.type. |
Types on the left come from the Kafka connector reference. The Redshift side comes from the Redshift Iceberg page (checked 2026-10-30) and from svv_external_columns on the tables of this run. With Normalization on, which is the default, top-level fields become columns.
Cost and maintenance
- Storage is your bucket: you pay S3 rates for the Parquet and delete files, and nothing to Glue beyond its per-object pricing for the table entries.
- Compute. OLake Go runs wherever you run Docker. Redshift Serverless bills RPU-hours only while queries run; a query over the external schema scans the Parquet files in S3 through Redshift Spectrum, so filter on the columns you need. Athena bills per terabyte scanned.
- Maintenance. Glue has no built-in compaction for tables written by external engines. A topic synced every minute adds a small file and a delete file per run, so plan compaction from the writer side; OLake Fusion does this for the catalogs OLake Go writes to, and Spark on EMR's
rewrite_data_filesworks through the same Glue catalog. - Retention disk. Seven days of a busy topic is real disk on the brokers. Size for it, or shorten retention once the job runs reliably every hour.
- Key rotation. The IAM user's access key is what OLake Go writes with. Rotate it on your schedule, or run OLake Go on an instance with a role and leave the key fields empty.
Troubleshooting
1. The source test cannot reach the brokers
failed to ping kafka brokers: unable to dial: dial tcp 192.168.65.254:19999: connect: connection refused
The address in Bootstrap Servers is not reachable from inside the OLake Go container. For a broker on the same machine use host.docker.internal, not localhost.
Make sure the broker also advertises a listener the container can resolve; Kafka's advertised.listeners decides that. On MSK, run OLake Go inside the cluster's VPC or over a VPC connection.
2. The Streams page is empty
Skipping topic customers (does not match topic_pattern: ^nothing_here$)
The topic pattern is a full regular expression anchored by you. ^orders$ matches one topic, ^orders matches every topic that starts with it, and a pattern with a typo matches nothing. Fix the pattern on the source and run discovery again; the sync log names every topic it skipped and why.
3. The destination test fails on a table OLake Go did not create
User: arn:aws:iam::<account>:user/<olake user> is not authorized to perform: s3:GetObject on resource: "arn:aws:s3:::<another bucket>/.../test_olake.db/test_olake/metadata/00000-....metadata.json"
OLake Go's destination test opens a probe table called test_olake.test_olake in the Glue database test_olake. An earlier run in the same account and region may have left that table behind, pointing at a bucket your user cannot read.
The test then fails before it writes anything. Delete the stale table from Glue, or run OLake Go against a region whose Glue catalog does not have it.
4. Redshift cannot see the external schema's tables
ERROR: Database 'kafka_to_redshift_topics' does not exist in the Glue Data Catalog
The external schema was created before the first sync, or in a different region from the Glue database. OLake Go creates the Glue database on the first sync; create the external schema after it, in the workgroup's region.
5. A sync ends early after a consumer-group rebalance
A rebalance in OLake Go's consumer group, usually because another process joined it, makes the sync stop cleanly with what it has read. Nothing is lost: the messages read so far are committed, and the next sync resumes from the committed offsets.
Give each job its own consumer group and never point another consumer at it. If a group's offsets are damaged, create the job again with a new group id. The group name cannot be edited on an existing source in the UI.
How this compares with other ways to move Kafka data to Redshift
| Method | Freshness | Updates and deletes | Where the data lands | What you run |
|---|---|---|---|---|
| Amazon Data Firehose to Redshift from an MSK source | Minutes, by buffer | No; delivers through S3 and COPY | Native Redshift tables; Redshift is the only reader | A Firehose stream, an intermediate S3 bucket and a COPY command |
| Redshift streaming ingestion from MSK | Seconds | No; a materialized view over the stream, merge is yours | Native Redshift materialized view | An external schema on the MSK cluster and a materialized view per topic |
| Kafka Connect with a Redshift or S3 sink | Seconds to minutes | No; appends, or your own merge | Native Redshift tables or S3 files | A Kafka Connect cluster and the sink connector |
| Managed ELT (Fivetran, Estuary, Airbyte Cloud) | Minutes, by plan | Varies by tool | Redshift tables, a second copy you pay to move and store | Nothing; priced per row, per GB or per connector |
| OLake Go to Iceberg on Glue (this guide) | On a schedule down to one minute | Yes, upsert on a key with Iceberg row-level deletes | Apache Iceberg tables that Redshift, Athena, EMR, Spark and DuckDB all read | One Docker Compose stack, open source; your bucket plus your own compute |
Streaming ingestion is the simpler choice when the source is MSK, you need seconds of latency and Redshift is the only reader. Writing Iceberg once, with one row per key, avoids paying to move and store a second copy. That matters as soon as Athena, EMR or a notebook needs the same rows, or you want to own the files.
When not to use this
- You need seconds of latency. OLake Go drains the topic on a schedule, one minute at the shortest. Use Redshift streaming ingestion from MSK for a continuous feed.
- Messages are not JSON or Avro. Protobuf, plain text and binary payloads cannot be mapped to columns.
- Deletes must propagate and the key is in the payload. Tombstones delete a row only when
_kafka_keyis the single deduplication key; on a topic whose dedup key is a payload field, a tombstone fails the sync. Key the messages by the entity id and use the key as the deduplication key, or run the topic in Append mode and filter deletes downstream. - The partition count will change while the job runs in Upsert mode. The same key would then hash to a different partition, and concurrent partition readers could leave a stale row behind. Finish the repartition, then create the job.
FAQs
How do I get Kafka topics into Redshift without Kafka Connect or Firehose?
Run OLake Go (open source, Apache 2.0) with the Kafka cluster as the source and the AWS Glue Data Catalog with an S3 bucket as the Iceberg destination. Each sync reads the topics from the last committed offset, upserts the messages on a deduplication key, and commits Iceberg tables that Redshift reads through an external schema. No Kafka Connect cluster, no Firehose stream and no COPY job sit in the path.
Does OLake Go keep one row per key, or one row per message?
One row per key when the stream runs in Upsert mode with a deduplication key, which is what this page uses: a later message with the same key replaces the earlier row. In Append mode every message becomes a row, with the Kafka partition, offset and timestamp kept in columns, which suits event logs that are never updated.
Where does the first sync start reading a Kafka topic?
A new consumer group has no committed offset, so the first sync reads every message the broker still retains in every partition of every selected topic. The run on this page read all 48 messages on its first sync. Each later sync resumes from the offsets OLake Go committed in its consumer group, so retention is the replay window.
Does Redshift read Iceberg tables with row-level deletes?
Yes. Redshift reads Iceberg v2 tables with positional deletes through Redshift Spectrum, on Serverless and RA3. The run on this page used positional deletes, which is also the only upsert type OLake Go offers for Kafka, and Redshift returned one row per key after the repeated messages.
Is Redshift one of OLake Go's target query engines?
Not in the picker yet. On this page the job lists Athena and DuckDB as target engines; Kafka streams always use Positional Deletes, which is the format Redshift reads. Redshift then reads the tables through the external schema like any other Iceberg v2 table.
Which message formats does OLake Go read from Kafka?
JSON values, and Avro values when a schema registry is configured on the source. Field types are inferred from a sample of messages at discover time: integers become BIGINT in Redshift, decimals DOUBLE PRECISION, ISO 8601 timestamp strings TIMESTAMP and other strings VARCHAR. Protobuf and plain-text messages are not supported.
Does this work with Amazon MSK?
Yes. OLake Go speaks the Kafka protocol with PLAINTEXT, SASL_PLAINTEXT or SASL_SSL and the PLAIN or SCRAM-SHA-512 mechanisms, which covers Amazon Managed Streaming for Apache Kafka (MSK), Confluent Cloud and self-hosted clusters. The connector was tested most on MSK; the run on this page used Apache Kafka 4.3.1 in KRaft mode.
Related guides
Deeper reading on this site: