MongoDB to Apache Iceberg: CDC without Kafka
MongoDB to Apache Iceberg usually means Debezium's MongoDB connector, Kafka and a sink connector, before a single row reaches the lake. This guide replicates MongoDB to Iceberg without Kafka. OLake Go opens a MongoDB change stream itself and commits the changes as Iceberg tables into an Apache Polaris catalog, with the files in your own bucket.
Polaris is an open source Iceberg REST (Representational State Transfer) catalog you run yourself. Apache Spark, DuckDB and Trino read the tables through that one endpoint, and in the run on this page all three returned the same rows.
Key takeaways
- OLake Go replicates MongoDB collections into Iceberg tables in Polaris: a full historical snapshot first, then change data capture (CDC) from a change stream, with no Kafka, Debezium or Kafka Connect in between.
- Documents land as flat tables: top-level fields become columns, and every sync is one Iceberg commit with Parquet data files and positional delete files.
- The same tables are open to any engine that reads an Iceberg REST catalog. Spark, DuckDB and Trino returned identical rows and totals in the run on this page.
The short answer. To replicate MongoDB to Apache Iceberg without Kafka, run OLake Go with a MongoDB replica set as the source and an Iceberg REST catalog such as Apache Polaris as the destination. The first sync copies each collection in full; every later sync replays inserts, updates and deletes from a change stream. Spark, DuckDB and Trino then query the same tables.
How MongoDB CDC reaches Apache Iceberg here
Two things happen in order, and OLake Go does both on its own. The first sync opens a change stream and saves its resume token, then reads each collection in parallel chunks and writes Parquet data files. Every later sync resumes the stream from the saved token and replays the inserts, updates and deletes since.
An update needs the old version of the document retired. With positional deletes, OLake Go keeps an index of where each _id sits (data file and row number) and writes a small delete file that points at those positions. Readers skip the retired rows without comparing keys, which is why every current Spark, DuckDB and Trino release reads this format.
One thing to keep an eye on: the oplog is MongoDB's replay window. A change stream can only resume from a token that is still in the oplog, so a job paused for longer than the oplog window needs a fresh snapshot. Size the oplog for your longest planned pause; the source test reports the current window.
What you need
- MongoDB 4.0 or later running as a replica set, self-hosted or on Atlas, with a user that can read the database and the oplog. The collections on this page ran on MongoDB 7 as a single-node replica set; step 1 covers Atlas too.
- An Apache Polaris server and a bucket, both reachable from OLake Go and from your query engines. The run on this page used Polaris 1.8.0 and MinIO in Docker; on AWS, use an S3 bucket and an IAM role instead.
- At least one engine that reads an Iceberg REST catalog. This page shows Apache Spark 3.5.6 with Iceberg 1.10.0, DuckDB 1.5.5 and Trino 484.
- OLake UI from the Docker Compose install. The run on this page used OLake Go v1.1.0.
- Docker, and about 40 minutes.
Step 1: Prepare MongoDB for CDC
Most readers point OLake Go at collections they already have. If you want to follow along with the exact data from this page, create these two collections first:
The two sample collections used on this page
const now = new Date();
db.customers.insertMany([
  { _id: 1, name: 'Aarav Mehta', email: 'aarav@example.com', city: 'Mumbai', tier: 'gold', created_at: now, updated_at: now },
  // ... 8 customers with integer _id values
]);
db.orders.insertMany([
  { _id: 1, customer_id: 2, product: 'Headphones', amount: NumberDecimal('99.19'), status: 'shipped', created_at: now, updated_at: now },
  // ... 40 orders
]);
// Then insert whatever you like. This page started with 8 customers and 40 orders.
OLake Go reads MongoDB changes through change streams, which MongoDB builds on the replica set oplog. Three things must be in place before the first sync.
| Setting | Value | Why it matters |
|---|---|---|
| Replica set | any name, even a single node | Change streams and the oplog exist only in replica set mode. Atlas clusters are already replica sets. |
| Oplog retention | long enough to cover your longest pause | OLake Go resumes from a change-stream token saved after each sync; if the oplog has rolled past it, the next sync needs a fresh snapshot. |
| A user for OLake Go | read on the database plus clusterMonitor | The snapshot reads the collections; the change stream needs oplog access, which clusterMonitor (or readAnyDatabase) grants. |
// 1. A single-node replica set, if you do not have one (self-hosted only)
//    start mongod with --replSet rs0, then:
rs.initiate({ _id: "rs0", members: [{ _id: 0, host: "<host>:27017" }] })

// 2. A user for OLake Go
use admin
db.createUser({
  user: "olake", pwd: "<password>",
  roles: [{ role: "read", db: "shop" }, { role: "clusterMonitor", db: "admin" }]
})

// 3. Check the oplog window; OLake Go warns below 7 days
use local
db.oplog.rs.stats().maxSize      // bytes; raise with replSetResizeOplog if it is small
Check the result before moving on:
rs.status().members.map(m => m.stateStr)      // one PRIMARY
db.getSiblingDB("admin").getUsers().users.map(u => u.user)
On MongoDB Atlas the replica set and oplog are already there; create the user under Database Access with the read role on your database and clusterMonitor, and allow OLake Go's IP in Network Access. The full guide, including Atlas screenshots, is MongoDB and Atlas CDC setup.
Atlas and most self-hosted installs keep 24 hours or less of oplog by default. OLake Go's source test shows the current window and warns below 7 days. Size it for your longest planned pause, or run the job often enough that the token never falls out of the window.
Step 2: Set up the Polaris catalog
An Iceberg table is a set of files plus a catalog entry that says which metadata file is current. Apache Polaris holds those entries and the permissions; the Parquet files sit in your own S3 or MinIO bucket. OLake Go writes through Polaris, and every engine on this page reads through it with the credentials Polaris hands out.
The Polaris catalog page lists the other engines that read it. If you already run AWS Glue, Lakekeeper or another catalog, the Apache Iceberg overview shows what changes.
| Catalog | OLake Go writes | Apache Iceberg reads | Verified on this page |
|---|---|---|---|
| Apache Polaris | Yes | Yes: any Iceberg REST client with OAuth2 | Yes, end to end |
- Apache Polaris
Apache Polaris is an open source Iceberg REST catalog. It keeps the table metadata pointers, hands out short-lived storage credentials to engines, and applies its own role-based access control. OLake Go writes to it through the standard Iceberg REST API, and ClickHouse, Trino, DuckDB and Spark read from the same endpoint. The files live in an S3 bucket or an S3-compatible store that you own.
Three things need to exist before OLake Go can write: a Polaris server, a catalog inside it that points at your bucket, and a principal (a client id and secret) with the right to manage that catalog. The run on this page used Polaris 1.8.0 and MinIO in Docker; on AWS, swap the MinIO endpoint for a plain S3 bucket and an IAM role.
services:
  minio:
    image: minio/minio
    hostname: lake-minio
    command: server /data --console-address ":9001"
    environment: { MINIO_ROOT_USER: minioadmin, MINIO_ROOT_PASSWORD: minioadmin }
    ports: ["9000:9000", "9001:9001"]
  polaris:
    image: apache/polaris:latest
    depends_on: [minio]
    ports: ["8181:8181", "8182:8182"]
    environment:
      AWS_REGION: us-east-1
      AWS_ACCESS_KEY_ID: minioadmin
      AWS_SECRET_ACCESS_KEY: minioadmin
      POLARIS_BOOTSTRAP_CREDENTIALS: POLARIS,root,<root-secret>
      polaris.realm-context.realms: POLARIS
Polaris stores its own state in memory with this setup, so it starts empty every time; a production deployment points it at Postgres. Once it is up, create the bucket, the catalog and the principal through the management API. root is the bootstrap principal; the olake principal is the one OLake Go and the engines use.
P=http://localhost:8181

# 1. A bucket for the tables (MinIO; on AWS create it in the console or with aws s3 mb)
aws --endpoint-url http://localhost:9000 s3 mb s3://lakehouse

# 2. A root token
TOKEN=$(curl -s $P/api/catalog/v1/oauth/tokens -H 'Polaris-Realm: POLARIS' \
  -d grant_type=client_credentials -d client_id=root -d client_secret=<root-secret> \
  -d scope=PRINCIPAL_ROLE:ALL | jq -r .access_token)
H=(-H "Authorization: Bearer $TOKEN" -H 'Polaris-Realm: POLARIS' -H 'Content-Type: application/json')

# 3. The catalog: where the files go, and how Polaris and the engines reach the store
curl -s "${H[@]}" $P/api/management/v1/catalogs -d '{"catalog": {
  "name": "olake", "type": "INTERNAL", "readOnly": false,
  "properties": {"default-base-location": "s3://lakehouse/olake"},
  "storageConfigInfo": {"storageType": "S3", "allowedLocations": ["s3://lakehouse/olake"],
    "endpoint": "http://<minio-host>:9000/", "endpointInternal": "http://lake-minio:9000",
    "pathStyleAccess": true, "region": "us-east-1"}}}'

# 4. A principal for OLake Go and the engines. The response holds clientId and clientSecret: keep them.
curl -s "${H[@]}" $P/api/management/v1/principals -d '{"principal": {"name": "olake"}}'

# 5. Roles and the grant that lets the principal create namespaces and tables in the catalog
curl -s "${H[@]}" $P/api/management/v1/principal-roles -d '{"principalRole": {"name": "olake_role"}}'
curl -s "${H[@]}" $P/api/management/v1/catalogs/olake/catalog-roles -d '{"catalogRole": {"name": "olake_catalog_role"}}'
curl -s -X PUT "${H[@]}" $P/api/management/v1/principals/olake/principal-roles -d '{"principalRole": {"name": "olake_role"}}'
curl -s -X PUT "${H[@]}" $P/api/management/v1/principal-roles/olake_role/catalog-roles/olake -d '{"catalogRole": {"name": "olake_catalog_role"}}'
curl -s -X PUT "${H[@]}" $P/api/management/v1/catalogs/olake/catalog-roles/olake_catalog_role/grants -d '{"type": "catalog", "privilege": "CATALOG_MANAGE_CONTENT"}'
What each block is for:
endpointis the store address Polaris hands to engines along with vended credentials;endpointInternalis the address Polaris itself uses. On AWS S3 leave both out. On MinIO both are required, or Polaris tries to reach AWS and fails. Keep the trailing slash onendpoint: ClickHouse 26.8 and 26.10 build the object path from it, and without the slash every read fails with a 404 (the fix is explained under troubleshooting on this page).- Polaris vends credentials through the store's STS endpoint. MinIO exposes one, so nothing else is needed. For a store without STS, add
"stsUnavailable": trueand give Polaris static keys to hand out. CATALOG_MANAGE_CONTENTlets the principal create namespaces and tables and read and write their data. Scope it to a namespace instead when several teams share the catalog.- The principal's secret is shown once, in the response to step 4. It is what goes into OLake Go as
<client_id>:<client_secret>.
Polaris is a Java service, and Java's URI parser rejects hostnames that contain an underscore. A MinIO container named lab_minio makes every table creation fail with host must not be null or Expected scheme-specific part at index 5: http:. Use a hyphen in the hostname (lake-minio), as above.
You can check the principal outside OLake Go by exchanging its credentials for a token, the same call OLake Go makes on every sync:
curl -s http://localhost:8181/api/catalog/v1/oauth/tokens -H 'Polaris-Realm: POLARIS' \
  -d grant_type=client_credentials -d client_id=<client_id> -d client_secret=<client_secret> \
  -d scope=PRINCIPAL_ROLE:ALL
A good principal returns a JSON object with an access_token. Running Polaris on Kubernetes, with Postgres behind it, or with an external identity provider is covered on the Polaris catalog page.
Step 3: Connect MongoDB to OLake Go
- OLake UI
- OLake CLI
- In the OLake UI, open Sources and click Create Source. Pick MongoDB as the connector, give the source a name and keep the OLake Go version on the latest release.
- Under Change data capture (CDC), leave Enable CDC on.
- Under Connection details, add each host as
host:port(or one SRV host with Use SRV on for Atlas), then the Database Name, Auth DB (admin), username, password and the Replica Set name. Leave Read Preference onprimaryunless you have secondaries to spare. - Click Set up source. OLake Go tests the connection, confirms that it can open a change stream, and reports the oplog window with a warning below 7 days.
Here is the source form from the run on this page. MongoDB ran in another container as a single-node replica set, so the host is host.docker.internal; the user is the one from step 1.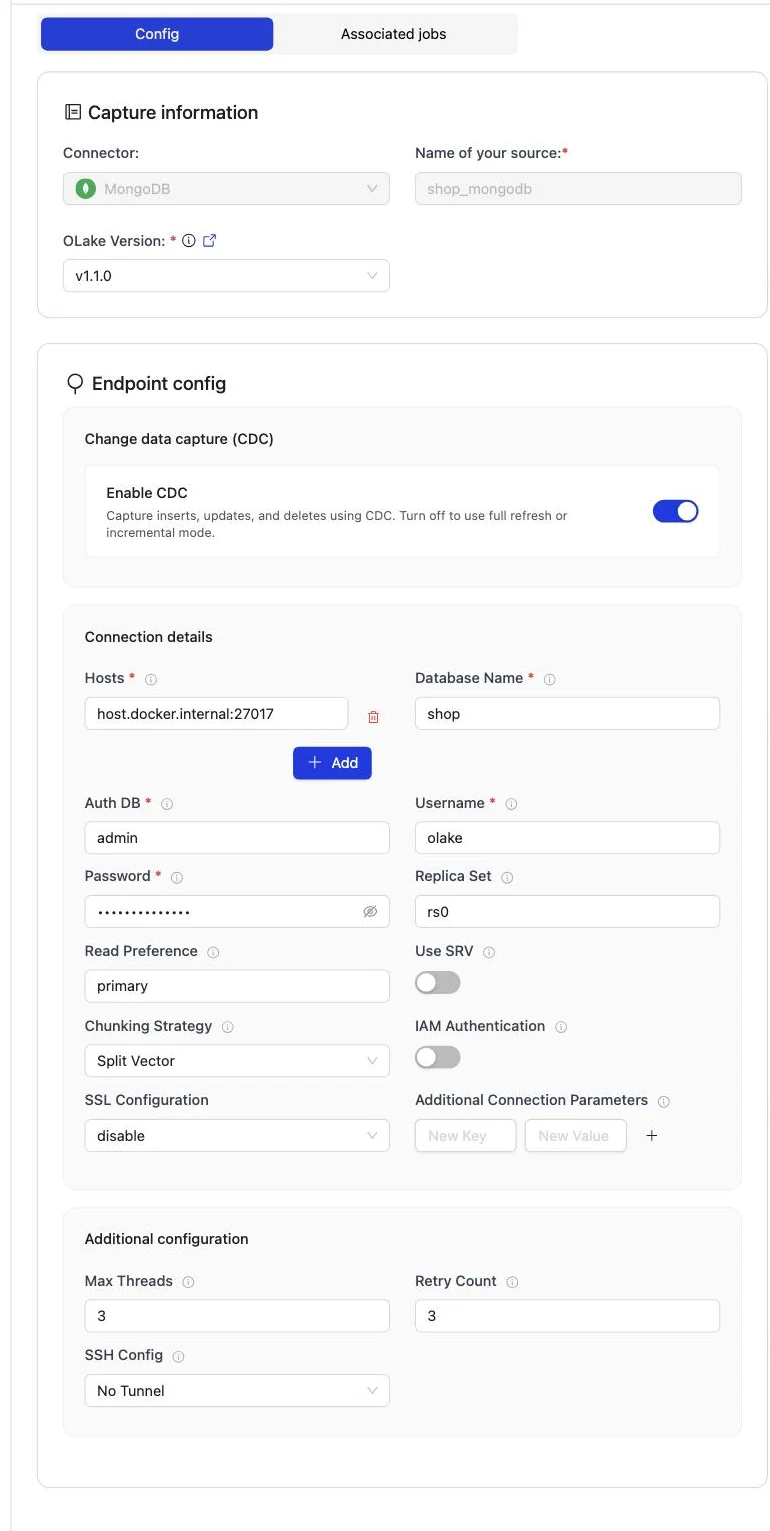
Set up source runs the connection test, then checks that the server is a replica set, that a change stream can be opened and how long the oplog window is. When one fails, the dialog names the setting and its recommended value.
The full field reference, including SRV strings, IAM authentication and SSH tunnels, is on the MongoDB connector page.
Create source.json in your config folder. replica_set is what lets OLake Go open the change stream:
{
  "hosts": [
    "host1:27017",
    "host2:27017",
    "host3:27017"
  ],
  "username": "username",
  "password": "password",
  "authdb": "admin",
  "replica_set": "rs0",
  "read_preference": "secondaryPreferred",
  "srv": false,
  "database": "database",
  "max_threads": 5,
  "backoff_retry_count": 4,
  "chunking_strategy":""
}
Then confirm OLake Go can reach the database:
docker run --pull=always \
  -v "$PWD/config:/mnt/config" \
  olakego/source-mongodb:latest \
  check --config /mnt/config/source.json
A working setup returns "status": "SUCCEEDED" with a prerequisites list that reports change_streams as passed and the oplog_retention window. Every field is described on the MongoDB connector page.
Step 4: Configure the Iceberg destination
- Apache Polaris
- OLake UI
- OLake CLI
- Open Destinations and click Create Destination.
- Pick Apache Iceberg as the connector and Polaris as the catalog type.
- Choose OAuth2 as the authentication type. REST Catalog URI is the Polaris catalog endpoint (
http://<polaris-host>:8181/api/catalog), Polaris Catalog Name the catalog from the setup (olake), REST Auth URI the token endpoint, and REST Credential the principal's<client_id>:<client_secret>. - Fill in the store: AWS Region, and for MinIO the S3 Endpoint with the AWS Access Key and AWS Secret Key. On AWS S3 leave the endpoint empty.
- Click Create. OLake Go exchanges the credentials for a token, creates a namespace and a test table through Polaris, writes to the bucket and drops the test table again.
Here is the destination form from the run on this page. Polaris and MinIO ran in other containers, so both addresses use host.docker.internal; the credential is the olake principal from step 2.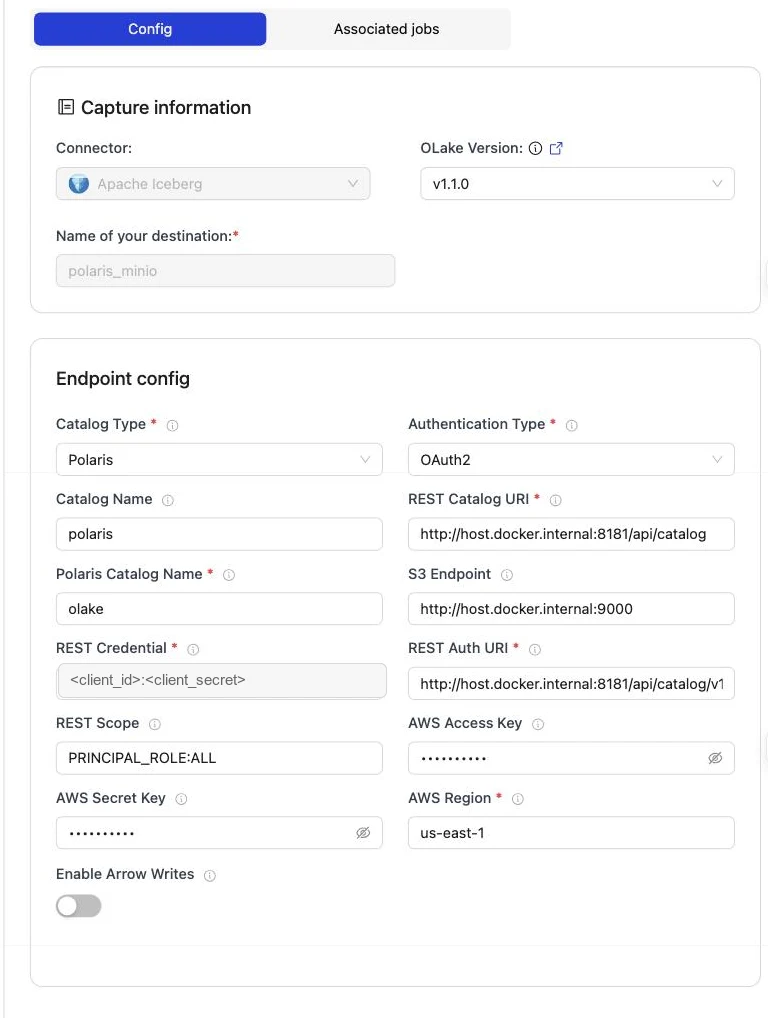
Polaris Configuration Parameters
| Parameter | Sample Value | Description |
|---|---|---|
REST Catalog URIrequired | http://<REST_ENDPOINT>:8181/api/catalog | Endpoint URL for the Polaris REST catalog service. |
Authentication Typerequired | oauth2 | Authentication method OLake Go uses for Polaris REST catalog requests. Set to match your catalog's authentication configuration. |
Polaris Catalog Namerequired | <POLARIS_CATALOG_NAME> | Name of the Polaris catalog to use, OLake Go passes this to the Polaris REST catalog as the warehouse identifier, so catalog operations are routed to that catalog and its pre-configured S3 storage and IAM settings. |
REST Auth URIrequired | http://<REST_ENDPOINT>:8181/api/catalog/v1/oauth/tokens | URL of the REST catalog’s OAuth2 token endpoint. OLake Go uses this with REST Credential to request an access token during OAuth2 client-credentials authentication. |
REST Credentialrequired | <olake_user_client_id>:<olake_user_client_secret> | Specifies the client ID and secret for OAuth2, formatted as client_id:client_secret. Used with REST Auth URI when OLake Go requests an access token from the catalog’s auth service. Not needed when using REST Token or other auth types. |
AWS Regionrequired | ap-south-1 | AWS Region where your S3 bucket exists. Required so OLake Go calls the correct regional S3 endpoint. |
| REST Scope | PRINCIPAL_ROLE:ALL | Required for OAuth2 client-credentials auth. Scopes are space-separated. Used with REST Auth URI and REST Credential for OAuth2 client-credentials auth. Values are catalog-specific. Not needed when using REST Token or other auth types. |
| S3 Endpoint | http://<S3_ENDPOINT>:9000 | S3 API endpoint for writing Iceberg data files. Leave empty for AWS S3 but required for S3-compatible storage like MinIO. |
| AWS Access Key | XXX | AWS access key ID for authentication. Optional if using IAM roles or instance profiles. If using IAM: Docker Compose: add the required IAM environment variables under x-envs in your compose file. See Service Environment Variables for setup details.Kubernetes: set up pod IAM in Cloud Integration. |
| AWS Secret Key | XXX | AWS secret access key for authentication. Optional if using IAM roles or instance profiles. If using IAM: Docker Compose: add the required IAM environment variables under x-envs in your compose file. See Service Environment Variables for setup details.Kubernetes: set up pod IAM in Cloud Integration. |
| Enable Arrow Writes | false | Writes data and delete files using Apache Arrow based writer and registers them in Iceberg. |
| Catalog Name | olake_iceberg | Name of the Iceberg catalog OLake Go registers tables under. Defaults to olake_iceberg if left empty. |
Create destination.json next to source.json:
{
  "type": "ICEBERG",
  "writer": {
    "catalog_type": "polaris",
    "catalog_name": "polaris",
    "rest_catalog_url": "http://<polaris-host>:8181/api/catalog",
    "iceberg_s3_path": "olake",
    "rest_auth_type": "oauth2",
    "oauth2_uri": "http://<polaris-host>:8181/api/catalog/v1/oauth/tokens",
    "credential": "<client_id>:<client_secret>",
    "scope": "PRINCIPAL_ROLE:ALL",
    "aws_region": "us-east-1",
    "s3_endpoint": "http://<minio-host>:9000",
    "aws_access_key": "<minio access key>",
    "aws_secret_key": "<minio secret key>",
    "arrow_writes": false
  }
}
Polaris Configuration Parameters
| Parameter | Sample Value | Description |
|---|---|---|
catalog_typerequired | polaris | Defines the catalog type used by the writer. |
rest_catalog_urlrequired | http://<REST_ENDPOINT>:8181/api/catalog | Endpoint URL for the Polaris REST catalog service. |
iceberg_s3_pathrequired | <POLARIS_CATALOG_NAME> | Name of the Polaris catalog to use, OLake Go passes this to the Polaris REST catalog as the warehouse identifier, so catalog operations are routed to that catalog and its pre-configured S3 storage and IAM settings. |
rest_auth_typerequired | oauth2 | Authentication method OLake Go uses for Polaris REST catalog requests. Set to match your catalog's authentication configuration. |
oauth2_urirequired | http://<REST_ENDPOINT>:8181/api/catalog/v1/oauth/tokens | URL of the REST catalog’s OAuth2 token endpoint. OLake Go uses this with REST Credential to request an access token during OAuth2 client-credentials authentication. |
credentialrequired | <olake_user_client_id>:<olake_user_client_secret> | Specifies the client ID and secret for OAuth2, formatted as client_id:client_secret. Used with REST Auth URI when OLake Go requests an access token from the catalog’s auth service. |
aws_regionrequired | ap-south-1 | AWS Region where your S3 bucket exists. Required so OLake Go calls the correct regional S3 endpoint. |
| scope | PRINCIPAL_ROLE:ALL | Required for OAuth2 client-credentials auth. Scopes are space-separated. Used with REST Auth URI and REST Credential for OAuth2 client-credentials auth. Values are catalog-specific. |
| s3_endpoint | http://<S3_ENDPOINT>:9000 | S3 API endpoint for writing Iceberg data files. Leave empty for AWS S3 but required for S3-compatible storage like MinIO. |
| aws_access_key | XXX | AWS access key ID for authentication. Optional if using IAM roles or instance profiles. If using IAM: Docker Compose: add the required IAM environment variables under x-envs in your compose file. See Service Environment Variables for setup details.Kubernetes: set up pod IAM in Cloud Integration. |
| aws_secret_key | XXX | AWS secret access key for authentication. Optional if using IAM roles or instance profiles. If using IAM: Docker Compose: add the required IAM environment variables under x-envs in your compose file. See Service Environment Variables for setup details.Kubernetes: set up pod IAM in Cloud Integration. |
| arrow_writes | false | Writes data and delete files using Apache Arrow based writer and registers them in Iceberg. |
| catalog_name | olake_iceberg | Name of the Iceberg catalog OLake Go registers tables under. Defaults to olake_iceberg if left empty. |
Step 5: Create the job and run the first sync
- OLake UI
- OLake CLI
- Open Jobs and click Create Job. Give it a name and a schedule. Every Day at a fixed hour, or a cron expression, both work; the schedule is how often the change stream is drained, not how often a full copy runs.
- Select the source and the destination you created.
- Under Advanced Settings, set Target Query Engines to Apache Spark, DuckDB and Trino, or whichever engines will read the tables. OLake Go then resolves an Iceberg delete format every one of those engines can read, so you never pick one by hand.
- Click Next. OLake Go discovers the collections and opens the Streams page.
- Tick the collections to replicate. For each one, set the sync mode to Full Refresh + CDC and the ingestion mode to Upsert. Leave the Upsert Type as OLake Go resolved it (Positional Deletes in the run on this page).
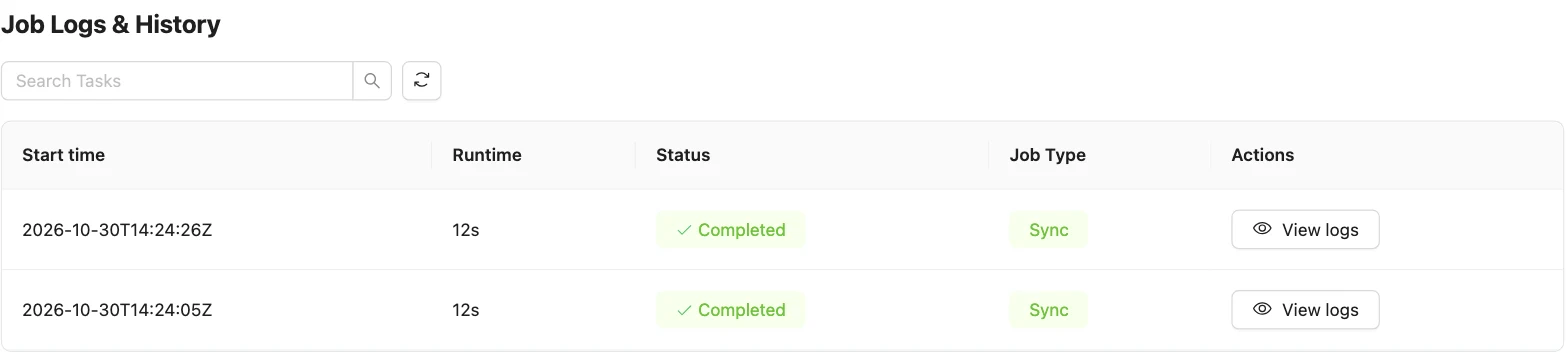
- Click Create Job, then open the job's menu and choose Sync Now for the first run.
Three target query engines were set on this job: Apache Spark, DuckDB and Trino. All three read every Iceberg delete format, and the run on this page used positional deletes on Iceberg format version 2 for every collection.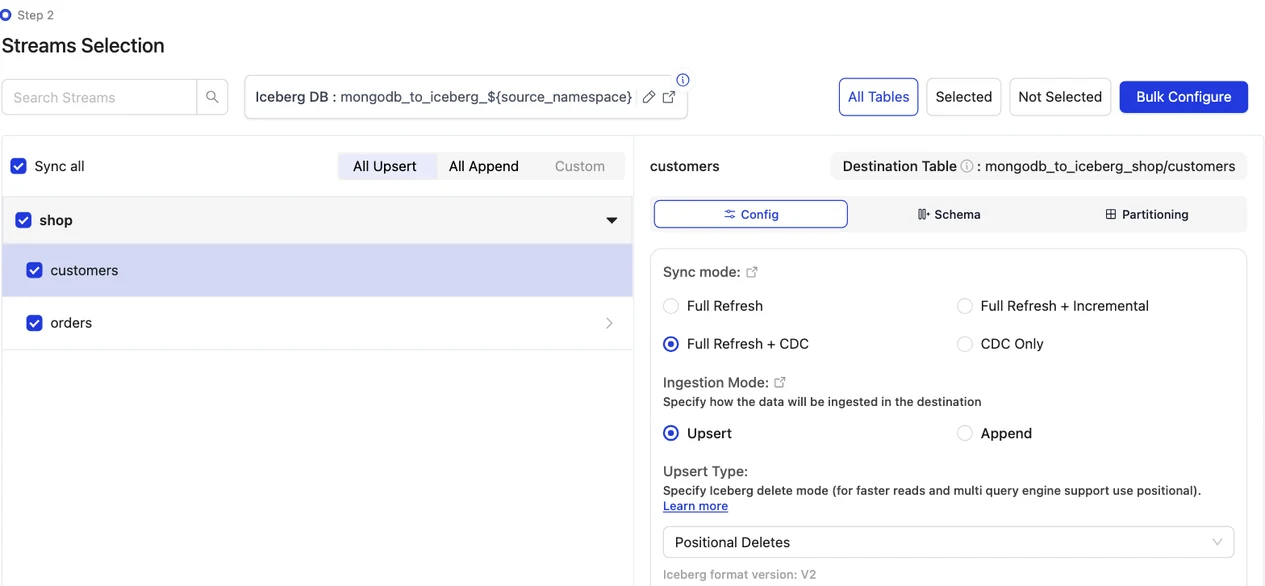
Discover the collections, choose the streams, then sync:
docker run --pull=always \
-v "$PWD/config:/mnt/config" \
olakego/source-mongodb:latest \
discover --config /mnt/config/source.json
discover writes two files: available_streams.json (every collection it found, do not edit) and selected_streams.json (the collections you want and their settings). In selected_streams.json, set sync_mode to {props.cliSyncMode ?? 'cdc'} for each collection and pick the delete format your readers can open:
{
"selected_streams": {
  "shop": [
    {
      "stream_name": "customers",
      "sync_mode": "cdc",
      "normalization": true,
      "append_mode": false,
      "update_type": "pos"
    }
  ]
}
}
update_type accepts eq (equality deletes, the default), pos (positional deletes) and dv (deletion vectors). Positional deletes and deletion vectors keep a small index between runs, so give the container a persistent directory for it through OLAKE_INDEX_DB_DIR. The first sync runs without a state file; OLake Go writes one at the end of the run:
docker run --pull=always \
-v "$PWD/config:/mnt/config" \
-e OLAKE_INDEX_DB_DIR=/mnt/config/index-db \
olakego/source-mongodb:latest \
sync \
--config /mnt/config/source.json \
--selected-streams /mnt/config/selected_streams.json \
--available-streams /mnt/config/available_streams.json \
--destination /mnt/config/destination.json
Every later run adds --state /mnt/config/state.json to the same command, which is how OLake Go knows to replay only the changes since the last run. The full selected_streams.json reference is on the Docker CLI page; the index directory is described under index DB setup.
On this page the first run copied 8 customers and 40 orders (48 documents, 6.40 KB) and finished in 12 seconds, container start included. OLake Go names the destination namespace after the job and the source database, so mongodb_to_iceberg on database shop produced mongodb_to_iceberg_shop. The Iceberg DB field at the top of the Streams page changes it before the first sync.
Step 6: Query the tables from DuckDB
DuckDB is the quickest way to check the result from a laptop: one ATTACH and the whole catalog is visible.
- Apache Polaris
DuckDB attaches Polaris as an Iceberg REST catalog with the principal's client id and secret; DuckDB fetches the token itself. On a laptop, where the store address Polaris hands out may not resolve, add an S3 secret for the store and turn credential vending off:
INSTALL iceberg; LOAD iceberg;
INSTALL httpfs;  LOAD httpfs;

CREATE SECRET polaris_secret (
TYPE iceberg,
CLIENT_ID '<client_id>', CLIENT_SECRET '<client_secret>',
OAUTH2_SERVER_URI 'http://<polaris-host>:8181/api/catalog/v1/oauth/tokens',
OAUTH2_SCOPE 'PRINCIPAL_ROLE:ALL'
);
-- MinIO, or any store whose address differs from the one Polaris vends
CREATE SECRET store_secret (
TYPE s3, KEY_ID '<access key>', SECRET '<secret key>',
ENDPOINT '<minio-host>:9000', URL_STYLE 'path', USE_SSL false, REGION 'us-east-1'
);

ATTACH 'olake' AS polaris (
TYPE iceberg,
ENDPOINT 'http://<polaris-host>:8181/api/catalog',
SECRET polaris_secret,
ACCESS_DELEGATION_MODE 'none'
);

SHOW ALL TABLES;
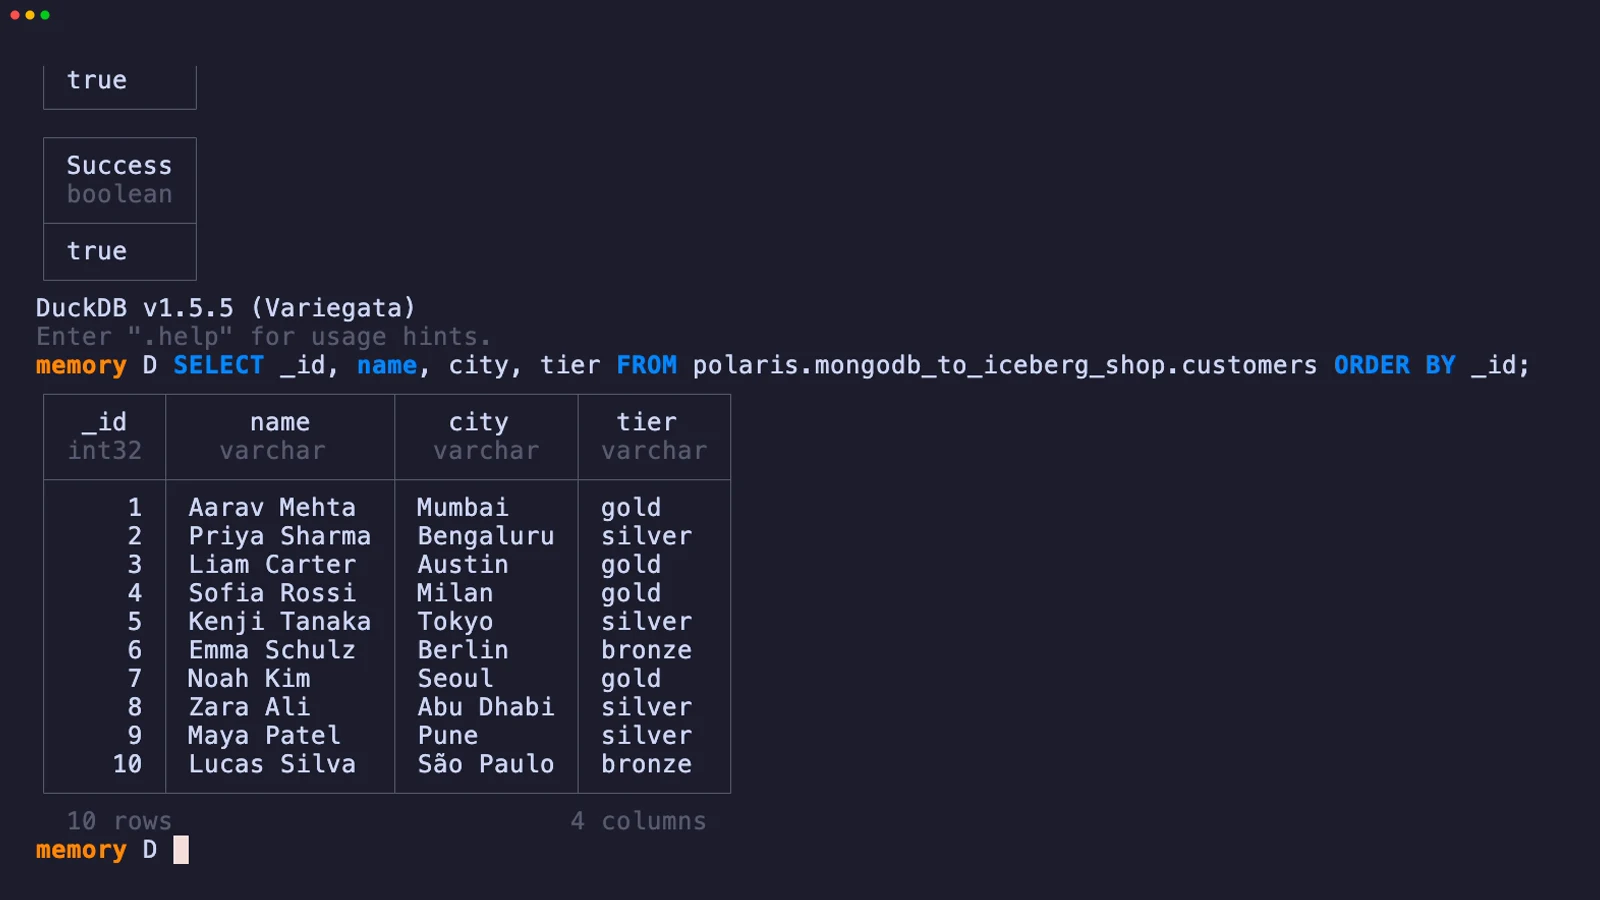
SELECT _id, name, city, tier FROM polaris.mongodb_to_iceberg_shop.customers ORDER BY _id;
With Polaris on AWS S3, drop the S3 secret and the ACCESS_DELEGATION_MODE line: DuckDB then reads with the credentials Polaris vends. DuckDB reads equality and positional deletes, and deletion vectors from duckdb-iceberg 1.5.3 onward.
A Decimal128 field such as amount arrives as a string, so cast it before you sum:
SELECT status, count(*) AS n, round(sum(CAST(amount AS DOUBLE)), 2) AS total
FROM polaris.mongodb_to_iceberg_shop.orders
GROUP BY status ORDER BY status;
Step 7: Change documents in MongoDB and sync again
To see the change path work, the run on this page made 12 changes in MongoDB after the first sync:
const now = new Date();
db.customers.insertMany([
  { _id: 9,  name: 'Maya Patel',  email: 'maya@example.com',  city: 'Pune',      tier: 'silver', created_at: now, updated_at: now },
  { _id: 10, name: 'Lucas Silva', email: 'lucas@example.com', city: 'São Paulo', tier: 'bronze', created_at: now, updated_at: now }
]);
db.orders.insertMany([
  { _id: 41, customer_id: 9,  product: 'Laptop',   amount: NumberDecimal('1299.00'), status: 'placed', created_at: now, updated_at: now },
  { _id: 42, customer_id: 9,  product: 'Mouse',    amount: NumberDecimal('25.50'),   status: 'placed', created_at: now, updated_at: now },
  { _id: 43, customer_id: 10, product: 'Monitor',  amount: NumberDecimal('349.99'),  status: 'placed', created_at: now, updated_at: now },
  { _id: 44, customer_id: 3,  product: 'Keyboard', amount: NumberDecimal('89.00'),   status: 'placed', created_at: now, updated_at: now },
  { _id: 45, customer_id: 7,  product: 'Webcam',   amount: NumberDecimal('79.90'),   status: 'placed', created_at: now, updated_at: now }
]);
db.customers.updateOne({ name: 'Liam Carter' }, { $set: { tier: 'gold', updated_at: now } });
db.customers.updateOne({ name: 'Zara Ali' },    { $set: { city: 'Abu Dhabi', updated_at: now } });
db.orders.updateMany({ _id: { $in: [1, 4, 7] } }, { $set: { status: 'delivered', updated_at: now } });
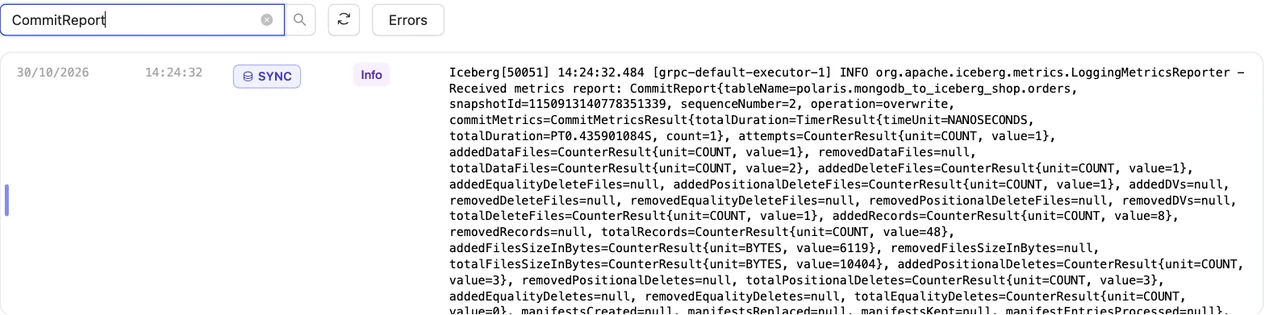
The second sync read 12 change events (1.60 KB) from the stream and finished in 12 seconds end to end. For orders that meant one new data file with 8 rows: 5 inserts plus the new versions of 3 updated documents. One positional delete file retires the 3 old versions by file and row number.
OLake Go's commit report in the sync log shows it directly: addedDataFiles=1, addedRecords=8, addedPositionalDeleteFiles=1, addedPositionalDeletes=3, and no equality delete files. The customers table has the same shape with 4 rows and 2 deletes.
Every engine shows the result on its next query, with no refresh. Liam Carter is gold, Zara Ali moved to Abu Dhabi, and the two new customers are there. The _op_type column shows how each row arrived: r for the snapshot, c for the inserts and u for the updates.
Schema changes. When a new field appears in the documents, OLake Go adds it as a column on the next sync, with nulls for older rows. A field whose type changes in an incompatible way fails the sync rather than corrupt the table. Full rules are on the schema evolution page.
Query the same tables from Trino and Spark
Nothing is exported or copied for a second engine. Trino and Spark read the files OLake Go wrote, through the same Polaris endpoint. As in DuckDB, the key column is _id.
- Trino
- Apache Spark
Trino reaches Polaris through its Iceberg connector in REST mode. One catalog properties file does it; Trino fetches the OAuth2 token with the principal's credentials and reads the files with the credentials Polaris vends.
connector.name=iceberg
iceberg.catalog.type=rest
iceberg.rest-catalog.uri=http://<polaris-host>:8181/api/catalog
iceberg.rest-catalog.warehouse=olake
iceberg.rest-catalog.security=OAUTH2
iceberg.rest-catalog.oauth2.credential=<client_id>:<client_secret>
iceberg.rest-catalog.oauth2.scope=PRINCIPAL_ROLE:ALL
iceberg.rest-catalog.oauth2.server-uri=http://<polaris-host>:8181/api/catalog/v1/oauth/tokens
iceberg.rest-catalog.vended-credentials-enabled=true
fs.native-s3.enabled=true
s3.region=us-east-1
# MinIO or another S3-compatible store only:
s3.endpoint=http://<minio-host>:9000
s3.path-style-access=true
SHOW SCHEMAS FROM polaris;
SELECT _id, name, city, tier FROM polaris.mongodb_to_iceberg_shop.customers ORDER BY _id;
Trino 484 read the tables on this page with no further settings. Equality and positional deletes are read on every current release; deletion vectors from Trino 480, where the docs still mark them experimental.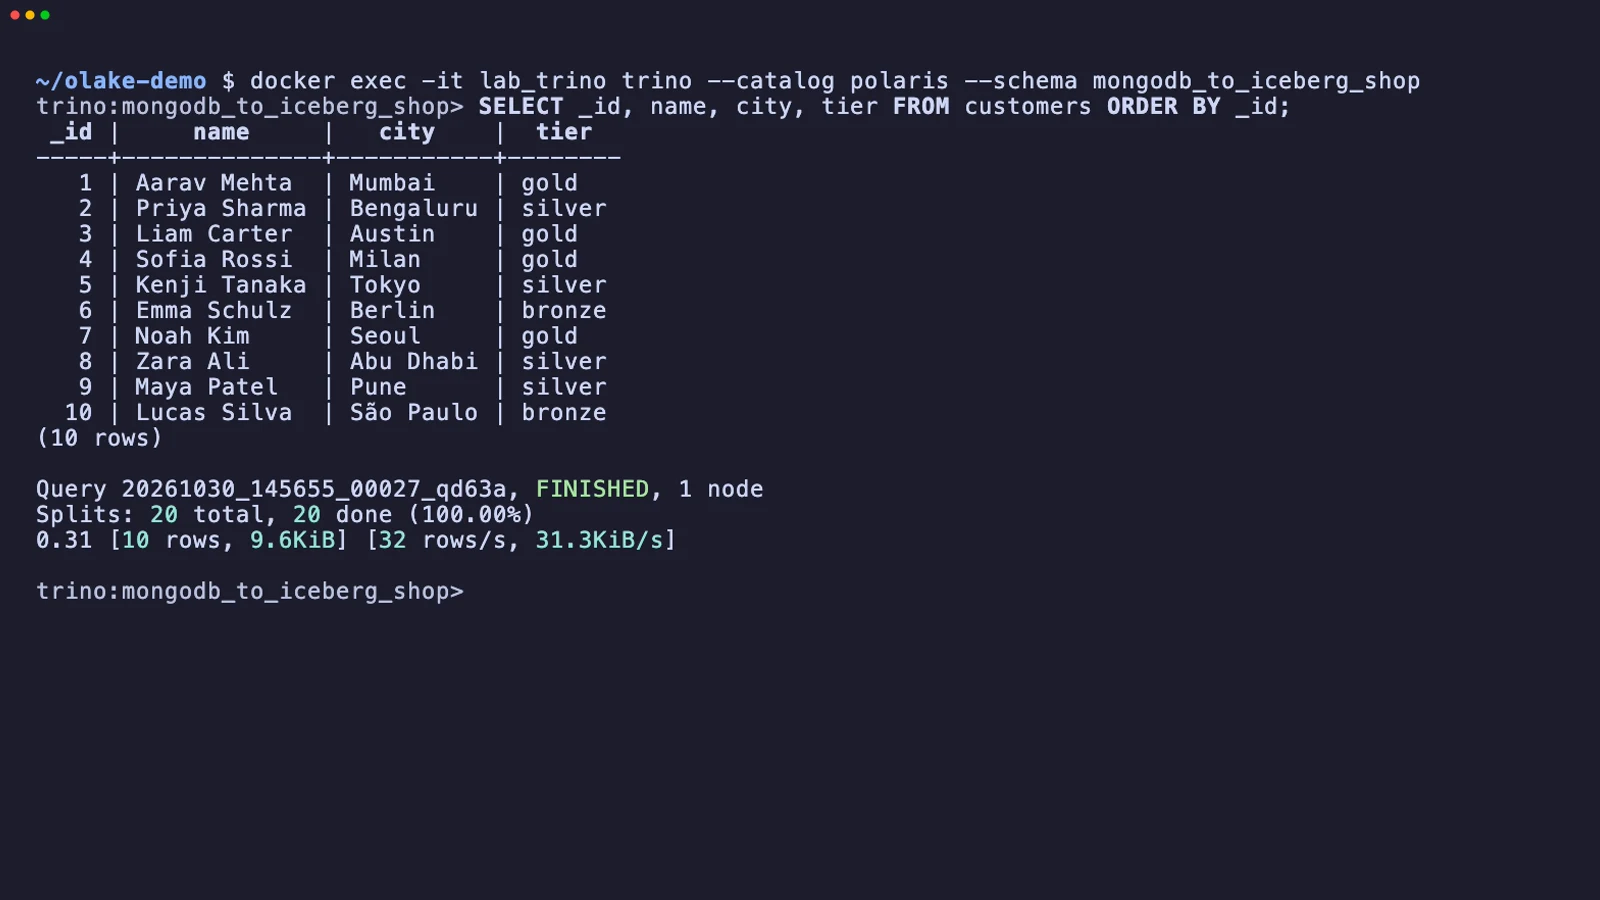
Open source Spark reaches Polaris through the Iceberg REST catalog. The warehouse is the Polaris catalog name, and credential is the principal's client ID and secret, which Spark trades for an OAuth2 token.
spark-sql \
  --packages org.apache.iceberg:iceberg-spark-runtime-3.5_2.12:1.10.0,org.apache.iceberg:iceberg-aws-bundle:1.10.0 \
  --conf spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions \
  --conf spark.sql.catalog.polaris=org.apache.iceberg.spark.SparkCatalog \
  --conf spark.sql.catalog.polaris.type=rest \
  --conf spark.sql.catalog.polaris.uri=http://<polaris-host>:8181/api/catalog \
  --conf spark.sql.catalog.polaris.warehouse=olake \
  --conf spark.sql.catalog.polaris.credential=<client_id>:<client_secret> \
  --conf spark.sql.catalog.polaris.scope=PRINCIPAL_ROLE:ALL \
  --conf spark.sql.catalog.polaris.header.X-Iceberg-Access-Delegation=vended-credentials \
  --conf spark.sql.catalog.polaris.client.region=us-east-1
SELECT _id, name, city, tier FROM polaris.mongodb_to_iceberg_shop.customers ORDER BY _id;
On MinIO or another S3-compatible store, also set spark.sql.catalog.polaris.s3.endpoint and spark.sql.catalog.polaris.s3.path-style-access=true. The run on this page used Spark 3.5.6 with Iceberg 1.10.0 against MinIO, with the MinIO keys passed as s3.access-key-id and s3.secret-access-key instead of vended credentials.
All three engines agreed on the counts and the money: 10 customers, 45 orders and 25579.19 in total, each casting amount to a double first. The orders roll-up matched MongoDB to the cent: 16 delivered orders for 8659.68, 18 placed for 10522.26, 11 shipped for 6397.25.
Data types: MongoDB to Iceberg
OLake Go maps MongoDB's BSON (Binary JSON) types to Iceberg types. Scalars pass through; everything structured arrives as text.
| MongoDB type | Iceberg (written by OLake Go) | Trino shows | Notes |
|---|---|---|---|
int, timestamp | int | integer | The integer _id keys on this page arrived as integer. |
long | long | bigint | |
double | double | double | |
boolean | boolean | boolean | |
date | timestamptz (UTC) | timestamp(6) with time zone | |
decimal128 | string | varchar | Money stored as NumberDecimal arrives as text. sum(CAST(amount AS DOUBLE)) gave the exact totals on this page; store doubles in MongoDB if you want a numeric column without the cast. |
objectId, binData, regex, code | string | varchar | An ObjectId primary key arrives as its 24-character hex string. |
object, array | string | varchar | JSON text; parse it at query time. |
MongoDB types in the table come from the MongoDB connector reference; the Trino column comes from DESCRIBE on the tables of this run. OLake Go adds _cdc_resume_token on MongoDB tables, the change-stream token each change came from.
Cost and maintenance
- Storage is your bucket: you pay S3 or MinIO rates for the Parquet and delete files, and nothing to Polaris for holding pointers.
- Compute. OLake Go runs wherever you run Docker. Each engine spends compute only when it queries, and none of them keeps its own copy.
- Maintenance. Nothing compacts the tables for you. A CDC table that gets a new small file and delete file per sync wants compaction; OLake Fusion does this for the catalogs OLake Go writes to, and Spark's
rewrite_data_filesworks through the same Polaris endpoint. - Oplog size. The oplog is sized in gigabytes, not hours, so a write-heavy cluster shortens the window. Check it after a busy day and resize before a planned pause.
- Credential rotation. Polaris principals do not expire by default. Rotate the
olakeprincipal's secret on your own schedule; a rotated secret fails the next sync at the token exchange, before any data moves.
Troubleshooting
1. The source test warns about the oplog
oplog_retention: current 1.3 hours, recommended >= 7 days
Not a blocker, but it is the window in which the next sync must start. The fix is on the MongoDB side: replSetResizeOplog on self-hosted, or the minimum oplog window setting on Atlas. Until then, run the job more often than the window.
2. The source test cannot open a change stream
change_streams: OLake cannot open a change stream, so CDC cannot run.
Either mongod is not running with --replSet, or the user lacks oplog access. Check rs.status() on the server and give the OLake Go user clusterMonitor (or readAnyDatabase) in admin on top of read on the database.
3. A money column will not sum
Binder Error: No function matches the given name and argument types 'sum(VARCHAR)'. You might need to add explicit type casts.
That is DuckDB; Trino says Unexpected parameters (varchar) for function sum. The field is a Decimal128 in MongoDB, which arrives as a string. Wrap it: sum(CAST(amount AS DOUBLE)), as in step 6.
4. The destination test fails at the token exchange
OLake Go's destination test exchanges the principal's credentials at /api/catalog/v1/oauth/tokens before anything else. Three causes cover nearly every failure: a wrong client id or secret, a principal without a role that carries CATALOG_MANAGE_CONTENT on the catalog, or a wrong Polaris Catalog Name. Run the token check from the catalog setup; it returns the same error Polaris gives OLake Go.
How this compares with other ways to move MongoDB data to Apache Iceberg
| Method | Freshness | Updates and deletes | What you run |
|---|---|---|---|
| Debezium MongoDB connector, Kafka and Kafka Connect with an Iceberg sink | Set by the sink commit interval | Appended as change events, with a separate merge job for the current state | Debezium, Kafka, Kafka Connect and usually a schema registry |
| Flink CDC with the Iceberg Flink sink | Set by the checkpoint interval | Upserts through equality deletes on tables with a key | A Flink cluster with checkpoint storage |
| Managed ELT with an Iceberg destination | Minutes, by plan | Varies by tool | Nothing to run; priced per row, per GB or per connector |
Periodic mongoexport to JSON, then a load job | Hours | Full reload or hand-written merge | A scheduler and your own scripts |
| OLake Go to Iceberg on Polaris (this guide) | CDC on a schedule down to one minute | Upserts through positional deletes, equality deletes or deletion vectors, matched to the target engines | One Docker Compose stack, open source; your bucket plus your own compute |
Debezium and Kafka make sense when Kafka already carries the change events for other consumers. Flink wins when you need joins, enrichment or second-level latency on the way in. For copying MongoDB collections into Iceberg without Kafka, OLake Go is one job and one catalog; the trade-off is that freshness is a schedule, not a stream.
When not to use this
- You need the documents kept whole. OLake Go flattens one level; deeply nested documents arrive as JSON text in one column. If every query starts by parsing that text, a document store or a JSON-native table may serve you better.
- You need sub-minute freshness. OLake Go runs on a schedule, down to one minute between syncs. A streaming pipeline is the better fit for second-level latency.
- Your server is a standalone
mongod. Change streams need a replica set. Convert it to a single-node replica set first, which needs a restart.
FAQs
How do I replicate MongoDB to Apache Iceberg without Kafka?
Run OLake Go (open source, Apache 2.0) against a MongoDB replica set and point it at an Iceberg REST catalog such as Apache Polaris. OLake Go opens a change stream itself, so there is no Kafka, Debezium or Kafka Connect in the path. The first sync copies each collection in full, every later sync replays inserts, updates and deletes from the stream, and each sync lands as one Iceberg commit.
How do nested documents arrive in Iceberg?
Flattened one level. Top-level fields become columns; nested objects and arrays arrive as JSON text in a string column, which you parse at query time. Decimal128 values also arrive as strings, so cast them before summing. ObjectId keys arrive as their 24-character hex string.
Which Iceberg delete format does OLake Go write for Spark, DuckDB and Trino?
Spark, DuckDB and Trino all read equality deletes, positional deletes and deletion vectors, so every format was open to this job. The run on this page used positional deletes on Iceberg format version 2. Every current release of the three engines reads them, while Trino reads deletion vectors only from release 480, where its docs still mark them experimental.
Does OLake Go copy the existing collections before it starts reading the change stream?
Yes, automatically. A job in Full Refresh + CDC mode opens the change stream, copies every selected collection in parallel chunks, then replays the stream from the token it saved. Nothing written during the copy is lost, and there is no separate backfill job.
Does MongoDB CDC with OLake Go work on Atlas?
Yes. Atlas clusters are already replica sets with the oplog on. Create a database user with the read role on your database plus clusterMonitor, allow OLake Go's address in the Atlas network list, and paste the SRV connection string into the source. Set the Atlas minimum oplog window to cover your longest pause between syncs.
What does OLake Go need on the MongoDB side?
A replica set (a single node is fine), oplog retention longer than your longest pause between syncs, and a user with read on the database plus clusterMonitor or readAnyDatabase in admin for oplog access. Step 1 has the mongosh commands.
Related guides
Deeper reading on this site: