OLake Go
Open-Source Replication into Apache Iceberg & S3
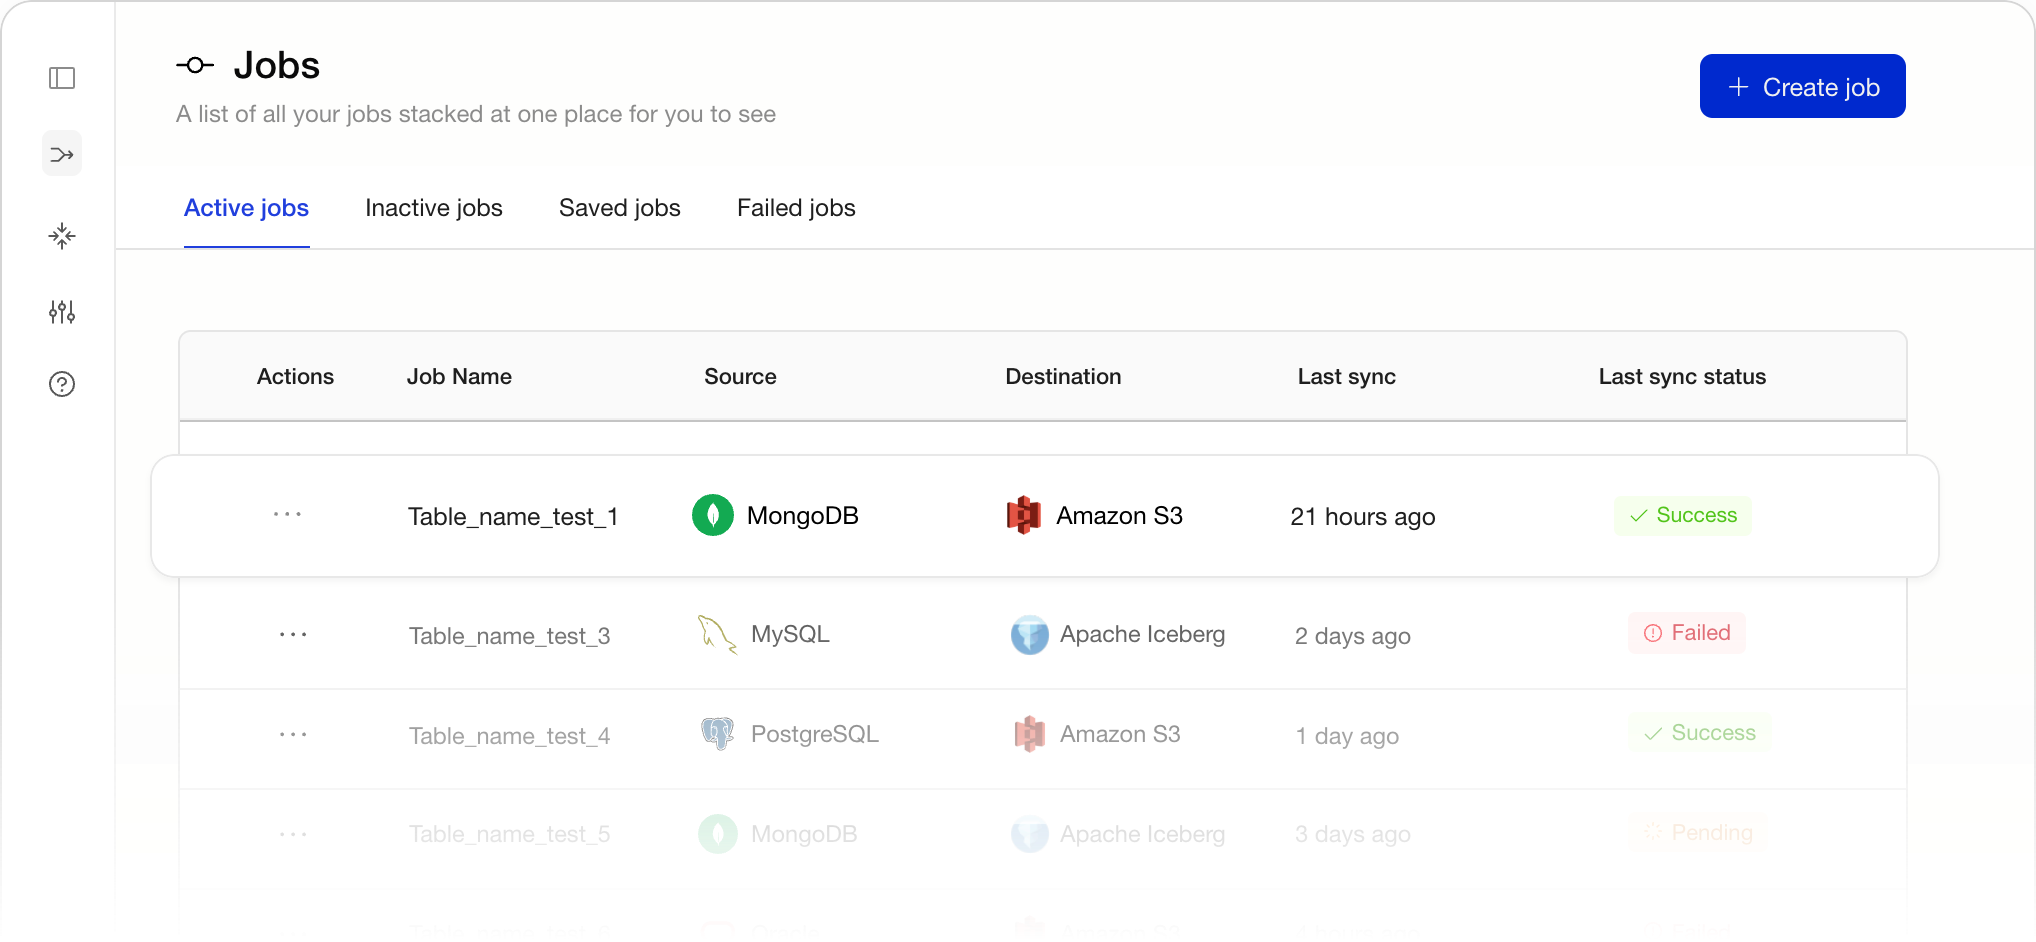
OLake Go helps you ingest data from 8 different sources into Apache Iceberg and S3
Available Sources
 Kafka
 Postgres
 MySQL
 MongoDB
 S3
 MSSQL
 DB2
 Oracle
Problem Statement
Still doubling back on your ingestion jobs?
- Problem ISlow syncs block your analytics
- Problem IILegacy ETL costs pile up fast
- Problem IIICDC pipelines break silently in production
- Problem IVSchema drift stalls ingestion
Features
Experience the most seamless workflow
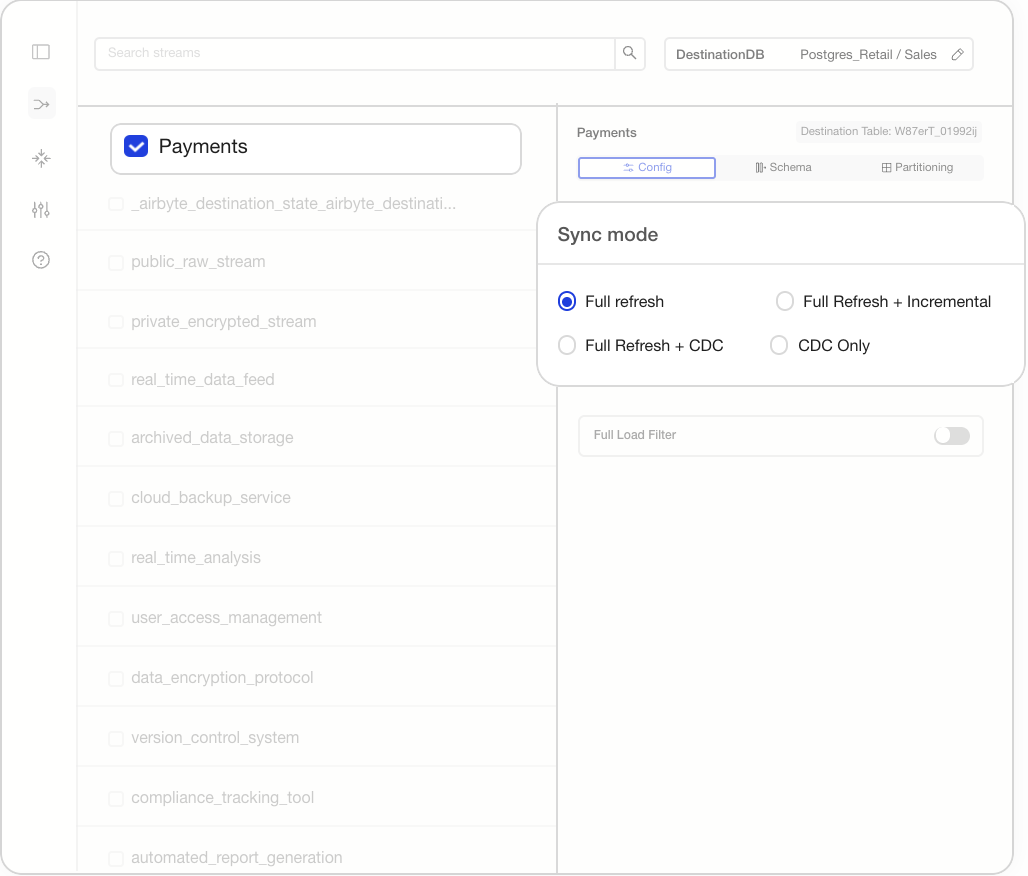
Full, Incremental & CDC Syncs
Run full loads, incremental pulls, or real-time change data capture, whatever each table needs, all from a single tool.
Schema & Partition Evolution
Source schemas change and partitions grow. OLake Go evolves your Iceberg tables automatically so pipelines never break.
Parallelised Chunking
Large collections are split into virtual chunks read in parallel, dramatically cutting the time for full snapshots of big datasets.
Stateful Resumable Syncs
Syncs checkpoint their progress and resume automatically after crashes or network failures; never from scratch.
Benchmarks
Get the OLake Go Advantage
OLake Go replicates up to 12.5× faster than Fivetran and 35–1000× faster than other open-source tools, syncing 50M CDC changes in 15 minutes.
Time to move 4.01 billion rows,
Postgres to Apache Iceberg, full load
| Metrics | OLake GoOpen Source | Airbyte | Fivetran | Debezium | Estuary |
|---|---|---|---|---|---|
| Rows Synced | 4.01 Billion | 12.7 Million | 4.01 Billion | 1.28 Billion | 0.34 Billion |
| Elapsed Time | 1.91 hours | 7.5 hours(failed sync) | 24 hours | 24 hours | 24 hours |
| Speed (Rows/s) | 5,80,113 RPS | 457 RPS | 46,395 RPS | 14,839 RPS | 3,982 RPS |
| Comparison | - | 1270x slower | 12.5x slower | 39.1x slower | 146x slower |
| CostOLake is OSS and self-hosted — only pay for your infrastructure. | < $ 6 | $ 5,560 | $ 0(free full load) | $ 75 | $ 1,668 |
How OLake Go does this
Parallel chunking / OLake Go splits large tables into chunks and loads them concurrently for maximum throughput.
Native Iceberg writes / data lands directly in open Apache Iceberg tables with no proprietary staging layer.
FAQs
You might have some questions
Check the Quickstart Guide. With a single Docker command you can spin up OLake Go and access the UI.
Yes. OLake Go is fully open source under the Apache 2.0 license. You can explore the GitHub repository (already starred by 1K+ developers) and use it freely without hidden costs.
We're actively working on providing enterprise support, from professional assistance and pilot programs to helping teams scale OLake Go in production. You can reach out at hello@olake.io to learn more.
Join our Slack community, review the Contribution Guide, and explore "Good First Issues" on GitHub. Contributors can get their pull requests merged and be part of building an open-source, Iceberg-native ingestion tool.
OLake Go makes data replication into Apache Iceberg seamless, faster, and cost-efficient. It handles real-time CDC, schema and partition evolution, full and incremental syncs, and compaction, all without vendor lock-in, so your Iceberg tables stay open, scalable, and ready for analytics.
As of now, we integrate with Apache Iceberg and S3 as destinations. You can query it using popular query engines like Spark, AWS Athena, Snowflake, Databricks, and BigQuery.