 Webinar
Apache Iceberg for Beginners: Build a Lakehouse Anywhere ft. MinIO
Details
- Date:
September 22, 2026
- Time:
On-demand
- Duration:
50 mins
Summary
Apache Iceberg explained for beginners: what a data lakehouse is, how Iceberg tables and the Iceberg REST catalog work, and how to run a high-performance lakehouse on cloud, on-prem, or hybrid infrastructure. In this OLake Community Call, Brenna Buuck, Developer Evangelist at MinIO and a data engineer for 11 years, covers the foundations of building Apache Iceberg data platforms, based on her work with teams running Iceberg lakehouses in production.
- The three layers of a data lakehouse: object storage, an open table format and a query engine, each decoupled from the others
- How a lakehouse differs from a data warehouse and a data lake
- How Apache Iceberg handles schema evolution, hidden partitioning and engine independence
- How Iceberg metadata files, manifest lists and manifests let query engines skip files
- Why object storage sits on the performance-critical path for Iceberg queries
- How the Iceberg REST catalog tracks snapshots, enables time travel and handles concurrent writes
- What's new in Iceberg v3: deletion vectors, row lineage, variant types and geospatial types
- Three ways to run an Iceberg catalog: standalone, embedded in object storage and federated
Hosted By
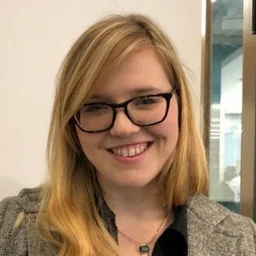
Brenna is a Developer Evangelist at MinIO and has worked as a data engineer for 11 years. She works with teams running Apache Iceberg lakehouses in production and shares what she learns about building high-performance data platforms on cloud, on-prem and hybrid infrastructure.
Ready to Join our next webinar?
Secure your spot by registering below.