MariaDB to BigQuery: CDC via Apache Iceberg
MariaDB to BigQuery usually means a Datastream stream pointed at MariaDB through the MySQL source, Debezium through Kafka, or a nightly mariadb-dump and bq load. This guide takes a fourth route. OLake Go reads the MariaDB binary log and commits the changes as Apache Iceberg tables into a BigLake catalog, Google Cloud's Iceberg representational state transfer (REST) catalog, with the files in your own Cloud Storage bucket.
BigQuery queries the tables through the catalog with a four-part name, with no dataset to create and no external table to declare. Nothing else is in the path: no Datastream, no Kafka, no load job. DuckDB and Spark read the same tables through the same catalog.
Key takeaways
- OLake Go replicates MariaDB into Iceberg tables in a BigLake catalog: a full historical snapshot first, then change data capture (CDC) from the binlog, with no Datastream or Debezium in between. OLake Go reads MariaDB through its MySQL connector, so every step applies as written.
- BigQuery reads the catalog as a data source. Every change a sync commits is visible on the next
SELECT, with no refresh and no load job. - The same tables, written once by OLake Go, are also queryable from DuckDB and Spark. In the run on this page all three engines returned identical rows.
The short answer. To replicate MariaDB to BigQuery with change data capture (CDC), run OLake Go with MariaDB's binary log as the source and a BigLake catalog with a Cloud Storage bucket as the Iceberg destination, with BigQuery as the target query engine. The first sync copies each table in full (the historical snapshot); every later sync replays inserts, updates and deletes from the binlog. BigQuery, DuckDB and Spark then query the same Iceberg tables, with no second copy.
How MariaDB CDC reaches BigQuery here
Two things happen in order, and OLake Go does both on its own. The first sync records the current binlog position. Then it reads each table in parallel chunks and writes Parquet data files: that is the historical load.
Every later sync opens the binlog at the saved position and replays the inserts, updates and deletes since. Nothing written during the snapshot is lost, and there is no separate backfill job.
Each sync ends with one commit to BigLake. OLake Go uploads the data and delete files to the bucket with the service account's own credentials, then updates the table's metadata pointer in the catalog. BigQuery, DuckDB and Spark see the new snapshot on their next query; none of them keeps a copy.
One thing to keep an eye on: the binlog is MariaDB's replay window. MariaDB deletes binlog files after binlog_expire_logs_seconds.
A job paused for longer than that cannot resume and needs a fresh snapshot. Keep retention longer than your longest planned pause, and alert on SHOW BINARY LOGS size if disk is tight.
What you need
- MariaDB 10.5 or later with the binlog on in
ROWformat and a user that can read it. The tables on this page ran on MariaDB 11.8 in Docker. Hosted MariaDB on Amazon Relational Database Service (RDS), Azure Database for MariaDB or SkySQL works the same way; step 1 links the setup guides. OLake Go reads MariaDB through its MySQL connector, so every MariaDB step on this page applies as written. - A Google Cloud project with the BigLake API enabled, a Cloud Storage bucket for the files, and a service account for OLake Go with the BigLake Editor role on the project and Storage Object User on the bucket. The run on this page used a bucket in
us-central1. - BigQuery in the same project. Queries run in the bucket's region, and the account running them needs the BigQuery Job User role plus read access to the catalog.
- OLake UI from the Docker Compose install. The run on this page used OLake Go v1.1.0.
- Docker, and about 30 minutes.
Step 1: Prepare MariaDB for CDC
Most readers point OLake Go at tables they already have. If you want to follow along with the exact data from this page, create these two tables first:
The two sample tables used on this page
CREATE TABLE customers (
  id INT AUTO_INCREMENT PRIMARY KEY,
  name VARCHAR(100), email VARCHAR(200), city VARCHAR(100), tier VARCHAR(20),
  created_at TIMESTAMP DEFAULT CURRENT_TIMESTAMP,
  updated_at TIMESTAMP DEFAULT CURRENT_TIMESTAMP ON UPDATE CURRENT_TIMESTAMP);

CREATE TABLE orders (
  id INT AUTO_INCREMENT PRIMARY KEY,
  customer_id INT, product VARCHAR(100), amount DECIMAL(10,2), status VARCHAR(20),
  created_at TIMESTAMP DEFAULT CURRENT_TIMESTAMP,
  updated_at TIMESTAMP DEFAULT CURRENT_TIMESTAMP ON UPDATE CURRENT_TIMESTAMP,
  FOREIGN KEY (customer_id) REFERENCES customers(id));

-- Then insert whatever you like. This page started with 8 customers and 40 orders.
OLake Go reads MySQL changes from the binary log (binlog), the same stream MySQL replicas use. Four things must be in place on the server before the first sync.
| Setting | Value | Why it matters |
|---|---|---|
log_bin | ON with a server_id | Without a binlog MySQL records no row changes, so there is nothing to replicate. Changing it needs a restart. |
binlog_format | ROW | Statement-based logging does not carry the row images OLake Go needs. |
binlog_row_metadata | FULL | Adds column names and types to every event, so OLake Go can map changes to columns after a schema change. |
| Replication user | SELECT, REPLICATION SLAVE, REPLICATION CLIENT | The snapshot reads the tables; the change stream reads the binlog. |
-- 1. Binary logging: put these in my.cnf (or the parameter group on managed MySQL) and restart
--    server-id = 1
--    log_bin = mysql-bin
--    binlog_format = ROW
--    binlog_row_metadata = FULL
--    binlog_expire_logs_seconds = 604800   -- keep 7 days, so a paused job can catch up
--    gtid_mode = ON, enforce_gtid_consistency = ON   -- optional; gives microsecond _cdc_timestamp

-- 2. A user for OLake Go
CREATE USER IF NOT EXISTS 'olake'@'%' IDENTIFIED BY '<password>';
GRANT SELECT, REPLICATION SLAVE, REPLICATION CLIENT ON *.* TO 'olake'@'%';
FLUSH PRIVILEGES;

-- 3. Table statistics: the chunked snapshot plans its chunks from them
ANALYZE TABLE customers, orders;
Check the result before moving on:
SHOW VARIABLES WHERE Variable_name IN ('log_bin', 'binlog_format', 'binlog_row_metadata', 'server_id');
SHOW GRANTS FOR 'olake'@'%';
Managed MySQL sets these through a parameter group or server setting rather than my.cnf. Each flavour has its own guide:
| Where MySQL runs | Guide |
|---|---|
| Amazon RDS | RDS MySQL CDC setup |
| Amazon Aurora | Aurora MySQL CDC setup |
| Azure Database for MySQL | Azure MySQL CDC setup |
| Google Cloud SQL | Cloud SQL MySQL CDC setup |
| Your own server or VM | Generic MySQL CDC setup |
| Docker, for a local test | Local MySQL with Docker Compose |
MySQL deletes binlog files after binlog_expire_logs_seconds. If a job is paused longer than that, the next sync cannot find its saved position and needs a fresh full snapshot. Keep retention longer than your longest planned pause.
Step 2: Set up the BigLake catalog
BigQuery reads Iceberg tables through a catalog. BigLake is the one this page uses: it is Google Cloud's Iceberg REST catalog, OLake Go creates a namespace per job in it, and the files sit in your Cloud Storage bucket.
BigQuery, DuckDB and Spark all read from the same catalog. BigQuery treats it as a data source in the project, so a table OLake Go commits is queryable on the next statement.
| Catalog | OLake Go writes | BigQuery reads | Verified on this page |
|---|---|---|---|
| BigLake (Google Cloud Lakehouse) | Yes | Yes: native: namespaces map to BigQuery datasets | Yes, end to end |
- BigLake (Google Cloud Lakehouse)
BigLake is the Iceberg REST catalog built into Google Cloud's Lakehouse. OLake Go talks to it at https://biglake.googleapis.com/iceberg/v1/restcatalog, the table files land in a Cloud Storage bucket you own, and BigQuery reads the tables without any registration step. Writing to BigLake needs OLake Go 0.9.1 or later.
Everything below happens in the Google Cloud console, in the project that will hold the tables.
- Enable the API. Open APIs and services, then Enable APIs and services, and enable the BigLake API. BigQuery and Cloud Storage are on by default in most projects.
- Create a bucket. In Cloud Storage, create a bucket in the region where BigQuery will run the queries (
us-central1on this page). The bucket name becomes the catalog name in BigQuery, so pick one you are happy to type in SQL. - Create a service account for OLake Go. In IAM and Admin, Service Accounts, create one (for example
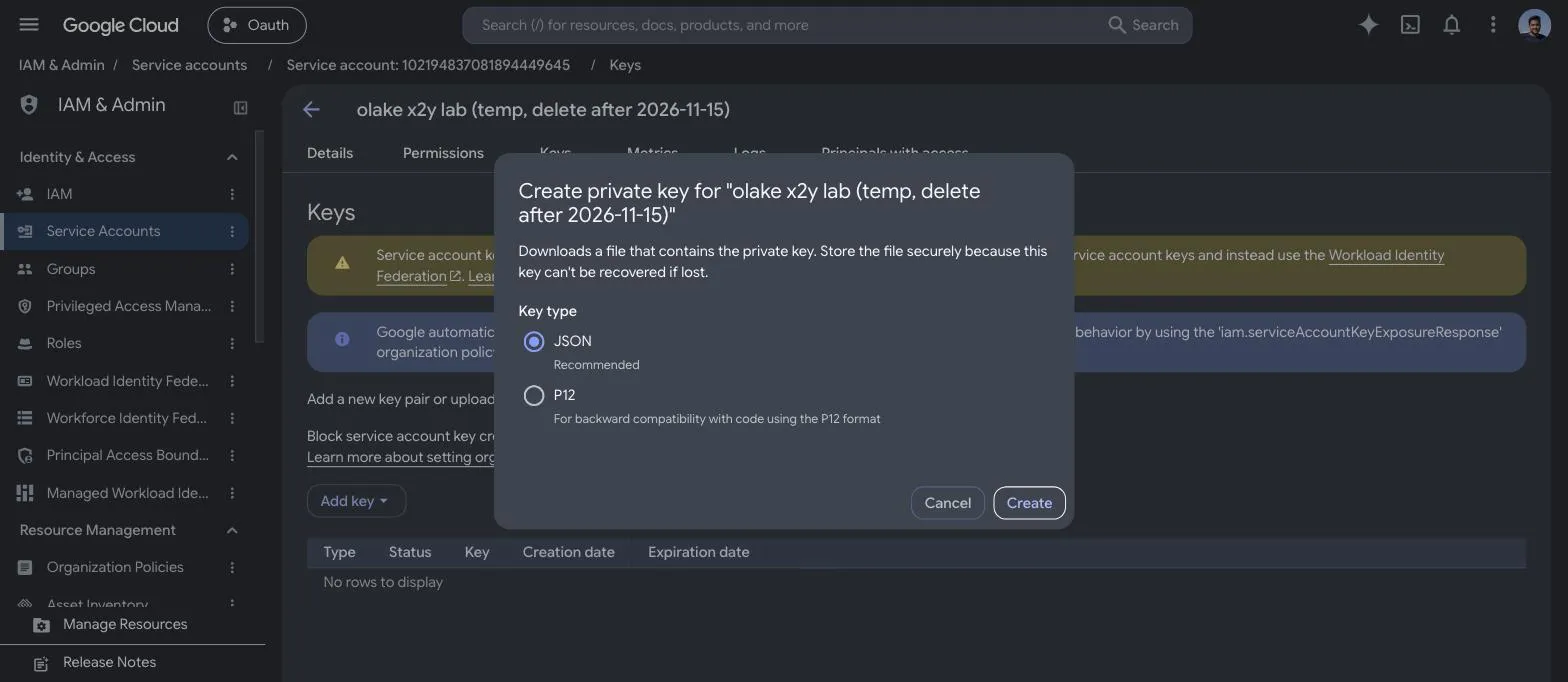
olake-biglake). Then grant it two roles: BigLake Editor on the project (IAM, Grant access, the service account as principal) and Storage Object User on the bucket (the bucket's Permissions tab). - Download a JSON key. On the service account's Keys tab, Add key, Create new key, JSON. The file downloads once; OLake Go asks for its contents.
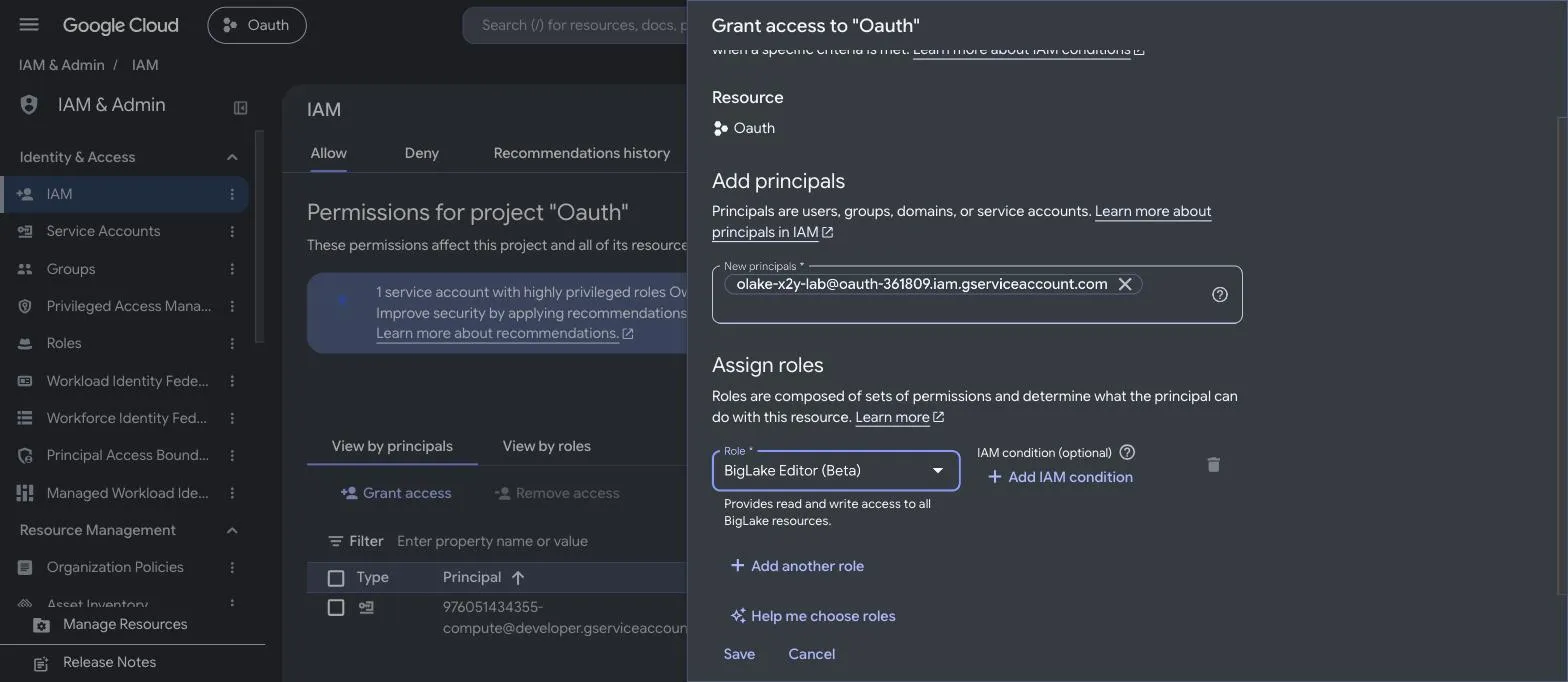
There is no catalog to create. BigLake creates a single-bucket catalog named after the bucket the first time OLake Go calls the endpoint with gs://<bucket> as the catalog path, in the default end-user credential mode, where every client brings its own storage credentials. The catalog shows up under BigLake, Catalogs after the first connection test.
Two things to know before the first sync:
- The service account's BigLake Editor role is what lets OLake Go create namespaces and commit tables. Storage Object User on the bucket is what lets it write the Parquet and metadata files. Missing either one fails the connection test with a
403frombiglake.googleapis.comor fromstorage.googleapis.com, which tells you which grant is missing. - Leave the catalog in end-user mode. OLake Go 1.1.0 does not send the
X-Iceberg-Access-Delegationheader, so a catalog switched to vended credentials rejects its commits (see troubleshooting). Readers that want short-lived tokens from the catalog can switch the mode later withgcloud beta biglake iceberg catalogs update <bucket> --credential-mode=vended-credentials, after settingrest_access_delegationin a CLI config.
Step 3: Connect MariaDB to OLake Go
- OLake UI
- OLake CLI
- In the OLake UI, open Sources and click Create Source. Pick MySQL as the connector, give the source a name and keep the OLake Go version on the latest release.
- Under Change data capture (CDC), leave Enable CDC on. The default Initial Wait Time is fine; raise it only if the binlog is large and the next sync times out while finding its saved position.
- Under Connection details, fill in the host, port, database name, username and password. Keep TLS off for a local test; on managed MySQL use the provider's certificate.
- Click Set up source. OLake Go tests the connection, then checks the binlog prerequisites (
binlog_access,log_bin,binlog_format,binlog_row_metadata) and shows the current and recommended value for anything that fails.
Here is the source form from the run on this page. MariaDB ran in another container, so the host is host.docker.internal on port 3307; the connector is MySQL, which is how OLake Go reads MariaDB, and the user is the replication user from step 1.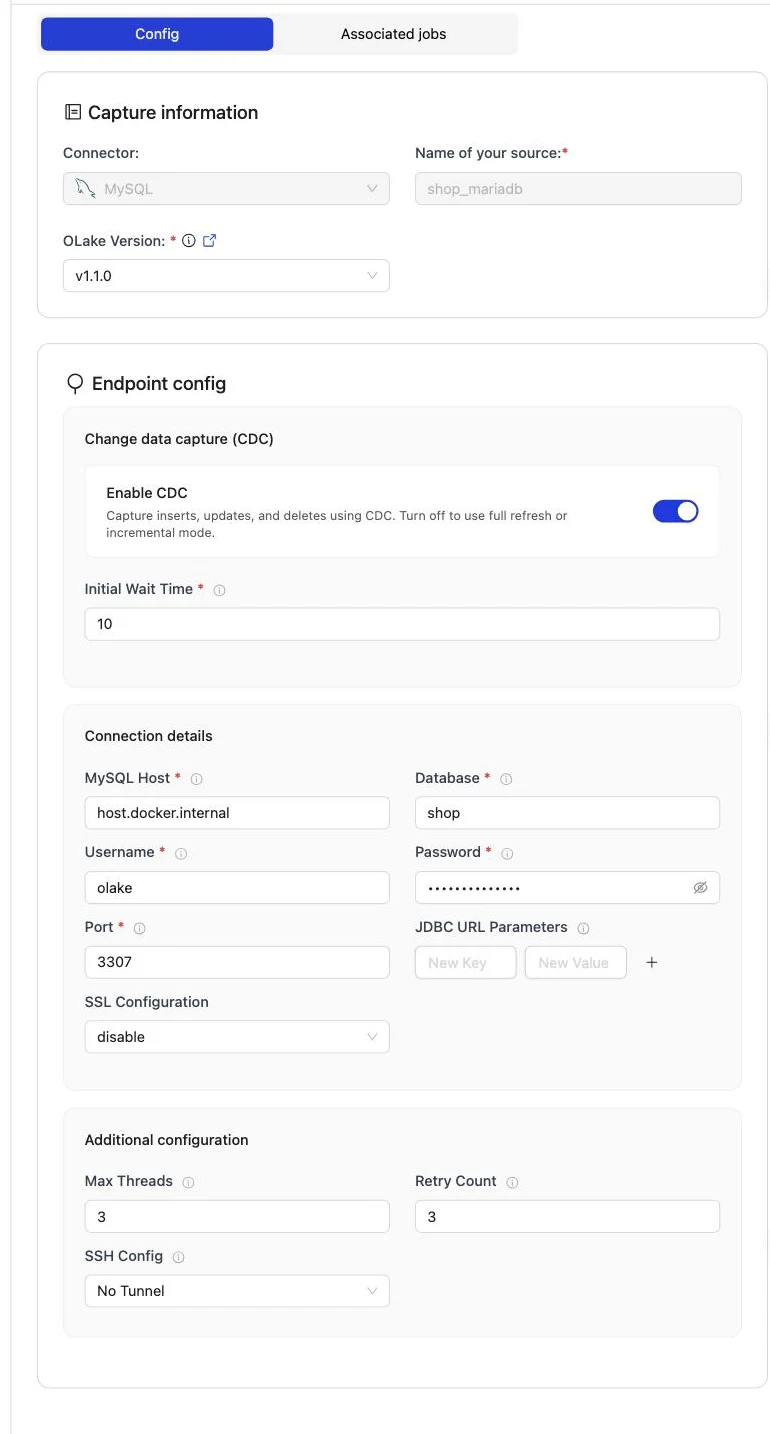
Set up source runs the connection test and the binlog checks (binlog_access, log_bin, binlog_format, binlog_row_metadata) before anything is saved. When one fails, the dialog names the setting and its recommended value.
The full field reference, including SSL and SSH tunnels, is on the MySQL connector page.
Create source.json in your config folder. The update_method block is what turns CDC on:
    {
        "hosts": "mysql-host",
        "username": "mysql-user",
        "password": "mysqlpwd",
        "database": "my-db",
        "port": 3306,
        "tls_skip_verify": true,
        "update_method": {
          "initial_wait_time": 10
        },
        "max_threads": 5,
        "backoff_retry_count": 4,
        "ssh_config": {
          "host": "my-tunnel-host",
          "port": 22,
          "username": "my-tunnel-user",
          "password": "tunnel-password"
        },
        "ssl": {
          "mode": "disable"
        },
        "jdbc_url_params": {
          "connectTimeout": "10000"
        }
    }
Then confirm OLake Go can reach the database:
docker run --pull=always \
  -v "$PWD/config:/mnt/config" \
  olakego/source-mysql:latest \
  check --config /mnt/config/source.json
A working setup returns "status": "SUCCEEDED" together with a prerequisites list that reports the binlog settings as passed. Every field is described on the MySQL connector page.
Step 4: Configure the Iceberg destination
- BigLake (Google Cloud Lakehouse)
- OLake UI
- OLake CLI
- Open Destinations and click Create Destination.
- Pick Apache Iceberg as the connector and BigLake as the catalog type.
- Fill in the fields below. The catalog path is the bucket, with no folder after it. Paste the whole service account JSON file into the credentials field.
- Click Create. OLake Go calls the BigLake endpoint, creates the catalog if it is the first contact, and writes and drops a test table in the bucket.
Here is the destination form from the run on this page. It holds the BigLake endpoint, the bucket as the catalog path, the service account JSON and the project ID.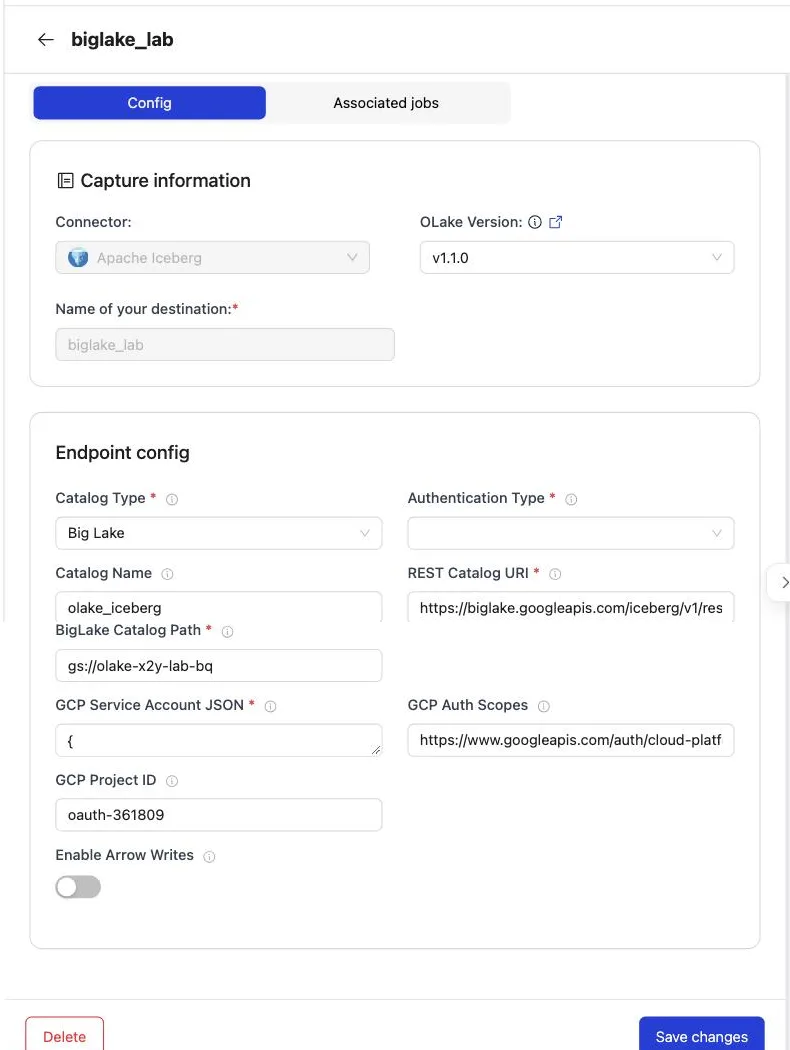
| Field | Value on this page | What it is |
|---|---|---|
| REST Catalog URI | https://biglake.googleapis.com/iceberg/v1/restcatalog | The BigLake Iceberg REST endpoint. The same for every project and region. |
| BigLake Catalog Path | gs://<bucket> | The bucket that holds the tables. The bucket name is also the catalog name BigQuery uses. Bucket root only; a folder after it is not supported. |
| Authentication Type | GCP | Google OAuth through the service account. The only choice for BigLake. |
| GCP Service Account JSON | the key file contents | Used for both the catalog calls and the Cloud Storage writes. |
| Catalog Name | olake_iceberg | A label OLake Go uses in its own logs. Lowercase letters and underscores only. |
| GCP Auth Scopes | https://www.googleapis.com/auth/cloud-platform | The OAuth scope on the token. Leave the default. |
| GCP Project ID | the project ID | Routes and bills the catalog calls. Required for multi-bucket catalogs, harmless to set for a single bucket. |
| Enable Arrow Writes | off | Keeps the default Java writer, which is what this page was tested with. |
Create destination.json next to source.json. The service account JSON goes in as one escaped string.
{
  "type": "ICEBERG",
  "writer": {
    "catalog_type": "biglake",
    "catalog_name": "olake_iceberg",
    "rest_catalog_url": "https://biglake.googleapis.com/iceberg/v1/restcatalog",
    "iceberg_s3_path": "gs://<bucket>",
    "rest_auth_type": "org.apache.iceberg.gcp.auth.GoogleAuthManager",
    "gcp_service_account_json": "{\"type\": \"service_account\", ...}",
    "gcp_project_id": "<project-id>",
    "gcp_auth_scopes": "https://www.googleapis.com/auth/cloud-platform",
    "arrow_writes": false
  }
}
| Key | Value on this page | What it is |
|---|---|---|
catalog_type | biglake | Selects the BigLake REST catalog. |
rest_catalog_url | https://biglake.googleapis.com/iceberg/v1/restcatalog | The BigLake endpoint. |
iceberg_s3_path | gs://<bucket> | The bucket, which is also the catalog name in BigQuery. The key is named for S3 but takes a gs:// path here. |
rest_auth_type | org.apache.iceberg.gcp.auth.GoogleAuthManager | Google OAuth with the service account. |
gcp_service_account_json | the key file as a string | Credentials for the catalog and the bucket. |
gcp_project_id | the project ID | Routes and bills the catalog calls. |
gcp_auth_scopes | https://www.googleapis.com/auth/cloud-platform | The OAuth scope. |
rest_access_delegation | not set | Set it to vended-credentials only when the catalog is in vended-credentials mode. The UI has no field for it. |
arrow_writes | false | The default Java writer. |
Step 5: Create the job and run the first sync
This job lists BigQuery, Spark and DuckDB as target query engines. OLake Go then offers only the delete formats all three read, and the run on this page picked Positional Deletes from that list. Each stream runs as Full Refresh + CDC, so the binlog carries every change after the snapshot.
- OLake UI
- OLake CLI
- Open Jobs and click Create Job. Give it a name and a schedule. Every Day at a fixed hour, or a cron expression, both work; the schedule is how often the change stream is drained, not how often a full copy runs.
- Select the source and the destination you created.
- Under Advanced Settings, set Target Query Engines to Google BigQuery, Apache Spark and DuckDB. OLake Go then resolves an Iceberg delete format every one of those engines can read, so you never pick one by hand.
- Click Next. OLake Go discovers the tables and opens the Streams page.
- Tick the tables to replicate. For each one, set the sync mode to Full Refresh + CDC and the ingestion mode to Upsert. Leave the Upsert Type as OLake Go resolved it (Positional Deletes in the run on this page).
- Click Create Job, then open the job's menu and choose Sync Now for the first run.
OLake Go offers every delete format BigQuery, Spark and DuckDB all read: equality and positional deletes. Deletion vectors are not in the list because BigQuery reads them only in preview.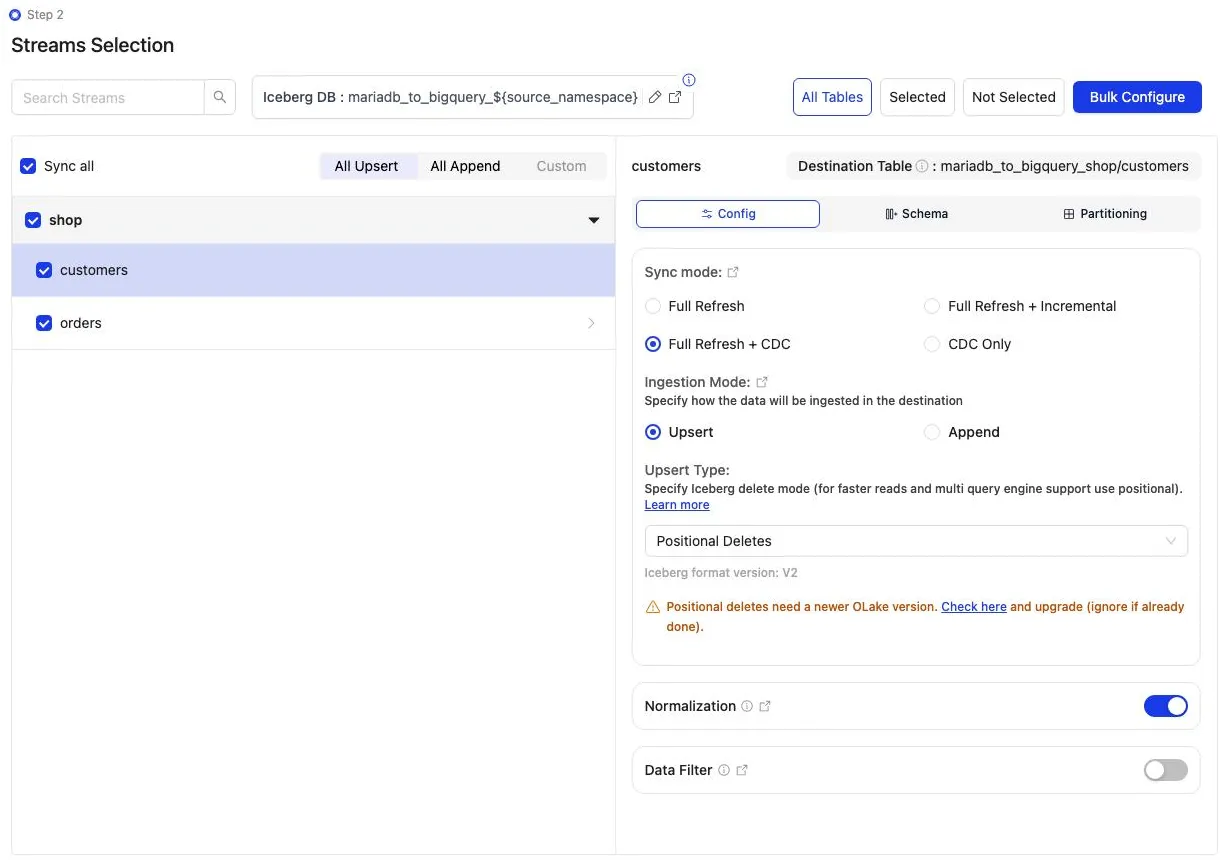
Discover the tables, choose the streams, then sync:
docker run --pull=always \
-v "$PWD/config:/mnt/config" \
olakego/source-mysql:latest \
discover --config /mnt/config/source.json
discover writes two files: available_streams.json (every table it found, do not edit) and selected_streams.json (the tables you want and their settings). In selected_streams.json, set sync_mode to {props.cliSyncMode ?? 'cdc'} for each table and pick the delete format your readers can open:
{
"selected_streams": {
  "shop": [
    {
      "stream_name": "customers",
      "sync_mode": "cdc",
      "normalization": true,
      "append_mode": false,
      "update_type": "pos"
    }
  ]
}
}
update_type accepts eq (equality deletes, the default), pos (positional deletes) and dv (deletion vectors). Positional deletes and deletion vectors keep a small index between runs, so give the container a persistent directory for it through OLAKE_INDEX_DB_DIR. The first sync runs without a state file; OLake Go writes one at the end of the run:
docker run --pull=always \
-v "$PWD/config:/mnt/config" \
-e OLAKE_INDEX_DB_DIR=/mnt/config/index-db \
olakego/source-mysql:latest \
sync \
--config /mnt/config/source.json \
--selected-streams /mnt/config/selected_streams.json \
--available-streams /mnt/config/available_streams.json \
--destination /mnt/config/destination.json
Every later run adds --state /mnt/config/state.json to the same command, which is how OLake Go knows to replay only the changes since the last run. The full selected_streams.json reference is on the Docker CLI page; the index directory is described under index DB setup.
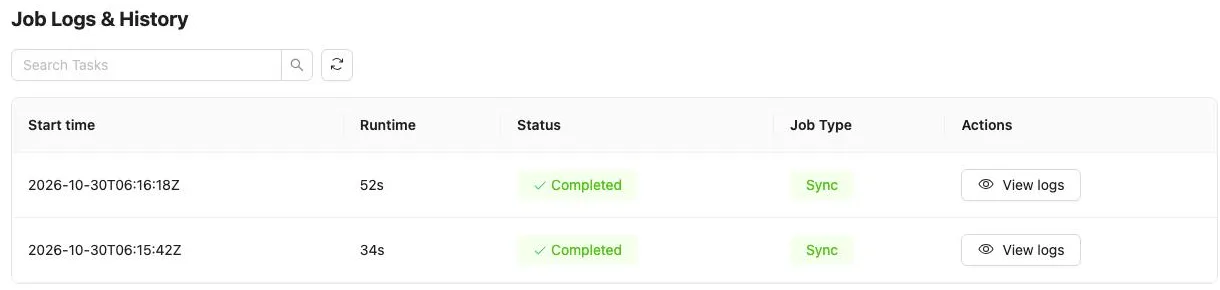
On this page the first run copied 8 customers and 40 orders (48 records, 2.10 KB) and finished in 34 seconds, container start included. OLake Go names the BigLake namespace after the job and the source database, so mariadb_to_bigquery on database shop produced mariadb_to_bigquery_shop. The Iceberg DB field at the top of the Streams page changes it before the first sync.
Step 6: Query the tables in BigQuery
- BigLake (Google Cloud Lakehouse)
There is no registration step and no external table to declare. A BigLake catalog is a BigQuery data source in the same project: the catalog is the bucket name, the namespace OLake Go created is the dataset, and the tables are the tables. Address them with the four-part name in backticks, and run the query in the bucket's region.
SELECT id, name, city, tier
FROM `<project-id>.<bucket>.mariadb_to_bigquery_shop.customers`
ORDER BY id;

SELECT status, count(*) AS n, round(sum(amount), 2) AS total
FROM `<project-id>.<bucket>.mariadb_to_bigquery_shop.orders`
GROUP BY status ORDER BY status;
From a terminal, bq query --project_id=<project-id> --location=<region> --use_legacy_sql=false "<sql>" runs the same statements. Set the location to the bucket's region (us-central1 on this page); the default US multi-region returns Not found: Dataset for a catalog whose bucket is regional.
OLake Go adds four columns to every table: _olake_id (a hash of the primary key), _op_type, _olake_timestamp and _cdc_timestamp. _op_type is r for a row from the first snapshot, c for an insert, u for an update and d for a delete. Filter them out of dashboards, or use them to see when a row last changed.
BigQuery reads Iceberg v2 tables with positional and equality deletes, which is why the job on this page uses positional deletes. Deletion vectors on v3 tables are a preview feature in BigQuery with per-query limits, so keep the job off deletion vectors while BigQuery is a reader.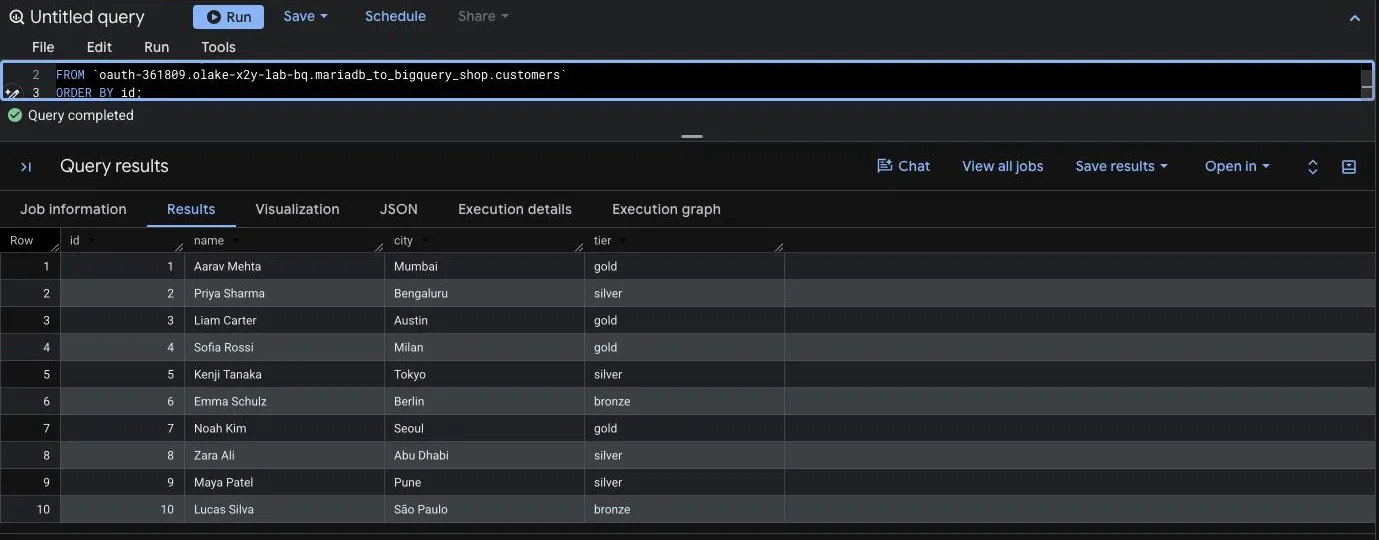
Step 7: Change rows in MariaDB and sync again
To see the change path work, the run on this page made 12 changes in MariaDB after the first sync:
INSERT INTO customers (name, email, city, tier) VALUES
  ('Maya Patel', 'maya@example.com', 'Pune', 'silver'),
  ('Lucas Silva', 'lucas@example.com', 'São Paulo', 'bronze');
INSERT INTO orders (customer_id, product, amount, status) VALUES
  (9, 'Laptop', 1299.00, 'placed'), (9, 'Mouse', 25.50, 'placed'),
  (10, 'Monitor', 349.99, 'placed'), (3, 'Keyboard', 89.00, 'placed'), (7, 'Webcam', 79.90, 'placed');
UPDATE customers SET tier = 'gold'      WHERE name = 'Liam Carter';
UPDATE customers SET city = 'Abu Dhabi' WHERE name = 'Zara Ali';
UPDATE orders    SET status = 'delivered' WHERE id IN (1, 4, 7);
The second sync read 12 records (563 bytes) from the binlog and finished in 52 seconds end to end. For customers that meant one new data file with 4 rows: 2 inserts plus the new versions of 2 updated rows.
One small positional delete file retires the 2 old versions. OLake Go's commit report in the sync log shows it directly: addedDataFiles=1, addedRecords=4, addedPositionalDeleteFiles=1, addedPositionalDeletes=2. The orders table has the same shape with 8 rows and 3 deletes.
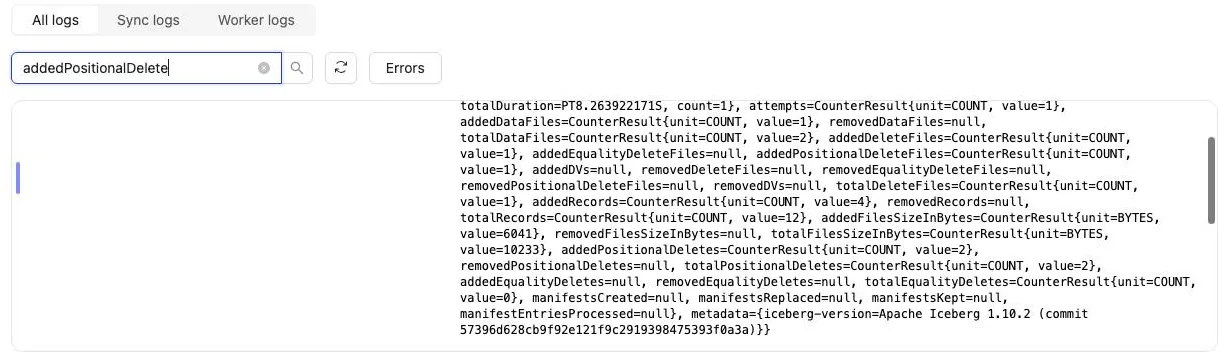
BigQuery shows the result on the next query, with no refresh and no ALTER TABLE. Liam Carter is gold, Zara Ali moved to Abu Dhabi, and the two new customers are there.
The two retired versions are gone, because BigQuery applies the positional deletes while reading. The _op_type column shows how each row arrived: r for the snapshot, c for the inserts and u for the updates.
Schema changes. When a column is added in MariaDB, OLake Go adds it to the Iceberg table on the next sync and commits the new schema to BigLake in the same commit. BigQuery shows the column on the next query. Widening changes (int to bigint, float to double) are applied.
Narrowing or incompatible type changes fail the sync rather than corrupt the table. binlog_row_metadata = FULL is what lets OLake Go see the new column names in the binlog. Full rules are on the schema evolution page.
Query the same tables from DuckDB and Spark
This is the point of writing Iceberg instead of loading BigQuery tables. Nothing is exported, copied or refreshed: both engines read the files OLake Go wrote, through the same BigLake catalog.
- DuckDB
- Apache Spark
DuckDB attaches BigLake as an Iceberg REST catalog with a Google access token. The catalog on this page is in end-user credential mode, so DuckDB also needs its own Cloud Storage credentials to read the files: an HMAC key for the service account (Cloud Storage, Settings, Interoperability, Create a key for a service account).
INSTALL iceberg; LOAD iceberg;
INSTALL httpfs;  LOAD httpfs;

-- gcloud auth print-access-token, or a token minted for the service account
CREATE SECRET biglake_catalog (
TYPE iceberg,
TOKEN '<access token>',
EXTRA_HTTP_HEADERS MAP {'x-goog-user-project': '<project-id>'}
);
-- the HMAC key pair for the bucket
CREATE SECRET biglake_files (TYPE gcs, KEY_ID '<hmac access id>', SECRET '<hmac secret>');

ATTACH 'gs://<bucket>' AS biglake (
TYPE iceberg,
ENDPOINT 'https://biglake.googleapis.com/iceberg/v1/restcatalog',
SECRET biglake_catalog
);

SHOW ALL TABLES;
SELECT id, name, city, tier FROM biglake.mariadb_to_bigquery_shop.customers ORDER BY id;
The access token lives an hour; CREATE OR REPLACE SECRET with a fresh one when a query fails with 401. If the catalog is in vended-credentials mode instead, drop the gcs secret and add ACCESS_DELEGATION_MODE 'vended_credentials' to the ATTACH: BigLake then hands DuckDB a short-lived storage token per table. DuckDB reads positional deletes, so the rows match BigQuery after every sync.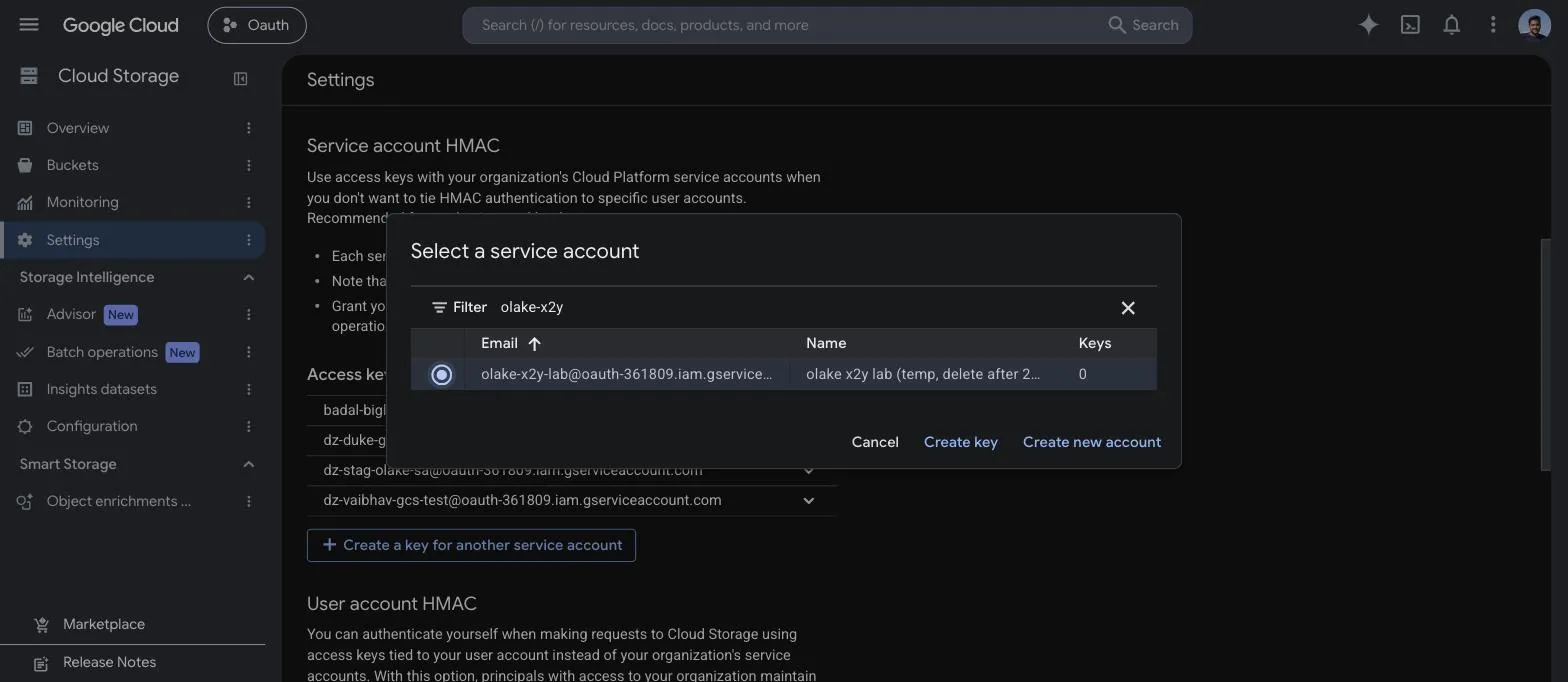
DuckDB 1.5.5 returned the same 10 customers and the same orders roll-up as BigQuery in the run on this page. It read the current metadata file of each table through the catalog and the data files through the hash-based message authentication code (HMAC) key.
Spark reaches BigLake as a plain Iceberg REST catalog with Google's auth manager from the iceberg-gcp-bundle. The same service account key OLake Go uses works for both the catalog calls and the file reads, so point GOOGLE_APPLICATION_CREDENTIALS at it before starting Spark.
export GOOGLE_APPLICATION_CREDENTIALS=/path/to/service-account.json
spark-sql \
  --packages org.apache.iceberg:iceberg-spark-runtime-4.0_2.13:1.10.0,org.apache.iceberg:iceberg-gcp-bundle:1.10.0 \
  --conf spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions \
  --conf spark.sql.catalog.biglake=org.apache.iceberg.spark.SparkCatalog \
  --conf spark.sql.catalog.biglake.type=rest \
  --conf spark.sql.catalog.biglake.uri=https://biglake.googleapis.com/iceberg/v1/restcatalog \
  --conf spark.sql.catalog.biglake.warehouse=gs://<bucket> \
  --conf spark.sql.catalog.biglake.rest.auth.type=org.apache.iceberg.gcp.auth.GoogleAuthManager \
  --conf spark.sql.catalog.biglake.header.x-goog-user-project=<project-id> \
  --conf spark.sql.catalog.biglake.io-impl=org.apache.iceberg.gcp.gcs.GCSFileIO
SHOW TABLES IN biglake.mariadb_to_bigquery_shop;
SELECT id, name, city, tier FROM biglake.mariadb_to_bigquery_shop.customers ORDER BY id;
Use the Spark 4.0 runtime with Iceberg 1.10 or later; Spark 3.5 builds of Iceberg do not run on Java 21. Spark reads positional deletes with any Iceberg version, so no table setting changes when the job's delete format stays positional.
Spark 4.0.1 with Iceberg 1.10.0 returned the same rows in the run on this page, running on a laptop against the same catalog and bucket.
An orders roll-up matched MariaDB to the cent in all three engines. It gave 16 delivered orders for 8659.68, 18 placed for 10522.26, 11 shipped for 6397.25.
Data types: MariaDB to Iceberg to BigQuery
OLake Go maps MariaDB types to Iceberg types, and BigQuery maps Iceberg types to its own when it reads the catalog. Most columns pass through unchanged; three groups are worth knowing about.
| MariaDB | Iceberg (written by OLake Go) | BigQuery shows | Notes |
|---|---|---|---|
int, mediumint, smallint, tinyint (signed or unsigned) | int | INT64 | The id and customer_id columns on this page arrived as INT64. |
bigint, bigint unsigned | long | INT64 | |
decimal(p,s), float, double, real | double | FLOAT64 | OLake Go stores decimals as doubles. The orders.amount sums on this page matched MariaDB to the cent in every engine; round at query time when you need exact decimal arithmetic. |
datetime, timestamp | timestamptz (UTC) | TIMESTAMP | datetime has no zone in MariaDB; it is read as UTC. |
char, varchar, text family, enum, json, time, bit(1) | string | STRING | MariaDB stores json as longtext; parse it with PARSE_JSON or JSON_VALUE. time arrives as text. |
binary(n), varbinary, blob family | fixed[n] or binary | BYTES | Keep large binaries out of the sync. |
MariaDB types in the table come from the MySQL connector reference, which OLake Go uses for MariaDB. The BigQuery side comes from the BigQuery Iceberg tables page (checked 2026-10-30) and from the table schemas of this run.
Cost and maintenance
- Storage is your bucket: you pay Cloud Storage rates for the Parquet and delete files. The BigLake catalog itself has no per-table charge.
- Compute. OLake Go runs wherever you run Docker. BigQuery bills on-demand queries by bytes scanned, or by slot time on an edition; a query over the catalog reads the Parquet files in the bucket, so filter on the columns you need. DuckDB and Spark cost whatever machine they run on.
- Maintenance. A CDC table that gets a new small file and delete file per sync wants compaction, and BigLake keeps every snapshot OLake Go commits in the table's
metadata.json. BigLake rejects ametadata.jsonabove 1 MB, which a busy table reaches after a few thousand syncs. Expire old snapshots and compact on a schedule with OLake Fusion or with Spark'sexpire_snapshotsandrewrite_data_filesprocedures through the same catalog. - Binlog disk. Seven days of binlog on a busy server can be tens of gigabytes. Size the volume for it, or shorten retention once the job runs reliably every hour.
- Key rotation. The service account key is what OLake Go writes with. Rotate it on your schedule from the service account's Keys tab and paste the new JSON into the destination.
Troubleshooting
1. The first sync stops with a statistics error
failed to get or split chunks: stats not populated for table[shop.orders]. Please run ANALYZE TABLE to update table statistics
OLake Go plans the parallel snapshot from information_schema row estimates. A freshly created or freshly loaded table has none. Run ANALYZE TABLE <table>; for each table in the job, then sync again.
2. The source test fails on the binlog
binlog_format: current STATEMENT, recommended ROW
The test dialog names the setting. binlog_format and binlog_row_metadata can be changed at runtime with SET GLOBAL.
Put them in my.cnf (or the server parameters) too, or they revert on restart. log_bin itself needs a restart.
3. The next sync cannot find its binlog position
idle timeout reached, exiting binlog syncer
Two causes. If binlog_expire_logs_seconds already removed the saved binlog file, run a fresh full snapshot and lengthen retention.
If the file exists but the server is slow to seek to the position, raise Initial Wait Time on the source. 10 seconds was enough for the two-table database on this page.
4. The destination test fails on a catalog in vended-credentials mode
failed to test destination: failed to create or get table: rpc error: code = Internal desc = Failed to process request: Malformed request: X-Iceberg-Access-Delegation header must be present and contain `vended-credentials` when credential mode is `CREDENTIAL_MODE_VENDED_CREDENTIALS`.
The catalog was created, or switched, with --credential-mode=vended-credentials, and OLake Go 1.1.0 does not send the header BigLake wants in that mode (olake#1369). Switch the catalog back with gcloud beta biglake iceberg catalogs update <bucket> --credential-mode=end-user, which is the default for a catalog OLake Go created itself. With the CLI, "rest_access_delegation": "vended-credentials" in destination.json makes the same test pass; the UI has no field for it yet.
5. BigQuery cannot find the dataset
Not found: Dataset <project>:<bucket>.mariadb_to_bigquery_shop was not found in location US
The query ran in a location other than the bucket's region. Set the query location to the bucket's region in the editor's More, Query settings panel, or pass --location=<region> to bq. Leaving the location unset lets BigQuery pick it from the table.
How this compares with other ways to move MariaDB data to BigQuery
| Method | Freshness | Updates and deletes | Where the data lands | What you run |
|---|---|---|---|---|
| Datastream with the MySQL source | Near real time, by Google's description; CDC from the binlog | Yes | Native BigQuery datasets; BigQuery is the only reader | Nothing to run; a connection profile and a stream in the console, with MariaDB presented as a MySQL source |
| Debezium, Kafka and a BigQuery sink | Seconds | Yes, with the connector's upsert mode | Kafka topics, then BigQuery tables | Kafka, Kafka Connect, Debezium and a sink connector per table |
Export (mariadb-dump or SELECT INTO OUTFILE), then bq load | Hours to daily | No; full reloads only | Native BigQuery tables | A script, a scheduler and a staging bucket |
| Managed ELT (Fivetran, Estuary, Airbyte Cloud) | Minutes, by plan | Varies by tool | BigQuery tables, a second copy you pay to move and store | Nothing; priced per row, per GB or per connector |
| OLake Go to Iceberg on BigLake (this guide) | CDC on a schedule down to one minute | Yes, as Iceberg row-level deletes | Apache Iceberg tables that BigQuery, Spark, DuckDB, Trino and Flink all read | One Docker Compose stack, open source; your bucket plus your own compute |
Datastream is the simpler choice when BigQuery is the only reader and a managed Google service is the preference. Writing Iceberg once avoids paying to move and store a second copy. That matters as soon as Spark, DuckDB or a notebook needs the same rows, or you want to own the files.
When not to use this
- Every query must hit native BigQuery speed. A catalog table is read from Parquet in the bucket on every query. Keep the Iceberg tables as the source and load the hot slice into a native table on a schedule.
- Tables have no primary key. Inserts replicate; updates and deletes cannot be matched to a row and are not applied. Add a primary key or a unique index first.
- You want deletion vectors. BigQuery reads them only in preview, with a cap of 100,000 deletion vector entries per query. Keep the job on positional deletes while BigQuery is a reader.
FAQs
How do I replicate MariaDB to BigQuery without Datastream?
Run OLake Go (open source, Apache 2.0) against a MariaDB server with row-based binary logging on, and point it at a BigLake catalog with a Cloud Storage bucket. The first sync copies the tables in full, every later sync replays only the changes from the binlog, and BigQuery queries the tables through the catalog with a four-part name. Datastream, Kafka, Debezium and a load job are not needed. OLake Go reads MariaDB through its MySQL connector, so the setup is the same as for MySQL.
Does BigQuery read Iceberg tables with row-level deletes?
Yes. BigQuery reads Iceberg v2 merge-on-read tables with positional and equality deletes. The run on this page used positional deletes and BigQuery returned one row per key after the updates. Deletion vectors on Iceberg v3 tables are a preview feature with per-query limits, so keep the job on positional deletes while BigQuery is a reader.
Does OLake Go copy the existing MariaDB data before it starts reading the binlog?
Yes, automatically. A job in Full Refresh + CDC mode records the binlog position, copies every selected table in parallel chunks, then switches to the binlog from that position. Nothing written during the copy is lost, and there is no separate backfill job.
Do I need to create a BigQuery dataset or an external table?
No. A BigLake catalog is a data source BigQuery reads directly: the bucket name is the catalog, the namespace OLake Go creates is the dataset, and the tables appear under it. The query uses the four-part name project.bucket.namespace.table, and there is no CREATE EXTERNAL TABLE and no metadata refresh.
Does MariaDB CDC with OLake Go work on Amazon RDS, Azure or SkySQL?
Yes, as long as the binlog is on with row format. Managed MariaDB sets binlog_format, binlog_row_metadata and retention through a parameter group or server parameter instead of my.cnf; the MySQL setup guides on this site apply, because OLake Go reads MariaDB through the MySQL connector. On RDS for MariaDB the binlog is on once automated backups are enabled; set binlog_format to ROW in the parameter group.
Which MariaDB data types change on the way to BigQuery?
decimal columns become Iceberg double and show up in BigQuery as FLOAT64, so round at query time when you need exact decimal arithmetic. datetime and timestamp become TIMESTAMP in UTC. int and bigint become INT64, and varchar, text, json, enum and time arrive as STRING.
How much binlog does MariaDB need to keep for OLake Go?
Enough to cover your longest pause. OLake Go saves the binlog position after every sync and resumes from it; if MariaDB has already expired that file, the next sync cannot resume and needs a fresh snapshot. Seven days (binlog_expire_logs_seconds = 604800) is a safe default for a job that runs at least daily.
Related guides
Deeper reading on this site: